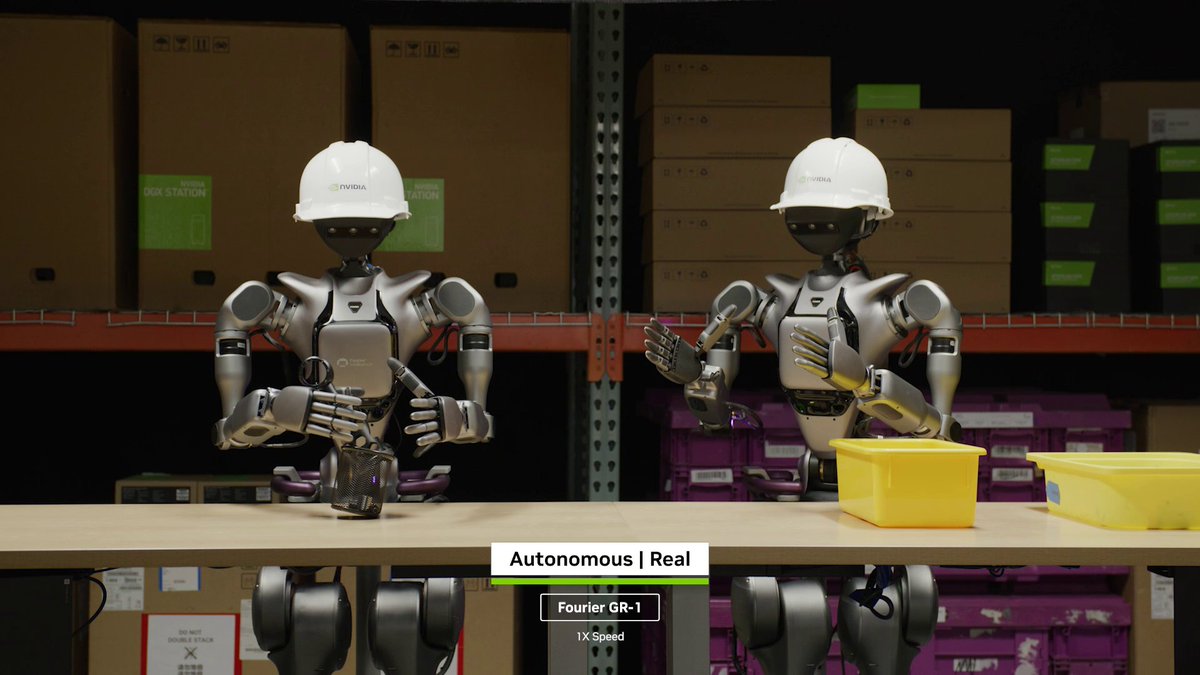
Загрузка видео...
Не удалось загрузить видео
NVIDIA just released GR00T 2, a new robot foundation model that predicts future video and actions together. Learning what the world will look like, not just what to do next, is what unlocks the rest. Jim Fan at CoRL Austin:
16,407 просмотров • 1 день назад •via X (Twitter)
Комментарии: 7

Nora1 день назад
@DrJimFan 未来の映画は終わりです

Artzy1 день назад
@DrJimFan Predicting the next frame makes the actual policy part so much cleaner

The SI Maximalist1 день назад
@DrJimFan The possibility of a robot anticipating what its reach might knock over is what excites me here.

Kailey Michael1 день назад
@DrJimFan @grok what's the training data size for gr00t 2

Igor Lessio - Robots/acc - AIFlow Labs1 день назад
@DrJimFan Predicting future video and actions together is the right bet, if the imagined video stays honest on contact-heavy tasks. World-model-first or pure action policy for real kitchens?

faruk1 день назад
@DrJimFan worth watching

asdasdkf1 день назад
@DrJimFan What about edge cases?
Похожие видео


0:22
Sensitive content
just found a video of what my army life will look like in the future and i fucking love it
⊹ ࣪ ˖
90,256 просмотров • 3 месяцев назад