Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

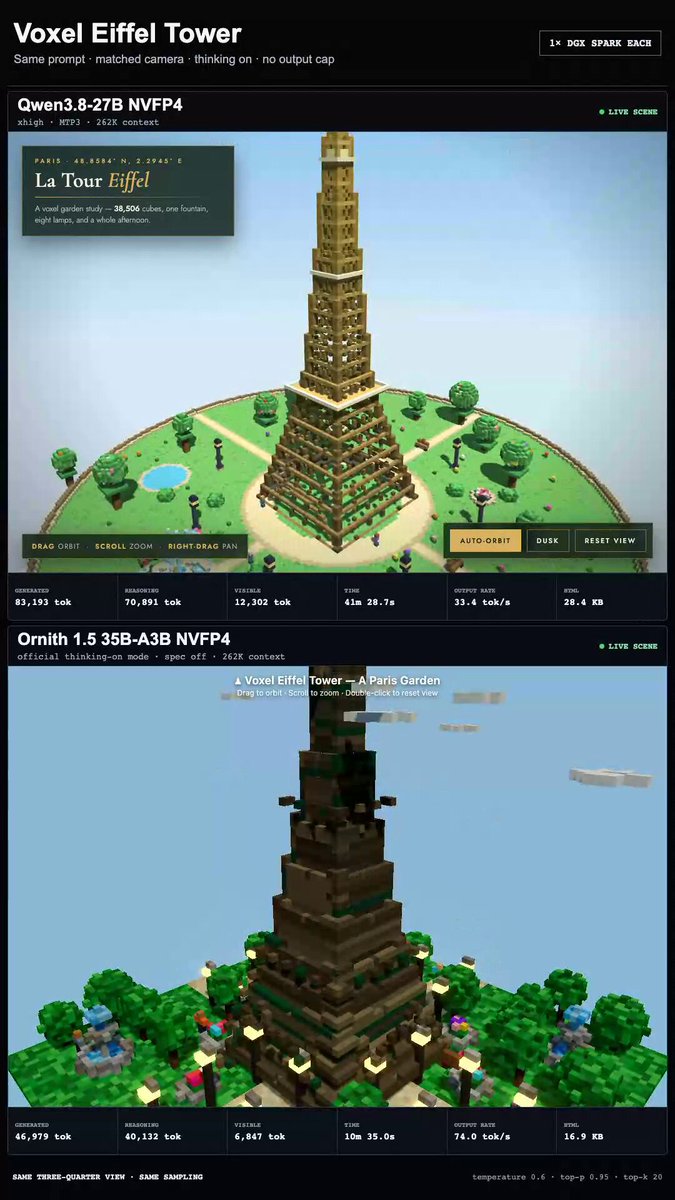
One task, two models. GLM 5.3 Flash running slower at 25 tok/s prose Qwen3.8 Flash running faster at 47 tok/s prose Who will finish the task first?
27,481 görüntüleme • 1 ay önce •via X (Twitter)

0 Yorum

Yorum bulunmuyor

Orijinal gönderinin yorumları burada görünecek

Benzer Videolar

Qwen3.8-Flash-Next is starting to feel like the local model Opus fans have been waiting for. Someone ran the NVFP4 176B-class Flash-Next on 2× DGX Sparks, and the results are wild. Real measured scaling → C1: 44.2 tok/s → C2: 64.6 tok/s → C4: 86.8 tok/s aggregate The per-stream speed drops with concurrency, but total throughput keeps climbing. Long-context behavior was even more impressive: → 5K: needle retrieved → 21K: needle retrieved → 84K: needle retrieved → 167K: needle retrieved → 262K: prefill succeeded, but the window was saturated That 167K retrieval test is the one I care about. Long agent runs are where models usually start losing the plot. Flash-Next didn’t. It also held up surprisingly well on physics-heavy reasoning, artifact generation, research workflows, evidence checking, and long-horizon planning. The personality is interesting too. DeepSeek V4 Flash feels like the dependable workhorse. GLM-5.2 feels like the problem-solving machine. Qwen3.8-Flash-Next feels more insightful. It has that rare ability to understand what you’re actually asking rather than just following the surface pattern. The main weakness I’ve noticed is instruction following. It can occasionally drift between prose turns where DeepSeek and GLM stay tighter. And this is why the 256GB M5 Ultra conversation gets interesting. If Apple can pair that huge unified-memory pool with enough bandwidth, this model class becomes genuinely practical for long-running local agents. We’re talking about frontier-class reasoning on hardware sitting on a desk.

FHILY👑

20,253 görüntüleme • 2 ay önce

vllm-exl3 v0.3.0 is LIVE with custom native CUDA kernels for 2-bit EXL3 on NVIDIA DGX Spark GB10. GLM-5.3-Flash-EXL3-K2 jumped from 16.9 → 24.6 tok/s average single-stream decode, a +45.6% gain. Coding hit 27.6 tok/s, +85.6%. 🚀 The previous ExLlamaV3-backed path inside vLLM was leaving a lot of GB10 bandwidth on the table. So I rewrote the hot path specifically for EXL3 on Blackwell sm_121: → in-register Trellis dequantization → native fused MoE decode → power-of-two chunked prefill GEMM → parallel NVMe pre-warm Then I tested it side-by-side on physical DGX Spark hardware using my GLM-5.3-Flash-EXL3-K2 pack and live vLLM HTTP streaming. 🚀 𝗗𝗘𝗖𝗢𝗗𝗘 𝗧𝗛𝗥𝗢𝗨𝗚𝗛𝗣𝗨𝗧 Single-stream C1: Coding 14.9 → 27.6 tok/s +85.6% Prose 13.7 → 24.6 tok/s +79.3% Reasoning 18.9 → 25.1 tok/s +32.7% Summary 17.1 → 25.6 tok/s +50.0% Format 16.3 → 24.0 tok/s +47.7% Average: 16.9 → 24.6 tok/s 𝗡𝗘𝗧 𝗚𝗔𝗜𝗡: +45.6% ⏱️ 𝗙𝗜𝗥𝗦𝗧-𝗧𝗢𝗞𝗘𝗡 𝗥𝗘𝗦𝗣𝗢𝗡𝗦𝗜𝗩𝗘𝗡𝗘𝗦𝗦 Coding TTFT: 2,344 ms → 859 ms That is a 63.3% reduction, or about 2.7× faster to first token. Follow-up turn with prefix cache hit: 5,608 ms → 3,588 ms 1.56× faster. ⚡ 𝗪𝗛𝗔𝗧 𝗖𝗛𝗔𝗡𝗚𝗘𝗗 𝗢𝗡 𝗧𝗛𝗘 𝗚𝗣𝗨 40 routed-MoE layers: 19.9 ms → 11.5 ms per token Per-layer MoE compute: 497 μs → 287.8 μs That removes 8.4 ms of MoE compute from every generated token. Total per-step wall time: 59.2 ms → 40.6 ms -31.4% The key is `p2b_fused_moe`. Instead of expanding EXL3 weights through a traditional intermediate path, the new kernel performs Trellis dequantization in-register while executing the routed expert computation. The weights stay compressed until the GPU actually needs them. 🔥 𝗣𝗥𝗘𝗙𝗜𝗟𝗟 𝗚𝗢𝗧 𝗔 𝗡𝗔𝗧𝗜𝗩𝗘 𝗣𝗔𝗧𝗛 𝗧𝗢𝗢 The new `exl3_gemm` uses power-of-two chunked prefill GEMM. Measured: 7.85 TFLOPS 13.0× faster than the legacy prefill kernel 1,875 tok/s cold prefill sustained across 65K context 💾 𝗧𝗛𝗘 𝗕𝗢𝗢𝗧 𝗣𝗔𝗧𝗛 𝗡𝗘𝗘𝗗𝗘𝗗 𝗪𝗢𝗥𝗞 𝗧𝗢𝗢 Loading a ~91 GiB model is part of the user experience. Standard shard loading is mostly serial. The updated recipe parallelizes NVMe pre-warm across 8 workers so the storage controller gets used properly instead of feeding a ~100 GiB model one shard at a time. That turns boot-time storage into another optimization target instead of something we simply accept. 💡 𝗧𝗪𝗢 𝗦𝗘𝗥𝗩𝗜𝗡𝗚 𝗙𝗟𝗔𝗚𝗦 𝗪𝗢𝗥𝗧𝗛 𝗞𝗡𝗢𝗪𝗜𝗡𝗚 `--long-prefill-token-threshold 1024` Prevents giant prefill chunks from monopolizing step budgets and starving parallel decode sessions. `--enable-prefix-caching` Avoids paying for the same conversational prefix again on follow-up turns. 📦 𝗘𝗩𝗘𝗥𝗬𝗧𝗛𝗜𝗡𝗚 𝗜𝗦 𝗢𝗣𝗘𝗡 vllm-exl3: GLM-5.3-Flash one-Spark recipe: Model: This is why I like working at the kernel level. The model did not change. The quant did not change. The hardware did not change. The execution path did. 16.9 → 24.6 tok/s. 🛠️ vLLM turboderp

Cruz

21,720 görüntüleme • 2 ay önce