Video yükleniyor...
Video Yüklenemedi
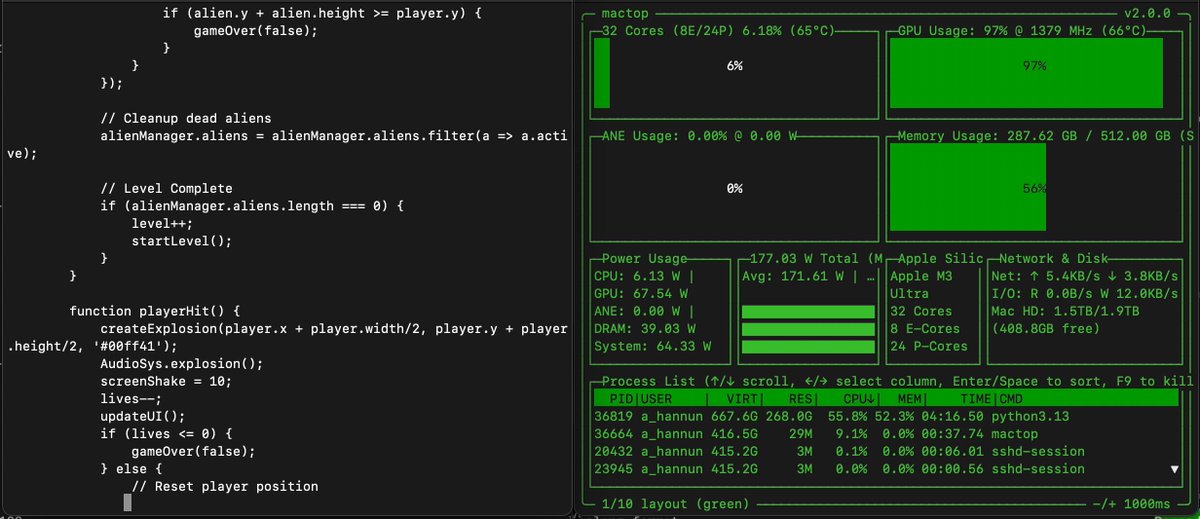
OpenCode + GLM-4.7-Flash 8bit. llama-server vs mlx_lm.server. Using one M3 Ultra for each host. Same prompts, you can check duration for each step in the video. Amazing experience on both side! Local coding AI model are becoming reality! 🔥
52,143 görüntüleme • 9 ay önce •via X (Twitter)
31 Yorum

having some issues with llama-server. feels like this version works way better than the one i’m on. the model never stop and just keeps responding. on unsloths gguf rn

Update to latest 7820 and use: llama-server \ --model ~/models/GLM-4.7-Flash-Q8_0.gguf \ --host 127.0.0.1 \ --port 8080 \ --ctx-size 202752 \ --predict 131072 \ --temp 0.7 \ --top-p 0.95 \ --min-p 0.01 \ --gpu-layers all \ --kv-offload \ --cache-type-k f16 \ --cache-type-v f16 \ --parallel 1 \ --cont-batching \ --no-warmup
this fixed it, ty one thing i found - with Q8_0 model (30GB) + f16 cache at 200K ctx, you need ~50GB VRAM which overflows the L40S swapping to --cache-type-k q8_0 --cache-type-v q8_0 cuts cache in half 40GB total, fits clean on 48GB
running on L40S via DigitalOcean (had some free credits lol). getting 97 tok/s with flash attn auto-enabled. appreciate the help

This is great. I’m going to buy a decent machine with the new M5, I really want to be able to do this and have decent local models at work.
M5 🔥🔥🔥

What hardware do you run, mac studio?
Yes, two of them.
Well there goes the family vacation budget 🤣
Wait for the M5! 😉
totally

Is it good??
Yes, fast and good enough. It's not Opus, it's ok if you drive specific changes in the code.

Amazing progress for on-device AI

Honestly, I think the way prices are becoming cheaper by the day, Running it locally is great for learning and backup, but I think using the cloud services is probably the best path
I agree in the short run, but long run, if we'll have enough local power, why not?
Yes, I agree. I think the bigger point is by the time you get enough power on your local compute rigs. The cloud providers will have stayed ahead by two or three exponents and you can get today's cloud performance in 2 years on local but that be like using GPT 3 right now

When do you think local LLMs will be affordable?
This year!
By a better Hardware or a better LLMs/Spare attentions?

much envy i have
M5 is needed, this is good enough, but we need more GPU power to really push Local coding AI to the max!

which one had better latency tho? and did you notice any memory issues?

try pi

Meh i should see what i can get away with on my m4 max 128gb ram

interesting how they’re different. could it just be temperature vs different inference engines?

Yeah all we need is quality and we are off to the races.

I was experimenting with this same setup on my m4 max and it is incredible. Although at some point I did thought that claude code is beemttwr but this is definitely better than what we we're doing 6 months back.

That’s exciting!

local coding models are def the future! how did you find the performance differences on M3 Ultra? 🔥

Same tech can produce wildly different results depending on the setup. You're highlighting the importance of optimization in local AI models. Makes me wonder what other hardware combinations could lead to similar breakthroughs.