Video wird geladen...
Video konnte nicht geladen werden
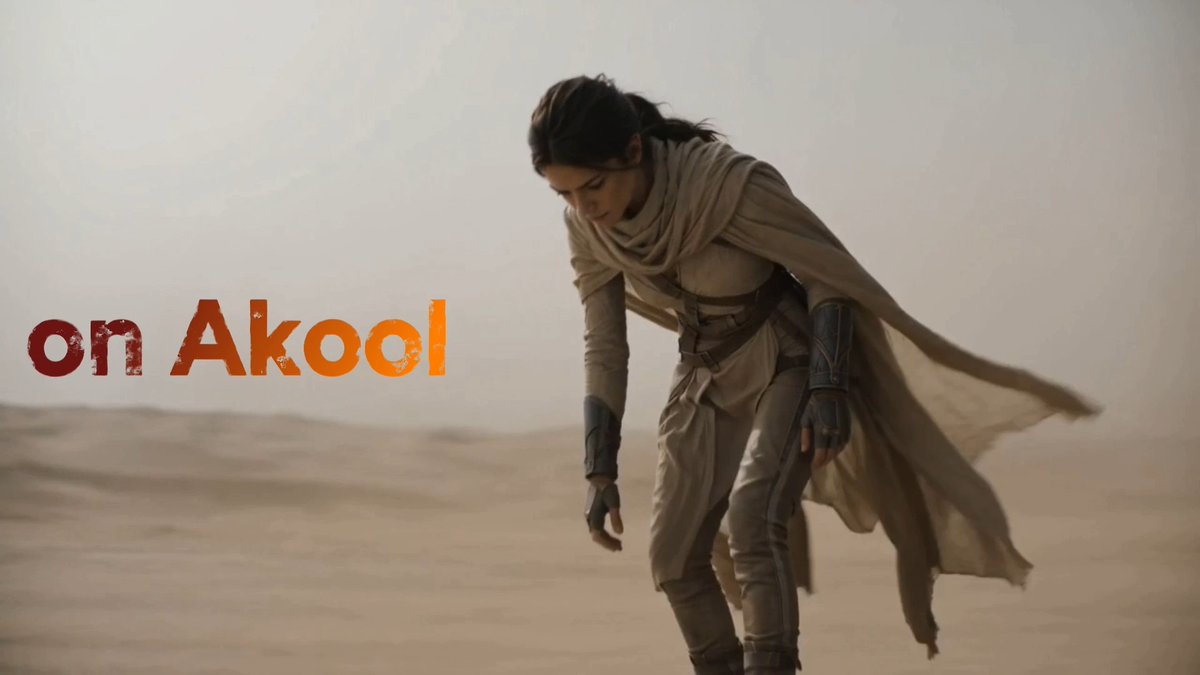
Open-source video generation is now faster than playback without compromising quality. Introducing Video Delta Net (VDN): hybrid attention for live text-to-video with near-lossless quality. VDN accelerates Minimax-H3 by 75 - 90 x, generating 14 seconds of 768p video in 11 seconds on 8× NVIDIA B200 GPUs. Checkpoints + training/inference... show more
443,511 Aufrufe • vor 1 Monat •via X (Twitter)
48 Kommentare

(2/6) Why hybrid attention? Softmax attention accounts for >85% of MiniMax H3’s runtime. But replacing it entirely with linear attention can sacrifice fine details and long-range consistency. VDN keeps local Softmax for nearby frames and uses our Video Delta Attention for distant context.
(3/6) Video Delta Attention (VDA) makes the delta rule video-native. Unlike LLMs, which update memory token by token, VDA lets all spatial tokens within a frame jointly solve for a single state update—capturing their correlations while remaining stable.
(4/6) To adapt pretrained H3 without destroying what already works, we use: - Layer-wise linear-attention alignment - End-to-end branch adaptation - LoRA co-adaptation We then add DMD2 distillation for 8-step generation. Most of the pretrained backbone remains frozen.
(5/6) With dedicated kernels, VDN-H3 reduces per-layer latency by 2.95× on H200 and 2.65× on B200. We also design branch-specialized Ulysses sequence parallelism. Combined with 8-step distillation, VDN-H3 generates 14.3s of 768p video in 11.23s on 8×B200 GPUs.
(6/6) VDN-H3 is only the beginning. We’re excited to explore hybrid attention for longer, faster, and truly live video generation. Code: Weight: Blog: Amazing team effort—full credits in the blog. @YimingXie4 @zhaohexu2001 @YiwenZhangYZ @ Michael Liu @KurtKeutzer @xiuyu_l @LvZhaoyang @Chenfeng_X @HavenFeng
Clarification: 75× and 90× are compared against the single-GPU generation, which incorporates techniques including attention optimization, quantization, distributed inference, and few-step distillation. Under the 8-GPU generation setting, our method still leads to 10.7× and 13.5× speedup on B200 and H200, respectively.

That’s great … but. Come on. That’s not impressive. 8 B200? Tell me faster than real time on a single RTX5090 then I will be impressed

Interesting work! The core VDA update seems mathematically equivalent to the implicit frame-level delta update I derived in an earlier blog post of video-delta-rule: Am I missing any key differences?

Amazing!
🚀🚀🚀

@naval impressive work, congrats on the launch!
@naval 🚀🚀

Who the fuck cares it requires a farm of data enter gpus

Thanks for your work Hao, have you guys tried to quant it down to fit it in consumer grade GPUs and see how does it score vs FastH3?

@naval @yellingfore

Amazing work!
🚀🚀🚀

Anyone have eight B200s you want to lend me to try this out?

Congrats Haocheng!
🚀🚀🚀

Fancy!

Amazing work!

Now let’s try that on a 5090
Amazing
🚀🚀🚀

Amazing!
🚀🚀🚀
Ref model capabilities with this?

sheesh congrats this is crazy work

Can these improvements be applied to local video generation ?

For a moment I thought this might affect me in some positive way.

How do I try this on Mac

Awesome work!

Congrats!
🚀🚀🚀

14 seconds of 768p in 11 seconds flips the bottleneck. you're waiting on the prompt loop, not the render. local softmax for nearby frames is why they didn't just ship pure linear and call the 90x done.

75-90x is insane speedup

Faster than playback is a weird sentence until you see the numbers.

Amazing!
🚀🚀🚀

Amazing!
🚀🚀🚀

super cool!

@naval 👏👏

Without compromising quality. Then proceededs to say it's lossless.

75-90x acceleration is wild for video generation.

Benchmark on 3090?

I made linear attention work, actually.