Загрузка видео...

Не удалось загрузить видео

На главную

OPUS 5.5 + DOTS + JEV closed 312 tickets in one week while 25 engineers closed 96... that org chart costs $343,750 a month in payroll the agent costs $2,055 a month in tokens, 167x less the code comes from Opus 5.5, the tests from Dots, and nothing reaches...

18,764 просмотров • 6 дней назад •via X (Twitter)

Комментарии: 5

Фото профиля Egor
Egor6 дней назад

the 41% comparison covers coding time, not the full engineering role

Фото профиля BreezeOg
BreezeOg5 дней назад

312 tickets is a serious gap but the payroll math is the wild part

Фото профиля magsimich
magsimich5 дней назад

Hype of opus 5.5 is really insane

Фото профиля jimerrors
jimerrors6 дней назад

数据很唬人,但有个细节值得抠一下:这 312 个工单里简单重复型占多少?人和 AI 接的工单难度分布一样吗?很多这类对比都是拿 AI 跑低难度工单去比工程师全量,口径不对齐。再就是关闭的定义,自动关和人工复核关差很多。

Фото профиля Enzo
Enzo6 дней назад

Your own numbers make the opposite point: if only 41% of engineering time is writing code, the agent replaces 41% of work, not 25 engineers. The other 590 hours (review, on call, customers deciding) are still sitting there.

Похожие видео

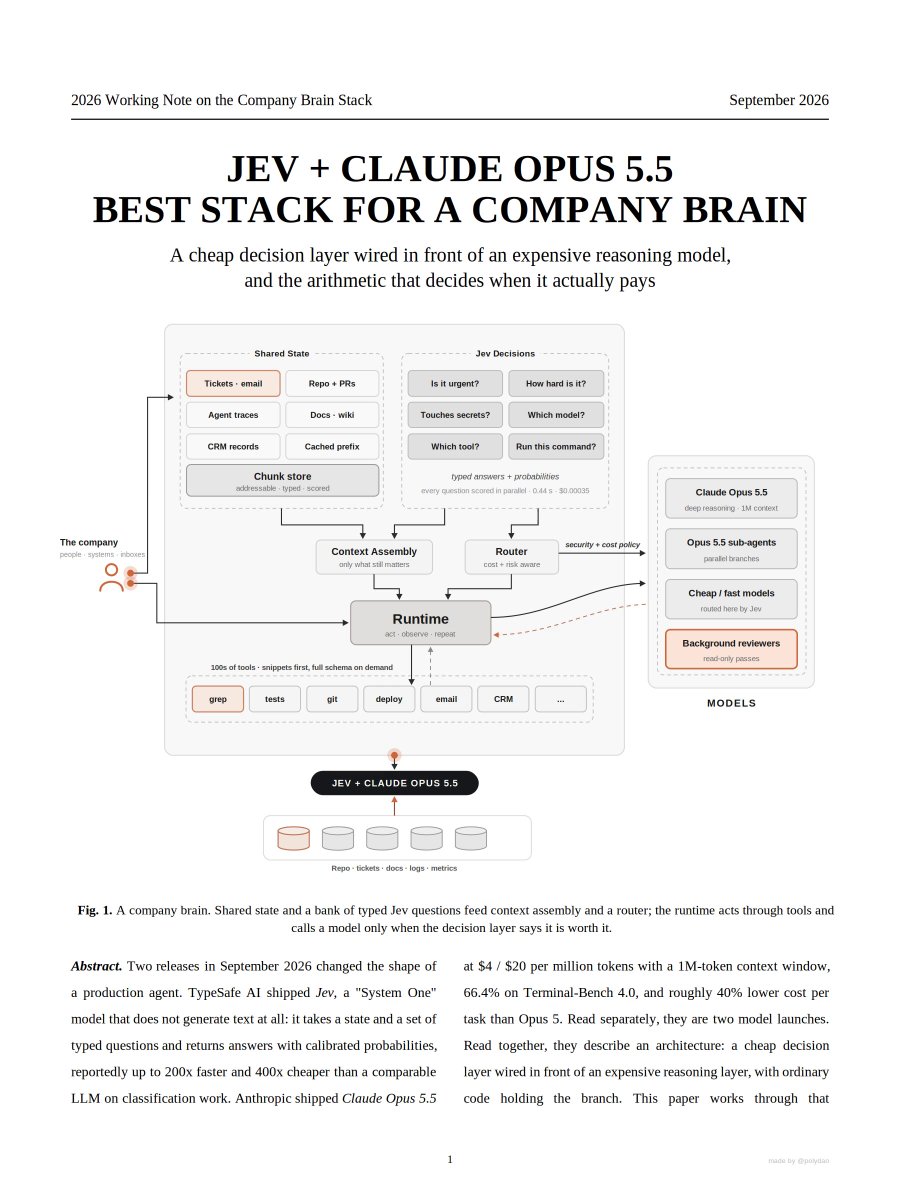
JEV + OPUS 5.5 IS INSANE FOR BUILDING A COMPANY BRAIN I pulled the whole architecture out of the TypeSafe and Anthropic docs and packed it into a 14-page PDF the 10 steps: 1. meet the pair > Opus 5.5 thinks, Jev decides, your code holds the branch 2. stop asking a text generator for a yes or no > Jev returns a typed answer with a calibrated probability in 0.44s for $0.00035 3. ask everything at once > Choice, Score and Noul run in parallel, so the fourth question costs almost nothing 4. branch on the number > 0.999 goes straight into the if statement. ~99% of turns end right here 5. stop routing blind > Opus 5.5 to Sonnet and back costs 5.84 against 3.32 for staying on 5.5 6. keep one context warm > cache reads at $0.20 per Mtok are 20x cheaper than a fresh load 7. escalate the hard part > the toughest 1% goes to Opus 5.5 with 1M context and 66.4% on Terminal-Bench 4.0 8. score every chunk on every query > keep whole, summarize or drop. the context gets rebuilt each turn 9. gate the actual command > every bash call gets classified before it runs, inside your own code 10. judge 100% of runs > $3.50 a day for 10,000 traces, and it matched the human label on all 500 decisions the result: a while loop that paid a frontier model for every tiny call turns into a brain that spends a fraction of a cent to notice and pays properly only when it has to think the person who brings this into their team walks into the budget meeting with the AI bill cut and the output up the PDF maps the company brain. the loop side of it - how Jev takes a Claude bill from $765 to $3 a month - is in the article below ↓

Mr. Buzzoni

103,282 просмотров • 11 дней назад

A one-man trading hedge fund now costs about $100 a month in AI subscriptions. Five PhDs on a Citadel desk cost $270,000 a month, and that is the cheap end. That buys one tested idea a month. Man Group's AI writes hundreds of new signals a week, on a floor where the humans used to manage twenty in a quarter. Fifty AI agents do the reading and the writing. One of them exists only to destroy what the others build, and that one is the reason any of it works. Every job on that payroll is now an agent you can run yourself: > AI research agents reading filings, transcripts, options flow and on-chain data overnight, fifty personas at once, none of them allowed to see what the crowd is pricing > coding agent that turns one sentence of plain English into entry rules, exit rules, sizing and risk limits, then debugs itself until it runs > backtest agent that replays five years of that idea in about 12 seconds > breaker agent, an AI whose only job is killing the thing, at double the trading costs and in the ten worst markets that asset has ever seen > critic agent that reads your journal and names the mistake you keep making Nobody on that list asks for a bonus in January. $200 million is already run this way on one platform where 52,000 people mostly sit and watch the machine work. The full map of what is built and what is missing is in the article below. Bookmark & read it If you're not yet using AI in your trading and investing.

cvxv666

173,490 просмотров • 1 месяц назад

This is f*cking insane. This Claude Code tip saved me thousands of dollars. once Opus 5.5 is your main model, stop burning it on work Sonnet 5.5 can do, while Fable 5.1 sits idle hand the grunt work to Sonnet 5.5 subagents and put Fable 5.1 on call run /advisor fable Opus 5.5 plans and ships the final code Sonnet 5.5 subagents read, edit and run the tests Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Sonnet 5.5 builds. Fable 5.1 reviews. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split anyone still running one model for everything is paying Opus prices to decide whether a file exists - the full tree > Opus 5.5 on high runs the main session > explorer reads the code on Sonnet 5.5 > worker edits and runs tests on Sonnet 5.5 > researcher pulls the docs on Sonnet 5.5 > all three on medium > Fable 5.1 on call for main and every subagent paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

48,238 просмотров • 6 дней назад

Claude Code tip: once Opus 5.5 is your main model, stop leaving Fable 5.1 sitting idle and stop burning Opus tokens on tasks Sonnet 5.5 can swarm put it on call with /advisor run /advisor fable Opus 5.5 plans and ships the code Sonnet 5.5 swarms the routine work at medium effort Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Fable 5.1 reviews. Sonnet 5.5 executes. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big model only sees the ones that split Plan on high. Delegate on medium. Keep Fable on call. - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on Sonnet 5.5 at medium effort > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

mirku

421,226 просмотров • 10 дней назад

This Chinese developer runs 9 agents on Claude Code under a GPT-5.5 orchestrator and they close 500 client tasks a month without a single assistant. His client work is closed without him, on a single laptop and only three subscriptions. The entire system lives on one MacBook Pro M4 with 128 GB of memory and subscriptions to Claude Code and GPT-5.5 cost him approximately $300 a month. There is no CRM, no team, no office only a terminal window with 9 parallel streams. The orchestrator works with a simple system prompt: «You are the orchestrator of a client inbox. Classify every incoming email into 4 categories: code, content, analysis, communication. Delegate to the corresponding worker agent. When the result is ready, check it for completeness, send it to the client on my behalf, and mark the task as closed. Do not ask clarifying questions.» And the orchestrator checks the inbox every 30 seconds, classifies fresh emails, and distributes them to 9 worker agents on Claude Code, each of whom is responsible for their own class of tasks. Here is an example of how one of them closes a request to refactor a client's auth module: Task: refactor user-auth module Broke the monolith into 3 files by responsibilities Added unit tests, coverage increased to 87% Renamed 4 functions to camelCase according to the style guide PR is ready for review, link below» And so about 50 cycles a day. By noon 25 tasks are closed, by dinner 50, and by the end of the month 500. On average, it takes about 7 minutes from the appearance of an email in the inbox to sending the result to the client. This is more than what a live team of 6 developers, copywriters and analysts working 8 hours a day closes. This is no longer an agency. This is a workstation where an orchestrator replaces a manager, and 9 worker agents replace the staff. The pipeline goes from inbox to closing 500 times a month without human participation at any step.

Blaze

29,917 просмотров • 5 месяцев назад