Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

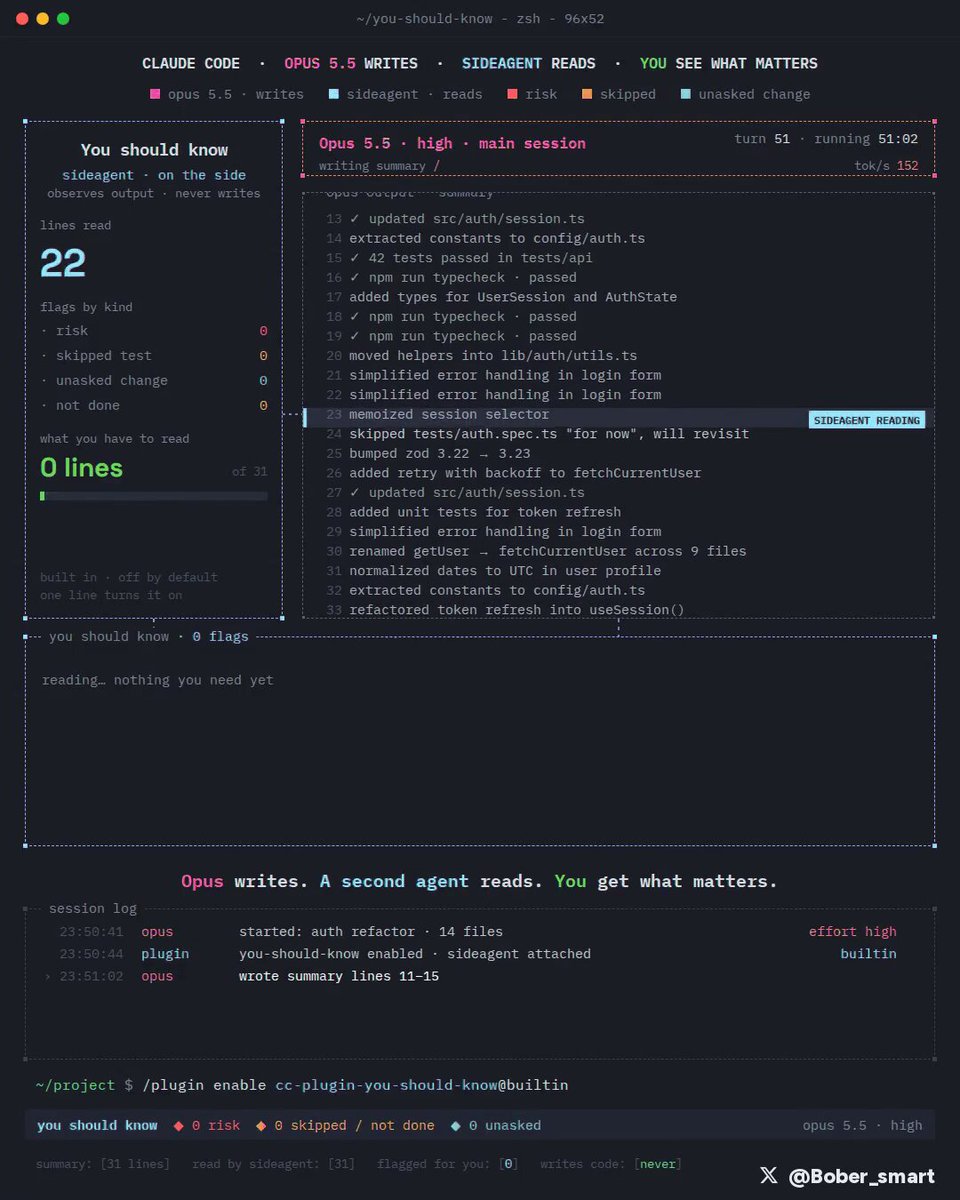
OPUS 5.5 SHOULDN'T BE DOING THE WORK. It should be writing the PLAN. Claude Code workflows let Opus write a script that runs a whole swarm of agents in the background. Opus plans. Haiku 5.5 scans every file in parallel. Sonnet 5.5 makes the fixes. A verifier checks every...

20,450 görüntüleme • 5 gün önce •via X (Twitter)

0 Yorum

Yorum bulunmuyor

Orijinal gönderinin yorumları burada görünecek

Benzer Videolar

By tomorrow, everyone will be using this: Anthropic just revealed the ultimate power move for Claude Code The concept: have Opus 5.5 design the master plan as a script, then deploy parallel swarms of the new Haiku 5.5 Massive scale operations with zero wasted Opus compute: the script manages the execution loop so Opus only reviews the final diff Simply boot up Claude Code with these parameters: claude --model opus --effort ultracode Here is the task distribution: -> Opus 5.5 translates your target into a fully runnable workflow script -> Haiku 5.5 scans all files concurrently at 340 tokens/sec to spot candidates -> Sonnet 5.5 applies each patch and validates findings within an isolated workspace -> You eliminate wasting Opus context on dozens of agent log transcripts Opus is involved at only three specific steps: -> writing the initial workflow script before execution -> analyzing verified results once the swarm wraps up -> giving final approval prior to committing any code to git Opus architects | Haiku audits | Sonnet delivers JEV engineering applies the exact same principle a level deeper: logic paths that require no deep reasoning (choosing files, picking tools, handling retries/stops) pass through JEV in milliseconds, leaving heavy models to focus only on complex branches The complete architecture: Opus 5.5 orchestrates the core session and generates workflow.js pipeline() fans out instances of Haiku 5.5 to inspect every file parallel() schema validators eliminate false alarms directly in V8 Sonnet 5.5 applies fixes within dedicated, isolated worktrees verify double-checks all code diffs prior to summary generation Opus 5.5 processes exclusively the results that survived validation JEV routes lightweight micro-decisions in milliseconds Feed this architecture and prompt directly into Claude Code Reconfigure my Claude Code setup following this tree: 1. Execute the primary session using Opus 5.5 with ultracode enabled 2. Assign read-only scanning phases to Haiku 5.5 across all workflows, while routing code modification steps to Sonnet 5.5, running each edit inside its own isolated copy 3. Update CLAUDE.md with a new rule: assign a separate verifier agent to every issue before reporting, and terminate fix loops after two iterations without progress 4. Route fast, deterministic branching (tool selection, path routing, retry logic) via JEV Present every modification as a diff upfront do not execute changes until approved Bookmark this to stay one step ahead

Bober_smart

32,522 görüntüleme • 4 gün önce

THIS IS F*CKING BRILLIANT. Anthropic’s docs describe one of the smartest ways to run Opus three models work on one task and each does only the part it’s cheapest at. start Claude Code like this: claude -> model sonnet -> advisor opus you stop paying Opus prices for work that doesn’t need Opus > Sonnet runs the session and edits the code > Haiku 5.5 searches the repo and docs, at up to 40x less per token than Opus 5.5 > Opus waits as the advisor and reads the whole session, tool calls included Claude usually calls Opus at three points: > before it locks a plan > when the same error comes back > right before it says it’s done Sonnet drives. Haiku scouts. Opus signs off and if you go one step lower, most of an agent’s day is tiny choices like picking a file or a tool, or deciding whether to retry. Jev takes those first, so Sonnet and Opus only see the moments that are really open the whole setup Sonnet runs the main session Explore on Haiku 5.5 searches and pulls docs, read-only Opus on call as the advisor give Claude Code this setup and the prompt below ↓ “Set up my Claude Code exactly like this: Main model Sonnet, advisor Opus, saved as advisorModel in my settings. One read-only subagent named exactly Explore, on claude-haiku-5-5, to replace the built-in one. One line in CLAUDE.md: ask the advisor before locking a plan, after the same error twice, and before calling a task done, not more often. Check what could turn the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY) and only report it. Show every change as a diff first. Don’t edit anything until I say go.” before you turn it on: every advisor call re-reads the whole transcript with no cache. on a 200k session that’s about $0.80 in input, against $0.04 for a normal request. keep it to a few calls the built-in Explore agent runs on your main model unless a subagent is named exactly Explore. any other name does nothing turning the advisor on or off keeps your prompt cache. switching models rebuilds it it needs the Anthropic API, and it stays off if telemetry is disabled bookmark it before your next long session

rvaniaaa

62,223 görüntüleme • 10 gün önce

THIS IS A PURE F*CKING GOLDMINE the best REA trick almost nobody runs yet. The idea: REA takes the app apart, Jev keeps only what's proven, and a fresh Opus 5.5 rebuilds the feature from that alone. Nothing gets copied and no guess makes it into the code, because the builder never sees the original, only the spec Jev signed off on. You just connect REA like this: npx rea-agents setup here's the split: → REA reads the feature down to the binary and writes every rule into SPEC.md → Jev checks each rule against REA's evidence and sends back anything unproven → a fresh Opus 5.5 session gets only SPEC.md and rebuilds the feature → Haiku 5.5 runs the tests against 3 intentionally broken versions Opus only shows up at three moments: → rebuilding from the approved spec → the checks Jev marks as unclear → signing off before anything ships REA reads. Jev judges. Opus rebuilds. That's the clean-room rule in one line: the model that saw the original never writes the code, and the model that writes the code never sees the original. the full tree > REA reads the app and writes SPEC.md with evidence for every rule > Jev approves or returns each rule > Opus 5.5 rebuilds from the approved SPEC.md in a fresh session > Haiku 5.5 runs the tests and the 3 broken versions > Jev routes unclear checks back to Opus > /goal keeps going until all 3 broken versions fail paste the tree and this prompt into Claude Code ↓ "Set up a clean-room rebuild around this tree: 1. Use REA to investigate [FEATURE] in [APP]. Write every behavior and rule into SPEC.md, each with the evidence REA found. 2. Send each rule to Jev. Any rule without evidence goes back to REA. 3. Start a fresh session with only SPEC.md. Rebuild the feature on Opus 5.5 without opening the original. 4. Write tests on Haiku 5.5 plus 3 intentionally broken versions. Use /goal until the rebuild passes and all 3 broken versions fail. Show me SPEC.md first. Nothing gets built until I say go." ↳ save it, it'll come in handy.

Archive

59,706 görüntüleme • 6 gün önce

Claude Code tip: if Opus 5.5 is already your main model, Fable 5.1 has been sitting idle this whole time. wire it in with /advisor start it with /advisor fable Opus 5.5 writes every line. Fable 5.1 reads the whole session, every tool call, and says nothing until one of three moments: → a plan gets proposed: is this actually the right move, or just the first one? → the same error comes back twice: is the search stuck, or is this a dead end? → the task gets marked done: what got missed while it was moving fast? Opus 5.5 ships. Fable 5.1 catches what would've shipped broken. Jev engineering makes the same move one layer down: forks that don't need a real thinker, which file, which tool, retry or give up, get routed to Jev and answered in under half a second. the expensive model only ever sees the forks that genuinely split. the tree this runs on: > Opus 5.5, high effort, owns the main session > explorer, medium effort, reads the code > worker, medium effort, edits and runs tests > researcher, medium effort, pulls the docs > Fable 5.1 outside all of it, on call, never writing a line itself drop the tree and this prompt into Claude Code: "Rebuild my Claude Code setup around this tree: 1. Look in ~/.claude/agents and .claude/agents for subagents that already cover explorer, worker and researcher. Draft new ones only for roles that are missing. Set each to model: opus, effort: medium. If an existing subagent is pinned to a different model, list it, don't touch it. 2. Set the main session's effortLevel to high in ~/.claude/settings.json, and set advisorModel to fable. 3. Check for anything disabling the advisor: CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable blocking feature-flag fetches, and CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report what you find. Change nothing yet. 4. Add one line to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before marking a long task done. Show every change as a diff first. Don't touch anything until I say go."

Ryven

36,121 görüntüleme • 21 gün önce

This is f*cking insane. This tip saved me thousands of dollars. run Opus 5.5, Sonnet 5.5, and Fable 5.1 together, and stop burning Opus on work it was never needed for. the whole idea in one line: the strong model plans, the mid-tier model executes, Fable stays quiet until it's actually needed. roles, broken down: Opus 5.5, high effort, owns the plan and ships the final code Sonnet 5.5, medium effort, splits into explorer (reads the codebase), worker (edits files, runs tests), researcher (pulls docs) Fable 5.1, called through /advisor fable, reads everything happening in the session but stays silent unless something's actually wrong three moments where Fable speaks: → a plan goes out: is this actually the right call? → the same failure shows up again: is the search going nowhere? → the task gets marked finished: did something get skipped? Jev engineering does the same thing one level down. the forks that don't need real thought, which file, which tool, keep going or stop, go straight to Jev and come back in under half a second. the big models only ever see the forks that genuinely need a decision. anyone still running one model for everything is paying Opus prices to decide whether a file exists. drop this into Claude Code: "Rebuild my Claude Code setup around this structure: Look through ~/.claude/agents and .claude/agents for subagents already covering explorer, worker, and researcher. Only create new ones for roles that are missing. Set model: sonnet, effort: medium on each. If an existing subagent is locked to a different model, leave it as is and just list it. In ~/.claude/settings.json, set effortLevel to high and advisorModel to fable. Check for anything disabling the advisor, CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, or anything blocking feature-flag fetches, plus CLAUDE_CODE_EFFORT_LEVEL, which can override subagent effort settings. Report what you find. Don't change any of it yet. Add one line to ~/.claude/CLAUDE.md: check in with the advisor before a big plan, when the same error shows up twice, and before marking a long task done. Show every change as a diff first. Wait for my go-ahead before touching anything."

rvaniaaa

254,273 görüntüleme • 20 gün önce