正在加载视频...

视频加载失败

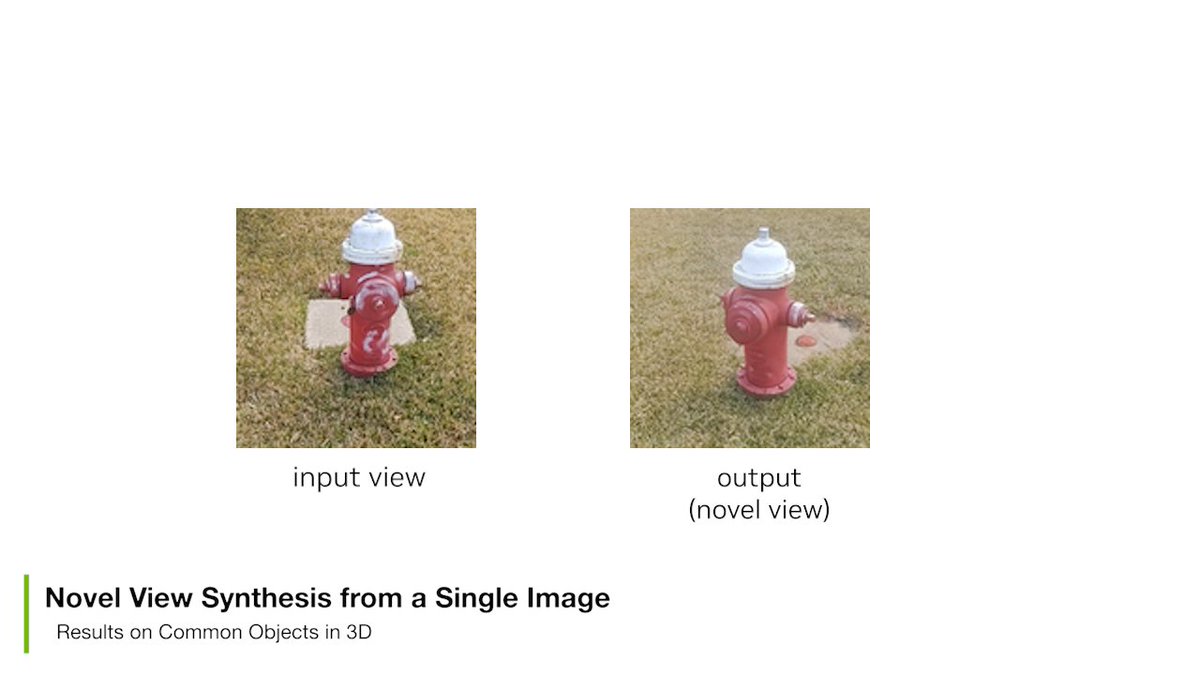
Our new work PSHuman reconstructs a detailed 3D human mesh from a single-view image in ~1min. Codes have already been released! Welcome to try it! Project page: Codes: Paper:
53,252 次观看 • 1 年前 •via X (Twitter)

10 条评论

Yuan Liu 的头像
Yuan Liu1 年前

The key idea is to adopt the multiview diffusion to generate novel-view images and normal maps. Then, we apply inverse rendering techniques to reconstruct the textured human meshes. We improve face reconstruction with a global-local denoising scheme.

jason rugolo 的头像
jason rugolo1 年前

incredible work

Roman 的头像
Roman1 年前

Great! I tried to replicate my wife in blender modifying a human model, now i suppose i'd just have to take a pic of her in A-pose, use PSHuman then add bones/rig in blender? 😃

Ulysse Mizrahi 的头像
Ulysse Mizrahi1 年前

What's the novelty compared to any image to mesh techniques which exist today? Also I'm seeing a bunch of seam artifacts on the textures

Yuan Liu 的头像
Yuan Liu1 年前

We add SMPL skeletons to guide the diffusion process, generate 6 novel-view images, and improve the face regions with a new denoiser. The multiview-to-mesh reconstruction follows Unique3D but initializes from SMPL.

Turbotardo 的头像
Turbotardo1 年前

Now do that for cats please

Hector 的头像
Hector1 年前

can this be ported to say fbx format? say unreal engine's metahuman face and body?

Yuan Liu 的头像
Yuan Liu1 年前

We are not so familiar with UE and probably cannot support it. This may not be directly applicable to Game development, which still requires additional efforts in remeshing, animation, etc.😊

Synthical 的头像
Synthical1 年前

Dark mode for this paper 🌚

XJournalK 的头像
XJournalK1 年前

Anywhere a user can try?

相关视频

One-2-3-45: Any Single Image to 3D Mesh in 45 Seconds without Per-Shape Optimization paper page: Single image 3D reconstruction is an important but challenging task that requires extensive knowledge of our natural world. Many existing methods solve this problem by optimizing a neural radiance field under the guidance of 2D diffusion models but suffer from lengthy optimization time, 3D inconsistency results, and poor geometry. In this work, we propose a novel method that takes a single image of any object as input and generates a full 360-degree 3D textured mesh in a single feed-forward pass. Given a single image, we first use a view-conditioned 2D diffusion model, Zero123, to generate multi-view images for the input view, and then aim to lift them up to 3D space. Since traditional reconstruction methods struggle with inconsistent multi-view predictions, we build our 3D reconstruction module upon an SDF-based generalizable neural surface reconstruction method and propose several critical training strategies to enable the reconstruction of 360-degree meshes. Without costly optimizations, our method reconstructs 3D shapes in significantly less time than existing methods. Moreover, our method favors better geometry, generates more 3D consistent results, and adheres more closely to the input image. We evaluate our approach on both synthetic data and in-the-wild images and demonstrate its superiority in terms of both mesh quality and runtime. In addition, our approach can seamlessly support the text-to-3D task by integrating with off-the-shelf text-to-image diffusion models.

AK

179,061 次观看 • 3 年前