Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

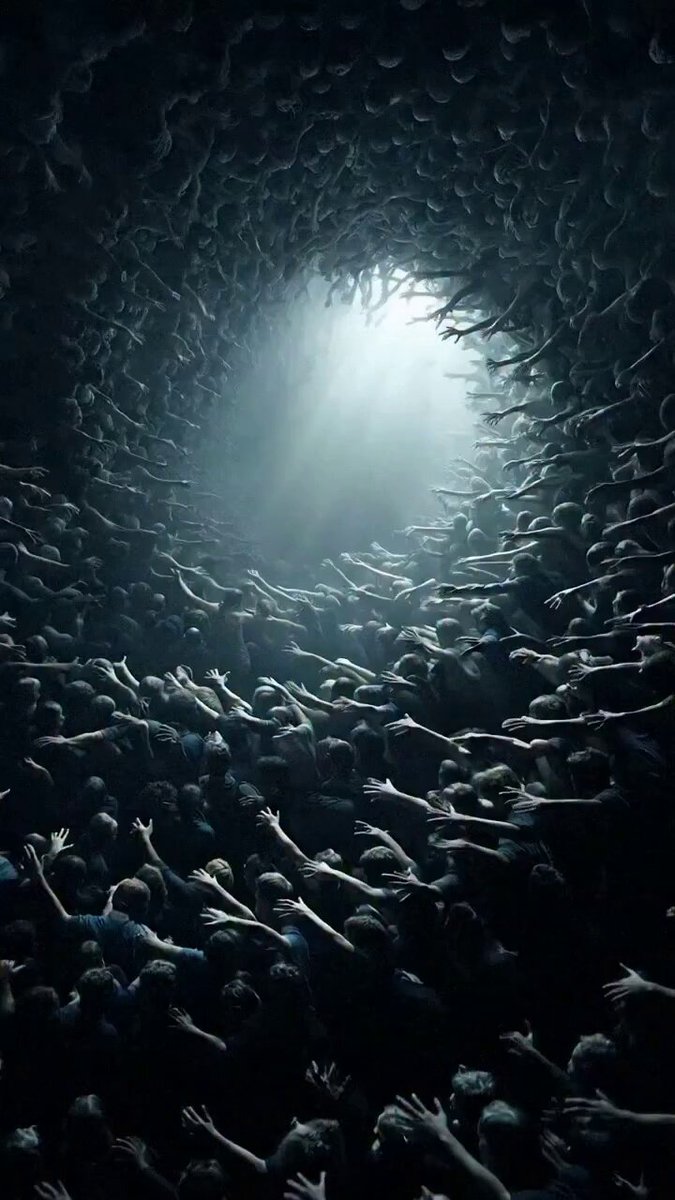
Proudly introducing my upcoming series, "Conversations between Nature’s Memory" 🏞️🧠 What if nature could remember? What if forests, roots, fungi, and soil were constantly speaking to each other through invisible systems we never learned how to hear? Conversations between Nature’s Memory imagines a living dialogue between two interconnected ecosystems,...

85,095 Aufrufe • vor 4 Monaten •via X (Twitter)

40 Kommentare

Profilbild von orkhan
orkhanvor 4 Monaten

Conversations between Nature’s Memory 420 artworks deployed via @TransientLabs 🖼️🔗 ▶️ Collectors Phase Date: 29 MAY 2026, 2PM UTC Price: 0.069 ETH ▶️ Public Phase Date: 29 MAY 2026, 4PM UTC Price: 0.1 ETH Post-release raffle for holders: • 2 Upframe displays from exhibition + dedicated series coffee-table book • 20 signed archival prints + dedicated series coffee-table book DM or [email protected] for any questions & direct inquiries.

Profilbild von sugargirl
sugargirlvor 4 Monaten

I've been following your works since 2 years now if I'm not mistaken and I'm looking forward to this as well. I think you need to correct the mint price to match the price you put out in your initial post about this drop. You can make a new tweet to clarify the MP. I've read the comments and seen you said its a typo. If that's the case, even the one on transient is wrong and needs to be corrected ASAP. All the best with the mint❤️

Profilbild von orkhan
orkhanvor 4 Monaten

I did already

Profilbild von sugargirl
sugargirlvor 4 Monaten

Awesome! Didn't see☺️

Profilbild von Damn
Damnvor 4 Monaten

wasnt the MP .0169 in the initial tweets?

Profilbild von orkhan
orkhanvor 4 Monaten

yes, it was a typo.

Profilbild von Causa sui
Causa suivor 4 Monaten

😍😍😍

Profilbild von Arthr
Arthrvor 4 Monaten

@rev_ilo 👀👀🔥🔥

Profilbild von munira.base.eth
munira.base.ethvor 4 Monaten

this makes me stop and actually listen when i walk through the woods now. cant wait for the series

Profilbild von Rik Oostenbroek
Rik Oostenbroekvor 4 Monaten

Sensei please educate me

Profilbild von SARES
SARESvor 4 Monaten

So beautiful brother! Exquisite ✨

Profilbild von Deecy
Deecyvor 4 Monaten

👀

Profilbild von Assouka Karim
Assouka Karimvor 4 Monaten

Just mesmerizing!!!!

Profilbild von Biddaddy
Biddaddyvor 4 Monaten

oh damn imagining roots gossiping is wild

Profilbild von Radag.eth
Radag.ethvor 4 Monaten

Need WL boss 0xEa93FD785196e0ba1d3aace1361b541a546B6c60

Profilbild von orkhan
orkhanvor 4 Monaten

added ro waitlist

Profilbild von Radag.eth
Radag.ethvor 4 Monaten

Thank you so much♥️Love your art

Profilbild von Amal
Amalvor 4 Monaten

Love what you're doing here Orkhan!

Profilbild von StatesOf.Sats 🟧
StatesOf.Sats 🟧vor 4 Monaten

Can I still get WL? I'm proud owner of your piece on Ordinals. 0x9D6eE26A20B63BE3E24AcC56444B4Af19f67eeeA

Profilbild von Chris Abiaad
Chris Abiaadvor 4 Monaten

🔥

Profilbild von Hoss
Hossvor 4 Monaten

🔥🔥🔥🔥

Profilbild von Nari
Narivor 4 Monaten

why you raise the mp LOL

Profilbild von orkhan
orkhanvor 4 Monaten

it was a typo.

Profilbild von Fran.Cisca
Fran.Ciscavor 4 Monaten

🫡

Profilbild von Zyphar
Zypharvor 4 Monaten

dmed

Profilbild von Ul base.eth
Ul base.ethvor 4 Monaten

Did you collected my wallet? 0xb3c83b2113a23d2bb7a11740b2cb80ff14abf1d0

Profilbild von SOTA
SOTAvor 4 Monaten

Can I get wl plsssss 0xf5d105e9807900Ab00e93B93c6fDf662fbD09E21

Profilbild von 𝐀𝐫𝐨𝐱
𝐀𝐫𝐨𝐱vor 4 Monaten

letsgoo

Profilbild von DaTguY👾
DaTguY👾vor 4 Monaten

Can I still join in? 0x30d8097952a9887dc28369d49fa78d0f5dcafc4f

Profilbild von Logic
Logicvor 4 Monaten

Love this great Art collection

Profilbild von Mavi Papaz
Mavi Papazvor 4 Monaten

thank you 0x53e93cdf4326053d49420392284b420684e786aa

Profilbild von 272761 era ❤️ Memecoin
272761 era ❤️ Memecoinvor 4 Monaten

Can you please add me to the waitlist 👀 0xbB86890018A65E57289f7beC7669C8C32Ee20B7a

Profilbild von Stella.Crypto
Stella.Cryptovor 4 Monaten

Looks nice

Profilbild von HumbleMan 🛸
HumbleMan 🛸vor 4 Monaten

0xdcffeb01930102caC482bcD290e68cE404294A5B

Profilbild von Deepsan
Deepsanvor 4 Monaten

Great to hear about this update 👀

Profilbild von Tudel
Tudelvor 4 Monaten

gib WL 0x7f7a8480bd6a9f8709a5b04aef82c47b41ea0c2b

Profilbild von Chexxe
Chexxevor 4 Monaten

added to the list already, this one deserves it

Profilbild von Grebe
Grebevor 4 Monaten

the mycelium angle is the real flex here, not the ai wrapper 🔥

Profilbild von 0xArif
0xArifvor 4 Monaten

Please give me spot sir

Profilbild von EAMIN HOSSAIN
EAMIN HOSSAINvor 4 Monaten

ADDED PLZ 0x584Ae94Fd9177d42F1808a0897675Cd157B11E2c

Ähnliche Videos

An egregore is not merely a mystical idea; it is a living psychological structure. From a psychoanalytic lens, it can be understood as a shared mental ecosystem. The accumulated thoughts, emotions, fears, and longings of a group that, through repetition, begins to operate as an autonomous force. Just as the personal unconscious stores unresolved experiences and symbolic narratives, the egregore functions as a collective psyche in motion. It sustains itself through belief, emotional investment, ritualized behavior, and constant reinforcement. The more it is fed, the more real it becomes. Its influence is subtle but pervasive. Anyone entering its field begins to feel, think, and behave in alignment with its logic, often mistaking borrowed impulses for personal choice. This is why patterns echo across families, ideologies, and institutions. What appears individual is frequently inherited from the group mind. In clinical work, this emerges when a person carries guilt, obligations, or symptoms that did not originate with them alone, but were transmitted through relational and symbolic networks. The egregore is the architecture through which these imprints are organized and passed on. To recognize an egregore is to abandon the illusion of psychological isolation. Each of us is woven through invisible currents of memory, meaning, and desire. The “self” is not a closed system, but a dialogue; constantly shaped by the collective field speaking through us, even in silence.

𝚃𝙷𝙴 𝚆𝙷𝙸𝚃𝙴 𝚁𝙰𝙱𝙱𝙸𝚃

17,369 Aufrufe • vor 9 Monaten

SHE IS PLAYING A PATTERN FOUND IN NATURE The Fibonacci sequence is a numerical pattern in which each number is the sum of the two before it: 1, 1, 2, 3, 5, 8, 13, 21… This sequence appears throughout nature in growth processes, spiral formations, branching systems, and proportional structures. While living systems do not always follow Fibonacci numbers perfectly, the underlying principle remains profound… Complex form often emerges through ordered relationships built from what came before. That same principle can be applied to rhythm. In music, timing is organized through recurring intervals, subdivisions, accents, and coordinated patterns that unfold through time. In drumming, this becomes especially remarkable because the brain and body must synchronize multiple limbs at once while maintaining a coherent rhythmic structure. When a drummer translates Fibonacci-based counting into performance, mathematics unfolds via movement. The numerical pattern becomes embodied timing. To do this, the nervous system must convert number into temporal spacing, temporal spacing into coordinated motion, and coordinated motion into sound. What makes this so powerful is that Fibonacci is a recursive structure, meaning that every new value emerges from the relationship between the previous two. That means the pattern carries memory, continuity, and expansion all at once. Rhythm works in a similar way. Each phrase is shaped by what came before it and by how it resolves into the next. So when Fibonacci logic is expressed through drumming, we are witnessing proportional growth translated into sound. The bottom line is that rhythm, mathematics, and biological coordination are far more interconnected than most people realize. This is a beautiful example of how numerical order can be felt, heard, and embodied as music. Did this expand your consciousness? ✨🙌🏾💫

🧬Maxpein🧬

78,568 Aufrufe • vor 4 Monaten

RAG might already be becoming obsolete. A month ago, Andrej Karpathy dropped a simple GitHub gist called “LLM Wiki.” Now the comments section looks like the birth of an entirely new AI category. 5000+ stars later, developers are rapidly building: • persistent AI memory systems • self-maintaining knowledge bases • multi-agent research environments • contradiction detection engines • AI-native company operating systems • local-first memory architectures • graph-based reasoning layers • evolving second brains And the craziest part? Most of them were built in DAYS. Because the core idea is insanely powerful: Instead of AI repeatedly retrieving raw chunks like traditional RAG… …the model continuously maintains a living knowledge system. Not temporary context. Persistent synthesis. The shift sounds subtle until you realize what it changes: RAG: retrieve → answer → forget LLM Wiki: ingest → synthesize → evolve That one architectural difference is causing an explosion of experimentation right now. People are already building: • agent memory operating systems • AI-maintained engineering documentation • self-healing knowledge graphs • persistent research environments • conversational memory architectures • contradiction-aware wikis • context compression engines • machine-readable company systems The comments section alone feels like watching an ecosystem form in real time. One developer built deterministic contradiction detection using sheaf cohomology Another built “sleep consolidation” for AI memory systems inspired by human memory formation Another created persistent multi-agent vault conversations Another turned entire repositories into continuously maintained AI wikis Another built local-first memory systems with audit trails, provenance, graph exports, and MCP integration This is the important part: Karpathy didn’t launch a product. He introduced a pattern. And patterns are what create ecosystems. The same way: • transformers created modern AI • RAG created AI retrieval startups • agents created orchestration frameworks LLM Wikis may create persistent AI memory infrastructure. That’s why this moment feels different. For years, AI systems have been stateless. Now developers are trying to build systems that actually accumulate understanding over time. And once knowledge compounds instead of resetting… …the entire interface layer of AI changes. (Link in comments)

Suryansh Tiwari

142,314 Aufrufe • vor 4 Monaten

Google Ironwood TPU Memory Hierarchy in 9 levels by hand ✍️ 1. Bit – The most basic unit of information, the on–off decision from which every number, tensor, and model state is ultimately constructed. 2. FP8 (1×8 → 8 bits) – Eight bits are grouped to form a floating-point value, typically used for inference, where reduced precision is a deliberate trade-off to maximize throughput and efficiency. 3. BF16 (×2 → 16 bits) – Two FP8-scale chunks are combined to gain more dynamic range and stability, while still staying friendly to high-throughput hardware. 4. Tensor tile (×1024 → 1K) – Data moves through the chip in blocks of 1024 values at a time, defining the granularity at which tensors are fetched and manipulated. 5. Matrix Multiplication Unit (MXU) (×64 → 64K) – A systolic array where matrix multiplication is not abstract but physical, with tensor tiles flowing through fixed hardware to achieve the highest possible throughput. 6. Vector Memory (VMEM) (×2048 → 128M) – On-chip working memory that holds activations, partial results, and intermediates, sized specifically to keep the systolic array busy without stalling. 7. Common Memory (CMEM) (×8 → 1 GB) – A small but critical shared memory sitting between VMEM and HBM, used for staging, accumulation, synchronization, and cross-lane coordination. 8. HBM (×96 → 96 GB) – Off-chip high-bandwidth memory where model weights and large states live, implemented as HBM3e with 16 stacks at 6 GB each, for a total of 96 GB. 9. Dual-Die (x2 → 192GB) – Two tightly coupled compute dies operate as a single logical accelerator, each with its own local HBM, effectively doubling memory capacity and bandwidth while allowing tensors and activations to stream seamlessly across dies as if they lived on one chip. I created this drawing for this week's seminar. I’ll take you through these 9 levels in a beginner-friendly way by hand ✍️. RSVP 👉

Tom Yeh

30,489 Aufrufe • vor 8 Monaten

Only 3 in 10 Americans socialise on a daily basis. So how good are we ACTUALLY at talking to each other anymore? Vanessa Van Edwards believes we’re living through a “connection crisis”, where conversations are becoming harder, more awkward and less satisfying, while more of our interactions are moving away from real face-to-face conversation. Vanessa is a behavioural researcher, international bestselling author and instructor at Harvard University whose work studies how people communicate, connect and understand each other. And she said something to me early in this conversation that really stayed with me: people who invest in conversation skills now are creating “career insurance”. She has spent years studying why some conversations seem effortless, why others die within minutes and what the best conversationalists are doing differently. We discussed things like: - Why “how are you?” and “what do you do?” can lead to dead-end conversations. - The 3 levels of conversation and how to move from small talk into real connection. - How awkward silence is one of our biggest conversational fears. - The questions that reveal someone’s values, motivations and personality. - 5 self-narratives that can influence how someone behaves at work and in relationships. - Why becoming better at conversation could become increasingly valuable as AI changes how we communicate. If you want to become better at talking to people, building relationships and having conversations people actually remember, I really recommend watching this one.

Steven Bartlett

25,019 Aufrufe • vor 24 Tagen

WTF, GROK BOT JUST MADE AI AGENTS AVAILABLE TO LITERALLY ANYONE – CREATING CONTENT HAS NEVER BEEN THIS EASY, EVEN IF YOU'VE NEVER MADE ANYTHING BEFORE Content was never a talent problem. It's a headcount problem. One person doing research, design, copy, analytics, timing and publishing – that's six jobs. The switching between them is what kills consistency, not a lack of ideas. Here's what one of these setups actually looks like. A Chief of Staff sits in the middle and routes every task. Nothing lands on the human. → Researcher tracks what's actually moving and pulls real sources instead of guesswork → Writer turns that research into finished copy, ready to review → Visualiser gets fed a few reference visuals once, then ships everything in that style → Analyst reads the numbers and tells the rest of the team what worked → Scheduler owns timing and holds the queue → Publisher ships it The part that makes it work: every agent on Grok Bot gets its own persistent computer, browser and file system – and they all share memory. So the research is already sitting inside the draft before the draft starts. No copy-pasting between tools. No approving every step. No human in the middle. You can even teach an agent a repetitive task by recording yourself doing it once. Start recording, do the thing, stop. It learns the pattern. And that's the real shift. Nobody needs AI to tell them what to post. They need it to delete the 40 steps between the idea and the post. Everyone has a backlog of things they've meant to make for months. This is what starts clearing it. Full breakdown of the setup in the article below ↓

SCOTTY BEAM

4,821,782 Aufrufe • vor 1 Monat

The AI boom just hit a wall nobody saw coming. And it's not software. It's not regulation. It's not even energy... It's memory chips. Right now, Dell is raising PC prices by 30%. Intel can't ship chips. Nvidia is slashing GPU production by 40%. And almost nobody understands why. Here's the "hidden" crisis the AI industry is trying to hide: AI data centers are hoarding memory. Not GPUs. Not processors. MEMORY. Every AI server needs massive amounts of high-bandwidth memory (HBM) to run those models everyone's hyping. One problem: There are only 3 companies in the world that can make it. Samsung. SK Hynix. Micron. That's it. And all 3 just diverted their entire production capacity away from normal RAM to feed AI data centers. The math that breaks everything: 1 gigabyte of HBM takes 4X the manufacturing capacity of regular DRAM. AI will consume 20% of global DRAM production in 2026. But the thing is, consumer demand for RAM didn't disappear. PCs still need memory. Phones still need memory. Cars still need memory. But there's no capacity left to make it. The price explosion: RAM prices are up 246% in the last 6 months. DDR5 contract prices jumped 100% month-over-month in some cases. Dell's CFO said he's "never witnessed costs escalating at this pace." SK Hynix and Micron? Sold out through all of 2026. Micron straight up EXITED the consumer memory market entirely to focus on AI customers. If you're not building an AI data center, you're not getting memory chips. AI data centers pay 3-5X margins compared to consumer products. So memory manufacturers are rationally choosing: Serve Microsoft and Google's AI buildout, or serve Dell's laptop business? Easy choice. Every wafer allocated to an Nvidia H100 GPU is a wafer DENIED to your next laptop. It's a zero-sum game. And consumers are losing. The dangerous cascade effect: Nvidia is cutting RTX 50-series GPU production by 30-40% because they can't get GDDR7 memory. Dell, Lenovo, HP are all raising PC prices 15-30% in early 2026. Xiaomi and other smartphone makers are cutting shipment targets. Even Intel's crash last week? Partially driven by memory shortages limiting chip production. This is a PERMANENT reallocation of the world's silicon capacity. Not a temporary supply hiccup. For decades, consumer electronics (phones, PCs, laptops) drove memory production. Now? AI data centers are the priority customer. And that priority shift is reshaping the entire tech economy. The timeline Is worse than you think: Industry analysts project shortages lasting through 2027, maybe 2028. Why? Because building new memory fabs takes 3-5 YEARS. Micron's new Idaho fab won't meaningfully impact supply until 2028. Samsung and SK Hynix are too busy ramping up HBM4 production to expand consumer DRAM. So we're stuck. AI companies need memory to scale. But producing that memory DESTROYS the supply chain for everything else. My question here: Everyone's betting on AI scaling infinitely. But what if the AI boom STALLS because there's not enough memory to support it? What if we're not in an "AI supercycle" but a "memory shortage that kills the AI buildout"? Intel crashed 17% because they can't manufacture enough chips. The root cause though? Memory shortages limiting what they can even produce. Nvidia is cutting GPU production by 40%. AMD is struggling to get GDDR6 for Radeon cards. This isn't just a consumer problem. It's an AI infrastructure problem. And if memory doesn't scale, AI doesn't scale. The AI industry sold you on infinite scaling. But they forgot to mention the part where there's only 3 companies making the memory chips that power everything. And all 3 just chose AI data centers over you. Even Nvidia can't make enough GPUs to meet demand. Not because of energy. Not because of regulation... But because the memory supply chain is BROKEN. And it won't be fixed until 2028.

Ricardo

594,643 Aufrufe • vor 8 Monaten

YOUR AI TEAM SHOULD NOT LOOK LIKE FIVE CHAT WINDOWS. IT SHOULD LOOK LIKE THIS. FIVE AGENTS. ONE PERSISTENT MEMORY. WORK THAT KEEPS MOVING AFTER THE HUMAN LEAVES. I TURNED THE ARCHITECTURE IN THIS ARTICLE INTO A LIVE SYSTEM MAP. everyone reads multi-agent architecture as a list of roles: chief of staff, researcher, writer, designer, operator the roles are not the interesting part. the handoffs are so i rendered the system as something you can watch instead of another diagram you have to believe the ring is the shared workspace. no agent owns the center the colored branches are five specialists working independently from the same persistent state the particles moving through them are tasks, context and artifacts being handed from one agent to the next the geometry below is the part most agent demos hide: workload, coordination, memory and the boundary where autonomy stops and a human has to approve the next action when the ring turns edge-on, five agents collapse into one thin line that is the point. from the outside this is not five bots. it is one system with five ways to act building it forced five decisions the article implies but never has to make visible: - the chief of staff cannot own the center. if every task must pass through one agent, the orchestrator becomes the bottleneck - shared context has to be infrastructure, not conversation history - a handoff is a first-class event. if you cannot see work moving between agents, you cannot tell coordination from five processes running beside each other - persistence is not “memory.” it is accumulated state that changes what the fleet does next - human approval is not another role in the org chart. it is a boundary around irreversible actions part i did not expect: the center barely moves while the edge is violent research branches, drafts multiply, visuals render, operations update, tasks cross the system constantly but the shared state stays stable enough for every agent to return to it that is what makes the fleet coherent my take: creating five agents is easy. writing five role prompts is a weekend the hard part is building a system where work survives the session, handoffs do not destroy context, one coordinator does not become a queue, and autonomy ends at exactly the right moment if you cannot see those four things, you do not have an agent team yet you have five chat windows running at the same time FULL ARCHITECTURE, PERSISTENCE MODEL AND APPROVAL BOUNDARY BELOW

monokern

28,513 Aufrufe • vor 26 Tagen

Grok Bot + Kimi K3 can be turned into something bigger than an agent: an AI operating system the formula: AI OS = Router + Reasoning + Memory + Tools + Loops + Verification not one giant assistant. six layers that keep work moving without you step 1 -> Grok Bot becomes the operator. you give it the goal, it breaks the goal into jobs, assigns priorities and decides what part of the system should act next. step 2 -> Kimi K3 becomes the reasoning core. hard research, synthesis, long context and planning move here instead of forcing every task through the same model. step 3 -> externalize memory. store goals, decisions, failed attempts, artifacts and current state outside the chat. close the session, come back tomorrow, and the system still knows where it is. step 4 -> connect tools: search, code, files, APIs, docs and data. reasoning decides what should happen. tools actually make it happen. step 5 -> add the loop engine: plan -> execute -> inspect -> update memory -> retry. the loop can wait for new information, rerun a failed task, hand work to another agent or stop when the goal is complete. step 6 -> verify before output. tests, source checks, constraints and explicit completion rules decide whether the system ships the result or sends it back into the loop. that's the difference between an AI assistant and an AI operating system. an assistant waits for your next message. an operating system carries state, routes work and keeps moving. Grok Bot handles orchestration, Kimi K3 handles deeper reasoning, memory keeps the state alive, tools execute, the loop keeps the system running, verification decides when it is actually done. build one reliable loop and you have an agent. connect reasoning, memory, tools and multiple loops around it and you start building infrastructure. the full Grok Bot + Kimi K3 AI OS breakdown is below ↓

Alex

13,312 Aufrufe • vor 24 Tagen

Micron is going to $4,000 and once you understand what inference actually is, the number stops sounding crazy (Save this). Dylan Patel just said that by 2030, OpenAI and Anthropic alone will need over 100 gigawatts of compute combined and by 2040, we may not even be measuring AI infrastructure in gigawatts anymore. We may be talking about terawatts. Every single one of those gigawatts needs memory to function. Without it, the compute is worthless. Most people heard that and thought about Nvidia but they should be thinking about Micron. Every AI model generating a response has two phases. The first is prefill, processing your prompt which is compute-heavy and the second is decode generating each word one token at a time and that phase is almost entirely memory-bound, not compute-bound. During decode, the GPU's processing units sit idle more than 95% of the time, waiting for data to arrive from memory. Google confirmed it in a research paper that decode-phase bottlenecks are dominated by memory bandwidth and capacity not raw compute. The GPU is not the bottleneck but the memory feeding the GPU is. This matters because inference is now where all the money lives. Training a model happens once, Inference happens billions of times a day every ChatGPT response, every Claude output, every agentic workflow running in the background and every one of those token streams is a billing event tied directly to memory performance. Adding more GPUs does not fix this because GPUs are already underutilized in inference because they are sitting idle waiting on memory. Adding more memory bandwidth and capacity is what directly reduces token cost, reduces latency, and allows the same cluster to serve dramatically more users simultaneously. Longer context windows compound the problem further, a model running a 1 million token context window requires dramatically more memory per session than a 10,000 token window, and every new model generation pushes context longer. The market treats memory as a downstream beneficiary of Nvidia orders. The correct framework is the opposite, Micron is the upstream constraint on how much value every Nvidia GPU can actually generate at inference scale. Micron guided Q4 to $50 billion in revenue, has HBM4 ramping at twice the pace of the prior generation, and CEO Sanjay Mehrotra has said supply will not catch demand before the end of 2027. At 8x forward earnings on $112 projected FY2027 EPS, Micron is the most undervalued infrastructure company in the entire AI stack. Inference is memory. Memory is Micron and the inference ramp has barely started. Milk Road Pro members are already up massively on this position and we're just getting started. If you want the full breakdown of what we're buying and why, come join us for just a dollar using the link below!

Milk Road AI

130,756 Aufrufe • vor 3 Monaten

HERMES AGENT CAN SHARE MEMORY WITH CODEX AND CLAUDE CODE THROUGH HINDSIGHT. ONE MEMORY BANK. ONE AGENT REMEMBERS, EVERY OTHER AGENT KNOWS. the problem: you use Hermes for orchestration. Codex for coding. Claude Code for debugging. each has its own memory. switch between them and you explain the same project three times. Hindsight fixes this. one shared memory bank that every agent reads and writes to. tell Codex: "the test color for this project is purple." switch to Hermes. ask: "what test color did I pick?" Hermes answers: "purple." no copy-paste. no re-explaining. instant recall. HOW IT WORKS: Hindsight runs as a Docker container on your machine. self-hosted. your data stays local. an LLM powers the memory processing (retain, recall, reflect). RETAIN: extracts facts from your conversations. entities, decisions, preferences, project context. saved to the memory bank automatically. RECALL: when you ask a question, Hindsight pulls from semantic search, keywords, graph connections, and temporal data. fused into one answer. REFLECT: deeper reasoning layer. connects memories across sessions. identifies patterns in your work. produces observations that get smarter over time. CONNECT TO HERMES: Desktop app: Settings → Memory and Context → switch provider from Namosin to Hindsight. set API URL to your local Docker container. set bank ID. done. CLI: hermes memory setup → select Hindsight. verify: hermes memory status should show: provider: hindsight, installed, available. CONNECT TO CODEX: npx hindsight-coding-agents install codex \ --self-hosted --server this installs lifecycle hooks: initialize memory on session start. recall context during work. retain the session when done. enable hooks in Codex: Settings → Hooks → trust all three. CONNECT TO CLAUDE CODE (same command): npx hindsight-coding-agents install all "all" connects every detected agent on your machine. Claude Code, Codex, Cursor, and others. one command. every agent shares the same bank. TAGS FOR FILTERING: every memory gets tagged by harness (Hermes, Codex, Claude Code) and optionally by project name. in the Hindsight control plane: filter by harness. see only Hermes memories. or only Codex memories. or search across everything. soft partitions inside one bank. not hard walls. cross-reference when you need to. ONE BANK OR MANY: one global bank: solo dev, related projects. all agents share everything. patterns emerge across projects. per-project banks: unrelated codebases. each project gets its own memory. no cross-contamination. your call. start with one. split when projects diverge. KNOWLEDGE PAGES (v0.9.0): Hindsight auto-generates living summaries from your accumulated memories. components, concepts, conventions, decisions. not static docs. projected from real agent conversations. auto-refresh as new memories land. WHAT TO KNOW: self-hosted via Docker. your data never leaves your machine. backup system built in (admin CLI + scheduled exports). works with any LLM (local Ollama, OpenAI, Codex subscription). memory defense: redact or block sensitive content automatically. 33,000+ memories accumulated in ~10 days of normal use.

YanXbt

29,658 Aufrufe • vor 1 Monat

A woman sits between two men. One is old and wealthy, and he is offering her a fortune. The other is young with nothing to give but himself. And Bouguereau painted her in the exact moment before she chooses... The painting is called Entre la richesse et l'amour, "Between Wealth and Love," made in 1869 by the French master William-Adolphe Bouguereau. At its center sits a young woman in a soft pink dress, her expression caught somewhere between thought and sorrow. On one side of her leans an old man, richly dressed, holding out an ornate casket, a small chest of treasure. He is wealth. He is offering comfort, security, a life without want, in exchange for her hand. On her other side is a young man in simpler clothes, earnest, leaning toward her, his hand pressed over his heart. That gesture is all he offers. He holds out no gold and no gift, only himself, the sincerity of his feeling, and the promise of a life that may be poor but will be warm. He is love. Bouguereau does not tell us what she decides. That is the genius of the painting: he freezes her in the one instant every human being recognizes, the moment when two futures stand on either side of you, and you understand that to choose one is to lose the other forever. Everyone, sooner or later, sits in that chair. Everyone is asked, in one form or another, to choose between the safe life and the true one. And the painting does not pretend the choice is easy. It never tells us what she should do. It only asks us to look, and to notice what we find ourselves wishing for... I started my newsletter because the past is full of masterpieces like this one, and fewer and fewer people are helping us truly see them anymore. Every week I try to. If that is something you'd like to be part of, you can join through the link in my bio, and if you'd like to support my work, a paid subscription is what makes it possible. Thanks for reading.

James Lucas

110,698 Aufrufe • vor 2 Monaten

A new way of working. And a scary one at that. Memory Store is one of a group of new kinds of AI-first companies that can turn you into a Fast Company. I’m using several of them on my desktop and they are a dramatically new way to work. It builds a memory for: 1. Your AI agents. 2. Any employee using it. 3. The company itself. I sit down with founder Diwank Singh Tomer, Diwank Singh Tomer, who both freaks me out as well as shows how AI can radically help workers as well as managers. First, why does it freak me out? Well, his AI watches nearly everything a worker does and keeps a “memory” of it. It watches your email. Your calendar. Your Slack. And a whole lot of other things. This can really freak out workers if “forced” on them. And leads to a whole new set of security issues companies need to consider before adopting these things. Such data about a company could give a competitor a HUGE advantage, if leaked. They would know how a company “thinks.” It really is a surveillance system for employees and the company itself. OK, now why would anyone ever use such a thing? Because it gives employees super powers. It makes them more productive. Shows workers a lot of things about themselves, and helps them work and stay on task. It also gives the company super powers. Institutional memory stays with the AI now, even if an employee dies or leaves. As companies move to “AI First” approaches, they will increasingly see the value in companies like Memory Store. It prepares employees for meetings. It helps them remember things. It shows them what they should be working on, and helps them do it. Memory Store builds a memory for: 1. Your agents. 2. Your company. 3. Yourself, or any employee on it. This helps all three work better together. Diwank Singh Tomer and I go in depth about what it does and how deeply it improves working at a company that deploys it. But to get the ultimate benefits you gotta convince your coworkers to use it. And your managers to approve it. Which means you have to get over your fears and get everyone you work with over theirs too. Which will be the challenge for Diwank. Luckily for him his first customers are raving about how good it is and how much his platform helped their companies. Increases sales. Makes teams more productive. Decreases errors and unnecessary costs. Which tells me everyone soon will be using systems like this. This is what the new way of working looks like. Once I got over my fears it sure is an amazing way to work. Will you try working this way?

Robert Scoble

26,186 Aufrufe • vor 4 Monaten