Loading video...
Video Failed to Load
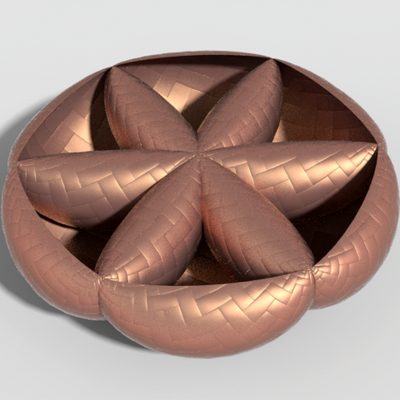
Quick “teaser” for a fun #SIGGRAPH2025 project, led by Hossein Baktash, on optimizing a shape to have the desired rolling statistics. Basically we can turn arbitrary objects into fair dice, or make dice which capture the statistics of other objects—like several coin flips.
17,815 views • 1 year ago •via X (Twitter)
10 Comments

You can read all about it in this Ars Technica article: The original paper, as well as some printable 3D STL files, are on Hossein's webpage:

Scan any documents, convert images into text, PDF files, etc. 👍

How do you guys do so many cool things?!?! 🤩 this is so fun
We just collaborate with a lot of cool people! 😆 (Thanks Steve.)

Does probabilities imitate geometry or geometry imitate probabilities? Just like art and nature. interesting post...

So cool

Logarithmic maps are incredibly useful for algorithms on surfaces--they're local 2D coordinates centered at a given source. @yousufmsoliman and I found a better way to compute log maps w/ fast short-time heat flow in "The Affine Heat Method" presented @ SGP2025 today! 🧵

The single most undervalued fact of linear algebra: matrices are graphs, and graphs are matrices. Encoding matrices as graphs is a cheat code, making complex behavior simple to study. Let me show you how!

People are confused about why preconditioning gradient might be better until they see this video. Intuitively, gradient descent is only good if each parameter axis contribute same amount to the descent: if they don't, you should rotate them. Problem is you can't, so you rotate the gradient instead.

10 years ago, in May 2015, we published the first working very deep gradient-based feedforward neural networks (FNNs) with hundreds of layers (previous FNNs had a maximum of a few dozen layers). To overcome the vanishing gradient problem, our Highway Networks used the residual connections first introduced in 1991 by @HochreiterSepp to achieve constant error flow in recurrent NNs (RNNs), gated through multiplicative gates similar to the forget gates (Gers et al., 1999) of our very deep LSTM RNN. Highway NNs were made possible through the work of my former PhD students @rupspace and Klaus Greff. Setting the Highway NN gates to 1.0 effectively gives us the ResNet published 7 months later. Deep learning is all about NN depth. LSTMs brought essentially unlimited depth to recurrent NNs; Highway Nets brought it to feedforward NNs.