Video wird geladen...
Video konnte nicht geladen werden
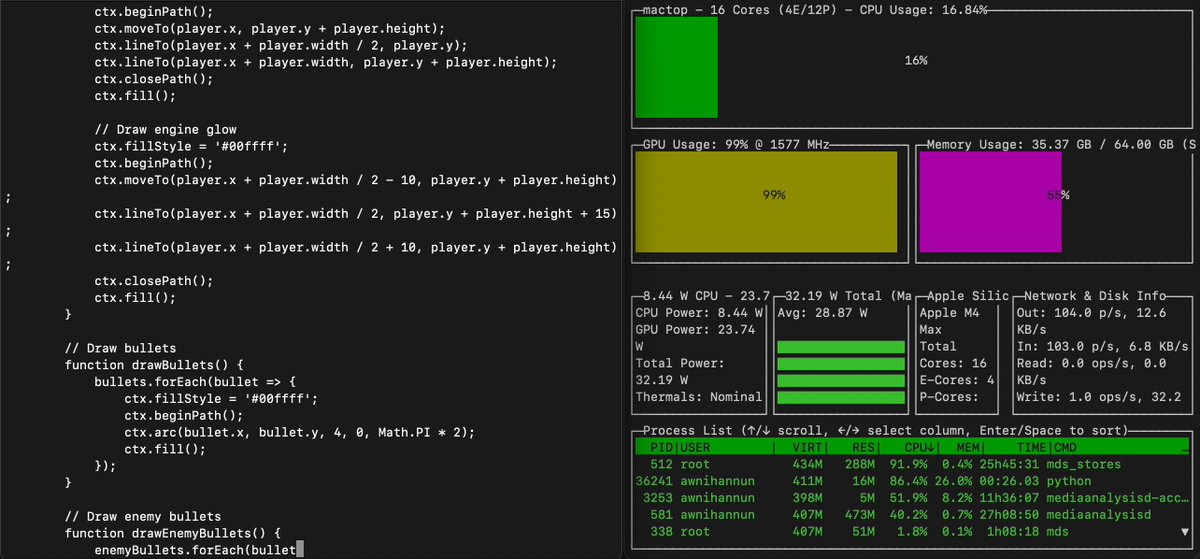
Running GLM-4.7-Flash on 4 x M4 Pro Mac Minis using EXO Labs. Uses tensor parallelism with RDMA over Thunderbolt & MLX backend (h/t Awni Hannun). Runs at 100 tok/sec. We're working on optimizing this at EXO Labs. Aiming to hit ~200 tok/sec on this setup soon.

62,320 Aufrufe • vor 9 Monaten •via X (Twitter)
49 Kommentare

@exolabs @awnihannun 8bit on an RTX 5090, 2K context window, is 145-t/s via Ollama. I can only dream of running BF16 though...

@exolabs @awnihannun This can be improved, significantly.

@exolabs @awnihannun Why not bump it up to 72 qubits?

@exolabs @awnihannun I’ve got a DGX Spark! Does it cook??
@exolabs @awnihannun Not yet. Imminent.

@exolabs @awnihannun this is exactly why Apple silicon is quietly becoming the best AI dev environment.

@exolabs @awnihannun That is so cool🔥! Looking into running @exolabs with @Eigent_AI

Dynamite stuff guys. I have collected (3) sparks and a handful of Studios = 1TB.. when do you think you will have some additional heterogeneous inference updates available…? I have been able to load models.. but nothing as concurrent as you demonstrated in your exo spark/studio combo? Very excited to see what models at full scale we can run soon. Please and thanks.
@exolabs @awnihannun Working on better support for heterogeneous hardware, including disaggregated prefill/decode
@exolabs @awnihannun Thanks Mr. Cheema. Big fans of your work. Please don’t hesitate if there’s anything I could do to contribute. Heterogeneous inference is the future of local models. Your work is critical.
For what is worth: From our testing: Mac Studio (MLX) + DGX Spark (GB10) cluster. The MLX-CUDA overhead fix will help a lot of people. One thing we're watching: GB10 uses sm_121 compute capability, which PyTorch doesn't support yet. This blocks vLLM/SGLang on Spark hardware even when networking is solid. If EXO can address sm_121 at the framework level (bypassing PyTorch's gap), that would unlock a whole segment of early Blackwell adopters stuck waiting on upstream. Happy to test if useful. Appreciate the work you're doing. Appreciate everyone in this space..

@exolabs @awnihannun is this bf16?

@exolabs @awnihannun exo looks so cool...

@exolabs @awnihannun mlx + thunderbolt rdma is such a clever combo

@exolabs @awnihannun Mac silicon is awesome for local LLM. can you share a blog post on setup and instructions.

@exolabs @awnihannun Just got some Mac Studios and gonna try it, can't wait to see the benchmark results!
@exolabs @awnihannun Share results
@exolabs @awnihannun which context length do you use for that benchmark?

@exolabs @awnihannun 200 tok/sec could be really interesting. What would the context size look like?

@exolabs @awnihannun This is awesome. I tried on M3 Max. Super slow as expected. Time for M4 pro Minis I think :)

@exolabs @awnihannun wow, what a setup!

@exolabs @awnihannun Crazy impressive! Decentralized setups slash risk—ever notice real-world uptime jumps after going agent style? Welcome to AgentFi mindset

@exolabs @awnihannun 100 tok/sec on minis is wild, feels like illegal compute but in a cute box

@exolabs @awnihannun 4.7 flash is a 30b sparse model, why are people running this on such expensive hardware during the ramageddon? Figure out how to run it on your CURRENT 32gb of ram with a 12gb vram gpu instead!

@exolabs @awnihannun Flash? This should run on one of them.
@exolabs @awnihannun Correct, this is scaling up not out with tensor parallelism using RDMA over Thunderbolt

@exolabs @awnihannun RTX6000 still the best option, hopefully things move faster 😭😭😭

@exolabs @awnihannun Is there any starter guide ?
@exolabs @awnihannun I liked @digitalix’s video on this, goes through installation and using the macOS app. It’s super easy.

@exolabs @awnihannun This setup is pure magic

@exolabs @awnihannun Tu é brasileiro, cabra?
@exolabs @awnihannun decentralized compute is the real level-up, agent economy incoming

@exolabs @awnihannun @grok do the math. What is the cost of this set up in USD?

@exolabs @awnihannun RTX 6000 must be 200-ish t/s? 👀

@exolabs @awnihannun that's nice!
@exolabs @awnihannun Thanks Kernz

@exolabs @awnihannun Alex can we attach also Linux GPUs to the stack ? I’m thinking 2x MacStudio ultra + 2x4090

@exolabs @awnihannun You're telling me I can do this with 4 minis and not ultra studios? The CPU is the limitation not the GPUs?

@exolabs @awnihannun curious how this setup compares to a single high-end gpu in terms of performance and cost

@awnihannun @exolabs 800 or no dice
@awnihannun @exolabs 800 tok/sec?

@exolabs @awnihannun why mac mini over mac studio?

@exolabs @awnihannun Which RAM specs of M4 Mac Mini do you need for your cluster?

@exolabs @awnihannun Will it work on a single Mac mini M4 cranked to maximum 64 GB ram and top processor + video card ?
@exolabs @awnihannun Yes, it already fits on a single Mac with enough memory. Clustering provides a speedup in this case.
@exolabs @awnihannun Just tested this with opencode and lmstudio. It struggles.
@exolabs @awnihannun We are working on making this 10x better
@exolabs @awnihannun I have only one computer, does it make sense to install exo ?

@exolabs @awnihannun @alexocheema, achieving higher inference speeds with this setup is definitely promising for future applications.