Video wird geladen...
Video konnte nicht geladen werden
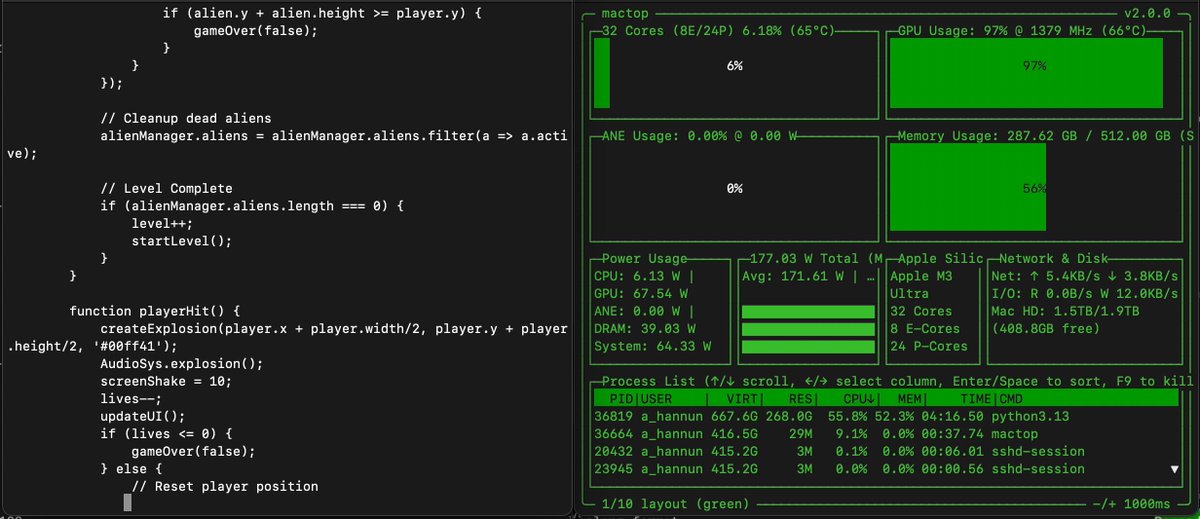
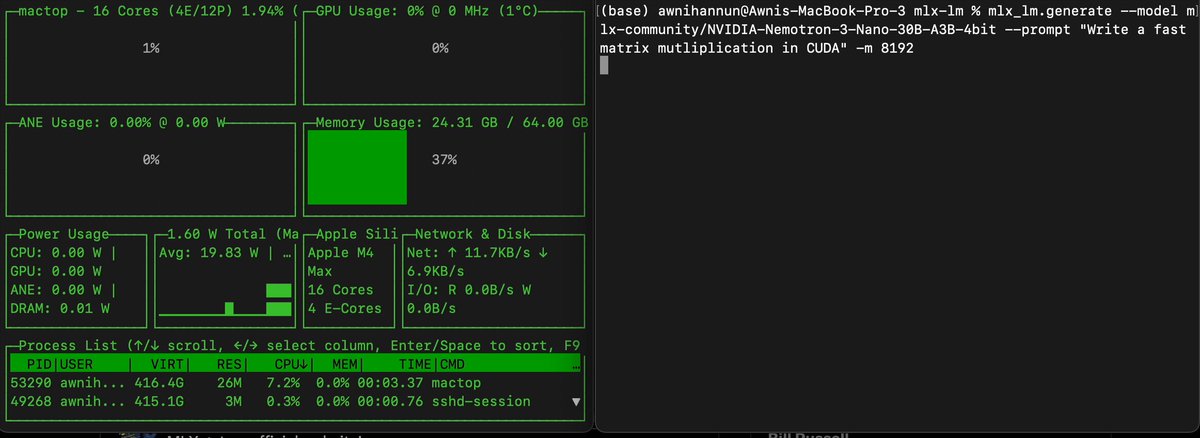
Qwen3-Coder-Flash runs quite fast on an M4 Max with mlx-lm. Running the 4-bit here, generated 4,467 tokens at >107 tokens/sec:
196,606 Aufrufe • vor 1 Jahr •via X (Twitter)
46 Kommentare

I tried @simonw space invaders prompt. It one-shotted a nearly working full game (the game play is not perfect yet). Maybe a DWQ will fix it.
Much better (if not perfect) result with a partially trained DWQ 4-bit + using the recommended sampling params ``` mlx_lm.generate --model mlx-community/Qwen3-Coder-30B-A3B-Instruct-4bit --prompt "Write an HTML and JavaScript page implementing space invaders" -m 8192 --top-k 20 --top-p 0.8 --temp 0.7 ```
@N8Programs @ivanfioravanti

107 tokens/sec! OMG 😱

I'm just a bit annoyed that they released the 480B monster and this tiny 30B, but with nothing in between. A well-trained coder the size of GLM-Air-4.5 would be an absolute local killer.

it runs super fast on my M1 Studio 64GB

The code

this is simply beautiful. curious if you tried lmstudio to make mlx setup easier
I use it often, highly recommend.

😎🦿

Anyone have the minimum m-series hardware requirements for the Qwen3 Coder Flash model? For example, could it run on an M1 and M2?
Oh MEGA wow!

Nice! About to buy another M2 ultra 196gb and pair them using @exolabs to run Qwen3 480b

Do you have instructions how to run it on my Mac locally with M4 and 128 GB of RAM?
1. pip install mlx-lm 2. mlx_lm.generate --model mlx-community/Qwen3-Coder-30B-A3B-Instruct-4bit --prompt "Write an HTML and JavaScript page implementing space invaders" -m 8192
Wow, it worked! It works really fast on my machine. I'm trying to install a stronger (bigger model) now on my machine. What do you think is the best model that would work on my M4 with 128 GB of RAM. I'm going to try mlx_lm.generate --model mlx-community/Qwen3-Coder-480B-A35B-Instruct-4bit \ --prompt "Refactor this Rust crate for performance" \ -m 8192 Would you say it's the best? Is it likely to work?

@awnihannun Unfortunately I believe that model might be too big for an M4 with 128gb. I to might give it a go though.
@awnihannun Yeah, doesn’t seem to work on my machine. Getting some errors. Apple should release Macs with more memory!

fastest fingers in the west

Hmm, this is on-par or faster than M3U generation? I wonder where bottleneck is?
Yes small models can be faster on M4M than M3U. There is more CPU overhead on M3
Is the graph interruption for MoE partly responsible? I'm curious which part of the execution runs on the CPU?
There is no graph interrupting. CPU is responsible for submitting work to GPU and there is a lot that goes along with that from building the high level graph down to kernel launch latency.
Interesting, thanks!

@apple please release a machine for us , we need interface desperately. Nvidia digits is trash

wow, need to try it on my M4 Max this weekend!

Imagine the quality at fp16.

Okay, I'll admit. This kind of stuff the mac does pretty well

How do I replace agent workflow of cursor with this?

Qwen3-Coder-Flash === Qwen3-Coder-30B-A3B-Instruct ?

🚀🚀🚀

That is pretty impressive

How is the Mac specced?

Nice. I get 160 on my 5090

Supply chain resilience isnt about predicting disruption... its about adapting to it fast. Agility trumps efficiency these days.

@awnihannun do you know if there is a MLX Quant Version with the Tool-Calling Fix?

wow

But the fans I guess are going crazy, aren’t they?

may i ask for exact specs of your m4 max?

now about the quality on complex tasks, how did it performn?

What TLI are you using?

M4 Mac with 64gb ram is a viable local AI machine?

So the quality is pretty reasonable? I'm trying to move off of Opus and I have an M4M64

What are the specs on your M4 Max Mac?

it needs 32 gb of ram !?!?

@Cenismo