正在加载视频...
视频加载失败
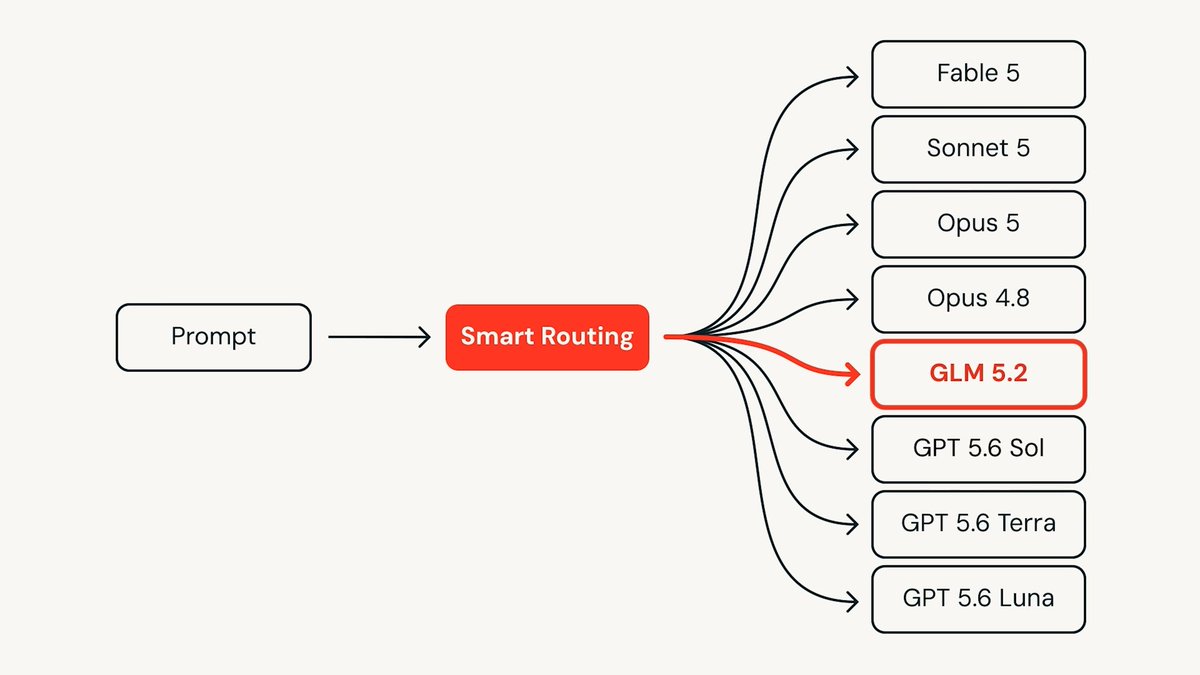
The right model depends on the task. NVIDIA NeMo Switchyard helps developers route each agent workflow step across a chosen model pool based on their own quality, latency and cost criteria. Kari Briski joins MTS to explain why agent workflows need model routing.
97,218 次观看 • 1 个月前 •via X (Twitter)
33 条评论

Learn more:

@MTSlive so awesome to have kari on the show!

@ChrisJBakke @MTSlive NVIDIA monitoring the situation 🤘

@MTSlive The smarter the routing, the more important the data behind each decision becomes. Model choice is only one part of the stack.

@MTSlive Model routing by task is becoming essential once agent workflows get multi step. One model for everything is rarely optimal on cost or latency.

@MTSlive I'm a contributor to Switchyard. If anyone wants help setting it up let me know.

@MTSlive ⚓️✅❌🚀🎇

@MTSlive Doesn't matter which model wins the routing fight, every single path still ends at an Nvidia GPU.

@MTSlive @elonmusk

@MTSlive oxi, now proibida no mundo todo

@MTSlive model routing based on latency + cost is the part most teams still underestimate

@MTSlive Model routing is becoming core infrastructure for agent systems—use the expensive reasoning model where it matters, optimize everything else around it.

@MTSlive Smart routing saves real money

@MTSlive The right model depends on the task.

@MTSlive 👍

@MTSlive Love how NeMo Switchyard lets us pick the perfect model for each step—smart, flexible, and cost‑savvy!

@MTSlive

@MTSlive Routing only works after teams save representative workflows and set a quality floor.

@MTSlive Per-step routing is right, and it only works if you have per-step evals: without them you're routing on vibes and the cheap model quietly tanks one node of the workflow.

@MTSlive rubin vs tpu pileup this month is the whole story. everyone shipping silicon at once.

@MTSlive ♻️🔰♻️🔰♻️🔰♻️🔰♻️🔰♻️

@MTSlive

@MTSlive This is a key piece of the agentic AI puzzle. Model routing makes sense when different workflow steps have different requirements. The real challenge is deciding dynamically when quality matters more than latency or cost. That’s where intelligent orchestration becomes critical.

@MTSlive Smart model routing can make agent workflows far more efficient. Matching each task to the right model helps balance quality, latency, and cost without relying on one model for everything.

@MTSlive Model routing gets really interesting once you optimize for the whole workflow, not each model in isolation. The best model for one step can be the wrong one for the next.

@MTSlive Not one person buying this stock. Absolutely makes zero sense why this company is not doubling its stock buyback. Executive leadership screwed investors. This company has an image problem. @JensenHuang

@MTSlive Routing is becoming part of model performance, not just infra plumbing. A cheaper model on the right step beats pushing a frontier model through every step blindly.

@MTSlive Switchyard tackles model routing. Good for balancing quality, latency, cost.

@MTSlive “NVIDIA is amazing. I just hope it keeps pushing a little harder.”

@MTSlive Yes sir nvidia has great architecture

@MTSlive Hello @nvidia - why are you helping Russia kill Ukrainians? Do you support mass killing of civilians? In Russian attack drones, Nvidia chips for fully autonomous targeting were found. It was precisely such a drone that killed three civilians in Zaporizhzhia on July 6.

@MTSlive Quality, latency, and cost routing per workflow step is the right architecture. GPT should get the hard turns.

@MTSlive does routing happen per step after failure, or only from the initial plan?