正在加载视频...
视频加载失败
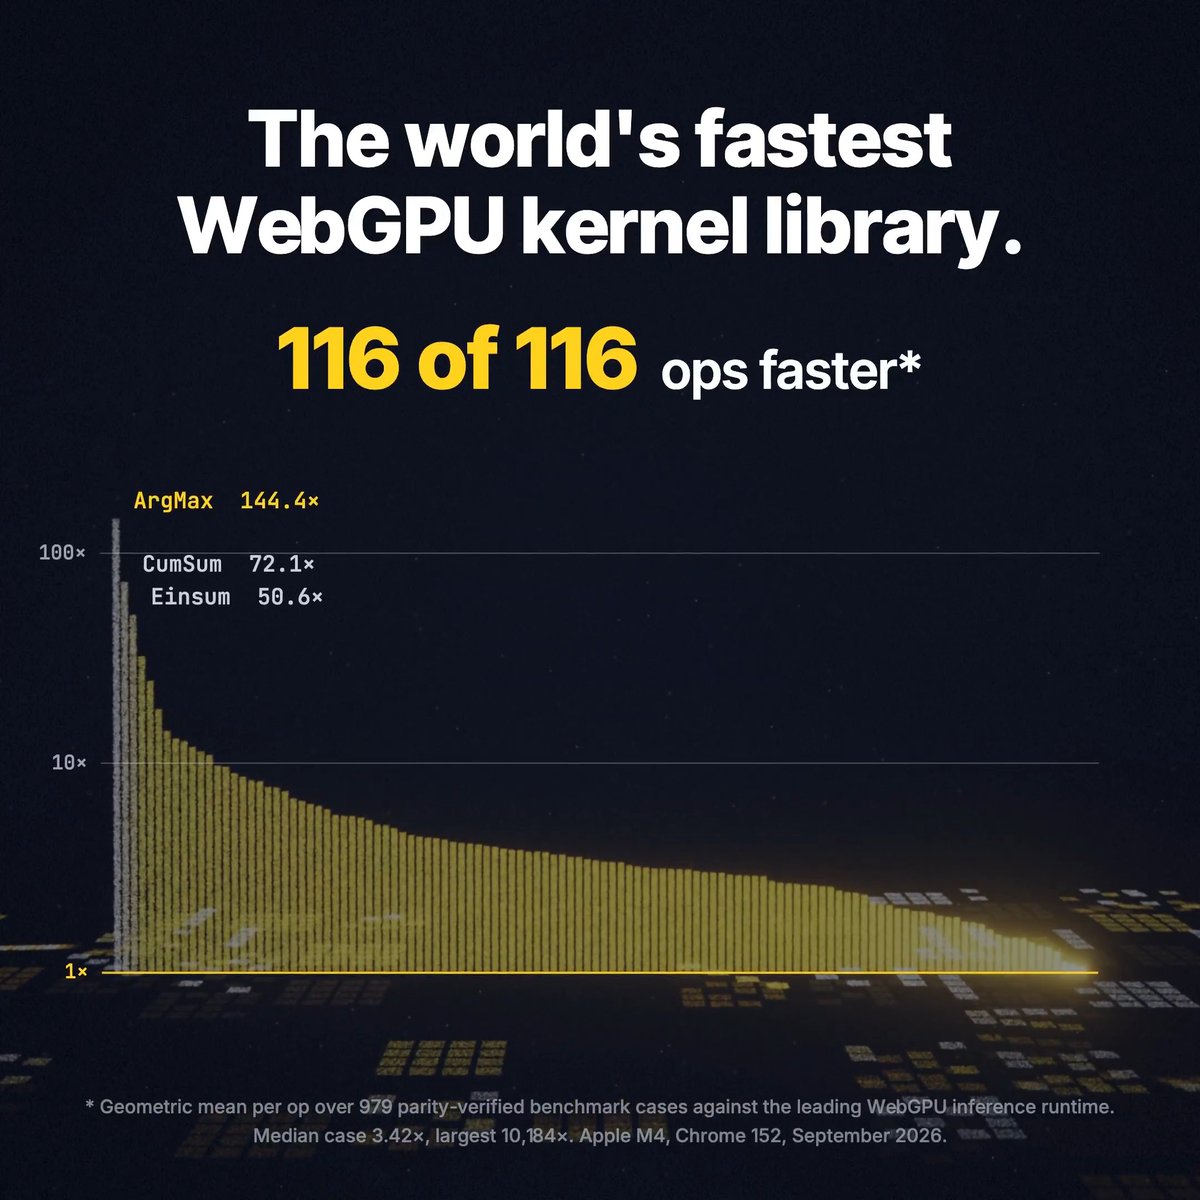
This doesn't feel like it should be possible. Muse Glimmer 30B can now run locally in your browser on WebGPU... at the same speed as llama.cpp (~25 tok/s on my M4 Max)! Just open a website. No installation required.

21,602 次观看 • 2 个月前 •via X (Twitter)
15 条评论

Thanks to @UnslothAI for the GGUF quants! 🦥 Try it out yourself (requires 12-14+ GB of VRAM):

@Presidentlin

This is the kind of browser-local inference that changes automation UX: no install step, fewer environment failures, and enough speed for read → summarize → decide loops. I’d love to see a reliability benchmark across Chrome/Safari + different GPUs next.

I've experienced MoE models (like some Qwen ones) are even faster than dense models

I would say this suggests the boundary between deployment environment and inference runtime is getting surprisingly thin

Sick drop thanks! Adding

unified memory is why this lands at all. there is no host to device copy, so the weights are already sitting where the gpu reads them. the cost that stays is the first load, since the browser has to pull and cache the whole weight set before token one.

Browser-side at llama.cpp speed is a big deal for a 30B dense model. This belongs next to the other ways people are running Glimmer locally, from 2-bit GGUFs to MLX quants:

this is vibing, it would be nice if that only used 4Gb though 😉

Could this work offline as is or do you need to have internet connection for opening the hugging face page?
this is vibing

The Firefox browser is now using built-in local AI models. I have not investigated this yet. But it seems to be using it for translation.

Most people are still underestimating what AI can do.

is this open souce? i would really like to see if its possible to do this for other models like the ling tiny

that's wild - tradeoff is the model might hit some limitations or quirks when running client-side vs server-side. ever run into any odd behaviors?