正在加载视频...
视频加载失败
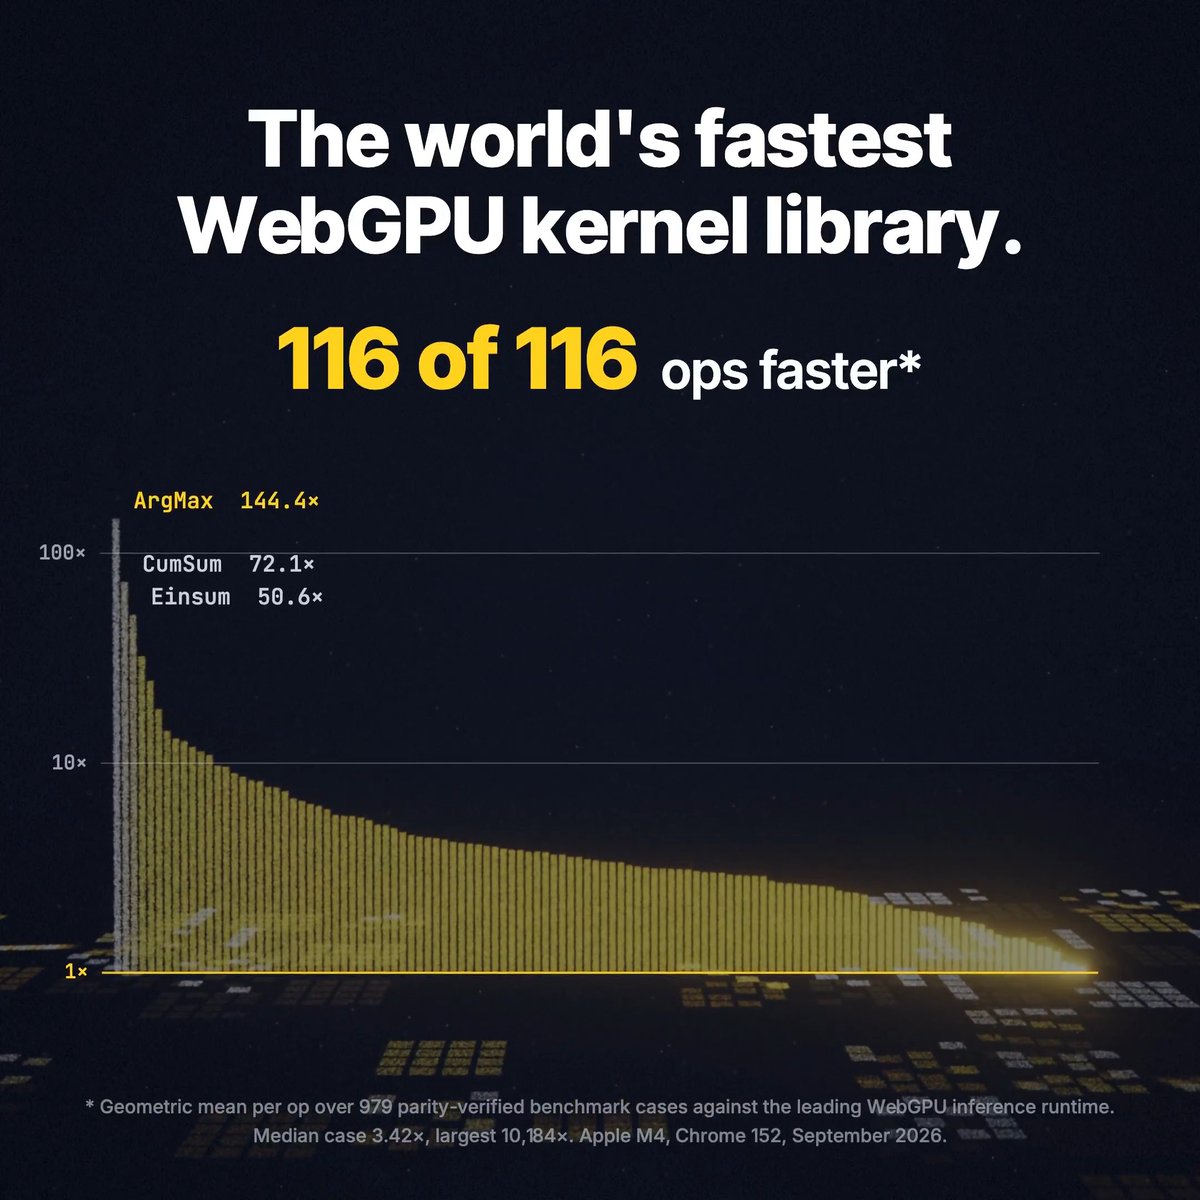
It's official: Qwen3.8-27B just scored 52 on the Artificial Analysis Intelligence Index. We now have an open-weight model that matches GPT-5.6 Luna (max) AND can run locally... even in your browser with custom WebGPU kernels! What a time to be alive! 🤯

29 条评论

@ArtificialAnlys that Qwen WebGPU is beautiful!

@ArtificialAnlys where is the repo? how much vram?

@ArtificialAnlys Open weight matching that score is huge

@ArtificialAnlys 27B matching Luna is cool but running the thing in a browser is the part that sounds fake lol

@ArtificialAnlys lets hope AI coding subs start introducing it and other small models

@ArtificialAnlys “Runs locally in your browser” sounds great, until you ask on what hardware. A 27B model doesn’t magically remove the hardware requirements just because it runs through WebGPU. Why is that part always missing?

@ArtificialAnlys that's more of a publicity stunt than a real breakthrough.

@ArtificialAnlys 27b parameters still need roughly 14gb at 4-bit, so browser support excludes many laptops

@ArtificialAnlys It can single shot this:

@ArtificialAnlys 跑分先放一边,浏览器里能跑才是真的离谱。

@ArtificialAnlys yeahh i think qwen is the best

@ArtificialAnlys That's crazy!

@ArtificialAnlys

@ArtificialAnlys Ahh, why do i need to care when It don't run on my windows..

@ArtificialAnlys That’s a new category.

@ArtificialAnlys QWEN IS BEAUTIFUL

@ArtificialAnlys Local deployment of a 27B model like this will challenge the existing frameworks. Big shift ahead.

@ArtificialAnlys I just posted this "What a time to be alive! 🤯"

@ArtificialAnlys huge! if all hardware and ai advancement stopped today, this would be enough to carry us far into the future and build so many things that never had somebody to build them. and it's not slowing down! Amazing a stock browser is the only thing that has to be installed for local ai

@ArtificialAnlys I will still prefer any time over QWEN

@ArtificialAnlys this is probably going to put more pressure on API pricing too

@ArtificialAnlys can't wait for the q2 and q1 to appear!

@ArtificialAnlys 52 on the Intelligence Index at 27B parameters, local-runnable. The gap between open-weight and frontier closed models keeps shrinking from the bottom up. VRAM is still the bottleneck though.

The custom WebGPU kernels are the part people will underrate here. Running locally is one thing, running inside a tab is a different constraint set entirely. The wall most people hit first is not compute, it is buffer limits. A tab does not get the machine's memory, it gets what the device grants, and maxStorageBufferBindingSize sits far below what a model this size wants unless you ask for higher limits at device creation. Then the weights have to survive a reload, so the caching story ends up mattering as much as the kernel story. Getting all of that to line up is genuinely hard, and it is most of why browser inference stayed a demo for so long.

@ArtificialAnlys How do I use webgpu Qwen anyone please

@ArtificialAnlys This model compression pace is accelerating.

@ArtificialAnlys Open-weight models running locally keep getting more impressive

Matching a benchmark score is impressive, but “matches GPT-5.6 Luna” needs task-level parity: exact eval version, prompting, tool use, context length, and variance. Browser WebGPU is feasible too—but quantization, VRAM, and sustained token throughput will determine how usable 27B actually feels locally.

@ArtificialAnlys I bet thousands are refreshing this page every hour :