Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

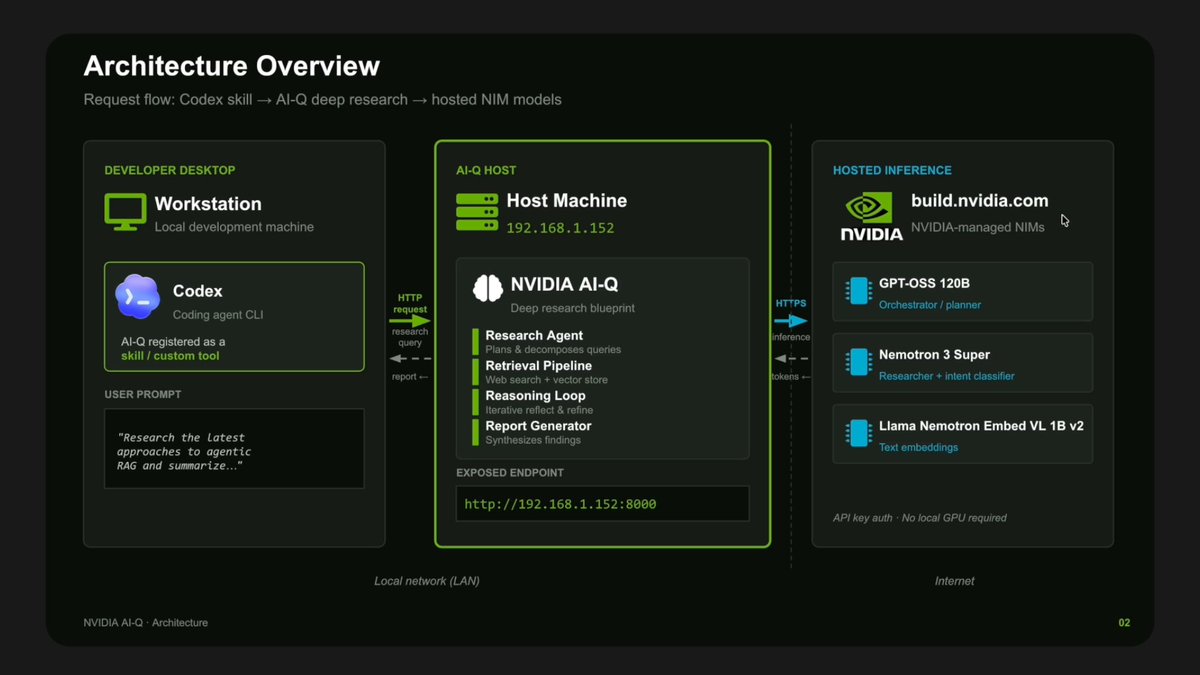
this is pure f*cking gold for anyone running coding agents Jev founder Diogo Amogo wrote a PDF on building a Jev harness the promise: > 200x faster > 400x cheaper the model hasn't been the slow part for a while the speed and the cost sit in the harness...

120,326 görüntüleme • 1 gün önce •via X (Twitter)

14 Yorum

FHX Markets profil fotoğrafı
FHX Markets1 gün önce

The model got fast. Everything around the model became the bottleneck.

Lanny Lobato profil fotoğrafı
Lanny Lobato1 gün önce

200x faster is wild but 400x cheaper is what actually makes this viable at scale

vvtentt profil fotoğrafı
vvtentt1 gün önce

People are big ants and many will be left without work

Crio Songo profil fotoğrafı
Crio Songo1 gün önce

That's a huge optimization. I will get the PDF this weekend and try it out myself.

帆70|BG小晴 profil fotoğrafı
帆70|BG小晴1 gün önce

原来瓶颈一直都在外壳设计上啊受教了

Gul Saeed Khattak profil fotoğrafı
Gul Saeed Khattak1 gün önce

Small correction: this paper is not by the Jev founder. It’s an independent note based on his design ideas The key detail is actually printed on the cover: it says “independent working note, not affiliated with TypeSafe.

WEEX AI Labs profil fotoğrafı
WEEX AI Labs1 gün önce

👀

Wallchain Community Hub profil fotoğrafı
Wallchain Community Hub1 gün önce

finally a harness worth actually setting up

The AI Therapist profil fotoğrafı
The AI Therapist1 gün önce

that 400x cost drop is sexy. I’d bet the secret’s in Jev harnessing parallel context windows rather than raw compute cuts. Makes those coding agents run tighter without bleeding cash. Efficient brains are always attractive to me. 😉

Hamza Khalid profil fotoğrafı
Hamza Khalid1 gün önce

200x and 400x on what baseline though, curious if that's against a naive setup or an already decent one

Harley Lewis Foote profil fotoğrafı
Harley Lewis Foote1 gün önce

The harness as bottleneck—finally someone naming the thing we all felt.

EDDY VU profil fotoğrafı
EDDY VU1 gün önce

Totally agree, redundant tool loops and bad scaffolding waste way more time than token generation ever does.

Tom profil fotoğrafı
Tom1 gün önce

It is easy to just come up with an idea. Now test it, compare, run benchmark, not just speed and cost numbers, but quality - that would be gold. Anyone?

Thorbjørn Rønje profil fotoğrafı
Thorbjørn Rønje1 gün önce

Setup compounds quickly.

Benzer Videolar

run agent harnesses 100% private & offline. (no token costs, no API keys, 100% open-source) your agent runs locally. the model doesn't. every prompt, every file, and every secret still leaves your machine before the agent does anything with it. Magnitude fixes that. it's an open source inference server that runs models on your own hardware and plugs into the coding agent you already use. setup is one command. it profiles your machine, measures the memory bandwidth that sets your token rate, and hands back complete configurations instead of a list of models. each one names a model, a compression level, a context size, and a speed range you can expect. pick one and start working. it doesn't replace your harness. setup asks which one you want and writes that config for you. Pi, OpenCode, Claude Code, Codex, and Cline all work, and there's a built-in one tuned for local models if you don't have a harness yet. that one uses your shell, edits files, and runs scripts out of the box. add skills and it handles Excel, PowerPoint, PDFs, or Chrome. everyday work it covers: → analyze sensitive data → manage private notes → review code and logs → search and organize files → build docs or slides Apache 2.0. no rate limits, and nothing leaves the machine. 𝗻𝗽𝗺 𝗶 -𝗴 @𝗺𝗮𝗴𝗻𝗶𝘁𝘂𝗱𝗲𝗱𝗲𝘃/𝗰𝗹𝗶 the repo is here: (don't forget to star 🌟) i wrote the full breakdown of why picking the configuration is the hard part. the article is quoted below.

Akshay 🚀

55,693 görüntüleme • 25 gün önce

Another insane Jev use case! Jev makes it incredibly cheap to evaluate and classify agent runs at scale. And finally, someone open-sourced a self-improving memory layer that can put that capability to work across agent harnesses. It turns your agent sessions into a compounding knowledge layer, where every successful run can make future agents smarter across: - Codex - Claude Code - Cursor - OpenCode and 20+ more Beacon by Asymptote Labs continuously builds a shared history across your agent harnesses and uses Jev to identify the runs worth learning from. It then turns the best workflows, corrections, and debugging patterns into reusable skills. GitHub repo: (don’t forget to star it ⭐) Most agent runs are messy. They contain exploration, failed commands, dead ends, and one-off fixes that should never become permanent memory. So Beacon preserves the full session history, while Jev helps decide what should be promoted, reviewed, or discarded. The recording below shows this in action. Beacon found 579 sessions across 5 coding-agent harnesses and normalized them into one consistent history. From there, Jev surfaces the lessons worth keeping and makes them available across your agent stack. - A pattern learned in Cursor can carry into OpenCode. - A lesson from Claude Code can improve the next Codex run. Every successful run adds to the shared knowledge layer, making future agents smarter. If you want to dive deeper into Jev, I also wrote a breakdown of how it works. The article is quoted below.

Akshay 🚀

116,060 görüntüleme • 4 gün önce