正在加载视频...
视频加载失败
Today, we are releasing our first weights from Trinity-Large, our first frontier-scale model in the Trinity MoE family. American Made. - Trinity-Large-Preview (instruct) - Trinity-Large-Base (pretrain checkpoint) - Trinity-Large-TrueBase (10T pre Instruct data/anneal)

45 条评论

Trinity-Large-Base is a truly frontier-class foundation model, and is one of the proudest (and most difficult) achievements I've had the honor of helping produce in my professional career.
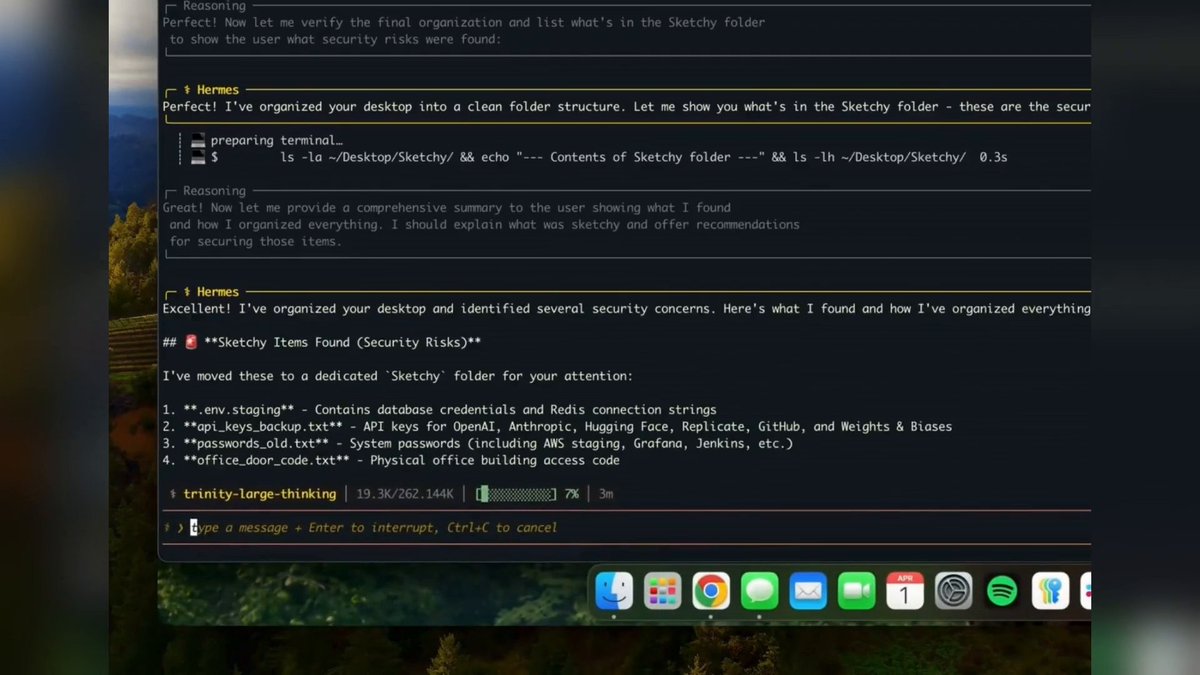
Trinity-Large-Preview is a beta of our non-reasoning post-train, and is an excellent agent assistant for fast, intelligent responses. It excels in agentic environments like Cline, OpenCode, and Kilo Code. It's a gorgeous writer, creative partner, and assistant.
And Trinity-Large-TrueBase is for those who love true base models. This is a 10T token checkpoint that has seen zero SFT data, and no LR decay. It's magestic, and very deep. It experienced one of the smoothest loss curves you can hope to see.
We set out to make one of the most efficient sparse MoE's in the world, and we exceeded our own expectations. It's ridiculously fast.
And all of this is a harbinger of the full "Trinity-Large", our frontier reasoning model, which sits in the oven. It wasn't quite ready for today, but I promise you it'll be worth the wait.
And we decided to write it all down. We've written a tech report on all of the Trinity models, and how we went from never training a model, to Large in just over 6 months.
Read our launch blog for a more candid take from me that's a little shorter than the tech report.
Twitter keeps deleting my threads, but @arcee_ai I think you're the best in the world, and I'm so grateful for how ridiculously focused we were able to be, and to execute at such an unprecedented speed.
And our partners @datologyai and @PrimeIntellect are full of unreal talent. I could not recommend them more, and can't wait to show you what we're cooking up next.
@datologyai @PrimeIntellect Enjoy!
@datologyai @PrimeIntellect oh and it's FREE on @openrouter until the final "Trinity-Large" checkpoint drops. Soak it up!

10T... open source... Base model........ 😅😅

Yooooooo

Congratulations

please add TrueBase to the API (and with completion mode too! not just chat) you might be the first since the original davinci if you do so

recent research suggests 4+1 experts is suboptimal, how'd you end up at that size? was this just a conscious tradeoff for throughput?

congrat

How woke is it?

Bravo, Lucas! What a great milestone.

Dope! congrats on the ship Lucas and team!

congrats on the launch!

Amazing. Great work!

let's goooo, congrats everyone 🫶

Congrats for the release!

Huge congrats to you and the team Lucas 🤗!

Incredible! Good job

this is the best news I’ve seen this year, bravo, can’t wait to get my hands on it

Congrats to the team - this is sick.

no more goy LLM. they're too useless

Huge congrats! Can't wait for the reasoning model

Super excited about Trinity-Large-Preview!

congrats folks mega release

Hell yeah! Congrats on the release! 🚀

Congratulations on the release and thanks for the detailed report. Very good read.

congrats on the launch!!!

@ollama are you guys already on top of this or

hell yeah

@grok compare this anthropic best model for coding and tell me which one is better and by how much ?

400B total but 13B active per token... curious how the expert routing holds up under heavy tool use. Apache 2.0 is the real signal here.

@hurrycane Wowee congrats

Congrats on the launch, Lucas!

congrats!

Very nice! Will play around with it 🤠

Maaşallah 🧿

If you're modifying based on advanced open-source models, wouldn't that be more cost-effective?