正在加载视频...
视频加载失败
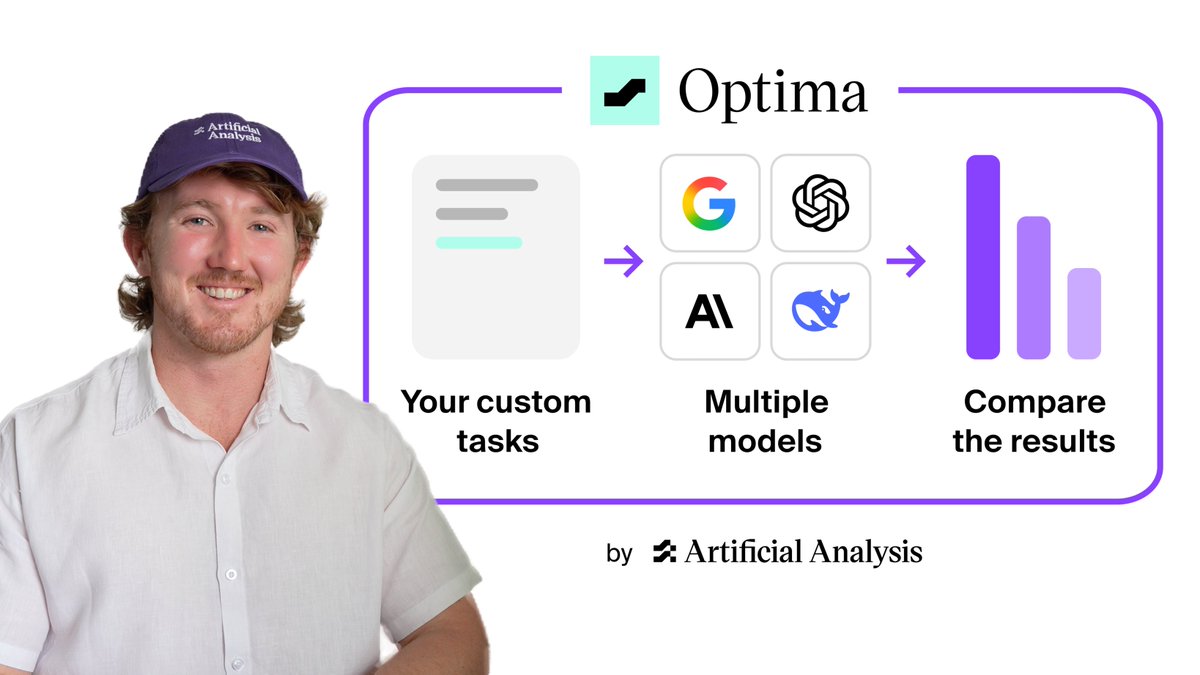
We’re launching Optima. Now anyone can create a custom benchmark for their use case, leveraging Artificial Analysis’ leading research and platform Building and running benchmarks is difficult. We have distilled Artificial Analysis’ research and experience developing benchmarks into Optima, a new platform for benchmarking models on your own workloads... show more

133,952 次观看 • 3 个月前 •via X (Twitter)
32 条评论

Build and run your own benchmark today:

🐐🐐🐐

Congrats y'all!!

Woah, this is actually useful, though a very niche case, but can be a better reporting of actual results, on someone's personal use case

Well this could be good timing. 👀

Way to go 🚀

That's great 👍🏽

Adding cost and latency makes model evaluation far more practical for production teams. The best model is not always the highest-scoring one.

one of the best product for enterprise to find-out the right ai system for their use-cases, cool stuff ❤️

Another fantastic idea. You guys are absolutely killing adding practical and useful features to AA.

@_micah_h Smart. A lot of companies are missing the bigger picture

Benchmarking your own workload is far more useful than generic scores.

i've seen custom benchmarks become training sets within weeks, how does optima detect leakage

public leaderboards never match my actual workload, so benchmarking on my own traces is the only number I trust. throwing a messy agent trace at this tonight.

Nice

is this free?

@grok how is pairwise judging approach (as mentioned in the post) automated ? or is it manual ? how is it done ? tell me in detail

This is very useful for companies struggling to catch up with the model race. The difficulty is not selecting the model, it is building your own eval. Great launch!

Good stuff AA

This is huge Custom benchmarks cost/time metrics is exactly what teams need

Finding a model that’s 10x cheaper or faster for your specific task is more useful than another public leaderboard flex.

Can I optimize cached input tokens where applicable and take it into account in the benchmark?

You're on the payroll! You're hiding GLM 5.3.

The real benchmark isn’t who tops a leaderboard—it’s who survives your workload without setting your token budget on fire.

Cool idea! When it says "bring your own agent," can that include our own harness? Could we run the same model through multiple harnesses?
Yes, exactly - you can run a eval on model(s) running in your own agent harness. We expose a HTTP endpoint for you to send outputs to Optima that can then be evaluated
nice!

The cost-per-task and latency tracking is the part that actually matters. Once people start ranking models on their own agent traces instead of public benches, a lot of the current “top model” rankings are going to look very different.

Optima von Artificial Analysis ist unspektakulärer als „NEUES MODELL!!!“ – und wahrscheinlich wichtiger. Denn öffentliche Benchmarks fragen: Wer gewinnt unseren Test? Eigene Benchmarks fragen: Wer gewinnt meinen tatsächlichen Anwendungsfall? Das klingt nach einer kleinen methodischen Änderung. Für Modellrankings ist es eher der Moment, in dem der Teppich weggezogen wird. Plötzlich zählt nicht mehr, wer auf der Bühne die schönste Zahl hochhält, sondern wer bei der echten Arbeit liefert. Marketingabteilungen entdecken gerade vermutlich eine neue Benchmark: Fluchtgeschwindigkeit zum Notausgang.

Cool

very interesting! i have edge evals for clinical and biomedical tasks, ranging across safety/classification/longevity/medical reasoning. i have kept it private because i don't want this to be contaminated. how private can the evals be on Optima?

The use case I'd benchmark first is boring and unglamorous: which model reads a photographed restaurant menu in Spanish and returns clean dish/price JSON. Public leaderboards never tell me that, and it's the only number that decides my model spend.