Loading video...

Video Failed to Load

Go Home

Introducing Arena Mode in Windsurf: One prompt. Two models. Your vote. Benchmarks don't reflect real-world coding quality. The best model for you depends on your codebase and stack. So we made real-world coding the benchmark. Free for the next week. May the best model win.

1,069,578 views • 7 months ago •via X (Twitter)

39 Comments

Devin Desktop's profile picture
Devin Desktop7 months ago

You can use Arena Mode by choosing up to five models or through Battle Groups. With Battle Groups, two models will be randomly selected each turn. To celebrate the launch, Battle Groups will consume 0x credits for the next week (for trial and paid users)! To start using Arena Mode, install or update Windsurf: Leaderboard: Blog post:

Devin Desktop's profile picture
Devin Desktop7 months ago

Why we built Arena Mode:

Devin Desktop's profile picture
Devin Desktop7 months ago

Arena Mode is part of Wave 14! We've also added Plan Mode to Cascade. Check out the blog post for more details:

Devin Desktop's profile picture
Devin Desktop7 months ago

May the best model win!

Devin Desktop's profile picture
Devin Desktop7 months ago

There's a lot of buzz around Kimi K2.5 and Opus 4.5. Kimi K2.5 is now in Windsurf and Frontier Arena!

Devin Desktop's profile picture
Devin Desktop7 months ago

How to use Plan Mode:

Wayne Chi's profile picture
Wayne Chi7 months ago

This is fantastic and looks like a direct follow-up to our work on Copilot Arena (an in IDE Arena) from ICML 2025. Really excited to see this line of work with professional support. Check it out and hope it helps!

Devin Desktop's profile picture
Devin Desktop7 months ago

whoa cool!

Big WUM's profile picture
Big WUM7 months ago

What a great way to burn through even more tokens

Abhishek Yadav's profile picture
Abhishek Yadav7 months ago

Finally, a benchmark that looks like real work instead of leaderboard gaming. Love this. benchmarks rarely capture refactors, edge cases, or messy real code.Preference based evals matter more than scores.

Carlos's profile picture
Carlos7 months ago

This just feels like you’re asking users to train models for you for free

Thanh Nguyen's profile picture
Thanh Nguyen7 months ago

I don’t know which dev would use this but def not me. I even hate it when chatbot ask me to compare and choose between 2 responses: it takes longer to generate and it hammers my cognitive ability by asking me to read something twice. I can only imagine the problem is exacerbated in coding task where the responses are longer and harder to compare.

Abhimanyu ARYAN's profile picture
Abhimanyu ARYAN7 months ago

Just tested it. It's amazing. I know the clear winner for me

Eashan Sinha's profile picture
Eashan Sinha7 months ago

Let's go

Tony Lee's profile picture
Tony Lee7 months ago

Okay I will cancel my cancelation of windsurf which I did yesterday.

Nate Chan's profile picture
Nate Chan7 months ago

hey i did it first

Alex Kaplan's profile picture
Alex Kaplan7 months ago

Let’s go 🥊🥊🥊🥊

Nnenna 👩🏽‍💻✨'s profile picture
Nnenna 👩🏽‍💻✨7 months ago

“Your codebase is the benchmark.” Spicy.

abuah's profile picture
abuah7 months ago

Can we use agents natively inside of Windsurf yet with their respective models? I want to do this with Claude Code and Codex, not Opus & GPT-5.2, if that makes sense.

swyx's profile picture
swyx7 months ago

some background for those intersted in details

Uncle J's profile picture
Uncle J7 months ago

Benchmarks are vanity metrics for model companies. The only benchmark that matters is "did my code ship without me babysitting it." Curious if Arena Mode tracks that.

Huseyn Hajiyev's profile picture
Huseyn Hajiyev7 months ago

Great benchmark approach! I believe it won't be more expensive and will allow us to pick the best result that way.

Charles Lazaroni's profile picture
Charles Lazaroni7 months ago

this is the right call. every synthetic benchmark gets gamed within a week. testing on your actual codebase with your actual stack is the only eval that matters. curious how the vote data looks after a month of real usage

Siddik's profile picture
Siddik7 months ago

But how is it useful? Many free arenas already exist where people can check model efficiency. Why would someone want to test a model by burning their own credits?

Micah Pierce's profile picture
Micah Pierce7 months ago

42 min in and SWE is now my go to.

Oskar Minor's profile picture
Oskar Minor7 months ago

It can be helpful - You'll be able to compare which model will be best for your project

Pratik's profile picture
Pratik7 months ago

This is genius. Benchmarks lie, but your own codebase doesn't.

bams's profile picture
bams7 months ago

Error

Botir Khaltaev's profile picture
Botir Khaltaev7 months ago

@windsurf, check out nordlys models,we build context specific routing, we took a bunch of swe data we clustered it to find real world tasks on a large scale, and built Nordlys Hypernova 75.6% on the SWE-Bench

Pratik's profile picture
Pratik7 months ago

This is actually smart. benchmarks mean nothing when you're 3 hours into debugging a specific codebase

Razex's profile picture
Razex7 months ago

But where s kimi ?

brgma's profile picture
brgma7 months ago

guys theres no switch or toggle for plan mode , check please

Vinícius Ragazzi's profile picture
Vinícius Ragazzi7 months ago

Who will win?

Alex Atallah's profile picture
Alex Atallah7 months ago

❤️

Apoorv Sharma's profile picture
Apoorv Sharma7 months ago

Will you train on this data?

8 Bit Elon's profile picture
8 Bit Elon7 months ago

@grok I thought windsurf was sunsetted and turn into antigravity?

Akshat Bahety's profile picture
Akshat Bahety7 months ago

I thought windsurf was dead

Echo's profile picture
Echo7 months ago

Just for paid member free

Sky's profile picture
Sky7 months ago

Add a damn confirmation on selecting a winner! 3 times now I've accidentally it whilst other models were still running (as normally the poorer model - sonnet 4.5?!? finishes early)

Related Videos

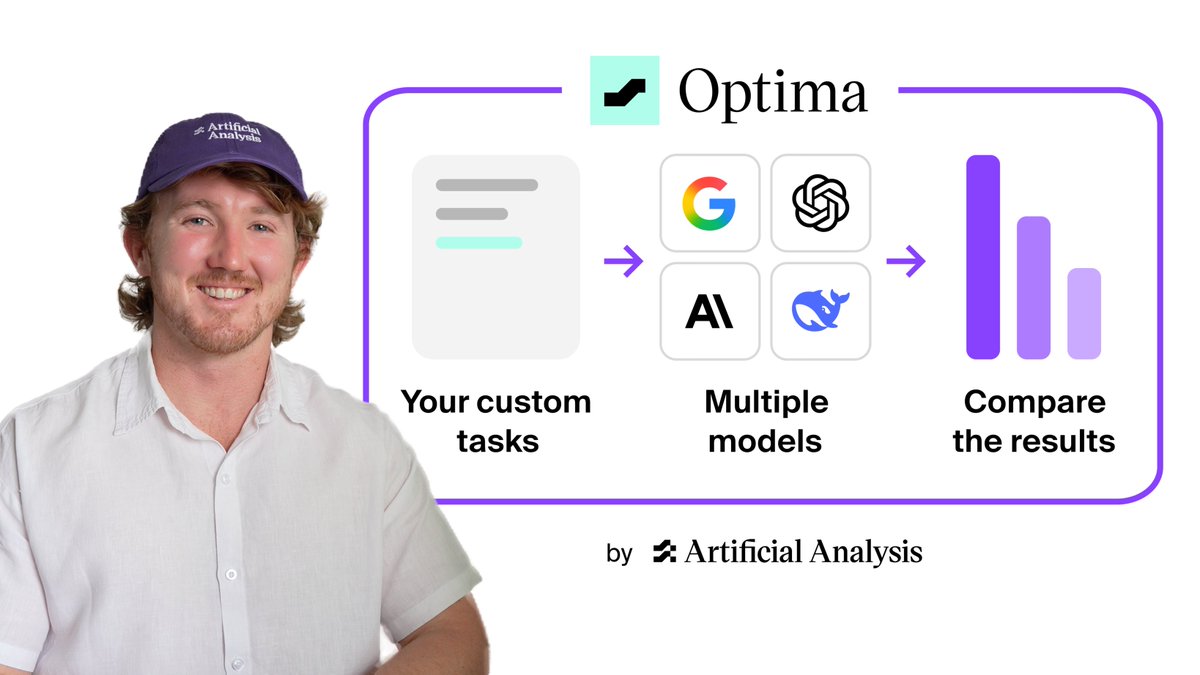
We’re launching Optima. Now anyone can create a custom benchmark for their use case, leveraging Artificial Analysis’ leading research and platform Building and running benchmarks is difficult. We have distilled Artificial Analysis’ research and experience developing benchmarks into Optima, a new platform for benchmarking models on your own workloads and comparing performance, speed and cost efficiency. Optima allows you to find the best model for your task, or an equally performant alternative to your current setup at 10x lower cost or time per task. We’ve integrated Artificial Analysis' research and experience in benchmarks across the Optima workflow: ➤ Build benchmarks based on your own data and use cases: There are three ways to build a benchmark with Optima. Upload an existing evaluation dataset from your own files or Hugging Face, or import agent traces from platforms including Arize AI, Braintrust and langfuse.com. Install the Optima skill to build a benchmark using context from your coding environment and previous sessions. Or simply describe your use case and provide example inputs and outputs, and Optima will build the benchmark for you ➤ Run across the latest models: Run the same benchmark across leading models in a single click, and keep your leaderboard up to date as soon as new models are released ➤ Bring Artificial Analysis grading to your own benchmark: Evaluate responses against objective rubric criteria or using the same pairwise judging approach used for Artificial Analysis benchmarks including GDPval-AA and AA-Briefcase. For pairwise judging, select your preferred responses from a sample and Optima uses those preferences to rank models across your test set ➤ Compare performance, cost and time efficiency: Optima measures more than model performance. Cost per Task and Time per Task are tracked alongside benchmark scores, with category-level results and support for custom metrics, allowing you to compare the tradeoffs between models for your specific use case Ahead of launch, here are examples questions our beta testers answered with Optima: ➤ Which model can save me 10x the cost without a meaningful decrease in quality for my finance & accounting agent? ➤ Which model best matches the writing style of lawyers for my legal agent? ➤ Which model can best identify different elements in my custom image dataset? Optima is available today. Build your own benchmark at

Artificial Analysis

132,623 views • 1 month ago