Загрузка видео...
Не удалось загрузить видео
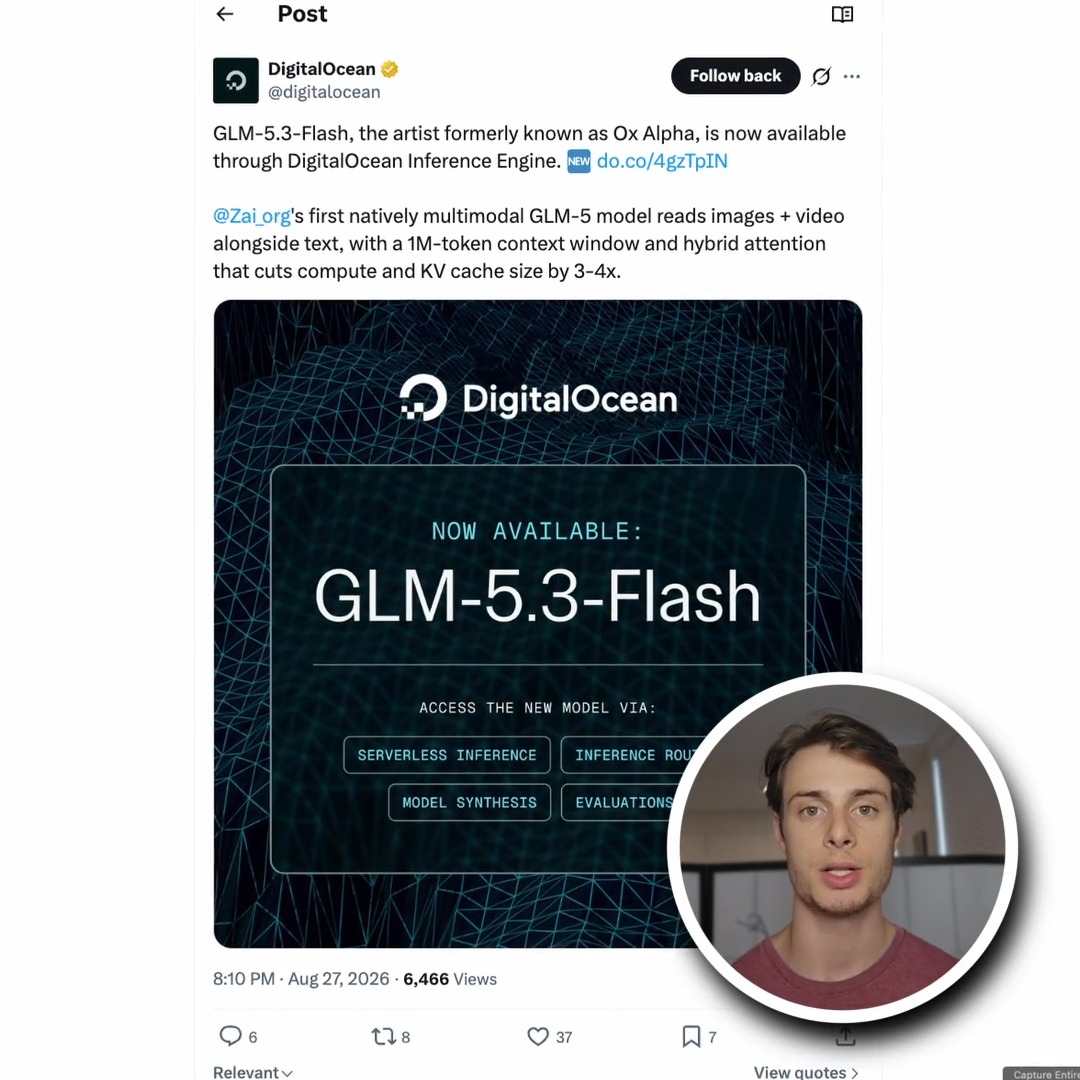
We're proud to be the fastest inference provider on Artificial Analysis, OpenRouter, and Hugging Face for GLM-5.3-Flash, at 122+ TPS. All served from the US only, starting on day 0, with ZDR by default. Stay tuned for updates as our engineers continue to optimize GLM-5.3-Flash for even higher throughput... show more

23,114 просмотров • 1 месяц назад •via X (Twitter)
Комментарии: 14

speed doesn't matter when you cant even use the model

Speed is important. Cost is even more important.

AMazing! Thank you very much!

122+ TPS 🔥 Day-0 launch is wild

122+ TPS matters, but geography and ZDR shape deployment choices.

make it cheaper

122+ TPS is genuinely impressive speed.

i’m at 290 toks it’s so nice also 20k pp/s 990 in batch of 8

What is ttft and your pricing ler million tokens

But you don’t even accept new customers to try your inference model api’s? So

Always rate limit in both openrouter and your platform…

I was hitting higher with GLM 5.3 flash today Just a couple small sessions. P90: 193.8 tok/s P90: 239.0 tok/s

fastest GLM-5.3-Flash on the planet also the only infra that treats “add credits” like Series A diligence

I'm getting constant 429 on openrouter when using this, has anybody experienced this as well?