Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

We’re releasing our Code Migration benchmark — and we managed to get Fable tested in time Code migration carries real economic weight. COBOL powers banks, payrolls, government services, and underpins nearly 95% of US ATM transactions. The danger with any migration is that a model ships code that looks...

17,124 görüntüleme • 3 ay önce •via X (Twitter)

5 Yorum

Amber Yang profil fotoğrafı
Amber Yang3 ay önce

cool video for a cool benchmark

Vals AI profil fotoğrafı
Vals AI3 ay önce

See which models did best at

安叫兽|Bird🕊️ 🔶 BNB profil fotoğrafı
安叫兽|Bird🕊️ 🔶 BNB3 ay önce

迁移最怕的就是这种静默漏行为

Gandhi profil fotoğrafı
Gandhi3 ay önce

TCSbench

Ethan Walker profil fotoğrafı
Ethan Walker3 ay önce

The real moat in AI may not be the model itself, but who owns the memory, tools, and context layer around it.

Benzer Videolar

GPT-5.6 vs GPT-5.5 on my custom spaceship prompt. I gave both models the exact same custom prompt. This is also the same prompt I previously gave to Fable 5. For context, GPT-5.6 Pro worked for 87 minutes, while GPT-5.5 Extra High worked for 34 minutes and 42 seconds. As I’ve said before, based on great authority GPT-5.6 will be an incremental/soldi improvement over GPT-5.5, not a “Fable killer.” My rough expectation has been that it would trade blows with Fable 5 on some benchmarks, maybe win around half depending on the category, but not clearly surpass it overall. And again fable five will have bigger model smell, but this was expected. After testing this coding output, that view feels pretty accurate. GPT-5.6 is clearly better than GPT-5.5 in several visual areas. The lighting, shading, chairs, object details, and exterior of the spaceship looked noticeably stronger. The scene was also easier to test. I do want to give GPT-5.5 credit though. It built out the rooms much much better and the planets looked better than GPT-5.6’s. It was also interesting that both GPT-5.5 and GPT-5.6 produced better-looking planets than Fable 5 in this specific test. The downside with GPT-5.5 was stability. The game was much glitchier and harder to test compared to GPT-5.6. But when it comes to the core of the demo, which is the spaceship itself, Fable 5 still beat both models pretty comfortably. GPT-5.6 is impressive, but from this test, it looks exactly like what I expected which was a meaningful incremental improvement over GPT-5.5, at least for indie game demos, but not something that replaces Fable 5. In collaboration with Chetaslua

Chris

250,919 görüntüleme • 3 ay önce

Claude Code tip: once Opus 5.5 is your main model, stop leaving Fable 5.1 sitting idle and stop burning Opus tokens on tasks Sonnet 5.5 can swarm put it on call with /advisor run /advisor fable Opus 5.5 plans and ships the code Sonnet 5.5 swarms the routine work at medium effort Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Fable 5.1 reviews. Sonnet 5.5 executes. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big model only sees the ones that split Plan on high. Delegate on medium. Keep Fable on call. - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on Sonnet 5.5 at medium effort > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

mirku

421,711 görüntüleme • 14 gün önce

Claude Code tip: once Opus 5.5 is your main model, stop letting your Fable 5.1 quota go to waste put it on call with /advisor run /advisor fable Opus 5.5 keeps doing the work Fable 5.1 sits on the sidelines, reads the whole session, and steps in at three moments: → before a plan: is this right? → when the same error comes back: am I going the wrong way? → before "done": did I miss anything? Fable 5.1 advises. Opus 5.5 writes the code the same idea sits under Jev engineering: the expensive model stops weighing in on every step and only gets called at the moments that change the outcome • the full setup > Opus 5.5 on high runs the main session > subagent one reads code > subagent two edits and runs tests > subagent three looks up docs > all three on medium > Fable 5.1 on call hand the tree and this prompt to Claude Code 👇 "Set up my Claude Code to match this tree: 1. Reuse fitting subagents from ~/.claude/agents and .claude/agents. > Propose new ones only for missing roles > Set each to model: opus, effort: medium > Leave any that set a different model alone and list them 2. Set main session effort to high via effortLevel in ~/.claude/settings.json 3. Check for env vars that disable the advisor (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, anything that stops flag fetching) and CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, don't change them 4. Add a rule to ~/.claude/CLAUDE.md: ask the advisor before a big plan, when an error repeats, and before calling a long task done Show me the changes first. Don't edit files yet." ↳

Mr. Buzzoni

324,943 görüntüleme • 16 gün önce

Chamath is making one of the most important business arguments of 2026. Half of large US companies right now cannot generate returns that exceed their cost of capital, which has normalized back to its long run average of 8 to 11%. Another one in seven companies globally is stuck generating persistent returns between 1 and 5% and most businesses don't have room for error and in this environment walks every frontier AI lab saying the same thing, give us your data, your workflows, your processes and our model will make everything better. And companies by the millions said yes. What they didn't fully account for is what happens on the other side of that door. Every time an employee runs a query through a frontier model API, the prompt goes through external servers, workflows, customer data, pricing logic, internal processes, all of it transmitted through a third party. As Alex Karp said companies are spending on tokens while handing over the exact proprietary advantages that make their business worth owning. Microsoft blocked internal use of Anthropic's Claude Fable 5 but over its 30-day data retention policy and the largest software company in the world decided a frontier model's data handling was too risky for its own employees. A US government action revoked access to another frontier model for foreign nationals overnight. Now here's where the cost math becomes impossible to ignore. Deutsche Bank calculated a roughly 65x cost gap between frontier models like Claude Fable 5 at ~$3.25 per task and open-source alternatives at ~$0.05. For 90% of everyday enterprise tasks, performance is comparable. Open-weight models now match closed frontier systems on core agent tasks at roughly one-tenth the cost, a high-volume deployment that costs $250/day on Claude runs at $12/day on an open-source equivalent. Chamath Palihapitiya tested this directly by running a standard enterprise code migration task through an orchestration layer wrapping an open-source model came in 16.4x cheaper than using a frontier model directly.

Milk Road AI

282,090 görüntüleme • 3 ay önce

This is f*cking insane. This Claude Code tip saved me thousands of dollars. once Opus 5.5 is your main model, stop burning it on work Sonnet 5.5 can do, while Fable 5.1 sits idle hand the grunt work to Sonnet 5.5 subagents and put Fable 5.1 on call run /advisor fable Opus 5.5 plans and ships the final code Sonnet 5.5 subagents read, edit and run the tests Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Sonnet 5.5 builds. Fable 5.1 reviews. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split anyone still running one model for everything is paying Opus prices to decide whether a file exists - the full tree > Opus 5.5 on high runs the main session > explorer reads the code on Sonnet 5.5 > worker edits and runs tests on Sonnet 5.5 > researcher pulls the docs on Sonnet 5.5 > all three on medium > Fable 5.1 on call for main and every subagent paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

48,494 görüntüleme • 10 gün önce

Claude Code tip: once Opus 5.5 is your main model, stop leaving Fable 5.1 sitting idle put it on call with /advisor run /advisor fable Opus 5.5 keeps writing the code Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Fable 5.1 reviews. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big model only sees the ones that split - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on medium > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: opus, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

698,269 görüntüleme • 15 gün önce

Claude Code tip, and it's absolute free f*cking gold: run Opus 5.5, Sonnet 5.5 and Fable 5.1 as one team and stop burning Opus tokens on routine work the setup in one line: plan on high, delegate on medium, keep Fable on call • who does what > Opus 5.5 on high - plans and ships the code > Sonnet 5.5 on medium - explorer reads code, worker edits and runs tests, researcher pulls docs > Fable 5.1 via /advisor fable - reads the whole session and speaks up only when it matters • when Fable 5.1 steps in -> before a plan: is this the right approach? -> when an error repeats: am I digging in the wrong place? -> before "done": what did I miss? Jev engineering takes it one layer lower: which file, which tool, retry or stop all go to Jev in under half a second, so the big models only see the real forks paste this into Claude Code ↓ "Rebuild my Claude Code setup: 1. Find subagents in ~/.claude/agents and .claude/agents that fit explorer, worker and researcher. Draft only the missing ones. Set each to model: sonnet, effort: medium. List any that pin a different model and leave them 2. In ~/.claude/settings.json set effortLevel to high and advisorModel to fable. 3. Report anything that disables the advisor (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, flag-fetching blockers) and CLAUDE_CODE_EFFORT_LEVEL. Change nothing. 4. Add to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done. Show every change as a diff. No edits until I say go." ↳

Mr. Buzzoni

143,984 görüntüleme • 13 gün önce

Claude Code tip: once Opus 5.5 runs your main session, stop leaving Fable 5.1 on the bench put it on call with /advisor run /advisor fable Opus 5.5 keeps writing the code Fable 5.1 reads the whole session, every tool call included, and only speaks up at three moments: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Fable 5.1 reviews. Opus 5.5 ships jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to jev in under half a second, and the big model only sees the ones that split - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on medium > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: opus, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

Hanako

52,065 görüntüleme • 13 gün önce

Official Anthropic tip for Claude Code: stop burning Opus 5.5 on work Sonnet 5.5 can do, while Fable 5.1 sits idle hand the grunt work to Sonnet 5.5 subagents and put Fable 5.1 on call run /advisor fable Opus 5.5 plans and merges Sonnet 5.5 subagents read, edit and run the tests Fable 5.1 reads the full session and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Sonnet 5.5 builds. Fable 5.1 reviews. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split - the full tree > Opus 5.5 on high runs the main session > explorer reads the code on Sonnet 5.5 > worker edits and runs tests on Sonnet 5.5 > researcher pulls the docs on Sonnet 5.5 > all three on medium > Fable 5.1 on call for main and every subagent paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

44,001 görüntüleme • 11 gün önce

China just released an open source AI model that matches the best closed models from OpenAI and Anthropic. Gavin Baker explained exactly how they did it and the answer should concern every American AI lab. The model is called GLM 5.2. It was built by Z. AI. You get 744 billion parameters, 1 million token context window and its MIT license, meaning anyone can download it, fork it, build a company on it, with no restrictions and no Dario. It scored 51 points on the artificial analysis intelligence index. The highest score any open weight model has ever achieved. It beat GPT 5.5 on the frontier software engineering benchmark. It trails Claude Opus 4.8 by less than one percentage point. And it costs 85% less to run than GPT 5.5 for comparable performance. Gavin Baker said on the All-In podcast that this model has challenged some of his beliefs. Then he explained how China built it. The method is called distillation. Just think of tens of thousands of phones and computers running simultaneously, all hitting the frontier model APIs through masked accounts, asking specific questions, and harvesting what happens inside the model when it answers. Every reasoning step, every token. The entire thinking process gets recorded and fed back into the Chinese model during training. It is a cheat sheet. It is the answer key to the exam. And here is the part that should worry everyone. Sacks said it plainly. China was already nine months behind American models. But now that GLM 5.2 is good enough to run its own reinforcement learning, it can improve itself without needing to distill from American models anymore. The cheat sheet let them get close enough to start writing their own answers. Sacks said we are six months behind on the model and 24 months behind on silicon and they are only a few months behind in total. The Z. AI founder told Elon Musk directly that open weight fable-level capability will be here before Q1 2027. Every restriction Anthropic lobbied for, every self-imposed safety guardrail, every month of delay in releasing American frontier models accelerated this. The Chinese labs were not under those restrictions. They were not going to wait. The composable model future Gavin described, where every enterprise runs a frontier model alongside their own fine-tuned open weight model, is coming regardless of what American labs do next. The question is just whether the open weight half of that stack is American or Chinese. Right now it is Chinese. WATCH THE FULL PODCAST ON The All-In Podcast

Ihtesham Ali

86,842 görüntüleme • 3 ay önce

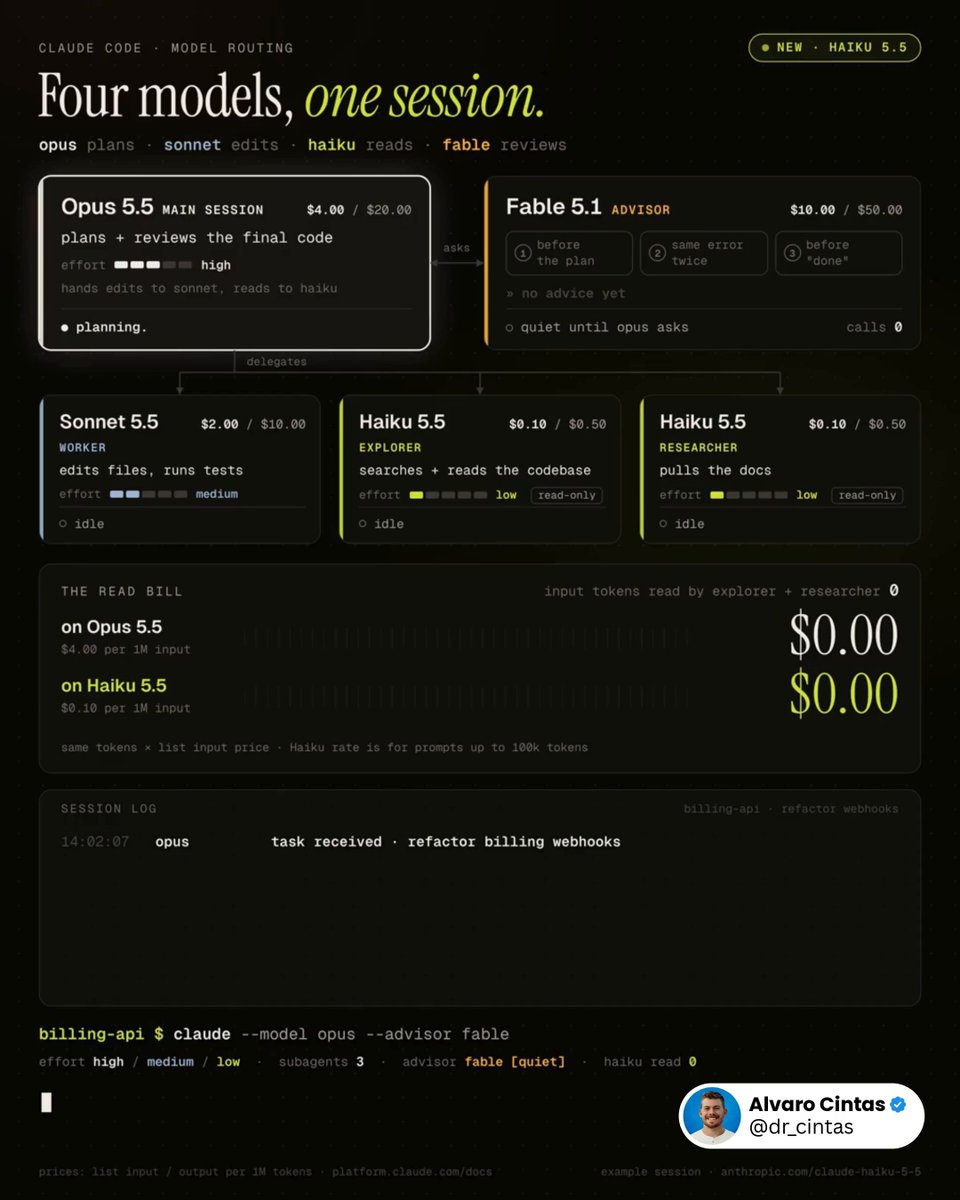
This workflow will save you thousands with Claude. Run Opus 5.5, Sonnet 5.5, Haiku 5.5, and Fable 5.1 together, and stop spending Opus tokens on work that doesn't need Opus. The entire idea in one line: Opus plans, Sonnet edits, Haiku reads, Fable reviews at decision points. Roles, broken down: - Opus 5.5, high effort, owns the plan and reviews the final code - Sonnet 5.5, medium effort, is the worker: edits files, runs tests - Haiku 5.5, low effort, splits into explorer (searches and reads the codebase) and researcher (pulls docs). it's the first Haiku with an effort setting - Fable 5.1, set with /advisor fable. Opus calls it at decision points, and it gets the full transcript each time Three moments Opus tends to call it: → before committing to a plan: is this the right approach? → the same error shows up again: is this going nowhere? → before marking the task done: did something get skipped? Why Haiku only reads: Anthropic's launch post says Sonnet 5.5 and Opus 5.5 are still the better choice for complex agentic coding (Terminal-Bench 4.0: 39.2% for Haiku 5.5, 70.6% for Sonnet 5.5) and that Haiku 5.5 fits narrowly scoped subagent work. so it gets the lookups, not the edits. Anyone still running one model for everything is paying $4 per million input tokens to check whether a file exists. Haiku 5.5 does it for $0.10. Drop this into Claude Code 👇 "Rebuild my Claude Code setup around this structure: Confirm Claude Code is v2.1.293 or later, so the haiku alias resolves to Haiku 5.5. If it isn't, stop and tell me to run claude update. Look through ~/.claude/agents and .claude/agents for subagents already covering explorer, worker, and researcher. Only create new ones for roles that are missing. Set model: haiku, effort: low on explorer and researcher, with no Edit or Write tools. Set model: sonnet, effort: medium on worker. If an existing subagent is locked to a different model, leave it as is and just list it. Name the explorer subagent Explore so it overrides the built-in one, which otherwise runs on my main model. In ~/.claude/settings.json, set advisorModel to fable, and set effortLevel to high for claude-opus-5-5 under modelSettings. A top-level effortLevel in user settings doesn't apply to Opus 5.5. Check for anything disabling the advisor: CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, or anything blocking feature-flag fetches. Also check CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort settings, and CLAUDE_CODE_SUBAGENT_MODEL_FORCE, which makes Claude Code ignore subagent model fields. Report what you find. Don't change any of it yet. Add one line to ~/.claude/CLAUDE.md: consult the advisor before a big plan, when the same error shows up twice, and before marking a long task done. Show every change as a diff first. Wait for my go-ahead before touching anything."

Alvaro Cintas

55,249 görüntüleme • 6 gün önce

Claude Code tip: keep Opus 5.5 as your main model, but stop paying Opus prices for your subagents move them to Sonnet 5.5 Opus 5.5 plans and decides Sonnet 5.5 subagents do the heavy reading, editing and testing at half the price ($2 / $10 vs $4 / $20 per 1M tokens) Fable 5.1 stays on call with /advisor and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Opus thinks. Sonnet does. Fable checks Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on Sonnet 5.5, medium > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: claude-sonnet-5-5, effort: medium > List any that pin a different model before changing them 2. Keep the main session on Opus, set effortLevel to high in ~/.claude/settings.json and advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

27,459 görüntüleme • 12 gün önce

Today, we’re releasing Athena (mvrko-sim-1), the flagship Large Event Model from markopolo.ai that beats GPT-5.6, Claude Opus 4.8, and Claude Sonnet 5 in OPeRa public benchmark for Shopping behaviour prediction! Athena introduces a completely different approach to understanding digital behavior. Most systems record actions after they happen. Athena models the sequence behind them to predict what a shopper will do next and exactly where they will do it, before the action even takes place. Athena vs. frontier models: We evaluated Athena on the full OPeRA test set alongside GPT-5.6, GPT-4.1, Claude Sonnet 5, and Claude Opus 4.8. Athena achieved 24.5% strict exact match scoring the highest among the five models evaluated. Athena is not a general-purpose language model. It is a Large Event Model built to understand behavior as a connected sequence. It combines the page someone is viewing, the actions that brought them there, and the goal they are trying to complete and then predicts the exact next browser action and target element. That distinction matters. Today’s digital systems largely react after someone clicks, abandons, purchases, or leaves. Athena creates the foundation for systems that can understand what is likely to happen before the outcome. Together with Rubaiyat, and the team at markopolo.ai, we built Athena from years of work on shopper behavior, digital journeys, and behavioral intelligence. Commerce was our first proving ground. Great thing is, we’re now releasing Athena publicly so builders can adapt the model to new datasets, industries, and problems. We’re seeing early usecases in Cyber Security, Gaming, Mobile App Ecosystem, Retail and more! Athena is now live on Hugging Face! We built the foundation for relevance and predictability! Now, let’s see what the world builds on top of it. Links in the first reply.

Tasbin

55,854 görüntüleme • 2 ay önce

Cerebras inference is very fast. So fast that it changes how we think about configuring our LLMs for voice agent use cases. Kimi K2.6 is a 1T parameter reasoning model that Cerebras serves at 650 - 1,000 tokens per second (end-to-end throughput), with time to first token metrics as low as 150ms (latency). These numbers are two to three times faster than other similarly capable models. The biggest lever we get from this kind of speed is that we can use the model in reasoning mode, and still have excellent "time to first non-thinking token." This solves a big pain point we have in 2026 for voice agent use cases. Almost all recent innovation in post-training has focused on making models good at reasoning ("test time compute"). This is great, but it makes the user-facing model latency much, much slower. Which is a problem for conversational voice agents. We can run Kimi K2.6 with reasoning turned on, and get responses faster than other models produce with reasoning disabled. On my 30-turn voice agent benchmark, Kimi K2.6 with reasoning enabled ties GPT 5.1 and Haiku 4.5 with reasoning disabled, and is still about 200ms seconds faster! On my primary task agent benchmark, Kimi K2.6 is now the #2 model. It ranks just behind Gemini 3.5 Flash in "high" reasoning mode, and tied with GLM 5, Sonnet 4.6, and GPT 5.4 with reasoning set to "low." But Kimi K2.6 completes each turn in the agent loop in under 500ms. The other four models are all at least 3x slower. (Models only qualify for this benchmark if they can complete task turns at a P50 <4s.) A couple of other things that this speed buys us, for production voice agents: - Tool calls happen fast enough that we don't have to work around tool call latency in our pipeline design. - We can prompt the model to output structured data at the beginning of a response, followed by plain text for voice generation. This opens up possibilities like asking the model to do complex classification/generation tasks that influence the rest of the pipeline. For example, the model could create a detailed style prompt for a steerable TTS model, for each individual conversation turn. And, of course, you can use Kimi K2.6 with reasoning turned off. Cerebras calls this "instant" mode. Here's a video of a Cerebras Kimi K2.6 voice agent with voice-to-voice response time, measured at the client, under 500ms. This is the true response latency as perceived by the user, including all network and audio codec overhead, transcription and turn detection, Kimi K2.6 token generation, and voice generation. 500ms is, effectively, instant. So the Cerebras naming for this mode is a propos. :-)

kwindla

40,593 görüntüleme • 4 ay önce

I don't understand why everyone isn't doing this yet. Anthropic's own Claude Code docs show how to run a whole team of Claudes, while Opus 5.5 only touches the plan and the merge the whole idea: agent teams in Claude Code one lead, separate teammates in their own context windows, one shared task list, and they message each other directly the lead: Opus 5.5 on high, splits the work, writes the tasks, merges at the end the builders: Sonnet 5.5, one owns client/, one owns api/, never the same file the adversary: Fable 5.1, never writes code, only shows up at three points: → before an interface locks: do both sides agree on the contract? → when a test fails twice: is it fixed or just hidden? → before a task is marked done: what breaks it? Sonnet 5.5 builds. Fable 5.1 attacks. Opus 5.5 merges Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the team only argues about the ones that split turn it on, then start the team in plain English: "Spawn three teammates: ux and backend on Sonnet, an adversary on Fable" - the full team > Opus 5.5 on high leads the session > ux on Sonnet 5.5, owns client/ > backend on Sonnet 5.5, owns api/ > adversary on Fable 5.1, owns nothing, reviews everything > shared task list with file locking, direct messages, no lead in the middle paste the team and this prompt into Claude Code ↓ "Set up agent teams for this repo: 1. In ~/.claude/settings.json add CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1 under env and set effortLevel to high 2. In ~/.claude/agents, draft three subagent definitions for the teammates > ux and backend with model: sonnet, each limited to its own folder > adversary with model: fable and read-only tools, whose only job is attacking contracts, repeated test failures and done claims > Skip any that already exist and list them 3. Add a TaskCompleted hook that blocks completion until the adversary signs off, and one rule to CLAUDE.md: no two teammates edit the same file 4. Find anything that would override this (CLAUDE_CODE_SUBAGENT_MODEL, CLAUDE_CODE_SUBAGENT_MODEL_FORCE, CLAUDE_CODE_EFFORT_LEVEL). Report it, change nothing Show me every change as a diff first. No edits until I say go." ↳

delost

70,168 görüntüleme • 9 gün önce

holy sh*t. Official Anthropic tip for Claude Code: stop burning Opus 5.5 context on tasks Haiku 5.5 can swarm, while Sonnet 5.5 builds put the architect on call with custom subagents CLAUDE_CODE_SUBAGENT_MODEL=haiku claude --model sonnet Sonnet 5.5 drives the primary session on high effort, writing diffs and running test suites Haiku 5.5 subagents swarm the repo in parallel at 340 tok/s, handling file discovery and spec docs lookup Opus 5.5 stays on call in ~/.claude/agents/ as the code reviewer, only stepping in at three critical moments: → before a plan locks: does the implementation plan miss auth invariants or schema contracts? → when a test breaks twice: are we fixing the root cause or falling into a recursive rabbit hole? → before calling done: did the full diff introduce hidden regressions or break pre-flight rules? Opus 5.5 reviews. Sonnet 5.5 builds. Haiku 5.5 swarms Claude Code subagent architecture runs the identical pattern through isolated contexts: high-volume operations (reading 30 files, grepping AST, running test suites) execute in separate worktrees, so 400k+ tokens stay in subagents while the primary session keeps a pristine 14k context Plan on high. Delegate on medium. Keep Opus on call. - the full subagent swarm setup > Opus 5.5 on call in ~/.claude/agents/code-reviewer.md catches deep architectural traps > Sonnet 5.5 lead drives edits, writes core logic, and executes test harnesses > Haiku 5.5 subagents swarm AST parsing, grep scans, and API docs in parallel at 340 tok/s > isolation: worktree guarantees test runs and scratch edits never pollute your git tree > isolated context windows shield the primary session from 400k+ tokens of verbose output paste the setup and this prompt into Claude Code below: "Configure my Claude Code workspace for hierarchical subagent orchestration: 1. Audit ~/.claude/settings.json and project config for model roles fitting lead, subagents, and reviewer: > Pin main session model: sonnet with effortLevel: high for primary execution > Set CLAUDE_CODE_SUBAGENT_MODEL to haiku in settings.json with CLAUDE_CODE_SUBAGENT_MODEL_FORCE to 1 > Pin custom code-reviewer model: opus with effort: high in ~/.claude/agents/code-reviewer.md 2. Create specialized subagent files in ~/.claude/agents/: > code-reviewer.md: model: opus, tools: Read, Grep, Glob, read-only review of plans and diffs > explorer.md: model: haiku, tools: Read, Grep, Glob, fast codebase search and AST discovery > researcher.md: model: haiku, tools: Read, WebFetch, external documentation and specification lookup 3. Configure automatic delegation checkpoints in ~/.claude/CLAUDE.md: > Invoke @ code-reviewer before finalizing multi-file architecture plans > Automatically summon @ code-reviewer when the same test or compiler error fails twice > Enforce @ code-reviewer diff contract audit before declaring tasks complete or staging git commits 4. Constrain subagent scopes: > Enable isolation: worktree for subagents making edits or running test harnesses > Return structured summaries only without flooding the main conversation context Show every configuration diff first. Do not apply edits until confirmed" ↳

mirku

106,514 görüntüleme • 3 gün önce