Загрузка видео...

Не удалось загрузить видео

На главную

We've raised $6.5M to kill vector databases. Every system today retrieves context the same way: vector search that stores everything as flat embeddings and returns whatever "feels" closest. Similar, sure. Relevant? Almost never. Embeddings can’t tell a Q3 renewal clause from a Q1 termination notice if the language is...

3,884,456 просмотров • 7 месяцев назад •via X (Twitter)

Комментарии: 66

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

If your AI agents keep retrieving the wrong context, explore HydraDB: Grateful to our investors who backed this vision: @Sky9Capital, @JeffDean, @gokulr, @shyamalanadkat, @klyap_, @0xJsum, @laura_yao, @caldbeckj, @anshulbhide, and @SeanZCai. @ashishkakran, @missionstcap, @prateeks, @MartinGTobias, @PickensAllison, @wadefoster, aekyi, @PuriSid, @mattsechrest, @CryogenicPlanet

Фото профиля Jeff Dean
Jeff Dean7 месяцев назад

Congrats!

Фото профиля Rohit Ghumare
Rohit Ghumare7 месяцев назад

Open source version:

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

We’re expanding our team - let’s chat?

Фото профиля Rohit Ghumare
Rohit Ghumare7 месяцев назад

DM'ed.

Фото профиля Nathan
Nathan7 месяцев назад

> The project "strawberry" and the fruit "strawberry" are the same word, but completely different contexts. VectorDBs cannot tell the difference. Except they can? The vector db simply abstracts fast storage and similarity computation via HNSW with a convenient API. Sure if you use static word embeddings they will map and be identical, but any decent text embedding model worth its salt today will be able to differentiate between these two concepts. And that has EVERYTHING to do with the embedding model and NOTHING to do with the vector db

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

tbh its not a vectorDB fault - its a function of how embeddings are computed and stored. different things. different problems. unfortunately no one wanted to hear about embeddings in our video.

Фото профиля Kevin Qi
Kevin Qi7 месяцев назад

Relational databases have existed since the advent of computers. Why do we need to reinvent the wheel every year?

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

RDBMS directly can't be used as context engineering infra for your AI to work with complex enterprise knowledge bases

Фото профиля Kevin Qi
Kevin Qi7 месяцев назад

You are saying that a competent tech team cannot reproduce what you offer simply by using sql and a good pre processing system to build the same relationships you tout?

Фото профиля Kevin Qi
Kevin Qi7 месяцев назад

And then on LLM requests, just show the returned relevant request into the context window ?

Фото профиля Tiffany Fong
Tiffany Fong7 месяцев назад

No error message. Just looks right. You'd never know.

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

No @hydra_db = ngmi

Фото профиля Jason Kneen
Jason Kneen7 месяцев назад

Not open-source? Nah.

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

if we open source will you become a customer?

Фото профиля Jason Kneen
Jason Kneen7 месяцев назад

if there is value in what the SAAS offers yes. If I can develop it myself with AI because it's overpriced then no. And if you don't open-source it the community will just build an OSS one anyway. So this is your chance to do that, own the repo, guide the development AND you have a ready made recruitment pool and advocate pool of developers who will be contributing, forking and adding to your product! A simple license that insists derivatives have to be open source and you can include their features in the core and you've got it all covered

Фото профиля GuestHiveAI
GuestHiveAI7 месяцев назад

This is exactly the problem I hit building an AI concierge for short-term rentals. Guest asks "where's the vacuum?" — pure vector search returns the cleaning fee policy. High similarity score. Completely wrong. So I stopped trusting embeddings alone. Built a hybrid system: → Semantic search (0.65) + full-text match (0.25) + recency bias (0.10) → Live context injection (who's checked in, which property, what time) → 3-level gatekeeper that only surfaces emergency info when the situation actually calls for it All in PostgreSQL. No separate vector DB. No $6.5M. The real unlock isn't better embeddings — it's knowing WHEN and WHY someone is asking.

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

we're expanding our team. let's give it a shot?

Фото профиля GuestHiveAI
GuestHiveAI7 месяцев назад

5 weeks. Solo. 128K lines of Python. Running in production right now handling real guest conversations 24/7. If that's the energy you're hiring for — DMs open

Фото профиля Simspron
Simspron7 месяцев назад

@contextkingceo Pretty sad when you can’t even write your own tweets

Фото профиля GuestHiveAI
GuestHiveAI7 месяцев назад

@contextkingceo 🤖

Фото профиля vixhaℓ
vixhaℓ7 месяцев назад

Finally someone brave enough to say it out loud: vector DBs are gaslighting our agents.

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

LETS SHOUT THIS OUT

Фото профиля JT
JT7 месяцев назад

this is why AI search across internal tools always feels slightly off

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

100%

Фото профиля Subah Wadhwani
Subah Wadhwani7 месяцев назад

LFG! Congrats guys. Was so much fun working with you on this.

Фото профиля Rohan Paul
Rohan Paul7 месяцев назад

I dont want my agents to reset their brains every session. Moving away from flat vector retrieval toward a structured memory tree is truly a great practical approach for solving agent continuity.

Фото профиля Soham Ratnaparkhi
Soham Ratnaparkhi7 месяцев назад

Flat embeddings + 10M docs = confident hallucinations at scale. The fix isn't a better embedding model. It's a fundamentally different retrieval layer - one that tracks relationships, ownership, and temporal state. Super proud to be building this since Day 0 Big year ahead 🚀 and ofc, congrats boss - lesss goo

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

yessir, can we please make @hydra_db 100x better?

Фото профиля Soham Ratnaparkhi
Soham Ratnaparkhi7 месяцев назад

@hydra_db Yessir

Фото профиля Carl Vellotti 🥞
Carl Vellotti 🥞7 месяцев назад

LLM search works great on 500 docs, dies at 10M. And you never realize until it's too late.

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

LLM search at demo day: genius LLM search in prod: confidently returns your CEO's lunch order as a "relevant policy document"

Фото профиля CG
CG7 месяцев назад

Finally someone did something about this, cool launch video too.

Фото профиля Charly Wargnier ♨️
Charly Wargnier ♨️7 месяцев назад

Congrats @contextkingceo! "Similar ≠ relevant" is the exact bottleneck of naive RAG rn. great to see you've built this 🤗

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

thank you @DataChaz! that bottleneck is exactly what pushed us to build this

Фото профиля Hannaan Kirmani
Hannaan Kirmani7 месяцев назад

so you're saying it won't go looking for my ex when i ask it to find X?

Фото профиля dinos
dinos7 месяцев назад

nice marketing video. where's the benchmark?

Фото профиля Vaibhav Domkundwar
Vaibhav Domkundwar7 месяцев назад

A lot of Better portcos are going to love this Nish — sending your way! Congrats on the launch. 🚀

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

Thank you sooo much @vaibhavbetter! So excited to have you onboard

Фото профиля Raul Junco
Raul Junco7 месяцев назад

Interesting idea. Vector search is great, but it struggles with context as datasets get larger. Adding a graph or ontology layer to capture relationships could help avoid a lot of those weird retrieval mistakes. Congrats!

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

exactly, and that's what we're solving for at @hydra_db!

Фото профиля Arlan
Arlan7 месяцев назад

lowk @turbopuffer is still very good but will try out ur product soon

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

@turbopuffer we think turbopuffer is great - we solve different problems :) if you want relations, timeline of how context has evolved, deal with messy unstructured knowledge then you need to try @hydra_db

Фото профиля Brian Chew
Brian Chew7 месяцев назад

Congrats on the launch! - x icon in footer still redirects to old handle: - site title still says cortex - the site's opengraph thing still shows cortex just wanted to share in case it helps!

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

thank you for pointing it out

Фото профиля Sean Cai
Sean Cai7 месяцев назад

Excited to back since day one :) Excellent anti-agi hedge, but I haven't been so excited about a vector db adjacent product since turbopuffer. There are personally some inane use cases around migrating enterprises to this context graph to better collect their reasoning traces for rl envs!

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

Ha anti agi hedge I love that. Grateful for your support and counsel as always!

Фото профиля Mikael
Mikael7 месяцев назад

Damn dude you got a lot of investors

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

grateful for their support

Фото профиля Average Database CEO
Average Database CEO7 месяцев назад

Did you mean $60.5m?

Фото профиля polihedge
polihedge7 месяцев назад

1. Don't want to book a demo 2. Pricing page loops to homepage 3. Several links in footer do not exist 4. Privacy Policy and Terms of Use are crossed links Lots of errors on the vibe code template site for HydraDB.

Фото профиля Antaripa Saha
Antaripa Saha7 месяцев назад

the problem statement is very real and have faced such issues during multiple client projects, would love to test out hydradb. congratulations, Nishkarsh!

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

this is sooo real...i feel it

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

Amazing - this goes in our next launch video

Фото профиля Siddhartha Saxena
Siddhartha Saxena7 месяцев назад

VectorDB are really broken and they just don't work. Excited to try out Hydra!

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

will wait to hear about your experience, my DMs are always open:)

Фото профиля Siddhartha Saxena
Siddhartha Saxena7 месяцев назад

Yes, going to this a try this weekend!

Фото профиля cole murray
cole murray7 месяцев назад

man with db tech to sell says other DB tech is bad ignoring the larger search problem

Фото профиля AshutoshShrivastava
AshutoshShrivastava7 месяцев назад

No 1 failure point is retrieval and most of us on X is arguing mostly about benchmarks. Lol

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

benchmarks won't save you when retrieval grabs the wrong client's contract

Фото профиля Shruti
Shruti7 месяцев назад

99% of AI companies are building on fundamentally broken retrieval. The 1% who figure this out first will own their vertical.

Фото профиля Tulsi Soni
Tulsi Soni7 месяцев назад

Actually useful vs the usual "10 AI tools" threads.

Фото профиля Lisa
Lisa7 месяцев назад

Every company building AI agents needs this. Some of my most gratifying moments as an investor have been hearing how much your customers love the product.

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

hearing things like that from customers is the best part of this whole journey 🙏

Фото профиля Prateek Sharma // Ahead VC
Prateek Sharma // Ahead VC7 месяцев назад

Love the idea of the librarian to capture the power of hydradb. Humans remember through a web of connections and our memory evolves as context changes. Great to see that finally AI can do the same! Congrats on the launch @contextkingceo and @hydra_db team!

Фото профиля Nishkarsh
Nishkarsh7 месяцев назад

@hydra_db grateful for your support always @prateeks!

Похожие видео

Researchers built a new RAG approach that: - does not need a vector DB. - does not embed data. - involves no chunking. - performs no similarity search. And it hit 98.7% accuracy on a financial benchmark (SOTA). Here's the core problem with RAG that this new approach solves: Traditional RAG chunks documents, embeds them into vectors, and retrieves based on semantic similarity. But similarity ≠ relevance. When you ask "What were the debt trends in 2023?", a vector search returns chunks that look similar. But the actual answer might be buried in some Appendix, referenced on some page, in a section that shares zero semantic overlap with your query. Traditional RAG would likely never find it. PageIndex (open-source) solves this. Instead of chunking and embedding, PageIndex builds a hierarchical tree structure from your documents, like an intelligent table of contents. Then it uses reasoning to traverse that tree. For instance, the model doesn't ask: "What text looks similar to this query?" Instead, it asks: "Based on this document's structure, where would a human expert look for this answer?" That's a fundamentally different approach with: - No arbitrary chunking that breaks context. - No vector DB infrastructure to maintain. - Traceable retrieval to see exactly why it chose a specific section. - The ability to see in-document references ("see Table 5.3") the way a human would. But here's the deeper issue that it solves. Vector search treats every query as independent. But documents have structure and logic, like sections that reference other sections and context that builds across pages. PageIndex respects that structure instead of flattening it into embeddings. Do note that this approach may not make sense in every use case since traditional vector search is still fast, simple, and works well for many applications. But for professional documents that require domain expertise and multi-step reasoning, this tree-based, reasoning-first approach shines. For instance, PageIndex achieved 98.7% accuracy on FinanceBench, significantly outperforming traditional vector-based RAG systems on complex financial document analysis. Everything is fully open-source, so you can see the full implementation in GitHub and try it yourself. I have shared the GitHub repo in the replies!

Avi Chawla

974,238 просмотров • 9 месяцев назад

Traditional data pipelines don't work for RAG applications. There are 3 issues with them: ​ 1. Traditional data engineering solutions are optimized to handle structured data. RAG applications rely primarily on unstructured data. ​ 2. The connector ecosystem to load data from unstructured data sources is very immature. ​ 3. Traditional solutions do not offer any way to transform unstructured data into an optimized vector search index. ​ The goal of a RAG Pipeline is to solve these problems. ​ The number one objective is to create a reliable vector search index using factual knowledge and relevant context. This sounds easy, but it's one of the biggest challenges we face when building RAG applications. ​ At a high level, there are four different stages in the architecture of a RAG pipeline: ​ 1. Ingestion: Here is where the pipeline loads the information from the data source. ​ 2. Extraction: Where the pipeline processes the input data and decides how to retrieve the text contained inside them. ​ 3. Transform: Where the pipeline chunks the data and generates document embeddings. ​ 4. Load: Where the pipeline creates a search index in a vector database and loads the document embeddings. ​ There are different rabbit holes at each one of these stages. Here are three of them: ​ 1. Ingesting data once is simple. The hard part is refreshing the vector database whenever the original data source changes. ​ 2. Extracting the content of a plain text document is simple. The hard part is to extract content from complex documents containing tables, images, or cross-references. ​ 3. A simple continual chunking strategy with an overlap is simple. The hard part is to find the optimal strategy for your specific knowledge base and the way you are planning to query it. ​ In the attached video, I'll show you how you can build an enterprise-grade RAG Pipeline that solves every one of the above problems. ​ I'll use Vectorize. They partnered with me on this post. You can use them to build RAG pipelines optimized for accurate context retrieval. ​ ​ If you have a few documents lying around, set up a free account and give it a try.

Santiago

40,646 просмотров • 2 лет назад

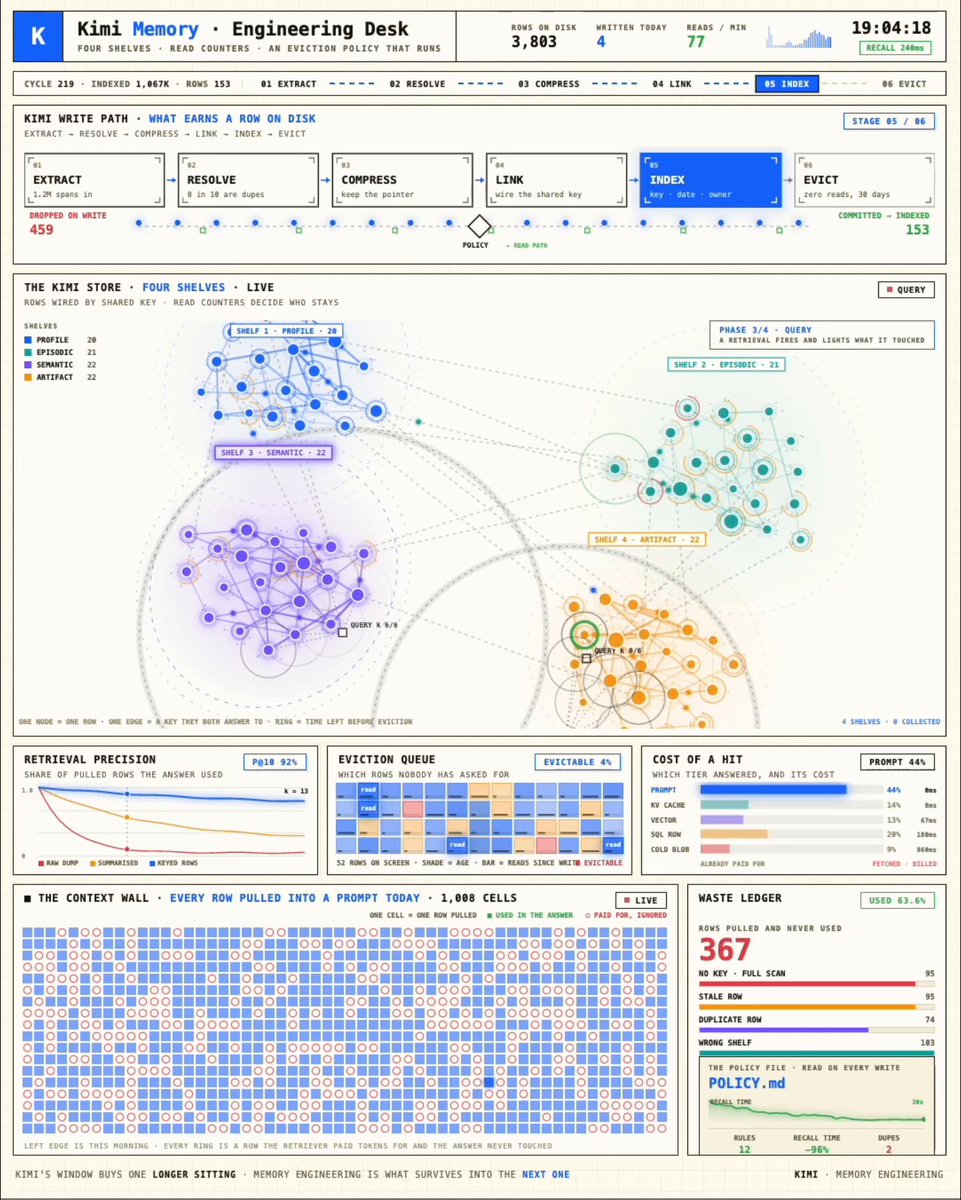
Engineer runs a Kimi K3 memory layer that costs $11 a month and remembers what a $500,000 vector database keeps losing. No embeddings. Four nodes and one rule about what's allowed to be forgotten. He published the whole schema. His version starts from the opposite idea. Memory is not a pile you search. It's a set of claims that expire unless something keeps paying to keep them. Four nodes. Every memory carries a clock someone has to reset: > WRITER - stores a fact with the reason it mattered, never raw text > DECAY - ages every memory down. Silence is deletion > RENEWER - only re-lifts a memory the model actually used again > GRAVE - holds what died, and why nobody reached for it Three nodes keep memory alive. One keeps the dead ones. Recall isn't storage here. It's rent a fact has to keep earning. That's the entire design. When everything is remembered forever, the useful and the stale retrieve identically. He replayed two months of agent context. 90,000 stored facts. 71,000 never retrieved once. The vector store returned all of them on similarity. Similarity graded closeness. Nobody graded whether the memory was ever right. Everyone else stuffs more into the context window and calls it memory. He built a layer that lets a fact die unless it keeps proving itself. The cost isn't storage. It's finding out how much of what your agent "knows" it has never once used. The article below is the full build - node prompts, the decay curve, the renewal rule. Save it. You'll want it open in the other tab.

wast3

67,778 просмотров • 2 месяцев назад

Announcing a new Coursera course: Retrieval Augmented Generation (RAG) You'll learn to build high performance, production-ready RAG systems in this hands-on, in-depth course created by and taught by , experienced AI and ML engineer, researcher, and educator. RAG is a critical component today of many LLM-based applications in customer support, internal company Q&A systems, even many of the leading chatbots that use web search to answer your questions. This course teaches you in-depth how to make RAG work well. LLMs can produce generic or outdated responses, especially when asked specialized questions not covered in its training data. RAG is the most widely used technique for addressing this. It brings in data from new data sources, such as internal documents or recent news, to give the LLM the relevant context to private, recent, or specialized information. This lets it generate more grounded and accurate responses. In this course, you’ll learn to design and implement every part of a RAG system, from retrievers to vector databases to generation to evals. You’ll learn about the fundamental principles behind RAG and how to optimize it at both the component and whole-system levels. As AI evolves, RAG is evolving too. New models can handle longer context windows, reason more effectively, and can be parts of complex agentic workflows. One exciting growth area is Agentic RAG, in which an AI agent at runtime (rather than it being hardcoded at development time) autonomously decides what data to retrieve, and when/how to go deeper. Even with this evolution, access to high-quality data at runtime is essential, which is why RAG is a key part of so many applications. You'll learn via hands-on experiences to: - Build a RAG system with retrieval and prompt augmentation - Compare retrieval methods like BM25, semantic search, and Reciprocal Rank Fusion - Chunk, index, and retrieve documents using a Weaviate vector database and a news dataset - Develop a chatbot, using open-source LLMs hosted by Together AI, for a fictional store that answers product and FAQ questions - Use evals to drive improving reliability, and incorporate multi-modal data RAG is an important foundational technique. Become good at it through this course! Please sign up here:

Andrew Ng

124,981 просмотров • 1 год назад