AJ
@ItsmeAjayKV • 8,109 subscribers
Bullish on local AI LLM finetuning, quants, repe, llama.cpp Jobless atm! 1x 3060, 1x 3090: 64GB RAM https://t.co/btCRUhcuR3 N4 (日本語勉強中) 🎌
Videos

Here's a comparison i never thought i would make Qwen-3.8-27b vs Gemini-3.7-flash Yes, you read it right! I don't know what to say, this is soo damn impressive. the difference is hugeee🤯 Take a look at this result 😍 (watch it in highest quality) Same prompt, both one shot on web-chat ui Qwen-3.8-27b produces consistent beautiful, visually stunning results. This is one of the best water surface simulations i have seen across every local models i have run and at the same time beating Gemini-3.7-flash result. And this is running on my 3090. And yes its Q5, not even f8.
AJ302,855 Aufrufe • vor 1 Monat


I'm really really impressed with Qwen3.8-Flash-Next😍 It is better than Qwen3.8-27B !! Below is a screen-recording from a Three.js FPS game made by Qwen3.8-Flash-Next running on my 3090. Everything here is generated at runtime: textures, sounds, music, models and the rigid-body solver. No image, audio or mesh files are downloaded. three.js is loaded from a CDN. atomic.chat Qwen3.8-Flash-Next IQ4_XS👌 DeepSeek Harness 👌 Single RTX 3090 + 64GB RAM (Total 88 GB) Stats: - ~ 10 - 11 hrs in total - 22M tokens, 94% cache - Avg decode 20t/s - Avg prefill 200t/s - TTFT avg 9.6s It is slow, but faster than Unsloth IQ3_XXS !
AJ18,718 Aufrufe • vor 1 Monat

For the first time, i'm not even bothered about missing Fable 5.1 Because i now have Qwen Qwen3.8-Flash-Next with me🤯! PS: Single 3090 users, you might not want to skip this one, you're in for a treat ! Gap between frontier closed models and local models is getting really really small. Building a Rocket League type game in Three.js 🚗⚽️ Gave it a starting prompt and let agent cook. It built an entire Rocket League style experience from scratch. 3D arena, car physics, ball physics, boost system, double-jump flips, goals, kickoff screen, AI apponent, 3- min matches, overtime, score hud, multiple camera modes, particles and sfx. You know the crazy part? This is Qwen3.8-Flash-Next running locally on my single 3090. You know what quant i'm using ? It's Unsloth AI UD-IQ3_XXS💀 7.27M tokens, ~6.89 cached in 2h 30min. Local AI is getting ridiculous🚀
AJ12,914 Aufrufe • vor 29 Tagen

🤯Laguna S-2.1 UD-IQ3_S on a single 3090 ~30-35t/s decode ~280-290t/s prefill ~23GB VRAM @ 64k context, f16 KV llama.cpp: -ngl 999 + --n-cpu-moe 32 + fa on 118B MoE, ~8B active, did we get a decent mid-range model that doesn't need multi gpu and can run with good enough speeds for long-context coding tasks? Might actually stick with this one. Been waiting for a mid-range model that fits on a single 3090, this is it. Usual three.js tests underway. Update soon.
AJ20,339 Aufrufe • vor 2 Monaten

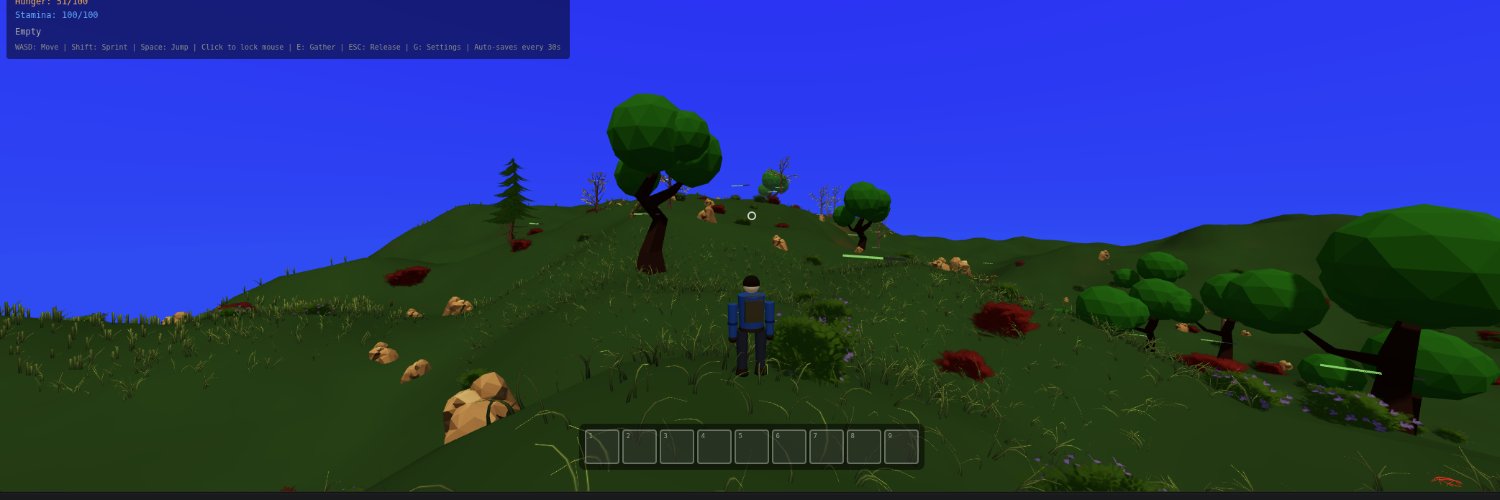
I'm really happy with Qwen3.8-27B ! All frustrations of not able to use Ox-Alpha and running out of credits for Glm-5.3, Grok turned me into Qwen-3.8-27b. Running locally on my 3090. This is the first fps game i'm creating with Qwen3.8-27b. I was after NMS vibe, alien planet, vast, flying drones, background music + sound effects. Without any external assets at all. With proper game like graphics settings panel 😍 And i'm really impressed, because all this is generated with my mixed quant for Qwen3.8-27B, which gives me more context + speed for a really good quality work. DSK harness at beginning and Pi agent towards the end cause i wanted to get this done fast. Full quant name: HF aj9o9/Qwen3.8-27B-GGUF file name: Qwen3.8-27B-gdn8-q6attn-iq3ffn.gguf Just like all of you, i also hate having to compact context, so higher context without ever needing to compromise quality is what i'm always after and this quant is created for that. Gives me 210K context at q8_0 kv + dflash2 Q4_K_M for speculative decoding. This result in 23GB vram usage.
AJ12,696 Aufrufe • vor 1 Monat


Every big MoE model I test on my 3090 is basically to see how good it is compared to Qwen3.6-27B. "How good is it compared to Qwen3.6-27B?" is the question I get asked the most, and that shows how much people love and, more importantly, trust the 27B 27B is battle tested. It has proven its worth and has nothing left to prove. Now it just needs to make way for the next 27B. Here’s an example video: a Three.js task, same prompt, not oneshot but two shots for all models. All ran on my 3090 + 64GB VRAM Qwen-3.6-27b fully on vram while others have experts offloaded to system ram. Pinned on the left: Qwen3.6-27B-Q5 On the right, i'm switching between Inkling-Small-Q4_K_M DSV4-Flash-0731-UD-IQ1 Ling-3.0-Flash-Q4_K_M Qwen3.6-27B nailed it. The effects and visuals are just spot on.The other models got some things right, but not everything. Second place would have to go to Inkling-Small while DSV4-Flash-0731 and Ling-3.0-Flash failed to capture the full requirements. This is also why we’re all excited for Qwen Qwen3.8-27B!
AJ11,670 Aufrufe • vor 1 Monat

Y’all thought I stopped at Q4_K_M 😭 Nope, q3 and q4 didn't cut it, quality was not at all good on my three js tests. So now running Poolside Laguna S-2.1 UD-Q5_K_S same 3090 + 64GB RAM same hybrid offload q8_0 KV 166k ctx Q4 was ~73 GB. Q5 is ~83 GB. More bits on disk. Hopefully this one is better, We’ll see if it’s worth it.
AJ13,341 Aufrufe • vor 2 Monaten
Keine weiteren Inhalte verfügbar