Video yükleniyor...
Video Yüklenemedi
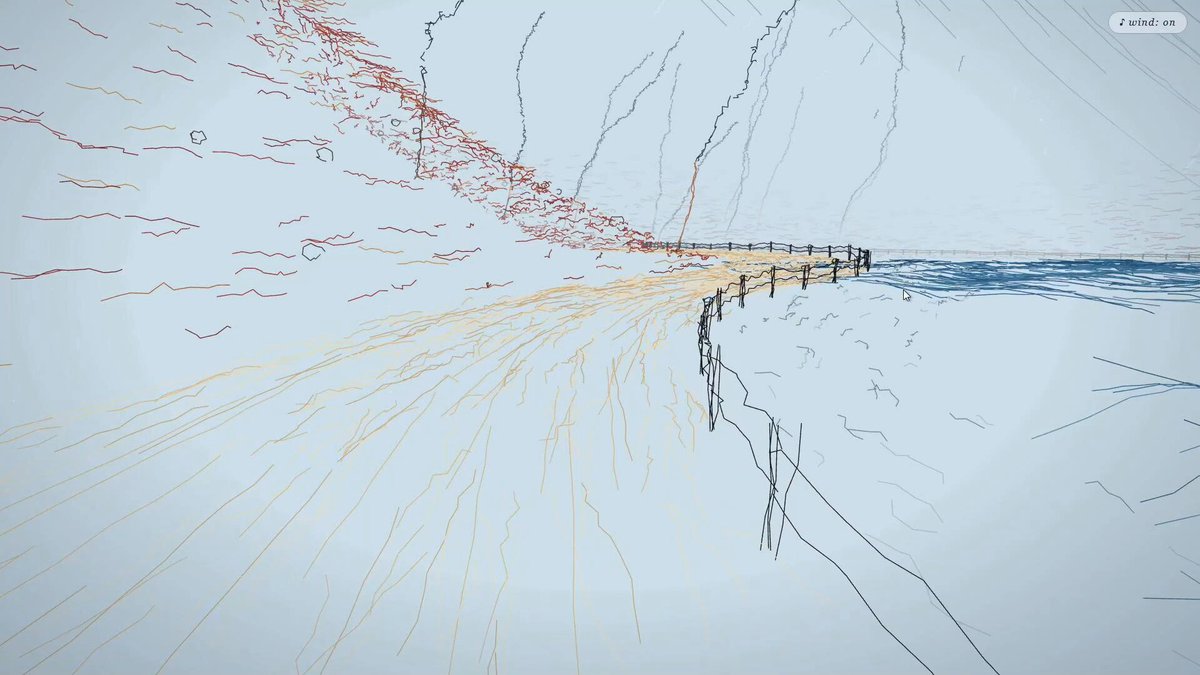
Here's a comparison i never thought i would make Qwen-3.8-27b vs Gemini-3.7-flash Yes, you read it right! I don't know what to say, this is soo damn impressive. the difference is hugeee🤯 Take a look at this result 😍 (watch it in highest quality) Same prompt, both one shot... show more
302,905 görüntüleme • 1 ay önce •via X (Twitter)
33 Yorum

prompt: Create a Three.js water simulation. Requirements: Plane mesh with 512x512 subdivisions Wave propagation simulation Mouse click creates ripples Multiple interacting waves Real-time lighting Everything in a single HTML file No external libraries besides Three.js
y'all supernova cooked with this one. What a model 😍

considering how cheap 3.7 flash is its probably a MoE around 60-70b, so actually a fair comparison
Overall this is a good win for 27b.

Gemini Flash 3.7 dead on arrival
So happy with 3.8-27b now

I was getting 38-45t/s out of unsloth's Qwen3.8-27b earlier today consistently out of a single 3090 and 64GB DDR4 RAM.
With MTP right? im switching between Q4/Q5 as i see fit.

Man you can make YouTube vidoes but more in depth?
I can, anything in depth you like to see here, i can prob make a post faster.

It is a great win for qwen 🚀

Comparing anything with Gemini models is a crime. Gemini is garbage through and through.
Haha valid reaction lol

Wow 👌 👏 😍

Q5 is significantly better than q4?

What harness are you using?
For that demo, just from webchat ui The harness i use most is pi, then Hermes and opencode

On 3090 on Q5 ? What about your context length ? How do you do ? I ve same 3090, can you share your llama.cpp settings ? 🙏

Very impressive, do you think Qwen 3.8-27B can handle controlling other LLM ? just like opus can do

wow local is real now again! wish coding subs would have them

Hi! Big thanks for gguf! Do your models have MTP?

Which is which, it's not clearly visible
It's in header, left is qwen, right is gemini

That Qwen result on a 3090 is wild 🤯 Local winning

What's average tps here ?

cool results! I’ll try this on 2bit, really curious about how it will handle

RTX3090 24GB, with how much RAM, and which CPU, and is that vLLM or llama.cpp ?

Amazing! Just a technical question: how did you manage the context window? I can't load a long one and it have to do multiple compact even with just one prompt.

But what should be the laptop specification

@GeminiApp hello

wait,why my qwen 3.8 27b make this for me? q8 model
Try with this prompt "Create a Three.js water simulation. Requirements: Plane mesh with 512x512 subdivisions Wave propagation simulation Mouse click creates ripples Multiple interacting waves Real-time lighting Everything in a single HTML file No external libraries besides Three.js "

Incredible model it is. Im really impressed