ModelScope
@ModelScope2022 • 15,020 subscribers
Driving innovations with open communities. 💬 Join our Discord: https://t.co/4M9AHVh5qa
Shorts


Videos

Meet LingBot-World 2.0.🌍A 1.3B world model, running continuous interactive generation in real time on a single consumer GPU. 🤖 ⚡ It responds to movement, camera control, combat, and text-driven events in real time, while the scene keeps unfolding instead of ending as a fixed video clip. 🌌 Causal pretraining and MoBA help preserve textures, geometry, and scene consistency over long autoregressive rollouts. 🧠 Consistency and distribution-matching distillation compress multi-step generation and train the model on its own rollouts, reducing accumulated drift. 🛠️ The 14B Causal Pretrain backbone and Bidirectional teacher are also open, giving developers a path to post-train, distill, compress, and adapt new world models. 🔒 CC BY-NC-SA 4.0. Non-commercial use only.
ModelScope33,630 просмотров • 1 месяц назад

NeoHorse-Jev-4B is now open—a compact model built to turn application states directly into structured decisions and probabilities. 🤖 🏆 Scores 77.70 across six text decision benchmark groups, ranking first among the four open-weight models with complete results in the comparison. ⚡ Prefill-only inference avoids autoregressive answer generation and supports three decision primitives: Choice for action selection, Noul for yes/no judgment, and Score for ordered ratings. 🎮 The same interface can power request routing, tool selection, workflow control, games, robot manipulation, and autonomous-driving simulations. 🖼️ Supports text inputs or a single image combined with text, returning normalized probabilities that applications can use directly. 🛠️ Deploy locally through vLLM, SGLang, Python, CLI, or HTTP. Apache 2.0.
ModelScope19,925 просмотров • 29 дней назад

Say hello to DreamX-Creator 1.0, a 7B native audio-video generator with local 2K refinement. Apache 2.0. 🤖 🏆 Delivers results comparable to much larger SOTA models like MiniMax H3 on Verse Bench, reaching 0.1351 DeSync after RL and 0.6930 VQ with the 2K Refiner. 🎬 Turn a first frame and prompt into synchronized video, dialogue, action sounds, ambience, weather, crowds, and music. No separate dubbing stage. 🔊 Gated Cross-Modal Attention lets sound and visuals shape each other, while modality-aware RL improves video, audio, and their alignment. ✨ The one-step 2K Refiner tops the compared refinement methods on MUSIQ (0.7073) and MANIQA (0.4382) while preserving motion and audio timing.
ModelScope31,067 просмотров • 1 месяц назад

Only ~1.2B parameters active at a time. Edge0-8B-A1B-preview makes an 8B-class MoE practical for local inference.📜 Apache 2.0. 🤖 ⚡ Reaches 23.9–25.3 tokens/s with about 1.0 GiB peak active memory in the reported short-context benchmark. 🏆 Retains most of the FP16 base model’s quality, with an average gap of just 2.8 points across five benchmarks. MMLU-Pro rises from 65.8 to 70.1. 🧠 SSD expert offload keeps most weights outside active memory, while a prerouter predicts which experts each layer will need next. 🛠 Recover-LoRA offsets quality loss from 4-bit quantization and expert offloading. The current Preview runs locally through MLX on Apple Silicon.
ModelScope16,923 просмотров • 1 месяц назад

An agent model, plus two multimodal models that can see and operate computers. Nex-AGI releases Nex-N2.5 in mini, Pro, and Max sizes.📜 Apache 2.0. 🤖 🏆 Max leads the published BrowseComp comparison with 92.6. Pro ranks first on OSWorld-G with 87.4. 🖥️ The 35B mini and 397B Pro browse the web, operate software, verify results, and self-correct through visual feedback. 🧠 The 1.6T Max targets complex text-based agent tasks, from coding and tool use to research and knowledge work. It marks Nex-AGI’s first full post-training run at trillion-parameter scale. ⚙️ All three support function calling and direct, adaptive, or full thinking modes.
ModelScope18,509 просмотров • 1 месяц назад

Breeze-TTS-2 is here. 🎙️ Real-time voice cloning, design, and direction in one model. 🤖 🏆 #1 open-weight TTS on Artificial Analysis, plus first place on voice design, instruction following, and latency benchmarks. 🎭 Clone a voice while preserving timbre, rhythm, emotion, and style, or design and direct new Chinese and English voices with natural-language prompts and inline vocal events. ⚡ Under 40 ms TTFA and 3.1× real-time streaming on the warmed-up fast path. Eager inference uses ~7.7 GiB, with a 12 GB GPU recommended. 📜 Code: Apache 2.0. Weights, derivatives, and self-hosted outputs: research and non-commercial use only.
ModelScope16,414 просмотров • 1 месяц назад

Listen, speak, handle interruptions, and call tools in one live conversation. 🎙️ Introducing NVIDIA-NemotronLabs-VoiceChat-11B, NVIDIA’s end-to-end full-duplex model for real-time voice agents. 🤖 🏆 It ranks #2 among open full-duplex models on both VoiceBench and Full-Duplex-Bench 1.0. ⚡ Natural turn-taking responds in ~448 ms, while barge-in lets users interrupt the model with ~480 ms latency. 🛠️ The first open full-duplex model with live tool calling. One unified system handles speech understanding, generation, transcription, and tool execution while keeping the conversation flowing. 🧠 Built with a Fast Conformer, Nemotron Nano v2, and a TTS decoder, trained on ~550K hours of real and synthetic speech. 📜 Research use only. OpenMDW 1.1.
ModelScope22,605 просмотров • 2 месяцев назад

MiniMax-Music3 is now open source. 🎶 Generate complete songs up to five minutes long, with expressive vocals, evolving arrangements, and coherent structure from intro to outro. 🤖 🧠 Around 11.1B parameters: an 8B Global LLM for long-range structure, a 0.6B Local LLM for acoustic detail, plus a 2.4B Flow Matching model and 123M decoder. 🎤 Control lyrics, song sections, genre, mood, vocals, instrumentation, and arrangement development. 🎧 Generates 32 kHz, 16-bit stereo WAV audio with stable long-form quality. Listen to the demos👇
ModelScope18,883 просмотров • 2 месяцев назад

YuE2-3B turns lyrics into complete songs through an editable musical score. 🤖 📄 🏆 YuE2 best-of-8 reaches 6.9632 SongBench Avg on WildSongBench, the highest score across the evaluated open and proprietary systems. Suno v5 scores 6.8721. 🎼 It plans melody and chords before generating vocals and accompaniment. Edit the score or supply your own ABC notation. 🎙️ The same checkpoint supports direct song generation, zero-shot covers, and agent-guided edits to the score, style, and lyrics. ⚡ Generate 48 kHz stereo audio locally on a 24GB GPU without quantization. 📜 Weights: CC BY-NC 4.0. Code: Apache 2.0.
ModelScope11,401 просмотров • 1 месяц назад

A real-time world simulator, now in 0.5B. ABot-World-0.5B-LF brings action-conditioned interactive rollout to ModelScope. 🎮License: Apache 2.0. 🤖 ⚡ Desktop-ready rollout: reported at 720p, 16 FPS, 1.2s latency, and 19GB GPU memory on a single-desktop setup. 🌍 Infinite interaction: responds to user actions continuously and keeps generating beyond fixed video-length limits. 🎬 LongForcing training helps the model expand new scenes and dynamics during rollout, without prompt switching or scene lock-in. 🛠️ Built on Wan2.2-TI2V-5B as a causal student model for lower-latency interactive world rollout.
ModelScope19,642 просмотров • 3 месяцев назад
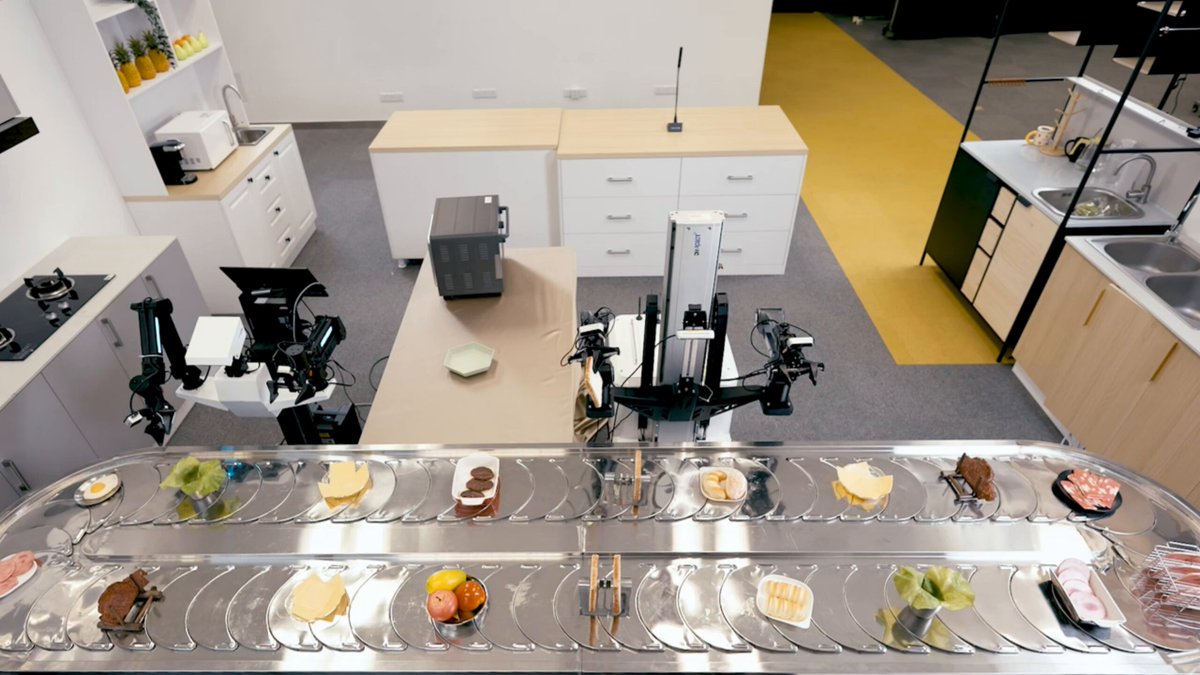
🤖 Introducing InternVLA-A1 — now fully open-sourced! Many VLA models follow instructions well in static scenes… but struggle in dynamic environments (conveyor belts, rotating platforms, multi-robot setups). Why? They see the present—but can’t imagine the future. InternVLA-A1 solution: unify perception, imagination, and action in one model: ✅ Scene understanding: Image + text → task parsing ✅ Task imagination: Predict future frames → reason about dynamics ✅ Guided control: Execute actions steered by visual foresight Powered by InternData-A1 - Large-scale high-quality simulated dataset, InternVLA-A1 stays robust under complex backgrounds, lighting, and distractions. 🔥 See it in action: 1️⃣ High-speed conveyor: track, predict, and stably grasp or flip packages 2️⃣ Rotating platform: task-aware recognition & precise pick-up of diverse items 📊 Outperforms π0 and Gr00t N1.5 on general manipulation benchmarks! ✨ Model, data, and code are all open! Models: Datasets: GitHub:
ModelScope38,118 просмотров • 9 месяцев назад
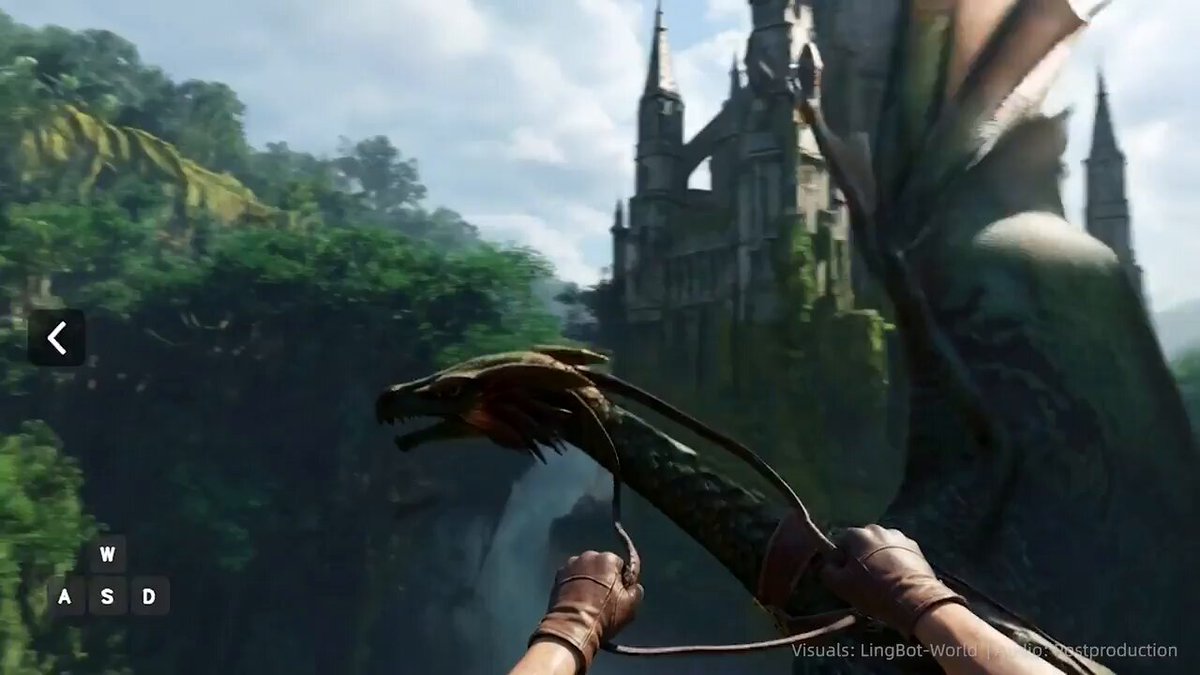
Introducing LingBot-World: An open-source world simulator pushing the boundaries of video generation. 🚀 🌍 High-Fidelity: Realistic, scientific, & stylized. 🧠 Long-Term Memory: Minute-level consistency. ⚡ Real-Time: <1s latency at 16 FPS. 📜 Apache 2.0 Licensed. Model: Github:
ModelScope28,809 просмотров • 8 месяцев назад

MOSS-TTS v1.5 is here, an upgrade to v1.0 from @OpenMOSS. (demo👇)🤖 Key improvements: ⏸️ Inline pause control: [pause 3.2s] now supported mid-sentence 🌍 31 languages, up from 20 — now includes Cantonese, Hindi, Thai, Vietnamese, Tagalog, Swahili and more 🎙️ More stable voice cloning with reduced variance across repeated generations 📝 Better long-reference, short-text cloning All v1.0 capabilities preserved: zero-shot cloning, long-form speech, Pinyin/IPA control, code-switching. 💻
ModelScope13,921 просмотров • 5 месяцев назад

🚀 New on ModelScope: MiniMax M2.1 is open-source! ✅ SOTA in 8+ languages (Rust, Go, Java, C++, TS, Kotlin, Obj-C, JS) ✅ Full-stack Web & mobile dev: Android/iOS, 3D visuals, vibe coding that actually ships ✅ Smarter, faster, 30% fewer tokens — with lightning mode (M2.1-lightning) for high-TPS workflows ✅ Top-tier on SWE-bench, VIBE, and custom coding/review benchmarks ✅ Works flawlessly in Cursor, Cline, Droid, BlackBox, and more It’s not just “better code” — it’s AI-native development, end to end. 🔗 Model:
ModelScope16,939 просмотров • 10 месяцев назад
Больше нет контента для загрузки