Загрузка видео...

Не удалось загрузить видео

На главную

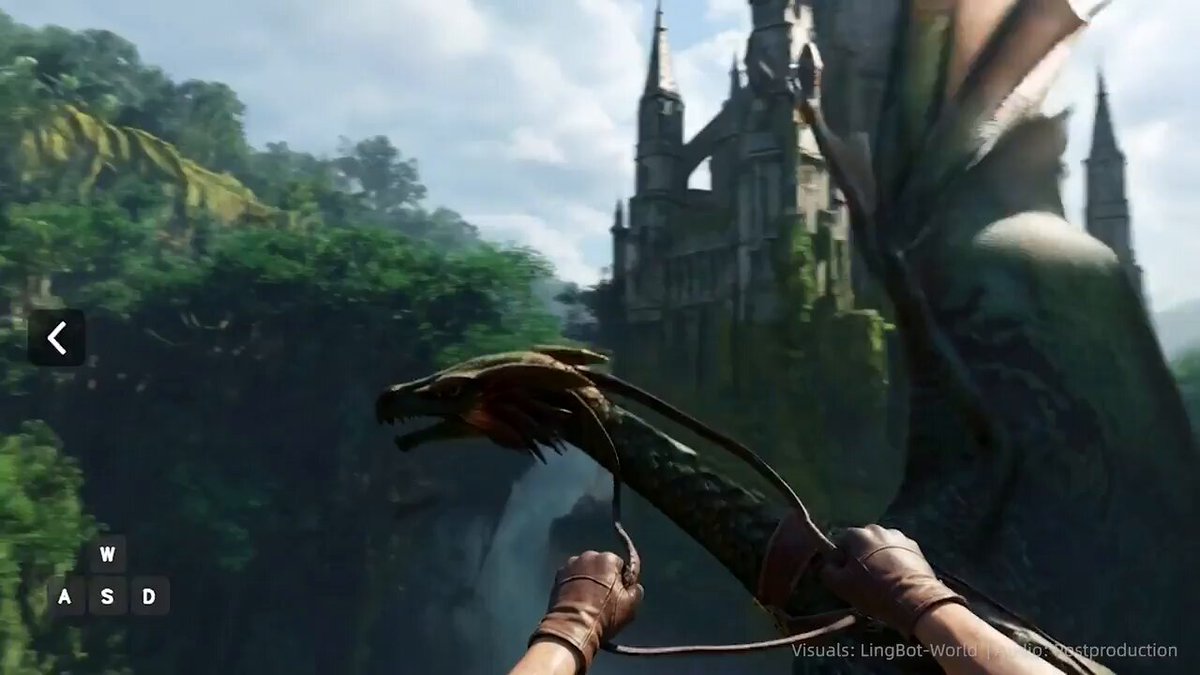
Meet LingBot-World 2.0.🌍A 1.3B world model, running continuous interactive generation in real time on a single consumer GPU. 🤖 ⚡ It responds to movement, camera control, combat, and text-driven events in real time, while the scene keeps unfolding instead of ending as a fixed video clip. 🌌 Causal pretraining...

33,630 просмотров • 1 месяц назад •via X (Twitter)

Комментарии: 1

Фото профиля GD
GD1 месяц назад

Super nice. What hardware is required to run this locally and performantly

Похожие видео

This World Model 'LingBot-World-Infinity (LingBot-World 2.0)' just released from Ant Group looks realy promising. It is an open causal world model with an Agentic harness. Most interactive world models hold together for a few minutes. Then textures smear and geometry warps. That's a video model, not a world — and Robbyant just drew the line at the attention mask. They released LingBot-World-Infinity (LingBot-World 2.0) — a 14B open causal video world model built on Wan2.2, trained with a Mixture of Bidirectional and Autoregressive (MoBA) attention mask, then distilled into a few-step real-time generator with no post-hoc drift filtering anywhere in the stack. Here's what's actually interesting: → Pure teacher forcing overfits — as context grows, the model leans on context instead of predicting frames. MoBA appends a bidirectional full-attention block as a regularizer → Leak-free cross-attention: AR rows attend to background prompt a_B plus chunk prompts a_≤i, lower-triangular. Bidirectional rows see one global prompt a_G → DMD runs over long self-rollout trajectories, not teacher-forced states — the student is optimized on the distribution its own errors induce → Director-Pilot harness: a VLM proposes event cards, the DiT generator renders physical dynamics. Mode B adds a SAM tracking loop for object-centric interaction → One 60-minute uninterrupted session, 20 distinct scenarios, no perceptible decay Full analysis: Paper: Model weight: GitHub Repo: Project: Ant Group Robbyant

Marktechpost AI

233,449 просмотров • 3 месяцев назад

Most AI world models can generate beautiful scenes. Keeping those scenes alive for an hour without falling apart is the real challenge. That's what caught my attention about LingBot-World 2.0 (LingBot-World-Infinity) from Robbyant Instead of chasing longer videos, it focuses on something much harder: persistent, interactive worlds that stay coherent while you explore. A few highlights: • Generates worlds from a single frame and continuously responds to live user actions through a causal world model. • Streams stable 720p at 60 FPS in real time. The team reports a continuous 60 minute stress test across 20 different scenarios with no noticeable visual degradation. • Uses a Brain-Cerebellum co-simulation framework where a VLM plans events while the video model turns them into consistent world evolution. • Pilot and Director Agents help drive character behavior and introduce new objects and events. • Open sourced with a 14B flagship model, while the paper also describes a lightweight 1.3B version for a single consumer GPU. There is also an online interactive demo. The biggest takeaway? We're moving beyond AI that generates clips. We're getting closer to AI that generates living, evolving worlds you can actually interact with. And that feels like a much bigger shift than another jump in video quality. Explore more: 💻 Github: 🤗 Weights: 🌐 Website-with videos you can use : 🎮 Try it online: #Robbyant #LingBot #WorldModel #EmbodiedAI #OpenSource #Robotics #ad

Alif Khan

84,566 просмотров • 3 месяцев назад