
Zhiyang (Frank) Dou
@frankzydou • 2,351 subscribers
PhD student @MIT_CSAIL. MPhil @HKUniversity. Ex-visiting @Penn. Dynamics Modeling, Physical AI, Robotics, Sim, Geometry, Control, AIGC. 🦋https://t.co/YpydZBLKs1
Shorts

Videos

Over the past few weeks, GPT-6 Astra, Claude Code with Opus 5.5, and other recent foundation models have surprised many of us in graphics, CAD, and robotics. They can now work directly with Blender, CAD kernels, game engines, physics simulators, and real robots very well. New examples appear almost daily, faster than the publication cycle can capture. 📝To keep track, we maintain a Living Survey of frontier AI for Design & 3D Modeling & Robotics: 🌐 Currently, it organizes 243 cases from 345+ public showcases and developer reports across 3D modeling, CAD and industrial design, animation, simulation, and robot control, each linked to its original source. (If you are working on related projects, it's better to check this out: ) Different from a traditional survey, three ideas guide it: 1. Horizon scanning beyond publication lag In an era where frontier foundation model capabilities evolve rapidly, traditional academic publishing cycles could lag behind public community developments and empirical findings. This platform establishes a centralized, high-velocity empirical synthesis repository to provide researchers and engineers with timely visibility into ongoing developments across 3D generation, parametric CAD, and embodied robotics—anchoring these observations in objective evaluations of strategic opportunities and critical safety boundaries. 2. Demonstrations as a distributed record of use We analyze the corpus of over 345 publicly documented showcases and developer reports as an extensive, distributed "crowdsourced user study." This framing captures how models operate when prompted across diverse geometry kernels (CGM, Open CASCADE), DCC software (Blender), physics simulators (Isaac Sim, MuJoCo, Genesis), and physical robot hardware—revealing real-world workflow friction, prompt overhead, and boundary failures that static benchmarks miss. 3. Ranking by open verifiability A central challenge is balancing the timely collection of rapidly emerging results with the need for high-quality, evidence-based evaluation. Our approach is to rank cases by open verifiability—the amount of evidence that others can directly inspect. Equally impressive demos can carry very different evidence, so every case is ranked by what others can inspect: - Rank 1 · Demo + Implementation Code: public code, scripts or CAD/robot harnesses (availability/verifiability) - Rank 2 · Demo + Interactive Web Link: a live web app, 3D viewer or cloud CAD project - Rank 3 · Demonstration Media Only: video or screenshots only Note: Rank 1 means the evidence is inspectable, not necessarily reproducible from a clean setup. Gallery: Contributions are very welcome via pull requests on GitHub. We especially welcome Rank 1 contributions (demos with code) and Rank 2 contributions (demos with interactive webpages). Many thanks to our collaborators: Jamison Meindl(Jamie Meindl), Akihisa Watanabe(Akihisa Watanabe ), Anna Deng, Tianyu Huang(Tianyu Huang), Igor Sadalski(Igor Sadalski ), Harrison Liang, Minghao Guo(Minghao Guo ), Benjamin Tod Jones, Wojciech Matusik(Wojciech Matusik ).
Zhiyang (Frank) Dou285,819 views • 27 days ago

Introducing ✨RigidFormer: Learning Rigid Dynamics with Transformers - our attempt to scale learning-based physical dynamics with Transformers. RigidFormer learns rigid dynamics with Transformers. It is a mesh-free, object-centric Transformer for multi-object rigid-body contact dynamics from point clouds. Learning physics with purely neural simulators, without relying on traditional physics engines, is an important and widely studied problem. Prior SOTA methods often use graph neural networks for accuracy and generalization, but still struggle with efficient, high-fidelity simulation at scale. RigidFormer uses only point inputs, matches or outperforms mesh-based baselines on standard benchmarks, runs much faster, generalizes across point resolutions and datasets, and scales to 200+ objects. We also show a preliminary extension to command-conditioned articulated bodies by treating body parts as interacting object-level components. RigidFormer is mesh-free: it does not require mesh connectivity, SDFs, or vertex-level message passing, making it well-suited for point-cloud observations and scalable simulation. This architecture can also be adapted to learn soft-body dynamics by replacing the rigid-body module (differentiable Kabsch alignment). 🎬See our video for more details. Many thanks to my amazing collaborators: Minghao Guo Minghao Guo, Haixu Wu Haixu Wu 吴海旭, Doug Roble, Tuur Stuyck Tuur Stuyck, and Wojciech Matusik Wojciech Matusik. Project page: Paper:
Zhiyang (Frank) Dou582,402 views • 5 months ago

Excited to share that our work NeuralActuator: Neural Actuation Modeling for Robot Dynamics and External Force Perception has been accepted to #RSS2026! Your robot — even a low-cost one — can feel external forces without torque or tactile sensors. TL;DR: NeuralActuator is a neural actuator model that jointly predicts 1️⃣torque to capture the nonlinear and time-varying current–to–torque relationship of low-cost servos, 2️⃣external contact forces (and force detection gates) for sensorless force perception, 3️⃣and motor conditions that indicate each motor’s operating regime. Here is a fast-forward video clip ⬇️ We are also covering more robots like LeRobot-S101 and Franka Panda. More details coming soon.
Zhiyang (Frank) Dou51,108 views • 5 months ago

I kept seeing #GPT-6 Astra modelling results on here and got curious enough to build the thing myself: an agentic pipeline that turns a plain RGB video into 3D assets. The living room for robots MIT CSAIL. Input: one handheld phone walkthrough of our lab kitchen (~20s). Nothing else — no depth sensor, no CAD, no asset library. ~1 day (I actually slept overnight), including human-in-the-loop. Live: It is still not perfect — thin and shiny things are still weak, a few objects are drafts, the room shell needs another pass. The loop, roughly: - Monocular video → metric scan (ViPE): camera poses + depth. This is the measuring instrument, not the output. - GPT-6 lists what should exist as separate objects, then open-vocabulary detection + tracking gives per-object masks; each object is fused and measured in metres. - For every asset, GPT-6 works in its own sandbox with tools: it writes the object as a program in a small Blender DSL (closed solids, PBR colours, hinges/drawers), builds it, renders it over the original video frames, compares it with the scan points in 3D, and iterates. - A separate GPT-6 session is the verifier — it can render the model on any frame it wants and must justify every complaint with a frame. The modeller never grades its own work. - A completeness pass renders the whole modelled scene from the video's own cameras, puts it next to the real frames, and says what's still missing. What the detector keeps missing (a row of identical cabinets) gets placed geometrically instead. - Out comes MJCF/URDF with joints. Now, adding simulation to this env.
Zhiyang (Frank) Dou11,508 views • 1 month ago

Excited to share that our paper 🌊🤺 “CFC: Simulating Character–Fluid Coupling using a Two-Level World Model” has been accepted to #SIGGRAPHASIA2025! In this work, we build a two-level world model (neural physics) for rigid-body–fluid interaction and use it to train physics-based character controllers efficiently. We study: (1) learning to model highly dynamic fluid environments, (2) representing character–fluid interaction via joint-level forces as an interface, and (3) enabling supervised policy learning on the learned world model—avoiding expensive fluid simulation in the training loop. Our talk is on Monday afternoon(Dec 15)—hope to see you there! Time: Monday, 15 December 2025 5:02pm - 5:13pm GMT+8 Location: Meeting Room S221, Level 2. #SIGGRAPHASIA #SIGGRAPH
Zhiyang (Frank) Dou20,247 views • 10 months ago
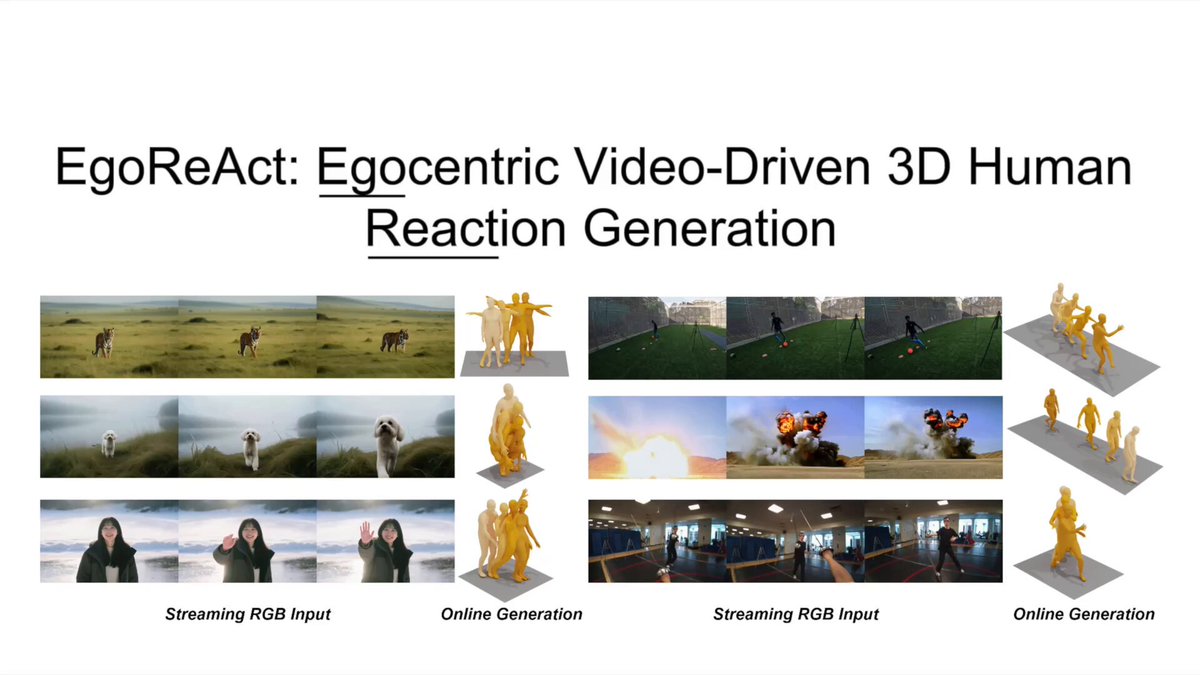
We present EgoReAct: Real-time 3D human reaction generation from streaming egocentric video. 🌟Reacting to streaming egocentric video is something humans do every day. We hope EgoReAct makes human motion more human-like. 🔎 What we found: existing ego-reaction data can be spatially inconsistent (e.g., moving reactions paired with fixed-camera videos), which breaks 3D grounding. 📷 What we built: HRD, a spatially aligned egocentric video–reaction dataset (3,500 pairs, 32 categories), plus a spatially aligned ViMo fix for fair evaluation. (Instead of collecting expensive ground-truth motion, we employ VDM to generate the egocentric videos.) 👁️⚡🏃 Our simple yet effective pipeline: motion tokenization for compact discrete codes + an autoregressive Transformer for online, strictly-causal generation. Metric depth and head dynamics further improve 3D spatial consistency. Project Page: ArXiv: #HumanMotion #EgocentricVision #3D #ARVR #Animation #AIGC #DeepLearning #GenerativeAI #Graphics #ComputerVision #Motion
Zhiyang (Frank) Dou11,427 views • 9 months ago

Excited to share our latest work on 🎧spatial audio-driven human motion generation. We aim to tackle a largely underexplored yet important problem of enabling virtual humans to move naturally in response to spatial audio—capturing not just what is heard, but also where the sound is coming from. To this end, we introduce the Spatial Audio-Driven Human Motion (SAM) dataset—the first comprehensive dataset featuring paired high-quality human motion and spatial audio recordings. For benchmarking, we develop a generative framework for human MOtion generation driven by SPAtial audio, termed MOSPA, which learns to synthesize realistic and diverse human motions conditioned on spatial audio input. We hope this research could provide a foundation for future research in spatial perception, virtual characters, and embodied AI. The dataset and model will be open-sourced soon. A big thank you to our intern, Shuyang Xu, for the wonderful collaboration! Congratulations, Shuyang! Project page: Paper: Video: #Animation #CG #CV #AIGC #DL #Deeplearning #Motion #Graphics #AI #GenerativeAI
Zhiyang (Frank) Dou14,728 views • 1 year ago

Got five papers accepted by #ECCV2024 European Conference on Computer Vision #ECCV2026 ! Huge thanks to all my collaborators! 😃 See you in Milan 🇮🇹 Summary of Selected Works (I made a fast-forward for them 😄) - [Shape Generation] Surf-D: Generating High-Quality Surfaces of Arbitrary Topologies Using Diffusion Models, ECCV 2024. - [Efficient Motion Generation] EMDM: Efficient Motion Diffusion Model for Fast, High-Quality Human Motion Generation, ECCV 2024. - [Controllable Motion Generation] TLControl: Trajectory and Language Control for Human Motion Synthesis, ECCV 2024. - [Avatar Generation] Disentangled Clothed Avatar Generation from Text Descriptions, ECCV 2024. Project Page: Surf-D: EMDM: TLControl: SOSMPL:
Zhiyang (Frank) Dou18,192 views • 2 years ago

Check out 🌟Vid2Sim: Generalizable, Video-based Reconstruction of Appearance, Geometry & Physics for Mesh-Free Simulation #CVPR2025, from Lingjie Liu’s lab at UPenn. Congrats to Chuhao Chen! Vid2Sim aims to achieve system identification by reconstructing geometry, appearance, and physical properties directly from video. It combines learned data priors with closed-loop optimization: a feed-forward predictor trained on physical prior, followed by fast refinement via Neural Jacobian and mesh-free simulation. The system delivers simulation-ready outputs in minutes, with strong generalization across objects and materials. 🏠Project page: #PhysicalAI #AIGC #CV #CG #simulation #graphics
Zhiyang (Frank) Dou12,441 views • 1 year ago
No more content to load