Загрузка видео...

Не удалось загрузить видео

На главную

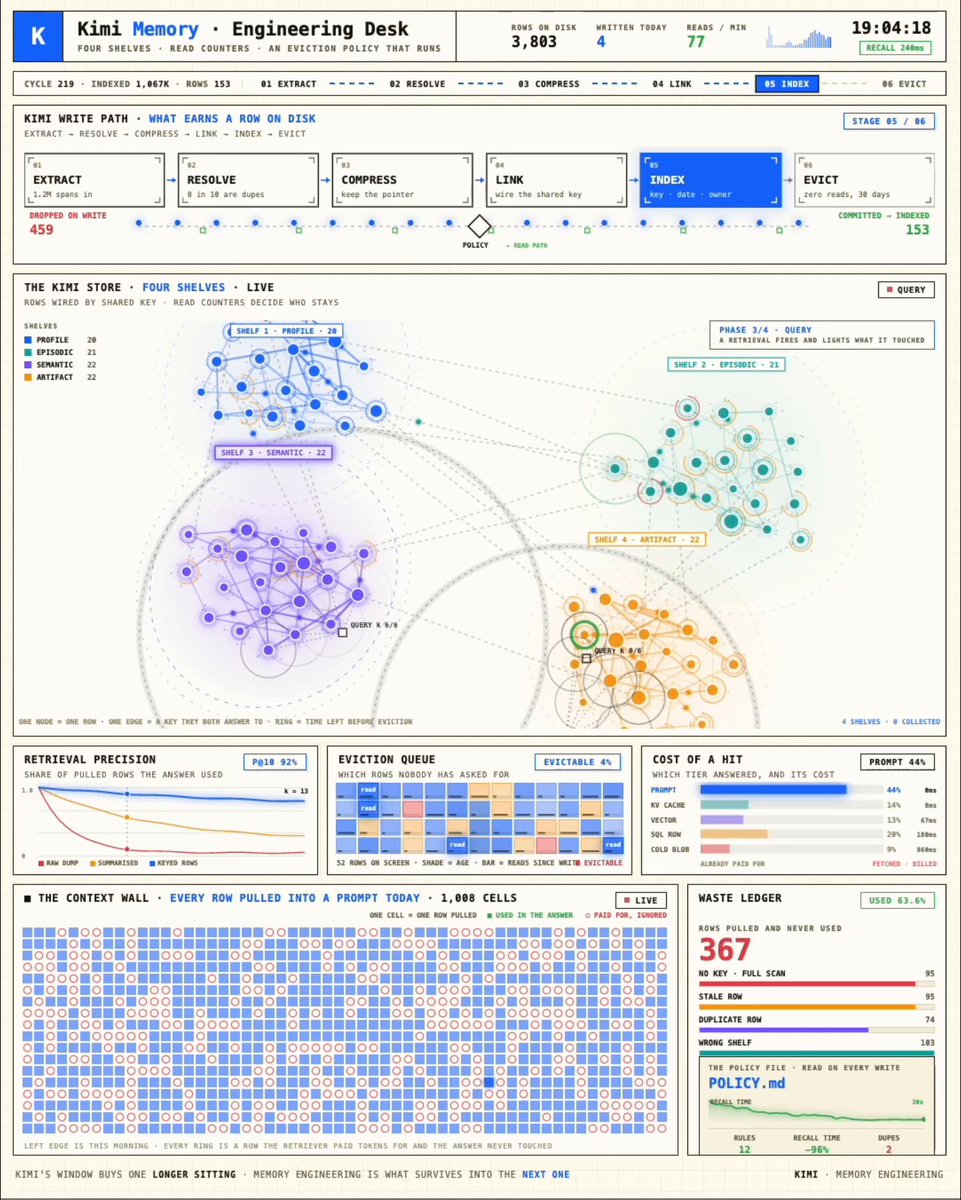
A FORMER GOOGLE LEAD BUILT A MEMORY SYSTEM THAT NEVER LOSES A SINGLE DETAIL Most agents forget everything the moment a session ends, starting from zero every single time. He built a scoring layer instead, one that decides what actually matters past this session and what gets dropped. Contradictions...

26,649 просмотров • 3 месяцев назад •via X (Twitter)

Комментарии: 0

Нет доступных комментариев

Здесь появятся комментарии из оригинального поста

Похожие видео

Engineer runs a Kimi K3 memory layer that costs $11 a month and remembers what a $500,000 vector database keeps losing. No embeddings. Four nodes and one rule about what's allowed to be forgotten. He published the whole schema. His version starts from the opposite idea. Memory is not a pile you search. It's a set of claims that expire unless something keeps paying to keep them. Four nodes. Every memory carries a clock someone has to reset: > WRITER - stores a fact with the reason it mattered, never raw text > DECAY - ages every memory down. Silence is deletion > RENEWER - only re-lifts a memory the model actually used again > GRAVE - holds what died, and why nobody reached for it Three nodes keep memory alive. One keeps the dead ones. Recall isn't storage here. It's rent a fact has to keep earning. That's the entire design. When everything is remembered forever, the useful and the stale retrieve identically. He replayed two months of agent context. 90,000 stored facts. 71,000 never retrieved once. The vector store returned all of them on similarity. Similarity graded closeness. Nobody graded whether the memory was ever right. Everyone else stuffs more into the context window and calls it memory. He built a layer that lets a fact die unless it keeps proving itself. The cost isn't storage. It's finding out how much of what your agent "knows" it has never once used. The article below is the full build - node prompts, the decay curve, the renewal rule. Save it. You'll want it open in the other tab.

wast3

67,952 просмотров • 2 месяцев назад

New short course: LLMs as Operating Systems: Agent Memory, created with Letta, and taught by its founders Charles Packer and Sarah Wooders. An LLM's input context window has limited space. Using a longer input context also costs more and results in slower processing. So, managing what's stored in this context window is important. In the innovative paper MemGPT: Towards LLMs as Operating Systems, its authors (which include the instructors) proposed using an LLM agent to manage this context window. Their system uses a large persistent memory that stores everything that could be included in the input context, and an agent decides what is actually included. Take the example of building a chatbot that needs to remember what's been said earlier in a conversation (perhaps over many days of interaction with a user). As the conversation's length grows, the memory management agent will move information from the input context to a persistent searchable database; summarize information to keep relevant facts in the input context; and restore relevant conversation elements from further back in time. This allows a chatbot to keep what's currently most relevant in its input context memory to generate the next response. When I read the original MemGPT paper, I thought it was an innovative technique for handling memory for LLMs. The open-source Letta framework, which we'll use in this course, makes MemGPT easy to implement. It adds memory to your LLM agents and gives them transparent long-term memory. In detail, you’ll learn: - How to build an agent that can edit its own limited input context memory, using tools and multi-step reasoning - What is a memory hierarchy (an idea from computer operating systems, which use a cache to speed up memory access), and how these ideas apply to managing the LLM input context (where the input context window is a "cache" storing the most relevant information; and an agent decides what to move in and out of this to/from a larger persistent storage system) - How to implement multi-agent collaboration by letting different agents share blocks of memory This course will give you a sophisticated understanding of memory management for LLMs, which is important for chatbots having long conversations, and for complex agentic workflows. Please sign up here!

Andrew Ng

201,127 просмотров • 2 лет назад

Spent the last week building something for the OKX AI Genesis Hackathon. The more I worked with AI agents, the more one problem kept bothering me. Every agent feels smart... until you restart it. Crash the process. Redeploy it. Move it to another machine. Everything it "learned" is gone. Not because the model forgot. Because its memory was never built to survive. And even if an agent says it remembers something... How do you know it's telling the truth? Today's agents usually keep memory in a vector database, a Postgres instance, or someone else's hosted service. If that database disappears, gets edited, or the company shuts down, there's no way to prove what the agent actually knew. That feels like a much bigger problem than people realize. As more agents start working with other agents, history needs to become something they can actually trust. So I built CORTEX. A permanent memory layer for AI agents. Instead of treating memory like temporary application state, Cortex treats every memory as something worth preserving. Once an agent writes a memory, it shouldn't matter whether my server stays online. It shouldn't matter if the process dies. It shouldn't even matter if Cortex disappears one day. The memory should still exist. Here's how every write works. The actual memory is stored permanently on Arweave Ecosystem. A cryptographic hash is anchored on X Layer mainnet so anyone can verify it hasn't been changed. Redis is used as a fast index so recalls are instant. The permanent storage isn't Redis. It isn't my API. It's the decentralized layer underneath. One of my favorite tests was the simplest one. I wrote a memory. Killed the server completely. Started everything again from a clean process. Asked the agent to recall what it knew. It pulled the same memory back. The hash still matched. The proof still verified. Exactly the behavior I wanted. That architecture is important. Arweave stores the content forever. X Layer proves exactly what was written and when. Redis makes retrieval fast. - Lose Redis? - you Still recover. - Restart the backend? - you Still recover. Even if Cortex itself disappeared, the underlying memories would still exist and still be verifiable. That's what "permanent" should actually mean. I also wanted it to be easy for developers. No custom SDK. No framework lock-in. Agents connect over MCP. Right now there are four tools: • write memory • recall memory • query memories • generate memory digests that compress old context without deleting the original history Works whether you're building with LangGraph, custom agents, or anything else that can speak MCP. The service is already listed on the marketplace(under review) Free to discover and connect. You only pay when an agent actually executes a tool. Payments happen on-chain through x402, so usage is metered exactly when work is done. I think permanent memory becomes much more important as the agent economy grows. If agents are going to make financial decisions, negotiate with each other, or build long-term relationships, they need more than context windows. They need history. And they need history that survives restarts and can be independently verified. That's what Cortex is trying to solve. Built for #okxai using Arweave + X Layer.

𝒴ℯ𝓂𝒾 ❄︎

26,301 просмотров • 4 месяцев назад

context engineering vs graph engineering. every few months the list gets a new word and everyone treats it as a replacement for the last one. these two are not on the same list. one decides what the model sees this turn, the other decides what exists at all. the cleanest way to tell them apart is to ask what a single unit of work looks like. > context engineering is the window the window opens empty, every single time. you assemble what goes in it. the prompt, the docs, the history, the tool results. the assembling is the work. the window only grows. it never shrinks on its own, so eventually something gets dropped. usually from the middle. usually without telling you. then the turn ends and the window is thrown away. not archived, thrown away. the next turn opens empty again and you re-explain what you already explained. good context engineering is knowing what to leave out, not what to pack in. the unit of work is one window. > graph engineering is the structure the same material arrives from the same sources. instead of packing it into a window, you pull entities out of it, resolve the duplicates into one node, and write typed edges between them. nothing here is stored as text you hope to find again. it is stored as a thing with a name and its connections to other things. when the turn ends, the graph is still there. the next turn does not start from zero. it starts by querying what already exists, and the query walks edges instead of guessing at similarity. good graph engineering is deciding what counts as the same thing twice. the unit of work is one relationship. > they are not alternatives the graph is what refills the window. context engineering decides what fits. graph engineering decides what there is to choose from. remove the graph and every session starts blind. remove the context work and the best structure in the world arrives as an unreadable dump. that also tells you which one broke. the answer drifted from what you actually said, or forgot something from this same session. that is the window. the answer is coherent but invents a connection that does not exist, or cannot join two facts it has clearly seen. that is the structure. people debug the prompt because the prompt is the easiest thing to edit. it keeps taking the blame for failures that live a layer down. save this - then read the full breakdown below

Hanako

19,160 просмотров • 3 месяцев назад