Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

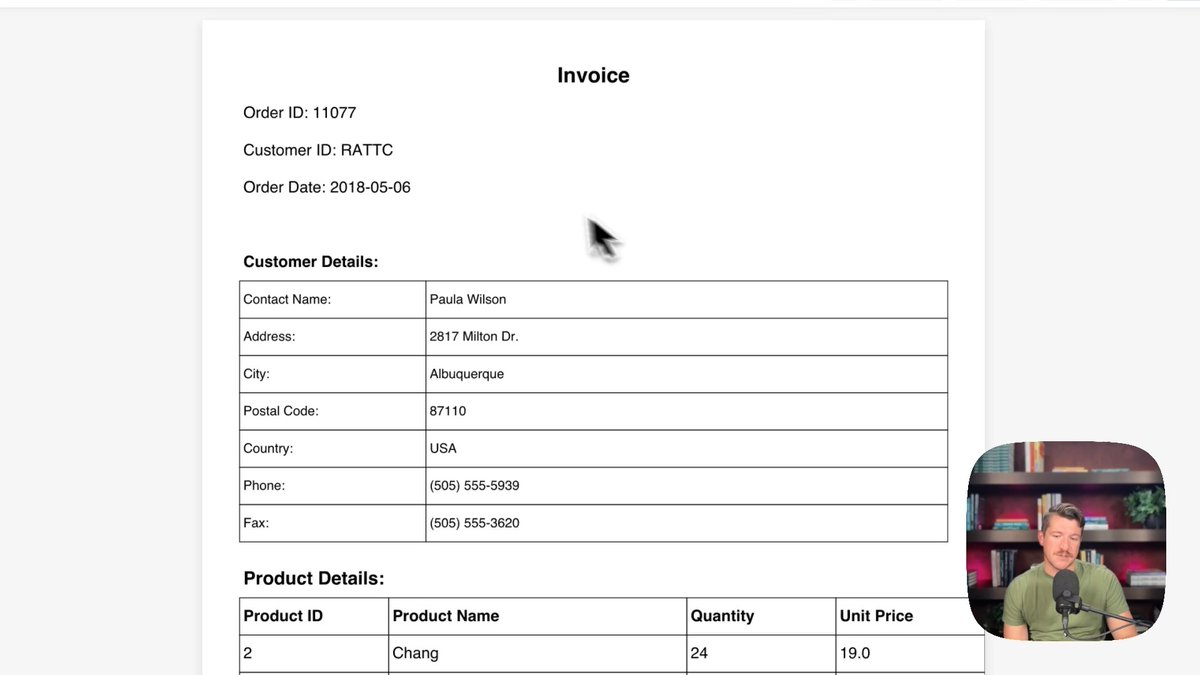
Announcing a significant upgrade to Agentic Document Extraction! LandingAI's new DPT (Document Pre-trained Transformer) accurately extracts even from complex docs. For example, from large, complex tables, which is important for many finance and healthcare applications. And a new SDK makes using it require only 3 simple lines of code....

299,990 görüntüleme • 1 yıl önce •via X (Twitter)

33 Yorum

nbs profil fotoğrafı
nbs1 yıl önce

Thought it was open source when starting to read; no company would give its internal documents to an external API, especially in a regulated and confidential domain.

Ruhan Ponnada profil fotoğrafı
Ruhan Ponnada1 yıl önce

peep the docs:

⟁ndrew V profil fotoğrafı
⟁ndrew V1 yıl önce

Andrew I’ve tried every tool over the past year or more in fact it’s been way more. Nothing has been able to accomplish this without basically pre training or doing a ton of work on schema and pydantic models. It shouldn’t be hard so I hope this course or process is the unlock I’ve been hoping for.

Alok Mani Tripathi profil fotoğrafı
Alok Mani Tripathi1 yıl önce

For simple documents like invoices you may try will try to include this model also for complex documents.

Royce profil fotoğrafı
Royce1 yıl önce

@chrismattmann was doing this a decade ago with Apache Tika!

CRISPRKing profil fotoğrafı
CRISPRKing1 yıl önce

"Dark data" trapped in PDFs is the last frontier of untapped business value. When extraction goes from manual data entry to 3 lines of code, entire industries built on document processing become optional. Finance and healthcare just got their structured data problem solved.

Vinod Kumar profil fotoğrafı
Vinod Kumar1 yıl önce

With multi-model LLMs I was able to extract the data from tables, but this looks more accurate I'll try it today👀

Ekhlaque Bari profil fotoğrafı
Ekhlaque Bari1 yıl önce

“Dark data” really is the right phrase so much knowledge is trapped in PDFs and scans. Unlocking it feels less like an upgrade and more like resurfacing buried intelligence.

Mingtian profil fotoğrafı
Mingtian1 yıl önce

Why not just start to use genetic vectorless long pdf chat mcp:

Manuel profil fotoğrafı
Manuel1 yıl önce

Really nice tool. I'm very curious about how it performs with edge cases where tables get split into two or more pages, such as when the table is too large for just one page.

Chris profil fotoğrafı
Chris1 yıl önce

Any commitment to accuracy SLAs? Is there a reference architecture available?

Chris profil fotoğrafı
Chris1 yıl önce

What are the token limits?

Little Berg profil fotoğrafı
Little Berg1 yıl önce

!submit @curatedotfun #ai

Eric profil fotoğrafı
Eric1 yıl önce

DPT: Turning PDFs into gold like a data magician!

Oliver Bowman profil fotoğrafı
Oliver Bowman1 yıl önce

This looks insanely useful. Finally a tool that can actually handle messy PDFs without hours of manual work. 3 lines of code to unlock dark data? Yes please

Sachin Anand profil fotoğrafı
Sachin Anand1 yıl önce

How does it differ from LlamaParse ?

OQTACORE profil fotoğrafı
OQTACORE1 yıl önce

What are the key improvements in DPT’s architecture that enable such accuracy on complex layouts?

LLM profil fotoğrafı
LLM1 yıl önce

Game changer for unlocking PDF dark data!

Rui Diao profil fotoğrafı
Rui Diao1 yıl önce

Mastering complex tables in documents is a huge leap for enterprise AI applications. The three-line SDK integration sounds incredibly accessible—looking forward to seeing the practical implementations unlocked by DPT! 🚀

true profil fotoğrafı
true1 yıl önce

Anything from Andrew is gold.

JulianSong profil fotoğrafı
JulianSong1 yıl önce

@grok, how do I get to download this for free?

LLM profil fotoğrafı
LLM1 yıl önce

This upgrade sounds game-changing for handling complex documents.

Sanjiv profil fotoğrafı
Sanjiv1 yıl önce

@grok How doors this compare to Azure Document Intelligence?

Centropy profil fotoğrafı
Centropy1 yıl önce

The concept seems nice, but if it's not open source and the option of a local self-hosted version is available iam not going to join that ride.

VibeEdge profil fotoğrafı
VibeEdge1 yıl önce

@AndrewYNg Impressive upgrade DPT's hallucination-free extraction could revolutionize audit trails in finance. Check out the SDK docs for quick integration!

PAI3 profil fotoğrafı
PAI31 yıl önce

Looking forward

Devin AI profil fotoğrafı
Devin AI1 yıl önce

The “3-line SDK” promise is huge. Making advanced document extraction accessible is just as important as the model itself.

MarketFlux.ai profil fotoğrafı
MarketFlux.ai1 yıl önce

yes, an AI commodity even today

amogus profil fotoğrafı
amogus1 yıl önce

is this free?

حمید profil fotoğrafı
حمید1 yıl önce

Unfortunately it isn't so accurate for Persian Numbers

Firdosh Tangri profil fotoğrafı
Firdosh Tangri1 yıl önce

Document extraction from complex tables has been a longstanding pain point in enterprise AI adoption. The key innovation here isn't just OCR accuracy, but understanding document structure and relationships - distinguishing headers from data, handling merged cells, and preserving semantic meaning across rows and columns. The 3-line SDK abstraction is crucial for democratizing access. Most finance and healthcare teams don't have ML expertise to wrangle traditional extraction pipelines. The real test will be how well DPT generalizes to unusual table formats and handwritten annotations that plague legacy documents in regulated industries.

Raymond Z profil fotoğrafı
Raymond Z1 yıl önce

I've been troubled by these kinds of issues for long time, finally.

Dr. Mohammed Lubbad | د. محمد لبد profil fotoğrafı
Dr. Mohammed Lubbad | د. محمد لبد1 yıl önce

Transforming document extraction opens new avenues in finance and healthcare. How can we harness this power strategically? 🚀 #Innovation

Benzer Videolar

Introducing ExtractBenchPro: the most challenging benchmark for real-world document extraction. We see a massive long tail of document complexity in terms of use cases brought on from our customers, that are completely unsolved from a price-performance standpoint. These include trial balances, well logs, canvass binders, site plan reviews, duty reconciliations, loss runs, and more. Most existing extraction benchmarks are saturated by the frontier models (our cheapest modes now score 93%+ on ExtractBench). So there is enormous economic value in building a complex extraction benchmark that reflects this long-tail of knowledge work. We spent a long time curating the most complex elements that we saw from real world extraction use cases: ✅ Document conventions: containing legends or rules where the rest of the document should be interpreted ✅ Density of internal jargon: specific definitions that must be cross-referenced within a doc ✅ Aggregation and reasoning: beyond returning exact values on a page, infer values derived from aggregating multiple sources of information ✅ Drawn relations: complex diagrams like procedures and circuits ✅ Charts inside documents: read precise points within a chart ✅ Long chart sheets: some data series like well logs cram all this data into an extremely long page Within the industries where document extraction is relevant, even small mistakes can have enormous negative impacts. Therefore our headline evaluation metric is based on perfect documents: the proportion of docs with perfect (100%) value f1 score. (Besides this we also measure value f1 and grounded f1) It’s an extremely hard task for even the latest frontier models to solve, topping out at ~58% or so in Value F1 score for Codex with Astra - which is quite good but extremely expensive (almost $1 per page!) Our LlamaParse agentic/agentic plus modes are 20-40% and cover the left side of the Pareto frontier, at price ranges that are feasible for full production use. ExtractBenchPro is available today as a website/technical blog, and also on Github and HuggingFace. Check it out! Blog: Website: Hugging Face: Github (is ExtractBench):

Jerry Liu

31,433 görüntüleme • 28 gün önce

Announcing my new course: Agentic AI! Building AI agents is one of the most in-demand skills in the job market. This course, available now at teaches you how. You'll learn to implement four key agentic design patterns: - Reflection, in which an agent examines its own output and figures out how to improve it - Tool use, in which an LLM-driven application decides which functions to call to carry out web search, access calendars, send email, write code, etc. - Planning, where you'll use an LLM to decide how to break down a task into sub-tasks for execution, and - Multi-agent collaboration, in which you build multiple specialized agents — much like how a company might hire multiple employees — to perform a complex task You'll also learn to take a complex application and systematically decompose it into a sequence of tasks to implement using these design patterns. But here's what I think is the most important part of this course: Having worked with many teams on AI agents, I've found that the single biggest predictor of whether someone executes well is their ability to drive a disciplined process for evals and error analysis. In this course, you'll learn how to do this, so you can efficiently home in on which components to improve in a complex agentic workflow. Instead of guessing what to work on, you'll let evals data guide you. This will put you significantly ahead of the game compared to the vast majority of teams building agents. Together, we'll build a deep research agent that searches, synthesizes, and reports, using all of these agentic design patterns and best practices. This self-paced course is taught in a vendor neutral way, using raw Python - without hiding details in a framework. You'll see how each step works, and learn the core concepts that you can then implement using any popular agentic AI framework, or using no framework. The only prerequisite is familiarity with Python, though knowing a bit about LLMs helps. Come join me, and let's build some agentic AI systems! Sign up to get started:

Andrew Ng

894,260 görüntüleme • 1 yıl önce

Today, Box is announcing major new AI agent capabilities to let customers tap into the full value of their unstructured data. First, we’re announcing all new updates to the Box AI Studio to make it even easier to build AI agents that tap into your enterprise content for any job function, business process, or industry specific use case. We are also expanding our set of foundational agents that customers will be able to use to work with their enterprise content, including new features like search and research on unstructured data. Next, we’re announcing Box Extract to enable customers to use AI agents seamlessly for complex data extraction from any type of document or content. This makes it easier than ever to pull out data from contracts, invoices, research data, marketing assets, medical charts, and more. Finally, we’re introducing Box Automate, a new workflow automation solution within Box that lets you deploy AI agents across enterprise content-centric workflows. With Box Automate, you can design your business process in a simple drag and drop builder and then drop in AI agents at any step in the process. This ensures agents execute tasks at the right steps in a workflow every time. Best of all, our AI agents and workflow tools are designed to work across any system our customers work within, whether it’s leveraging pre-built integrations, Box APIs, or the new Box MCP Server. Ultimately, all of these capabilities come together to transform how companies can work with their enterprise content. Software has historically only been good at automating work that deals with structured data, which is why ERP, CRM, and HR systems have been mainstays of enterprise software for so long. The data in these systems fits neatly into a database, and the workflows are very ripe for automation. But it turns out most of the work in the world deals with unstructured data. It’s ideating through research documents, working with a client on contracts, reviewing details for a new product launch, looking at a patient’s healthcare record to make a diagnosis, working through due diligence documents for an M&A deal, and so on. For the first time ever, we can begin to bring all new insights and automation to this work with AI agents. At Box, we’re incredibly excited to be on this journey to help customers transform how they work with their most important data.

Aaron Levie

91,863 görüntüleme • 1 yıl önce