Loading video...
Video Failed to Load
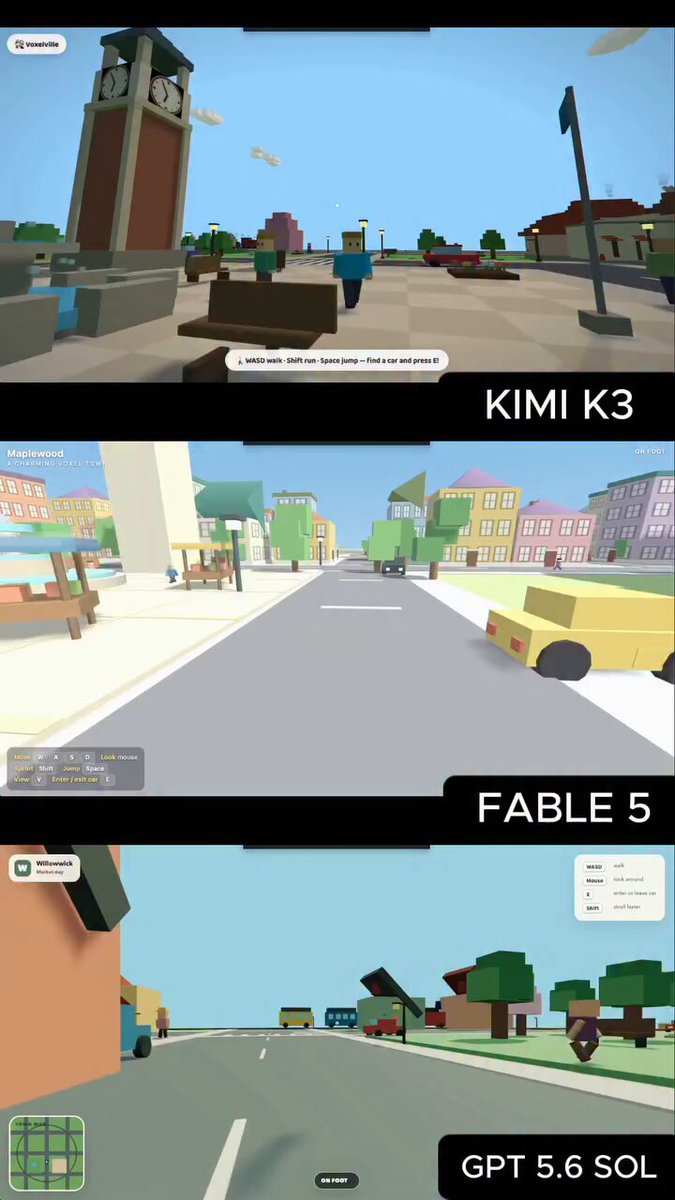
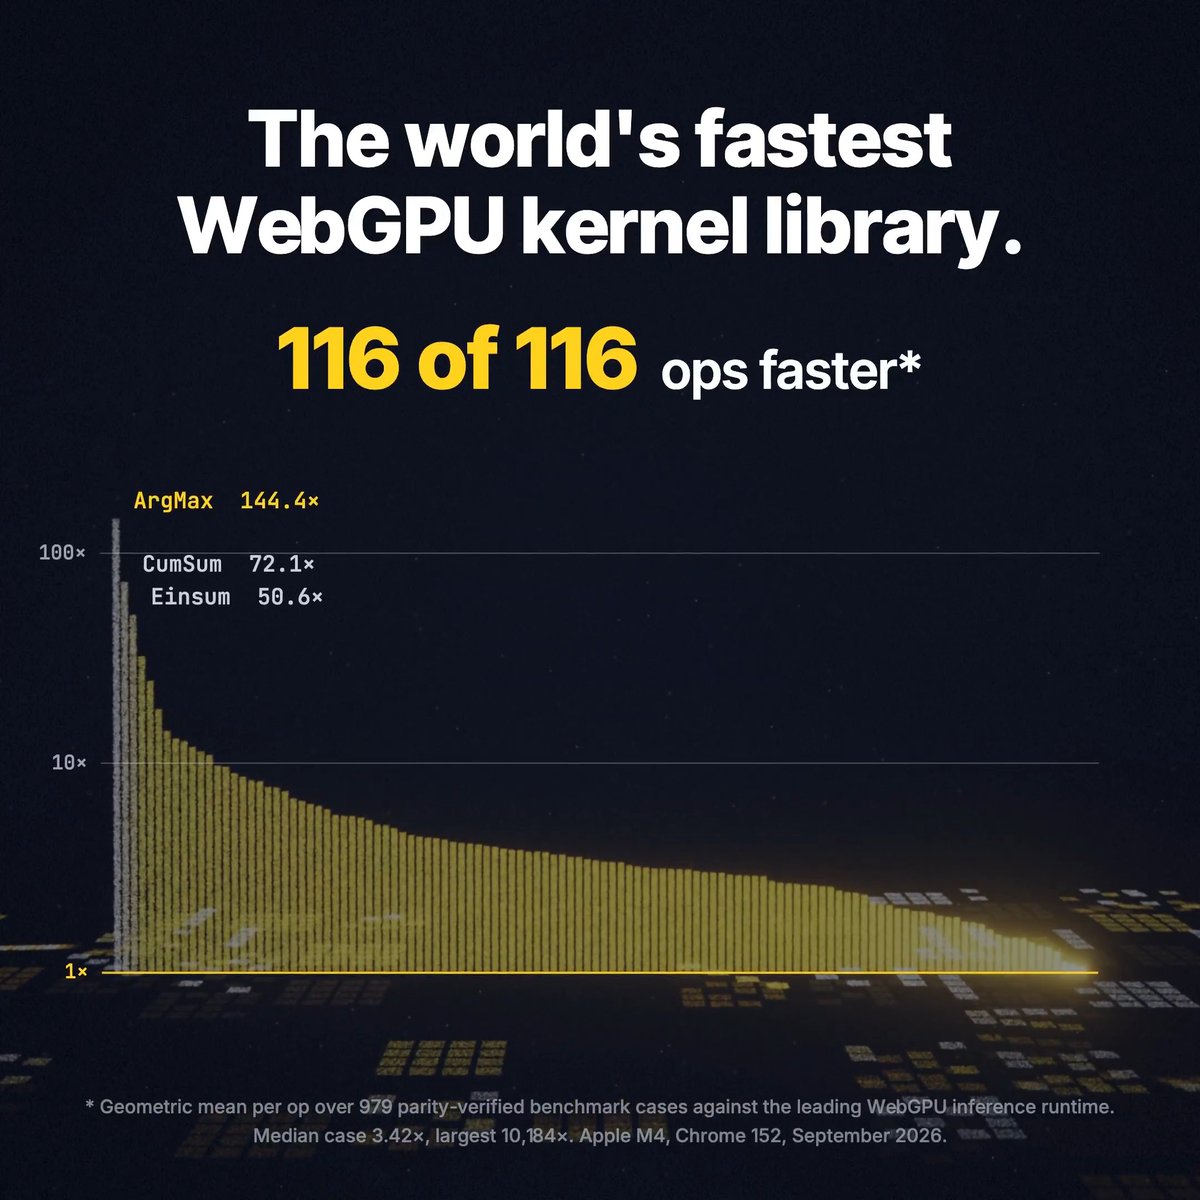
Bonsai 27B just changed the local LLM game forever. 1-bit quantization shrinks it from 54GB to just 3.8GB (-93%), while retaining 90% of its intelligence. That's insane. With custom WebGPU kernels written by Fable 5 and GPT 5.6 Sol, the model now runs locally in your browser!

211,255 views • 3 months ago •via X (Twitter)
35 Comments

Huge congrats to the @PrismML team on the release! 🤗 Collection on Hugging Face: 🔗 Link to demo:

Do you think there's any way to shrink Gemma 4 30B this far? It would be really cool because Gemma 4 has a lot of multilingual knowledge, and its tool calling works pretty well (even Cerebras hosting it)

@grok explain this to me like I'm retarded

Not working on my Chrome (and Edge).. Running the latest version, the latest drivers and having a 12GB card attached with hardware-accileration enabled. LFM and Gemma Kernals WebGPU worked fine.
Thanks for reporting the issue: it should be fixed now! 🙏 Could you try again?

Failed the carwash test for me, but love where this is going!

All you people with your "my 1-bit is super smart" BS. Amazing how popular it has become. No 1-bit model is useful for anything serious. Having a conversation with it? Sure, you could do that, and it would still appear smarter than the vast majority of people.

so you're just openly doing witchcraft now? jokes aside, this is actually insane. congrats and thank you!

1-bit quantization actually holding 90% intelligence is the part I'd want to stress test myself, on paper this always sounds better than it plays out on weird prompts. but browser WebGPU inference at 3.8GB is genuinely a distribution unlock, that's phone-runnable

Great in theory, but in practice not really useful yet.

larp larp larp sahur has a 4000 token context window

bro, this is absolutely wild. just one thing though, after copy-pasting your post to convince it that it was running in my browser, it wouldn't stop "to clarify" and entered a loop. I had to stop it manually. However, this is revolutionary for many applications and will allow many use-cases by moving compute to the edge. Please support fully in transformer.js and co.

Amazing work from @PrismML if the numbers hold up. This will unlock so much more devices to higher end/better models.

It's BS. It's a Qwen Model behind. The real 1 bit approach is Microsofts Bitnet. Train a model from scratch in 1.58 bit. Not quantity it to hell.

We've built an edge-device network to serve models just like this! Stay-tuned.

1 bit models are not usable

the model-written kernels are the wild part imo. 1-bit matmuls are fiddly enough that nobody hand-tunes them per gpu family. curious what '90% of intelligence' means at the eval level tho, quant usually eats long-context reasoning first

The open source path is so different. Model in hand, optimize yourself, run anywhere. That's fundamentally different value prop than token APIs.

WebGPU acceleration keeps proving browsers are becoming legit AI runtime platforms.

It's the missing 10% that really counts

Pied piper levels of compression. I ran this model with 8gb of VRAM. WOW... insanely smooth, there is huge interest for local AI, and this proves it'll be widely adopted considering current consumer hardware configs.

Is the new Fable 5 still on form for new kernel gen?

Wen GLM 5.2...?

浏览器本地跑27B这就有点离谱了

very cool ... but ...

@huggingface Loving the landing pages for the webgpu demos

Quantization means precisely that it loses precision, so the claim of retaining 90% is highly questionable at best.

@tcarambat I expect a video on this .. expeditiously

This matters beyond LLMs.🌏 Embodied AI will eventually need models that can run under strict memory and power constraints. Efficient inference is becoming a robotics problem too.

Binary weights being at all functional is genuinely insane.

Anthropic and OpenAI are so cooked. When this quant becomes common for local models, there will be so much less of a reason to use providers.

pokaż mi czy działa z codex i claude powiedz jak skonfigurować

1bit sounds highly unusable 🤔, hope I'm wrong

This is the real local-AI breakthrough: powerful models becoming small enough to run privately on everyday hardware.

Matter of time before we get this through UI hiccups