Loading video...

Video Failed to Load

Go Home

Delete all your E2E tests, seriously Okay, not the coverage, the code I’ve written Playwright tests, they’re great Maintaining hundreds of browser scripts while the UI keeps changing is not so much Honestly, AI feels more naturally suited to this than half the coding use cases we keep forcing...

90,340 views • 1 month ago •via X (Twitter)

23 Comments

Éverton Toffanetto's profile picture
Éverton Toffanetto1 month ago

Tests are written as scripts because they need to be deterministic. Using AI introduces a variable you don’t fully control. I see them as complementary approaches, not as one replacing the other.

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

The control part is the part that you need to weight, since full control comes with a cost as well. If you don't want to pay by hour for developers to maintain tests but want to have a regression testing path. It's an easy way to get it done without even thinking much about it :)

Kevin Möchel's profile picture
Kevin Möchel1 month ago

Have the AI write playwright tests Run them on a schedule If failed, have an agent fix them Run tests for free instead of a paid sub

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

You could do that but it's still not free, takes your time, validation and you have to physically be responsible for them It's a decision between your own time or just having it handled by a third party where all you maintain are written user stories

AI Apps API's profile picture
AI Apps API1 month ago

The maintenance cost is real and it comes from the same place every time, selectors encode layout instead of intent. A test that says click the button labeled Save survives a redesign, one pinned to a generated class name does not. Agents help most when the step is described that way, and the flaky part left over is usually waiting, asserting on state that has actually settled rather than a fixed timeout.

Paweł Kubiak 🅰️'s profile picture
Paweł Kubiak 🅰️1 month ago

Ok, but what about costs? I assume that TesterArmy agent can interact with website by sending screenshot/html/a11y tree to LLM to identify crucial elements to interact with. If so, then it is expensive in terms of costs. In that case I would keep e2e tests.

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

From what I understand from docs it's mostly based on visuals and it charges you per run with a monthly subscription With regular E2E it all depends how much maintenance you have around them. If you have an app that doesn't change that much, you don't feel the pain. In fast paced env tools like TesterArmy remove the burden of updating tests and adding new is super simple Gonna dig around how actual internals work other than screenshots :)

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

I actually found out they’re not relying on vision by default. They use accessibility APIs first (DOM on the web, native APIs on mobile), and only fall back to vision when needed since it’s much slower and more expensive However you are paying per run so they need to care about the tokens not you :)

AI Alpha By Mario's profile picture
AI Alpha By Mario1 month ago

The maintenance burden is the real killer — AI handling intent while the UI changes underneath feels like the right split

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

So far I had a really good and consistent results :)

AI Mastery Guide's profile picture
AI Mastery Guide1 month ago

Plain English tests instead of babysitting selectors sounds so much easier.

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

Indeed! it's much more convenient not to think about all the selectors and code around them when you don't have to :)

AI Mastery Guide's profile picture
AI Mastery Guide1 month ago

Less brittle scripts, more time actually shipping features.

Pavan K Jadda's profile picture
Pavan K Jadda1 month ago

Looks interesting

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

Give it a try :)

Shahar Nechmad's profile picture
Shahar Nechmad1 month ago

Agree. Maintaining selectors is probably one of the worst parts of E2E tests. These days, agents are smart enough, and computer use has become so much better. Check out also what Cloudflare is doing. They released a lot of infra in the past two weeks, to build this at scale.

incpo's profile picture
incpo1 month ago

at leats playwright is free

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

yes it is, but your time is not :) Gotta decide what is worth more

Vivek Nayyar's profile picture
Vivek Nayyar1 month ago

The issue is the latency and cost plus unpredictability. Will the model always find the right button to click and test 😅

Daniel Glejzner's profile picture
Daniel Glejzner1 month ago

Give it a try :) it comes with a free trial, cost is per run - pretty convenient as well. In my experience it does a pretty damn good job at clicking the right things. Not sure about the latency? What's the issue there?

Vivek Nayyar's profile picture
Vivek Nayyar1 month ago

Take screenshot, call llm to find the right element and then simulate click - this would have higher latency than a data test id click

fudes's profile picture
fudes1 month ago

Quoting a VC as an authority on building is like quoting a food critic as an authority on cooking.

Mitchell Agoma's profile picture
Mitchell Agoma1 month ago

Deleting brittle scripts while preserving meaningful coverage is the right distinction. AI can reduce maintenance, but teams still need deterministic checks and ownership of release risk. Related QA view:

Related Videos

everyone in iOS development should watch this. seriously, it might change the whole industry. i pointed claude code at a live ios device running on revyl, typed "test everything," and walked away. here's what's actually happening: ① you don't write the tests. no scripts, no selectors, no test plan. i never told it which screens to open or what to check. it read the app, decided what mattered, and tested it. the entire instruction was "test everything." ② it built its own test team. it looked at the app, clocked that it's basically four mini apps (rides, delivery, services, account), and split itself into 4 agents, one per surface. scoping coverage like that is usually a person's whole afternoon. it did it in seconds, unprompted. ③ all four ran at the same time, each on its own live device. this is where revyl comes in. every agent gets its own live ios session in the cloud, so four running apps get tested in parallel instead of taking turns on one simulator. serial testing turns coverage into a time tax. running all of it at once removes the tax. ④ it tests like a person, not like a script. each agent drives the app the way a user would, taps through the flows, and visually checks each screen against what it expected to see. nothing is pinned to a brittle element id, so renaming a button doesn't take down half your suite. that one detail is the most annoying thing about how we test today, and it just quietly goes away. ⑤ no xcuitest, no sims melting your laptop. i didn't write a single xcuitest script, and there were no simulators booting on my machine. the agents run on cloud devices, so coverage stops being capped by what your laptop can handle. the part that got me isn't that an agent tested an app. it's that i never told it how. i handed it a device and an intent, and it figured out the scoping, the parallelizing, and the driving on its own. if you still write and maintain mobile ui tests by hand, i'm not sure that lasts the year.

Landseer Enga

23,963 views • 4 months ago

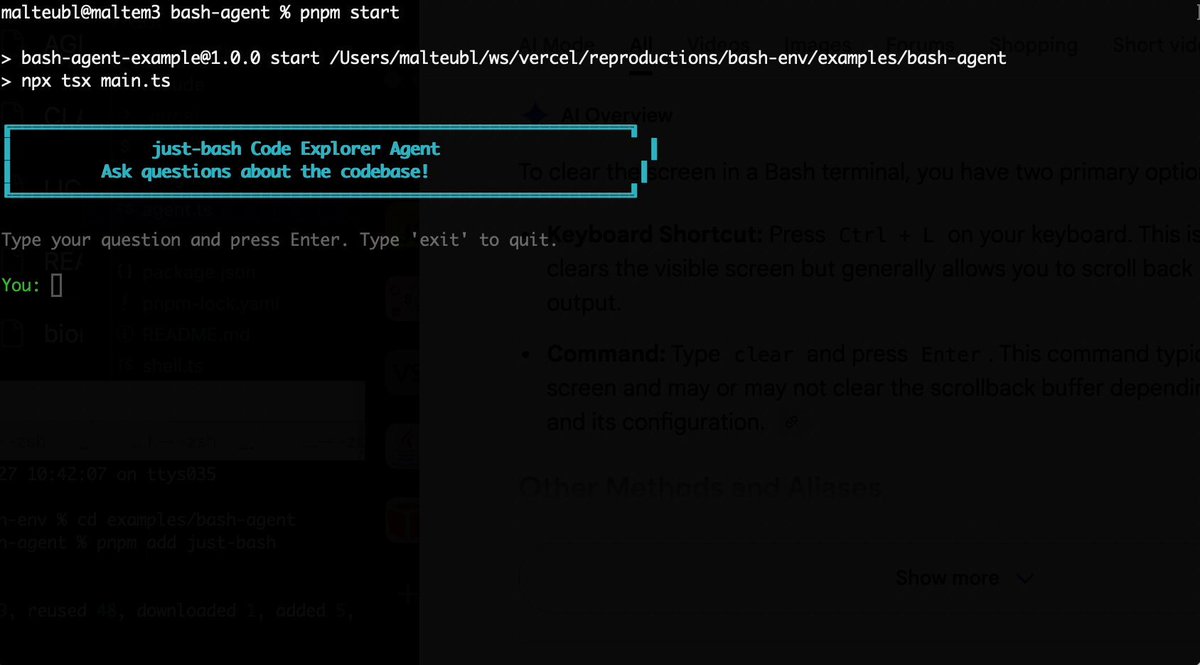
Bash is all you need! Which is why I'm introducing my holiday project: just-bash just-bash is a pretty complete implementation of bash in TypeScript designed to be used as a bash tool by AI agents. Because it turns out agents love exploring data via shell scripts, even beyond coding. It comes with grep, sed, awk and the 99th percentile features that an agent like Claude Code or Cursor would use. In fact, Claude Code can use it for secure bash execution. In the package - A bash-tool for AI SDK - A binary for use by yourself or your coding agents - An overlay filesystem to feed files to your agent securely - A Vercel Sandbox compatible API, so you can quickly upgrade to a real VM if you need to run binaries - An example AI agent that explores the just-bash code base using just-bash - I imported the Oils shell bash compatibility suite and just-bash passes a very good chunk What is interesting about this codebase: It was essentially entirely written by Opus 4.5. Coding agents love bash and they are good at reproducing it. They are also great at text-book recursive descent parsers and AST tweet-walk interpreters. That said, it is, like, a lot of code and I didn't read it all 😅. This is very much a hack, but it also seems to be _really_ useful. I haven't really found anything agents want to use that it doesn't support and it's fast and secure (caveats apply). It doesn't have write access to your computer and the filesystem is given a root that the agent cannot escape from. Find it at Related: Our recent blog post how we migrated our data analysis agent to bash tools and achieved incredible quality improvements The video shows the example agent investigating the just-bash code base

Malte Ubl

125,326 views • 9 months ago

Ever since I wired Claude Code to WhatsApp 3 weeks ago, I built a stupidly large infra around it. I mean, opus built it. No clue how the code even looks. The entire thing was vibe coded using my phone. I wanted to see how far I could push it without touching the computer. Everything via WhatsApp. Build what I need on the fly. So the resulting infrastructure will already be battle tested for software development. The entire thing was streamlined with nearly no manual interventions, everything was communicated via WhatsApp using a single script establishing this connection. If the script is down, I need to get home to start it again to resume the development. Claude was upgrading it, debugging it, restarting it while maintaining constant uptime so it could keep communicating with me. I stressed Claude about it, telling it that it will be “in the dark” and other words that deliberately sound scary about losing communications if the script dies. I also refused git and refused cloning the code, I wanted to see Claude adapting to work on a *LIVING* system. The way this whole thing works: Claude has its own dedicated phone number that I am paying for. A real WhatsApp account for it is installed on a real iPhone that is sitting on my desk. All is registered under my name, this is legit setup with no hacks and tricks. I’ve set up a WhatsApp “Community” and multiple different groups under it. Both me and Claude are the admins, so Claude could edit it on my behalf. Each group is a project I am working on and has its own isolated context. The Group description is a system prompt that gets auto-appended to the larger system prompt explaining this setup in general. When I send a message it’s an instant interrupt to Claude Code’s process, just like in the terminal. Voice notes are seamlessly transcribed with a local Whisper model. Images are used with multimodal reading in an isolated parallel session. Multiple groups running in parallel so I can work on all projects at the same time. No cross-talking, everything has an isolated context and history. And because it’s local on my own machine: Everything is REAL. The browser is REAL. I am connected as myself on it to all services because I actually use it in real life. Claude has unlimited internet access, just like humans who use actual browsers. It utilizes custom-made browser tools that I made to control any browser session it wants. Depending on the situation, it can either connect to my existing session or create one for its own. (You can tell it ‘look at my browser for a sec’ then talk about the current page you are on and it just works, pretty cool) My custom browser tools are not perfect (not by a long shot) but I managed to make them work well to the point they are somewhat reliable. This gives Claude full access to my real creds and all the services I actually use. I’m productive AS HELL with this. It really feels like a personal assistant. I ask it to read my emails and msgs, check x .com for news, research arxiv papers, write code, run experiments for me, investigate and reverse engineer github repos, even use my credit card and order things. [I try not to do this one a lot lol so far no disasters]. All from my phone. Super convenient. This is not a product or an open source project (maybe soon of it will make sense). This is just an ugly script I hacked the entire thing is ~600 lines. (ok maybe i did look at the code, but i swear i didn’t edit!) You can also vibe code this from scratch pretty fast and it will probably even end up better. This is just a cool thing so I’m sharing. It is a real speed booster for many things I do on daily basis, mostly boring things. Forcing my routine into some new “agent platform” just didn’t feel right for me. WhatsApp is where I already communicate and look for messages, so I decided that my agents will live there too. AGI in my pocket 24/7.

Yam Peleg

420,390 views • 9 months ago

i watched gemma 4 12b build something genuinely impressive today, and then loop itself to death right in front of me. the full run is in the video, sped up but completely uncut, watch it to the end and you will catch the exact moment it stops building and starts looping right in the middle of the work. the task was clean, build a single file gravity simulator, n-body physics, orbits, collisions, running locally on one 3090 through an agent. and for ten minutes it was a joy to watch. it reached for a symplectic integrator on its own, the correct one, the kind that keeps orbits stable instead of spiralling out. real gravity with softening, proper orbital velocities, momentum conserved on collision. the physics was right. the thing actually worked. then on the very last step, writing a few tests to prove its own code, it fell into a loop. not a crash, a loop. it started repeating itself and would not stop. ten more minutes, thirty four thousand tokens into a single answer, the same fragments over and over, until i killed it myself. so it's not that gemma can't code. it did the hard part beautifully. it cannot finish. it cannot hold a long task together without unravelling, and finishing is the entire job in agentic work. here's the part that stings. i run this exact task, same harness, same card, on the chinese open models, qwen especially, and i never see this. they build it, they test it, they stop. every single time. google has the raw capability, you can see it sitting right there in the code, and then the model loops itself to death on a task a 27b from alibaba finishes clean. open weights, apache 2.0, so much to love on paper. i just need it to know when to stop talking.

Sudo su

39,764 views • 3 months ago