正在加载视频...
视频加载失败
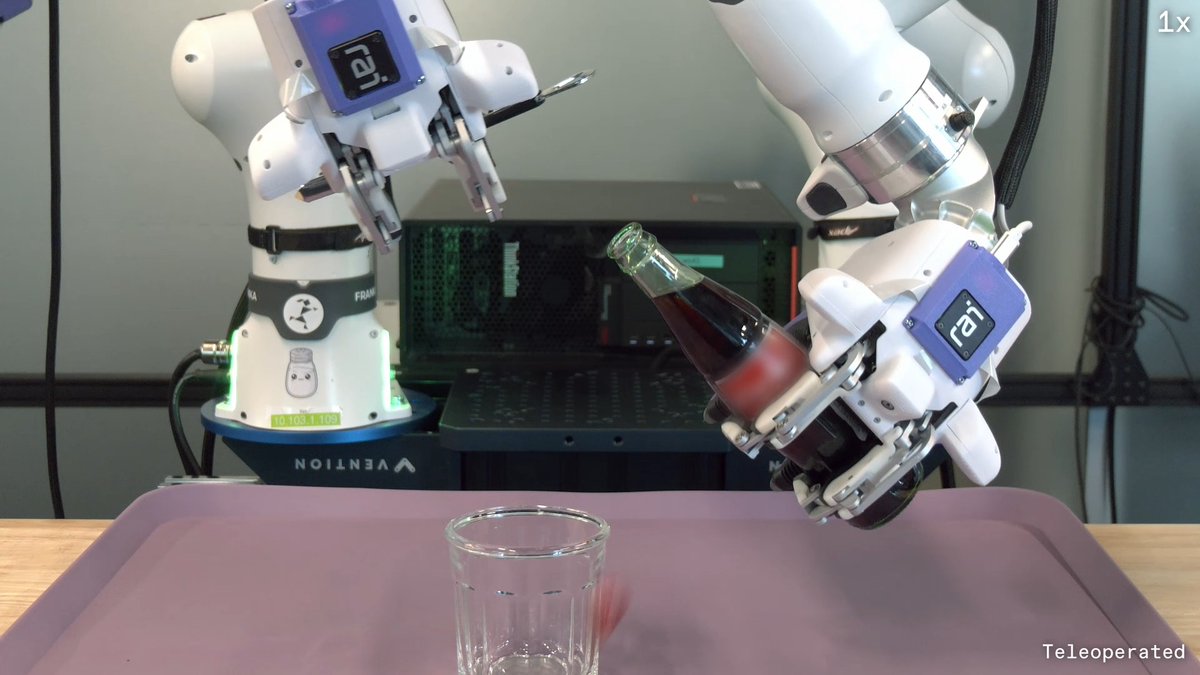
Doing proper science in robotics is hard, because human demonstrations are expensive and less controllable. OCBench is a new benchmark providing "human-like" scripted policies. This enables scientific studies of BC and RL with virtually unlimited data!

27 条评论

OCBench's scripted policies mimic the properties of human demonstrations (e.g., non-Markovian, smoothly random) much more closely than those in previous synthetic benchmarks. See the action histograms below!
OCBench provides 28 manipulation tasks. It supports both state- and pixel-based observations, as well as CPU and GPU (MJWarp) simulations. It provides "lite" versions with shorter horizons for faster iteration as well.
OCBench is also the benchmark used in my previous blog post ("Behavioral cloning mystery"). I hope it's useful for quick prototyping and controlled studies in robotics research! Project page: Blog post:

i've been waiting for this since the previous blog 🙏

how do you measure whether a synthetic demonstration is actually equivalent to a real one? or is the whole point that you can't and have to validate downstream?
Good question! My answer is that it's impossible to completely mimic human demonstrations. However, what is possible is to mimic their key *properties*, and this can be (indirectly) validated by reproducing phenomena that ~only happen with real data (

wow thanks for this

This is awesome! Super cool extension of OGBench

nah bowling is crazy 💀 awesome work!

Can't wait to try world models on this kind of data!!

better robotics science will come from cheaper data and smarter evaluation

wooow,thanks for the efforts!

thanks for this!

yay

Looks super interesting! Bookmarked for future reading list 🙌

Do methods rank the same on the lite short-horizon versions as on the full tasks? If they do, lite becomes a cheap proxy for the controlled studies too, not just quick prototyping.
They're not exactly the same, but are quite closely correlated!

wows

Did you script in any of the messy human stuff, like hesitations or mid-motion corrections?
Yes it does occasionally hesitate and make mistakes, and corrects them!

Even the teacher got scripted.

looks great still

OCBench’s scripted policies offer a way to separate gains from more demonstrations from gains due to a better demonstrator when comparing BC and RL.

脚本策略替掉真人示范,换来的是可复现,丢掉的是「像人」。做科研够用,sim2real 未必——脚本分布外的接触场景它给不出来。想看按接触类型分层的成功率。

Do the scripted policies also have those multi-modal grasps you get in real teleop, or is it mostly noise around one way of doing the task?

knob I'd want next: scripted operators at different skill levels mixed into one dataset. robomimic's BC fell off on the multi-human sets vs proficient-human ones, and that mix is the hardest thing to control with real people
OCBench datasets do consist of a diverse mixture of scripted policies of different levels of proficiency (e.g., with different speeds, mistake probabilities, etc.)!