Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

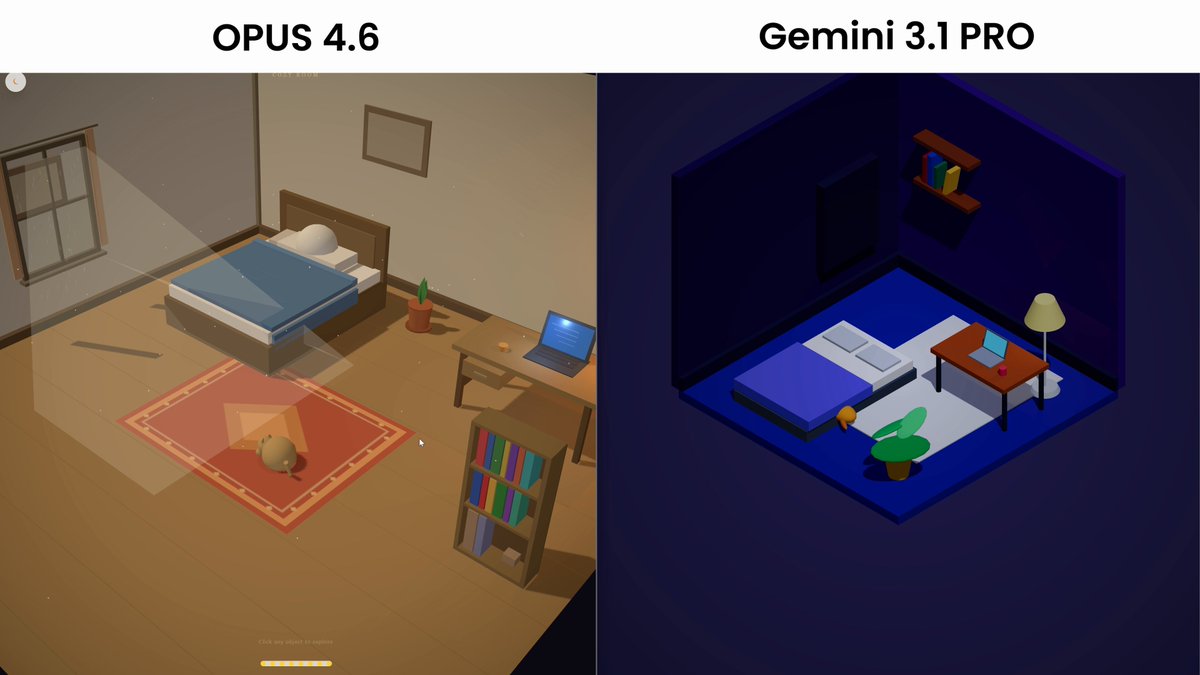
GLM-5.3 Flash in already nerfed? I compared Ox Alpha in it's prime vs today just before it got revealed as GLM-5.3 Flash using the same prompt to build 3d raptor engine using three.js OxAlpha on 24th August gave far more accurate output compared to today which looks way worse...

83,008 Aufrufe • vor 1 Monat •via X (Twitter)

39 Kommentare

Profilbild von teacup
teacupvor 1 Monat

Probably this:

Profilbild von Tim Jayas
Tim Jayasvor 1 Monat

apparently OxAlpha was better as a mystery model with less exposer, it felt so good to use

Profilbild von Raik R
Raik Rvor 1 Monat

AI is not deterministic

Profilbild von Mooncast Productions
Mooncast Productionsvor 1 Monat

If you don't set temperature to 0.0 you are getting random outputs each time.

Profilbild von Crypto Dreki
Crypto Drekivor 1 Monat

First of all how is the second worse than the first…lol. Second of all rng

Profilbild von Chris Hayes
Chris Hayesvor 1 Monat

you can't really just compare 2 generations 1:1 like that... you have to do like 10 of each and compare on average.

Profilbild von Jj McMc
Jj McMcvor 1 Monat

Are you intentionally leaving out that you previously got a result as bad as the bottom one, then claimed it suddenly improved, and now you are claiming it suddenly got worse? Do you really want engagement on your tweety THIS much?

Profilbild von Sebastian Buzdugan
Sebastian Buzduganvor 1 Monat

did you fix temperature and compare repeated runs, because one sample cannot prove a nerf

Profilbild von Danh Thanh
Danh Thanhvor 1 Monat

And this is created by gemini 3.1

Profilbild von Afterkind
Afterkindvor 1 Monat

Improved Ox Alpha was never 5.3 flash. That was a different model as said it themselves.

Profilbild von Calo
Calovor 1 Monat

I guess this was just the first run. As others said, AI is not deterministic.

Profilbild von Surf
Surfvor 1 Monat

Same effort level?

Profilbild von Tim Jayas
Tim Jayasvor 1 Monat

everything same same

Profilbild von ideatorx
ideatorxvor 1 Monat

Maybe it’s just very unreliable and it’s not self improving it’s just all over the map (my experience)

Profilbild von Elpsy(Lψ)
Elpsy(Lψ)vor 1 Monat

3일뒤에 동일 프롬프트로 테스트하면 결과가 다를 수 잇습니다.

Profilbild von cryptopsy
cryptopsyvor 1 Monat

how is it legal for them to nerf. you pay for one thing and get another

Profilbild von Tim Jayas
Tim Jayasvor 1 Monat

every AI model does this after the hype is gone and they get busy building the next new model

Profilbild von Jess.py
Jess.pyvor 1 Monat

maybe cuz its the flash version that was released? not the full standard version.

Profilbild von Rouge
Rougevor 1 Monat

And it's also different from your first try and will be different with your 4th try because those models still aren't deterministic.

Profilbild von GD
GDvor 1 Monat

For me even Ox was nerfed when it was so hyped. I was not impressed with it.

Profilbild von Tim Jayas
Tim Jayasvor 1 Monat

it was working good when not too many people where using the model at the same time

Profilbild von Cato Nooka
Cato Nookavor 1 Monat

you have to host it to be able to control quantization, temperature and more to get the same result.

Profilbild von Vechkasov Kirill
Vechkasov Kirillvor 1 Monat

Yes, it has become much worse to work

Profilbild von QuantizedDen
QuantizedDenvor 1 Monat

it still performs great and I would definitely pick it as a model for fast iterative work I asked it to make a minecraft mod and the results are pretty crazy

Profilbild von rubber ducky
rubber duckyvor 1 Monat

Hmm... This is a mystery indeed 🕵️

Profilbild von Akshay Joshi
Akshay Joshivor 1 Monat

It’s learned from all the 🆓 data it gulped everything, may be unsupervised

Profilbild von Xavier
Xaviervor 1 Monat

If you open two chats and give the same prompts you'll have a bit different results right? So, to be sure of what you are saying you should've run like 10 times, to get a correct idea of before and after. Since we can't go back to stealth, try running it multiple times to see

Profilbild von Sergio Caires
Sergio Cairesvor 1 Monat

every attempt will look different, better or worse because its non deterministic.

Profilbild von Veer Metri
Veer Metrivor 1 Monat

I think the plan with OX Alpha is not only to release and test GLM 5.3 Flash but rather the infrastructure too, do they might have just tested with GLM 5.3 Omni.

Profilbild von Adel Bucetta
Adel Bucettavor 1 Monat

glm-5.3 flash is a great example of how model updates often create trade-offs between size and performance. nerfing may save memory, but at what cost to output quality?

Profilbild von 𝚣𝚒𝚟𝚎𝚛𝚗𝚘
𝚣𝚒𝚟𝚎𝚛𝚗𝚘vor 1 Monat

What quant did you use ?

Profilbild von Banksyisatagger
Banksyisataggervor 1 Monat

Yeah its called a flash build buy the pro version

Profilbild von cotton2candyk
cotton2candykvor 1 Monat

那必然给你上量化模型了

Profilbild von Zishan A
Zishan Avor 1 Monat

100% nerfd

Profilbild von Adi
Adivor 1 Monat

yup, it feels different, going back to codex

Profilbild von Tim Jayas
Tim Jayasvor 1 Monat

and get codex resets every other day

Profilbild von 🆁
🆁vor 1 Monat

Curious about its pass@4 variance. Do 4 tests.

Profilbild von AD3 Digital Marketing
AD3 Digital Marketingvor 1 Monat

same harness or what?

Profilbild von Tim Jayas
Tim Jayasvor 1 Monat

yes same harness used with same prompt same model, the only difference is the time

Ähnliche Videos

glm 5.3 flash is 7.5x cheaper, but 3.4x slower than gemini 3.7 flash Z.ai glm 5.3 flash – shipped aug 26, $0.07/$0.25 per 1m Google DeepMind gemini 3.7 flash – shipped aug 13, $0.38/$1.88 per 1m we put the two models on one job: write one html file that draws an animated 3d scene in the browser. no images, no downloads, and it has to look the same on every load. the setup: three scenes – a glass aquarium in a lit room, the solar system, a night city under a thunderstorm. identical brief word for word, reasoning effort high, 64k output cap. the numbers below are not the whole run. they cover the three scenes we kept – the best one per task from each model, the ones in the video. - total generation time for the three scenes #1 gemini 3.7 flash – 10m 36s #2 glm 5.3 flash – 36m 30s - tokens spent on those three scenes #1 glm 5.3 flash – 110k #2 gemini 3.7 flash – 111k - cost of those three scenes #1 glm 5.3 flash – $0.027 #2 gemini 3.7 flash – $0.202 observations: • glm's first 10 attempts: 7 blank pages. it kept inventing short random helpers and forgetting to define one of them. the fix was one line in the brief: use exactly one random helper, named rand(), and don't invent shorthands next to it. next 12 attempts: 11 alive, 0 crashes. • glm spends 66% of its output on reasoning, gemini 57%. that is the whole speed gap. • gemini's storm came back as a black rectangle in 4 of 6 runs. glm's best storm has a branching bolt, lit rain and wet asphalt – for $0.01. conclusion: same three scenes, same token spend – glm 5.3 flash billed $0.027 and took 36m 30s, gemini 3.7 flash billed $0.202 and took 10m 36s. glm wins gemini on price and made the best storm of the whole run follow thehype. for 24/7 ai news, analysis and breakdowns

thehype.

16,041 Aufrufe • vor 1 Monat

GLM-5.3 Flash vs Qwen3.8 Flash-Next. Both local on my 4x 3090, both left alone with 1 prompt per task. 11 scenes, 18 hours, 2.4M tokens out. All of it is in the video. I wanted a clear winner. I didnt get one, but I know which one stays on my rig. GLM-5.3 Flash: Maya-M quant, 116 GB, runs in Project Maya on all 4 cards plus RAM. 35 to 48 tok/s while it works. Qwen3.8 Flash-Next: IQ3_S quant, 78 GB, runs in Strata on 2 cards. 85 to 118 tok/s. Both have 262K context and vision, so the agent opens its own page, takes a screenshot, looks at it and fixes what it sees. 1 prompt per scene. No follow ups and no hints from me. 120 minutes max per scene, 150 for the kart game. I ran them in 2 harnesses, OMP first and then DeepSeek Harness. Minutes until the model said it was done: Pelican in OMP: GLM 39, Qwen 66 Pelican in DeepSeek Harness: GLM 93, Qwen 86 Kart game in OMP: GLM 130, Qwen stopped by the 150 limit Millipede in OMP: both stopped by the 120 limit Millipede in DeepSeek Harness: Qwen stopped at 120 again Battle diorama in DeepSeek Harness: GLM 81, Qwen 113 Thats 11 of 16 combos. I ran out of time for the other 5, sorry. They work in a very different way and I didnt expect that. GLM thinks for a long time and then writes a lot at once. Its first pelican took only 36 turns. For the diorama it gave 1 answer of 47K tokens that ran for almost 18 minutes, with the full scene in a single file. Qwen goes in small steps and checks everything. The same pelican was 240 turns and 45 browser checks. In total GLM wrote 513K tokens in 5 runs and Qwen wrote 1.9M in 6 runs, so Qwen puts out 2.6x more per minute of real time, on half the cards. The harness also changed more than I thought it would. OMP keeps only 5 images in a request when the provider is local. So every new screenshot removes the oldest one, the prompt changes in the middle, and the server has to read the context again from the start. GLM lost 37 of its 130 kart minutes just on that. In DeepSeek Harness, on the diorama, it lost 3.5 minutes out of 81. Qwen reads a prompt almost 4x faster on my rig (84K tokens in 23 seconds, GLM needs 100 seconds for 96K), so in OMP it lost only 9 to 12 minutes per run. I cant give you a winner. GLM is the only one that finished the kart game inside the limit, and its scenes look cleaner to me. But its millipede is bad. Qwen puts more detail into everything, and its diorama and millipede from DeepSeek Harness are my favorite scenes in the video. It also got stopped by the time limit in 3 of its 6 runs, because it just keeps polishing. For my own use I'd take Qwen. It is a lot faster and it needs only 2 cards, so the other 2 stay free and I can run something else next to it. This is 1 run per combo, so dont read it as statistics. Both models ran with my refusal projection on, because thats how I use them every day. And in the kart clips the game's own AI is driving the player kart, I only recorded the screen. Music: YuE2

Alexey Fateev

12,116 Aufrufe • vor 2 Tagen

glm 5.3 vs qwen 3.8 vs gemini 3.7 vs deepseek v4 flash four models designed and built three structures each on a physics-backed site, with no dimensions anywhere in the brief the setup: our own agent loop on OpenRouter, a construction site as the tool set – footings, walls, arches, roofs, scaffold, a lamp. the site enforces physics and nothing else: unsupported brick falls, a roof needs walls under it, a worker reaches 3.2 m above whatever he stands on, an arch needs centring until the keystone is set, concrete cures before it carries. no budget ceiling – material cost is tallied and reported, never blocked. tasks: 1. house – a plot and a palette, no plan. shape, height and material are the model's call 2. lighthouse – a headland cut by a gully, with a rock stack standing 30 m offshore. the lamp must burn, it must be the highest thing built, and the keeper must be able to walk to it 3. bridge – a river with one islet and banks at different heights. cross it however you want models: Z.ai glm 5.3 flash, Qwen qwen 3.8 flash, Google DeepMind gemini 3.7 flash, DeepSeek v4 flash vision all twelve objects were finished and signed off by the models themselves. tallest lighthouse is qwen's at 38.4 m, planted on the offshore stack with a bridge run out to it – the only model that read the site that way. deepseek signed off its bridge on an empty riverbed: 0 bricks, 107 minutes, $1.16m of material tallied - total cost, three builds #1 glm 5.3 flash – $0.201 #2 gemini 3.7 flash – $0.871 #3 qwen 3.8 flash – $1.058 #4 deepseek v4 flash – $1.567 - wall clock, three builds #1 gemini 3.7 flash – 91m #2 glm 5.3 flash – 228m #3 deepseek v4 flash – 502m #4 qwen 3.8 flash – 912m - total tokens #1 gemini 3.7 flash – 3,567,052 #2 glm 5.3 flash – 4,732,748 #3 qwen 3.8 flash – 13,469,333 #4 deepseek v4 flash – 18,230,076 - defects logged by the site #1 deepseek v4 flash – 59 #2 gemini 3.7 flash – 132 #3 glm 5.3 flash – 221 #4 qwen 3.8 flash – 350 - material tallied across three builds #1 gemini 3.7 flash – $359,884 #2 glm 5.3 flash – $583,358 #3 deepseek v4 flash – $1,327,484 #4 qwen 3.8 flash – $2,188,625 observations: • glm is the cheap one and nothing here is close – $0.201 for three buildings, $0.042 per million tokens, 6x under gemini's rate • what glm spends it on is bulk, not care: 166,228 bricks in one house and 156 defect weight, the worst single object in the set • gemini is the efficiency line – 91 minutes and 3.57m tokens for all three and an eighth of qwen's clock • gemini also builds the smallest of everything. its lighthouse is 22.5 m against qwen's 38.4, its house 6.9 m against 19.3 • qwen is the maximalist: 1.18m bricks, $2.19m of material, tallest on all three tasks, and 912 minutes – 15 hours – to get there conclusion: twelve finished objects for $3.80 all in, and a 7.8x price spread between the cheapest model and the priciest! follow thehype. for 24/7 ai news, analysis and breakdowns

thehype.

26,360 Aufrufe • vor 1 Monat