Loading video...
Video Failed to Load
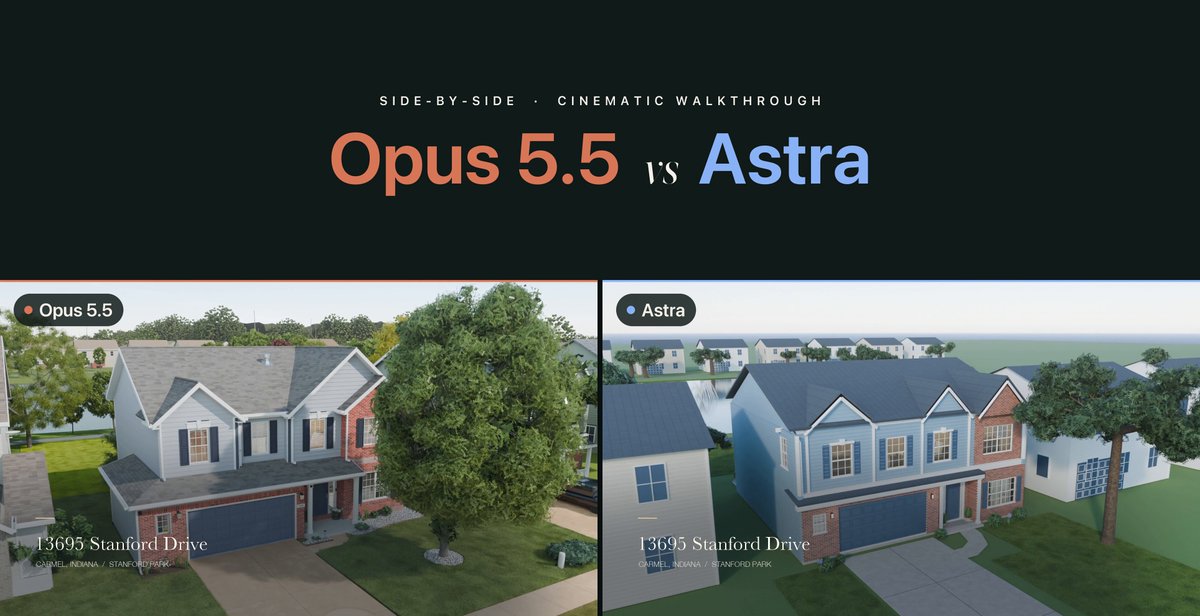
GPT 6 Astra one shotted a bug in BridgeMind that no model could solve in 6 months. Fable 5 failed. Fable 5.1 failed. Opus 5, Sol, Grok 4.6, all failed. Astra fixed it on the first prompt. Then it rebuilt my office in Blender from photos. Built a racing... show more
38,363 views • 22 days ago •via X (Twitter)
47 Comments

GPT 6 Astra has unbelievable debugging capabilities and one shot capabilities.

Anthropic is only worried about enterprise

They need to consider us more

NOW WE ARE TALKING!! Solving real world coding problems. More of these real world examples with real codebases please.
I've got you bro

You should keep that bug for testing models !
interesting idea

This is all so subjective and squishy... and of your 13 followers most of them are OpenAI people... no wonder this sounds like a commercial.
lol

one-shotted a bug six models failed at while using a third of the tokens is either the most important benchmark result of the year or a cherry-picked task. You know , i am really super curious which it is across 100 tasks ?

You need a mobile app version
I agree

Absolutely insane abilities from GPT 6 Astra. Loving this model right now! Loving, streams and videos. Keep it up, brother!!! 🚀🚀

yep, feels like a phase shift

You had a bug you couldn't resolve for 6 months?! Vibe coders 🤦🏻♂️

Anthropic bir hafta sonra Fable 5.2 yi duyurabilirmi? 😁

GPT 6 Astra cost per task is LESS THAN SONNET 5

one shotting a 6 month bug is insane if true
Yea it is incredible
Six months humbled in one prompt.

It remains to be seen whether posts like these reveal something important about Astra’s capabilities. It may just be that Astra happened to better at that one particular problem.

we might already be in the "AGI" era

I think this is the part where AI enters a phase of actual useability in the real world more widely than just apps. I 100% agree that this will be remembered at the beginning if AGI 10 years from now.
agree
Here's the important part though. This is one person's opinion after using the tool himself, not something proven by outside testing. People online often say big exciting things like this to get attention and views, especially when a new AI model just came out, since that is when everyone is curious about it.

inb4: “aNtHrOpIc iS BaCk!!1!”
They need a good opus model or something. I dont know how they come back from this
I’m just referencing every new model from N flagship over the next, ppl are rushing to hate + cancel + “how can Y keep up” and the cycle continues.

Chatgpt latest update makes usage way way way lower!

What’s the best harness? Trying to get it to work on a very long horizon project without pausing

I like watching how all of this is progressing and helping solve problems. It’s reached such an amazing level

also , fable 5.1 is not included in the plan so we can not even use it

GPT models were always the best debuggers.
Fable used to be better than GPT 5.6 Sol

Other models bounced off that bug. Astra fixed it then casually kept going into Blender like that was the warm-up.
yea its insane

Bro this is insane

The efficiency shifts with each new model highlight the ongoing evolution in AI capabilities. It will be interesting to see how these advancements impact model development timelines and user workflows in creative fields.

man i really need to stop reading these benchmark posts before coffee the blender thing from photos is the one that actually scares me, not the benchmarks

holy benchmarks lol

These models are great for one-shot miracles and very specific problems. For continuous use and actually building a project? They’re all fucking terrible. They drink tokens like water. Astra included. I don’t care how smart a model is if a few hours of real work burns through a weekly quota. That’s not productivity. That’s a demo.

Fable 5.1 >>> Astra
Very simply: another model.

Would love to try astra soon

Genuinely curious about the '6 months, first prompt' combination. Was the prompt you gave Astra identical to what you gave the others, or had six months of failures changed how you described the problem?

The bug fix and Blender rebuild test very different kinds of work Together, they make the review less dependent on a single benchmark

Six months of failing means you've basically given Astra a perfect bug report. Still impressive, I'd just want to see it one-shot a bug you found five minutes ago.