Загрузка видео...
Не удалось загрузить видео
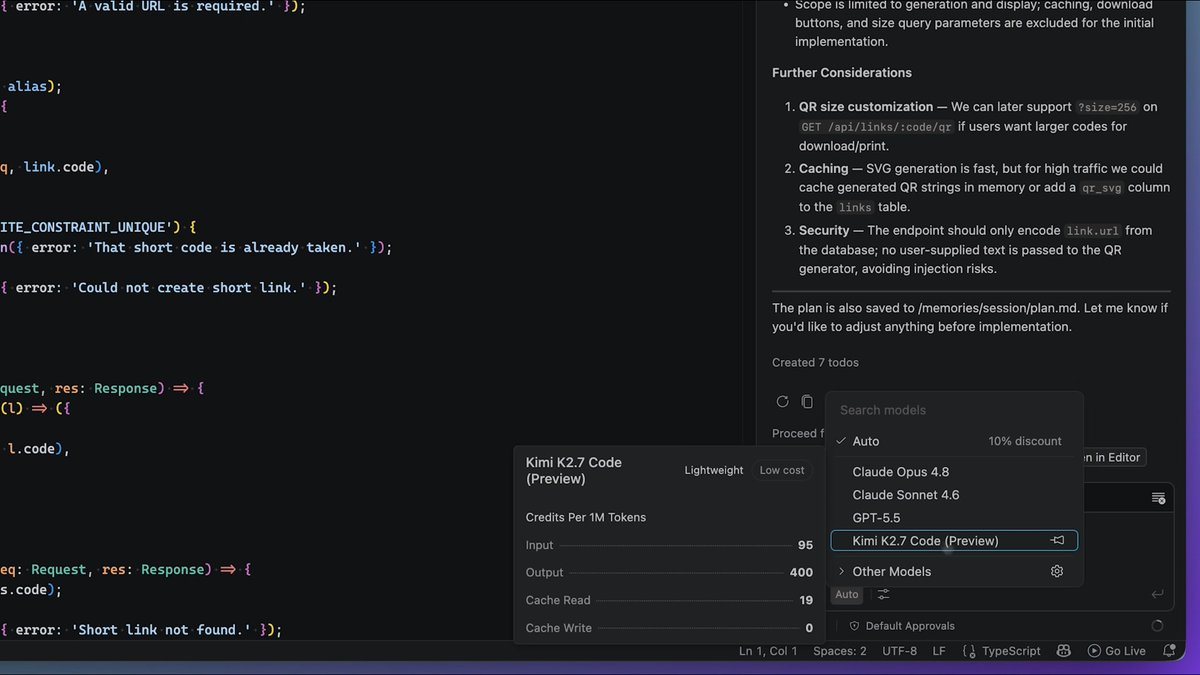
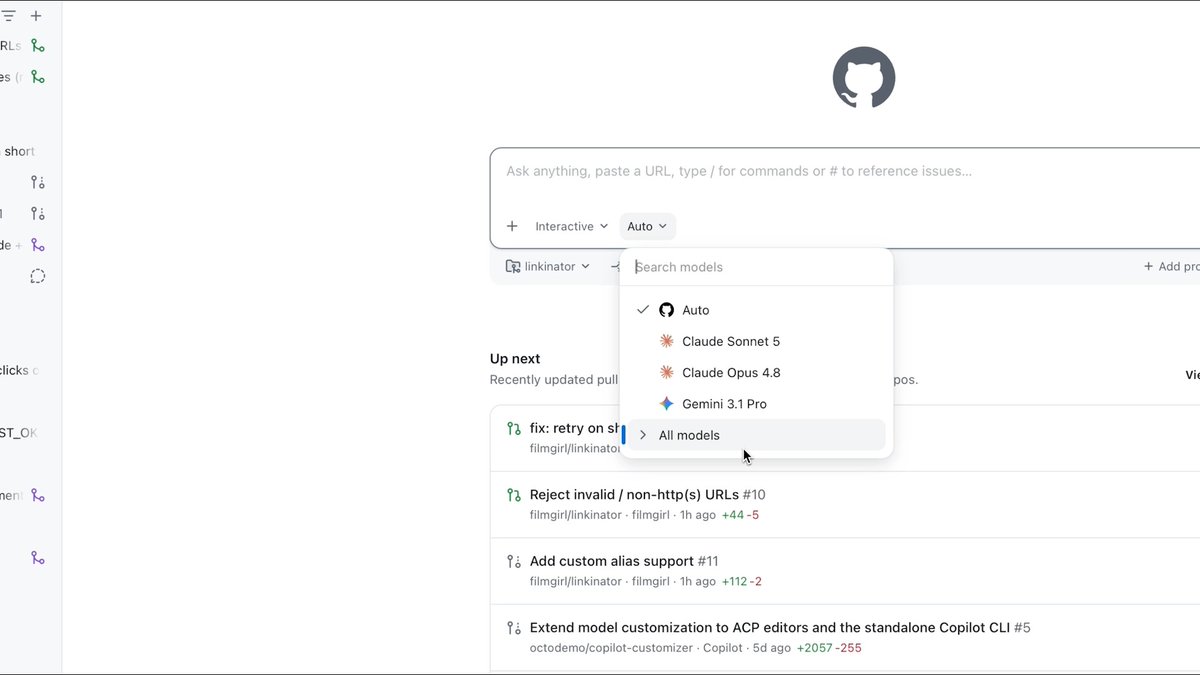
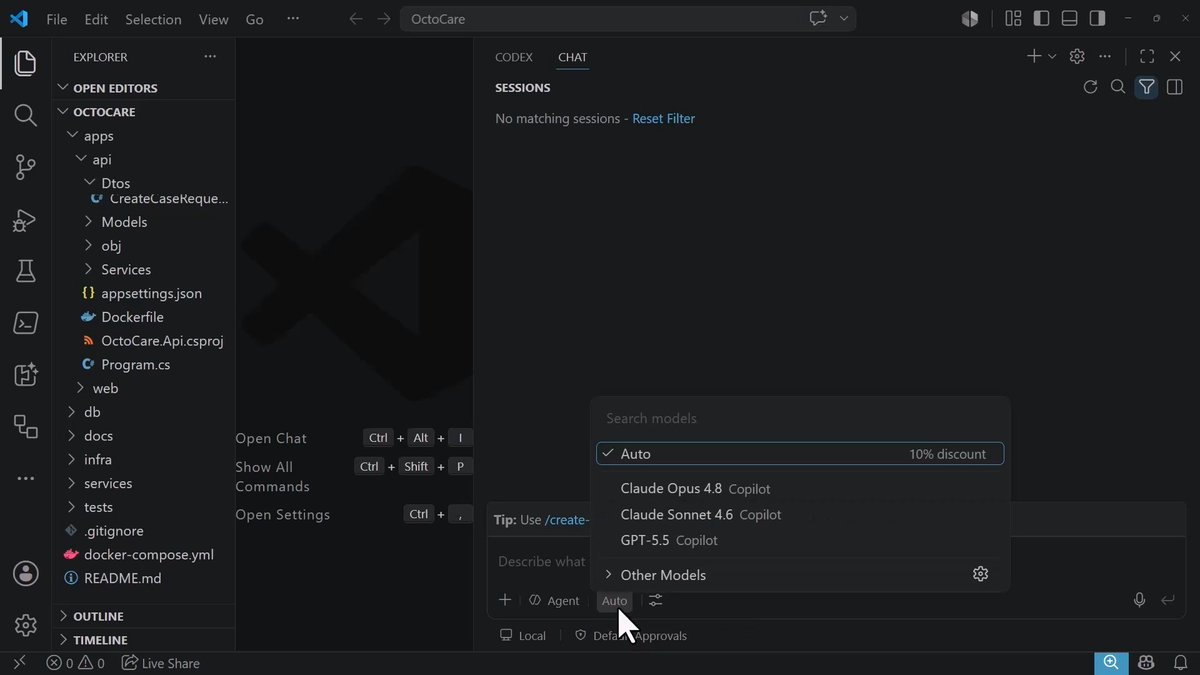
🌌 GPT-6 Astra from OpenAI Developers is now generally available in GitHub Copilot. This new model is designed for long-horizon, autonomous coding and agentic tasks. Our internal testing shows it plans and validates as it goes, batches diagnosis with verification, and independently confirms its results before declaring a task... show more

175,100 просмотров • 1 месяц назад •via X (Twitter)
Комментарии: 28

@OpenAIDevs When will support staff be available to reply to tickets?

@OpenAIDevs Astra is a generational event, regardless of what anyone believes about sama.

Long-horizon coding agents change the control problem because risk accumulates across sequences of actions, not isolated outputs. The important question is whether teams can preserve visibility into what the agent changed, why it changed it, and where human review should interrupt the workflow before errors compound.

@OpenAIDevs Every week I read a new post about a new breakthrough of some model. But as soon as I start testing them myself, I realize that 90% of what's written is complete BS. Thanks to you too for another lie.

@OpenAIDevs @Azure Copilot CLI Foundry lets you test/use the entire Frontier. GPT-6 👇

@OpenAIDevs AI coding is moving beyond “write the code.” Planning, testing, debugging, and verification are becoming part of the loop. @CottoniaAI thinks autonomous execution is the real unlock.

@OpenAIDevs With like what, 50K context window?:D

@OpenAIDevs Parallel coding agents may make terminal hopping feel like an outdated sport.

@OpenAIDevs The real test is whether “independently confirms its results” still holds after a 2-hour debugging session.

@OpenAIDevs Long-horizon coding in Copilot is the feature I've actually wanted. The short-chat loop was never where the painful work lived.

@OpenAIDevs Long-horizon coding only becomes useful when the agent can validate each step; batching diagnosis with verification is the part that should reduce review fatigue.

@OpenAIDevs Agentic products should be judged by the quality of their handoffs. When context and evidence survive each step, teams can scale work without scaling confusion.

@OpenAIDevs The self-verifying loop is the part that changes the economics for us. Once agents can plan, batch work, and prove the result, the bottleneck moves from typing code to coordinating the floor.

@OpenAIDevs when will GitHub Copilot support computer use capabilities?

@OpenAIDevs Great work github

@OpenAIDevs @OpenAIDevs really reposted this twice 🥀

@OpenAIDevs long-horizon autonomous coding is the real test

@OpenAIDevs #ZEROHelp

@OpenAIDevs Elon looking at Astra rn after he just yelled at the xAi team to speed up production

@OpenAIDevs It's interesting how Copilot's entire business model has become "Azure for model", somewhat of an AI Foundry for harness.

@OpenAIDevs Copilot getting this is big news

@OpenAIDevs Long-horizon coding is useful. Still want a written stop line another desk can enforce without reopening the session.

@OpenAIDevs The useful benchmark is wall-clock time from issue to merged PR, including reviewer cleanup. Fewer agent steps sound nice, but if a human spends an hour repairing the diff, the win disappears.

@OpenAIDevs The plan→validate loop sounds useful; what does “validates” mean in Copilot here—unit tests, type checks, or model-generated assertions? I’d also like to see task success and revert rates split by repo language/size, since fewer steps can mask larger diffs.

"Plans and validates as it goes" is a workflow claim, not a benchmark. What's the actual metric — task completion rate on a held-out repo, human-eval pass@1, something else? "Internal testing shows" from the vendor shipping the model needs a third party rerunning it before it means anything.

@OpenAIDevs Productivity of developers is definitely improving!
@OpenAIDevs #FightingForMyLifeWhileYouLaughAndSteal

@OpenAIDevs my monthly bill about to feel this one 💀