Loading video...

Video Failed to Load

Go Home

Half-Anniversary Server Data Recap | Redeem Code Rewards Half a year has passed beneath the Blood Moon. Who is the most deployed Vassal? How much total DMG was dealt in the Clan Hunt server-wide? What trials lie in the stage cleared by only 4 players server-wide? Every recorded choice,...

17,254 views • 9 months ago •via X (Twitter)

0 Comments

No comments available

Comments from the original post will appear here

Related Videos

Claude Code is now scary good at full-stack! I asked it to build a real-time weather intelligence dashboard with an interactive 3D globe and a forecasting layer that predicts weather 3 days ahead. It came back with a spinning globe that has a day/night cycle using NASA satellite imagery, city lights on the dark side, weather icons that switch between sun and moon based on local time, and a time travel slider that scrubs through 10 days of data. Claude Code built the whole thing in a single session, including the backend, database, data pipeline, and frontend. For the database, I needed something fast for time-series workloads since the app ingests hourly weather readings across many cities and serves time-range queries on every slider interaction. I used Tiger Cloud by Tiger Data - Creators of TimescaleDB, which gives you managed TimescaleDB on the Postgres you already know. Claude Code connected to it through the Tiger CLI MCP server and set up the entire backend directly: - Provisioned the database service - Created hypertables for time-partitioned weather storage - Set up continuous aggregates for pre-computed rollups - Built the data ingestion pipeline and the full NextJS + ThreeJS frontend The time travel slider queries thousands of rows on every position change. On a regular Postgres table, this would require manual partitioning and index tuning to stay fast as data grows. TimescaleDB partitions the data by timestamp automatically, so each query only hits the relevant time chunk. Continuous aggregates serve the trend charts and forecast layer from pre-computed rollups instead of rescanning raw data on every request. The video below shows the final build in action, and I worked with the Tiger Data team to put this together. Tiger CLI is open-source (Apache 2.0) and works with Claude Code, Cursor, Codex, Gemini CLI, and VS Code. To try this yourself: → Sign up for Tiger Cloud (I have shared the link in the replies). It gives you $1,000 free credits (no card needed) → Install Tiger CLI: curl -fsSL https(:)//cli(.)tigerdata(.)com | sh → Run tiger mcp install claude-code → Give Claude Code a prompt and let it build Find the sign-up link in the replies.

Avi Chawla

14,838 views • 3 months ago

How Cloudflare cut query times by 35x without leaving Postgres: Their Postgres tables hit billions of rows, and every time-range query started getting slower. Plain Postgres scans the entire table on every query, regardless of the time window. They tried the manual route by building precomputed aggregates with cron jobs and evaluating ClickHouse, which needed a full ingestion pipeline just to handle their write pattern. Here's where most teams get stuck at exactly this point. They utilize manual partitioning, splitting data into child tables by day or month. Then they wire up cron jobs to refresh aggregate tables. Every schema change after that requires updating the cron logic and coordinating across teams. The infrastructure becomes the project. Tiger Cloud is managed TimescaleDB by Tiger Data - Creators of TimescaleDB on the Postgres you already know, with automatic time-based partitioning, continuous aggregates, and compression built in from the start. Cloudflare moved to TimescaleDB after exhausting the manual route and saw 5-35x query performance improvement on the same data. Here is how it works: → Hypertables partition data by timestamp automatically. Every time-range query hits only the relevant chunk, not the full table. → Continuous aggregates refresh incrementally in the background, with no cron jobs to maintain. To show what this looks like in practice, I built a real-time earthquake intelligence dashboard on a 3D globe using Claude Code and Tiger Cloud in a single session. The USGS earthquake catalog has 400,000+ events since 1900, each a timestamped row. The dashboard plots them as ripple animations sized by magnitude and colored by depth, with a time slider that scrubs through 120 years of seismic history. Every slider position fires a live query against the hypertable, and the side panel pulls from continuous aggregates. Claude Code connected to Tiger Cloud through the Tiger CLI MCP server, provisioned the database, pulled the USGS catalog, and assembled the full Next.js and Three.js frontend without leaving the session. The video below shows the final build in action, and I worked with the Tiger Data team to put this together. Tiger CLI is open-source (Apache 2.0) and works with Claude Code, Cursor, Codex, Gemini CLI, and VS Code. To try this yourself: → Sign up for Tiger Cloud here: New accounts get $1,000 in free credits, no credit card required. → Install Tiger CLI: curl -fsSL https(:)//cli(.)tigerdata(.)com | sh → Run tiger mcp install claude-code → Give Claude Code a prompt and let it build. I also wrote a full walkthrough on how you can turn any coding agent into a production-grade data engineer that can manage over a billion-row Postgres workloads. It covers everything from the database setup to the final build. Read it below.

Avi Chawla

22,094 views • 1 month ago

Claude Code is now scary good at full-stack! I asked it to build a real-time weather intelligence dashboard with an interactive 3D globe, a forecasting layer that predicts weather 3 days ahead, and an anomaly detector that flags cities whose weather is behaving abnormally. It came back with a spinning globe that has a day/night cycle using NASA satellite imagery, city lights on the dark side, weather icons that switch between sun and moon based on local time, and a time travel slider that scrubs through 10 days of data. And when a city's weather breaks from its own normal, it pulses red (abnormally hot) or blue (abnormally cold) right on the globe, updating live and reflecting the anomaly state at any point you drag the slider to. Claude Code built the whole thing in a single session, including the backend, database, data pipeline, and frontend. For the database, I needed something fast for time-series workloads since the app ingests hourly weather readings across many cities and serves time-range queries on every slider interaction. I used Tiger Cloud by Tiger Data - Creators of TimescaleDB, which gives you managed TimescaleDB on the Postgres you already know. Claude Code connected to it through the Tiger CLI MCP server and set up the entire backend directly: - Provisioned the database service - Created hypertables for time-partitioned weather storage - Set up continuous aggregates for pre-computed rollups - Built the data ingestion pipeline and the full NextJS + ThreeJS frontend The time travel slider queries thousands of rows on every position change. On a regular Postgres table, this would require manual partitioning and index tuning to stay fast as data grows. TimescaleDB partitions the data by timestamp automatically, so each query only hits the relevant time chunk. Continuous aggregates serve the trend charts, the forecast layer, and the anomaly baselines from pre-computed rollups instead of rescanning raw data on every request. The video below shows the final build in action, and I worked with the Tiger Data team to put this together. Tiger CLI is open-source (Apache 2.0) and works with Claude Code, Cursor, Codex, Gemini CLI, and VS Code. To try this yourself: → Sign up for Tiger Cloud (I have shared the link in the replies). It gives you $1,000 free credits (no card needed) → Install Tiger CLI: curl -fsSL https(:)//cli(.)tigerdata(.)com | sh → Run tiger mcp install claude-code → Give Claude Code a prompt and let it build sign-up here: My co-founder also wrote a detailed article on this. The article is quoted below.

Akshay 🚀

37,269 views • 1 month ago

Spirit Airlines stopped flying in May. Second bankruptcy in two years. Yet Google still wants to pay $10Million for the dead body. The planes are gone, the airport slots are sold. One asset left. At the bankruptcy auction, Google opened at 5 million dollars. An AI data company called Mercor countered at 7 and a half million. Then Google closed it at 10 Million. But the bids weren't for the planes or Airport slots. They were for 100 million internal emails. 500 million Teams messages. 30 million lines of code. Employee records that go back to 1986. And no, its not passenger data. This is purely internal: decades of how a real business thought, argued, and made decisions. Why pay that much for a dead company's inbox? Because it's the one thing AI can't fake. The most valuable data in the world right now is just real people thinking out loud… real decisions, real mistakes, real cause and effect. Which is why after the auction closed, another AI company came in with a 12 and a half million offer for it. Here's how you can leverage this kind of data for your business without a bankruptcy auction. People type their real, unfiltered questions into a search bar every single day… for free. And for business owners, those raw questions are a free roadmap: they tell you exactly what to create, what to fix on your site, and what to sell next. Tools like AnswerThePublic mine and present that exact data by looking at the different ways people search for a product. The AI data gold rush is just getting started, follow to not miss out!

Neil Patel

12,729 views • 19 days ago

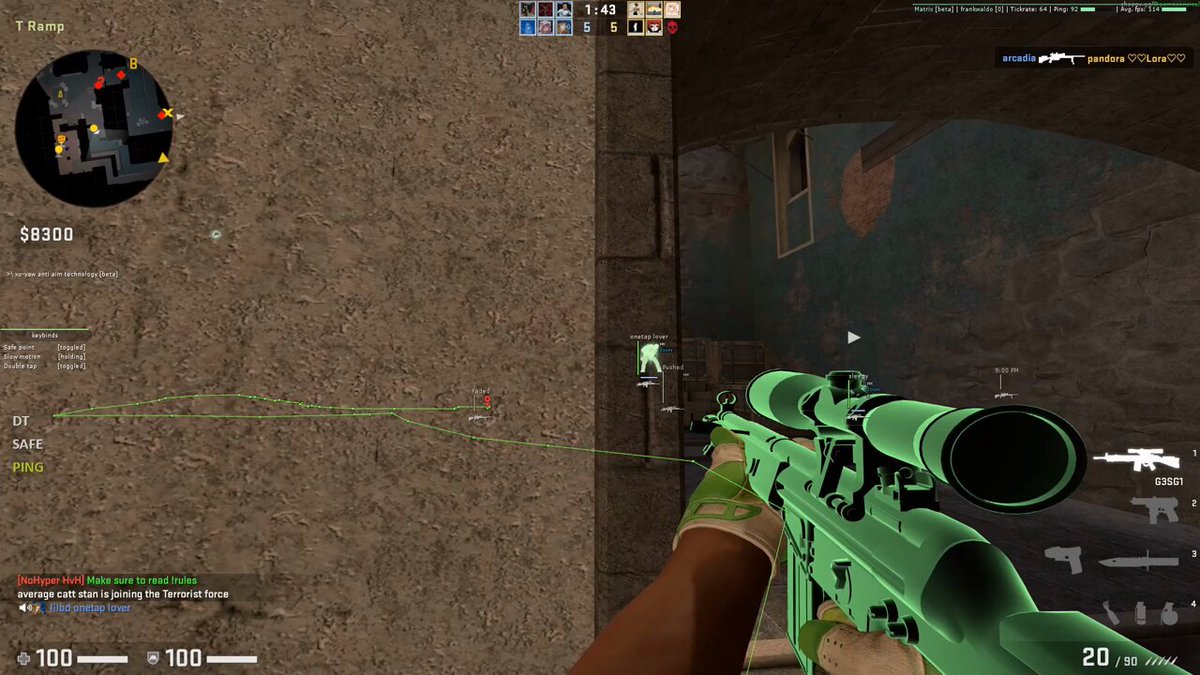
Counter Strike hacking is one of my guilty pleasures. This is a video of an AI tool built into one of the most popular HvH cheats on the market. HvH (Hack vs. Hack) is a game mode where everyone in the lobby is cheating. “If everyone is cheating, then how is it fun?” The game becomes something entirely different in this mode. Instead of focusing on physical reaction time, aim, and movement skills, players must concentrate on the quality of their cheats compared to those used by their opponents. The game essentially turns into a sandbox for software optimization, where cheaters compete against each other to see who has the better-written code and configuration. Players must use every tool available to keep up with everyone else in the scene. My favorite cheat, Anti-Aim (AA), is used to help protect players from getting shot by cleverly exploiting the game mechanics to fake the angle of their hitbox. It works by choking abs yaw packets to exploit a coding error in the game, causing your model’s position to appear bugged to other players. The server processes each command sent by the client in the order it receives them, then it updates animations for each command. After this, the server takes the latest information it has and sends it to other players. If you choke packets, you will essentially send all of your choked commands at the same time. Again, the server will look at what’s latest and send that to other players. Now, you should see the issue clearly: the client is missing loads of information and will start updating animations with incorrect information. This will lead to numerous inaccuracies in their animation state, most importantly their abs yaw (m_flGoalFeetyaw), which indicates where their feet are pointing. The creation of Anti-aim techniques significantly disrupted gameplay, giving users an extra unfair advantage. This compelled players to devise a solution— Resolvers are used to counter anti-aim by determining where the player’s hitbox actually is. One commonly used type of resolver is the old angle resolver. Old angle resolvers work by storing the previous angles from when the player wasn’t faking their position and later shooting at them. —forcing both sides—Anti-Aim developers and Resolver developers—to continuously improve their code and technique. HvH is an ever-evolving arms race where staying ahead is as much about innovation as it is about execution. Code rules all, and hitting p is the only goal. That’s what keeps me coming back. (Video: @peter2b2t, YouTube)

nv🐎

285,689 views • 2 years ago

8 rules to improve your AI coding agent. All of these rules work with Claude Code, Cursor, VS Code, and with most programming languages. Automating these rules will 10x the code quality and security produced by your AI coding agents. 1. Dependency checks - Prevent your agent from suggesting insecure libraries based on outdated training data. 2. Secret exposure - Auto-fix the use of hardcoded credentials introduced by your coding agent. 3. File and function size - Automatically refactor any files or functions that exceed a reasonable length. 4. Complexity and parameter limits - Simplify overly complex code written by the agent. 5. SQL Injection - Auto-fix all database interactions with unsanitized user input. 6. Unused variables and imports - Detect and remove dead code. 7. Detect invisible unicode characters in AI rules files - Remove zero-width spaces, direction overrides, and other invisible characters that can hide malicious behavior. 8. Insecure OpenAI API usage - Enforce use of secure OpenAI endpoints, proper authentication, and context isolation Here is how you can automate this: Install the Codacy extension. This will give you access to a CLI for local scanning and an MCP server for agent communication. From here on out, every time you need to generate some code: 1. Your agent will write the code 2. It will then call Codacy's CLI to check it 3. It will find any issues in real time 4. Your coding agent will fix the issues 5. When the code passes all checks, you are done Level of effort on your side: literally zero! Code quality and security because of this: 100x better! Here is the link to download the extension for your IDE: Thanks to the Codacy team for collaborating with me on this post.

Santiago

49,331 views • 11 months ago