Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

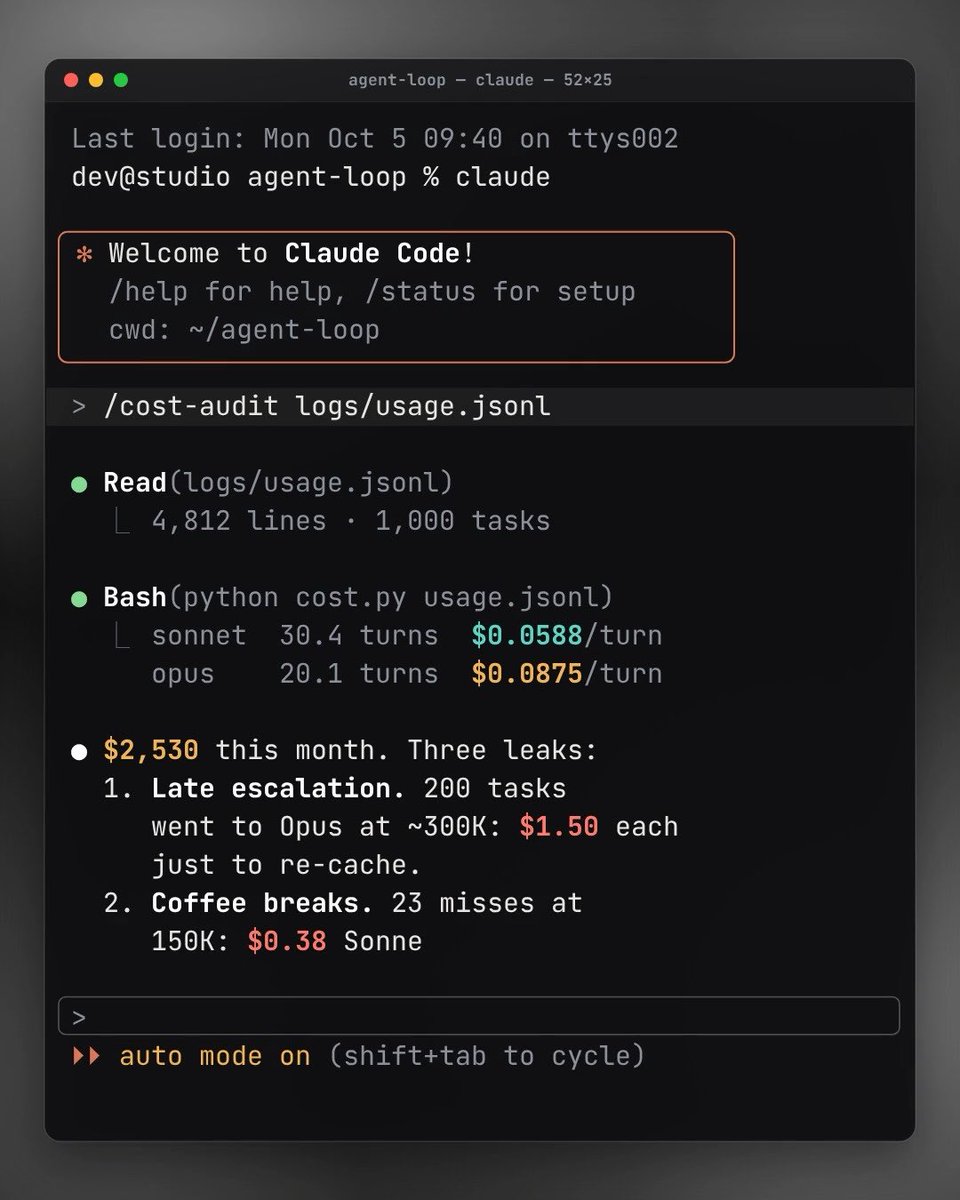
If your coding agent costs more than $2 per feature, read this. You're probably paying for 3 things you don't need: Opus reading every file in the repo. Opus making choices a $0.042 model can make. Simple tasks running on the most expensive model. Fix those 3 and the...

10,332 görüntüleme • 6 gün önce •via X (Twitter)

15 Yorum

Dvz | Python Architect profil fotoğrafı
Dvz | Python Architect6 gün önce

Bootcamp prompt hoarders celebrate 80% API bill reduction by stacking hybrid multi-model wrappers thinking they cracked the autonomous agent architecture. They stare at temporary token price deflation while remaining completely blind to the catastrophic cascading runtime latency tax hiding inside their nested orchestration loops. Shallow financial optimization is a dangerous proxy for real performance engineering. The moment your non-deterministic pipeline hits real-world concurrent session traffic, your lightweight routing gates choke on implicit output drift. Pulling un-profiled multi-tier models to bypass frontier token rates doesn't fix architectural fragility; it just route-forwards your processing debt and leaves your distributed backend infrastructure completely I/O blocked.

Mayor. profil fotoğrafı
Mayor.6 gün önce

good share buddy

Macro Bombastic profil fotoğrafı
Macro Bombastic6 gün önce

yeah the repo re-read is brutal, been there man

notgwapo profil fotoğrafı
notgwapo5 gün önce

seems like dialing things back a bit could save a ton. fr keeping it simple is underrated 🙏

Harry Tandy profil fotoğrafı
Harry Tandy6 gün önce

smarter model routing can save serious money without sacrificing quality

Abozar profil fotoğrafı
Abozar6 gün önce

Routing is the biggest lever, agreed. Two things to add from running agents in loops: a hard retry limit per step, and an escalation path so a weak answer from the cheap model goes to the strong one. Without the limit, the savings disappear when one step keeps retrying.

Ahmad profil fotoğrafı
Ahmad6 gün önce

the opus reading every file one got me lol

LordZeppelin profil fotoğrafı
LordZeppelin6 gün önce

Great read!

Shaoxiao | AI × 出海增长 profil fotoğrafı
Shaoxiao | AI × 出海增长6 gün önce

The $2/feature tax is usually three Opus habits: full-repo reads, enum picks, and trivial tasks. Default those to a cheap model; keep Opus for novel design. Routing policy is the product when overseas margins can't eat frontier tokens on every click.

雨婷聊座驾 profil fotoğrafı
雨婷聊座驾6 gün önce

charcloth trick changed my firekit forever

Aleena profil fotoğrafı
Aleena6 gün önce

Most coding agents waste money because they process more context than the task actually needs. Giving the right model the right context matters more than using the most expensive one. That's something we're thinking about at @jarvixdotlive too.

vansh patel | 10 products in 90 days profil fotoğrafı
vansh patel | 10 products in 90 days6 gün önce

routing the cheap yes/no checks off opus is the real cut. we waste so many frontier tokens on "is it done" loops that a tiny model could own

John Rood profil fotoğrafı
John Rood6 gün önce

the repo re-read is a context problem before it's a routing problem: the agent walks the tree because nothing durable tells it where things live. the biggest cut for us was a maintained project map, so it opens the three files that matter instead of re-walking the tree.

🏳️‍⚧️ real.dahlia profil fotoğrafı
🏳️‍⚧️ real.dahlia6 gün önce

Sounds like my code’s on a luxury diet, time to cut the caviar and stick to ramen.

Dynamics_01(大冰美式版 profil fotoğrafı
Dynamics_01(大冰美式版6 gün önce

the first one hurt me the most. I once watched Opus re-read my entire repo three times for a one-file change, and I could feel the bill ticking. splitting planner and executor onto cheaper models cut my costs to pocket change.

Benzer Videolar

THIS IS A PURE F*CKING GOLDMINE Anthropic just shared one of the best tricks for Claude Code. The idea: let Opus 5.5 write the plan as a script, and let a swarm of cheaper agents run it. Bigger jobs and way fewer Opus tokens, because the script holds the plan and Opus only sees the final answer. You just launch Claude Code like this: claude --model opus --effort ultracode here's the split: → Opus 5.5 turns your task into a workflow script → Haiku 5.5 agents scan every file in parallel → Sonnet 5.5 agents patch each fix in its own isolated copy → you stop burning Opus context on a hundred agent transcripts Opus only shows up at three moments: → writing the workflow before the run → reading the verified results after it → signing off before anything ships Opus plans. Haiku scans. Sonnet ships. JEV engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to JEV in milliseconds, and the big models only see the ones that split the full tree > Opus 5.5 runs the main session and writes the workflow > scan audits every file on Haiku 5.5 > edit patches each fix on Sonnet 5.5 in an isolated copy > verify cross-checks every finding on Sonnet 5.5 > Opus 5.5 reads only what survived verification > JEV routes micro-forks in milliseconds paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Run the main session on Opus 5.5 with ultracode on. 2. In every workflow, run read-only scan stages on Haiku 5.5 and edit stages on Sonnet 5.5, each edit in its own isolated copy. 3. Add one rule to CLAUDE.md: every finding gets an independent verifier agent before it's reported, and fix loops stop after two rounds with no progress. 4. Route fast deterministic forks (tool choice, path selection, retries) through JEV. Show me every change as a diff first. No edits until I say go." ↳ save it, it'll come in handy.

delost

388,662 görüntüleme • 5 gün önce

Production traffic is not uniform. You get a few requests that need your best model, but most are simple questions and lookups you can solve with cheaper, faster models. The most expensive mistake you can make today is sending every request to your strongest model. You need routing. Period. This is the simplest trick to improve the architecture of whatever you are building. Please, don't implement routing yourself. You don't have to. I'm currently working with TrueFoundry's Auto Routing. It reads each request, classifies it as simple, medium, or complex, and sends it to the model assigned to that tier. You have two choices: 1. Send every request to the free heuristic classifier to score signals such as technical vocabulary, code, prompt length, and multi-step reasoning. 2. Send the request to an LLM classifier when its difficulty requires a more nuanced judgment. The beauty of using routing is that nothing changes in your code. You still call a single endpoint model, but routing works behind the scenes to pair every request with the best possible model. TrueFoundry ran several experiments with two different setups: 1. Send every request to Claude Opus 2. Send every request to a router with Haiku, Sonnet, and Opus The first experiment ran 550 deterministically graded academic prompts through every setup. Auto Routing was 69% cheaper while retaining 98% of the baseline quality. The second experiment ran three production-shaped workloads through every setup, using user chats, developer chats, and long agent tasks. Auto Routing was 80% cheaper. Thanks to the TrueFoundry team for partnering with me on this post.

Santiago

15,543 görüntüleme • 1 ay önce