Navigation überspringen
I've always believed that intelligence should come from simple, general building blocks that learn…
0:00 / 1:18

I've always believed that intelligence should come from simple, general building blocks that learn…

Albert Gu

@_albertgu27.165 Follower

Auf X besuchen
7.381 LikesHerunterladenOriginalbeitrag

1.048.892 Aufrufe

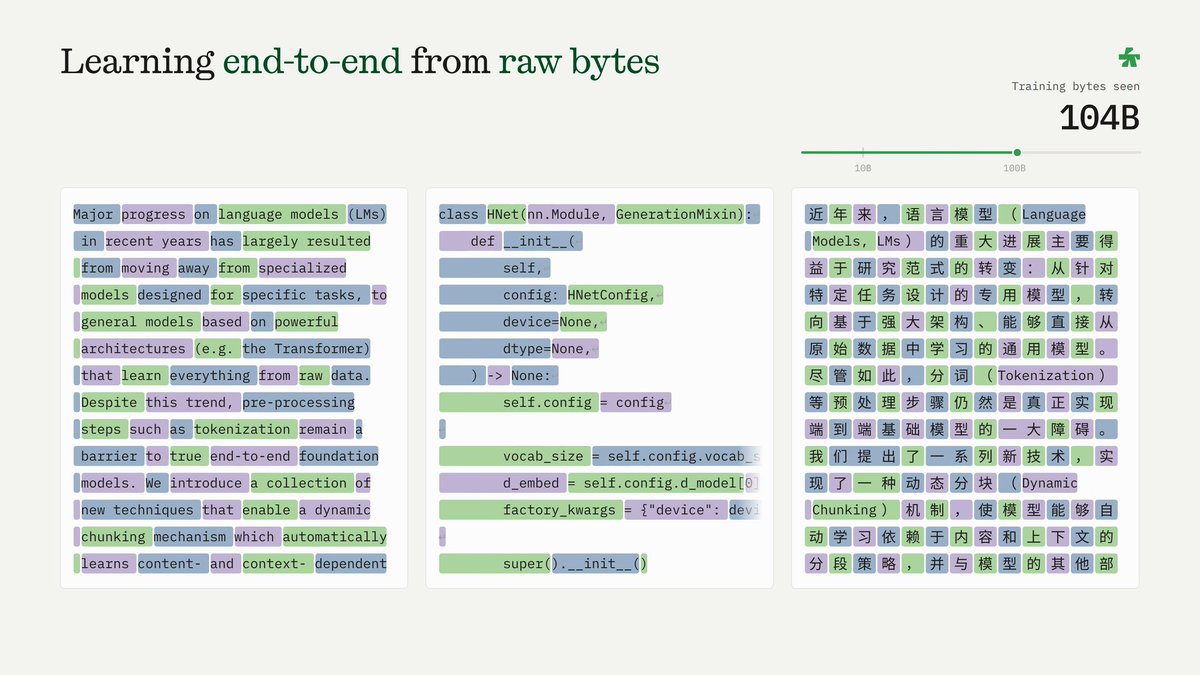
I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data. Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less? Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.

16 Kommentare

Kommentare aus dem Originalbeitrag auf X (Twitter)

  • Profilbild von Albert Gu

    @_albertgu

    Blog: Part 1 Part 2 (Voiceover created entirely by Cartesia's Sonic text-to-speech model!)

    67 Likes

  • Profilbild von Nathan (Quan) Zhou

    @quanathan_zhou

    This is the kind of work that makes me excited to be at @cartesia. Huge props to the team behind H-Nets~

    6 Likes

  • Profilbild von Justin Waugh

    @JustinWaugh

    So exciting to see h-net results! The In-context tokenization part is so cool - show's the real power of hnet imo. Feels like it's directionarlly a step on the path to a true continuous learner / infinite context.

    6 Likes

  • Profilbild von Karan Bania

    @karan_bania

    so cool to see it work on images and patchify background as one token

    2 Likes

  • Profilbild von Tim Shi

    @timshi_ai

    amazing

    1 Like

  • Profilbild von Saumya Verma

    @nikkuv5787

    bitter lesson never misses, we just keep forgetting it every hype cycle

    1 Like

  • Profilbild von Tommy

    @agneau123

    Raw bytes still force the hierarchy

    1 Like

  • Profilbild von hailports

    @hailports

    raw data, huh. language already comes pre-chewed by people. the real test is what happens where nobody bothered to name things.

    1 Like

  • Profilbild von Jonathan Chang

    @ChangJonathanC

    what happened here?

  • Profilbild von Charis Mitsakis

    @cmitsakis

    the efficiency jump is huge! the bitter lesson is always true

  • Profilbild von Chirag

    @chirag

    Other people have spoken of a cognitive core with search and tools. A lot of the initial wow came from the fact that some x million documents have been consumed and can be recalled verbatim. That's a different task from getting work done.

  • Profilbild von AI Quanting

    @AIQuanting

    What does staying at the byte level cost you at inference time?

  • Profilbild von Ir rev

    @1rreverant

    does any of the insights translate to image/video-gen?

  • Profilbild von Gravity Research

    @GravityRsch

    10x less compute is absurd

  • Profilbild von Nancy Xu

    @nancycxu

    Incredible work!!

  • Profilbild von Sophia Yang

    @sophiamyang

    beautiful!