Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

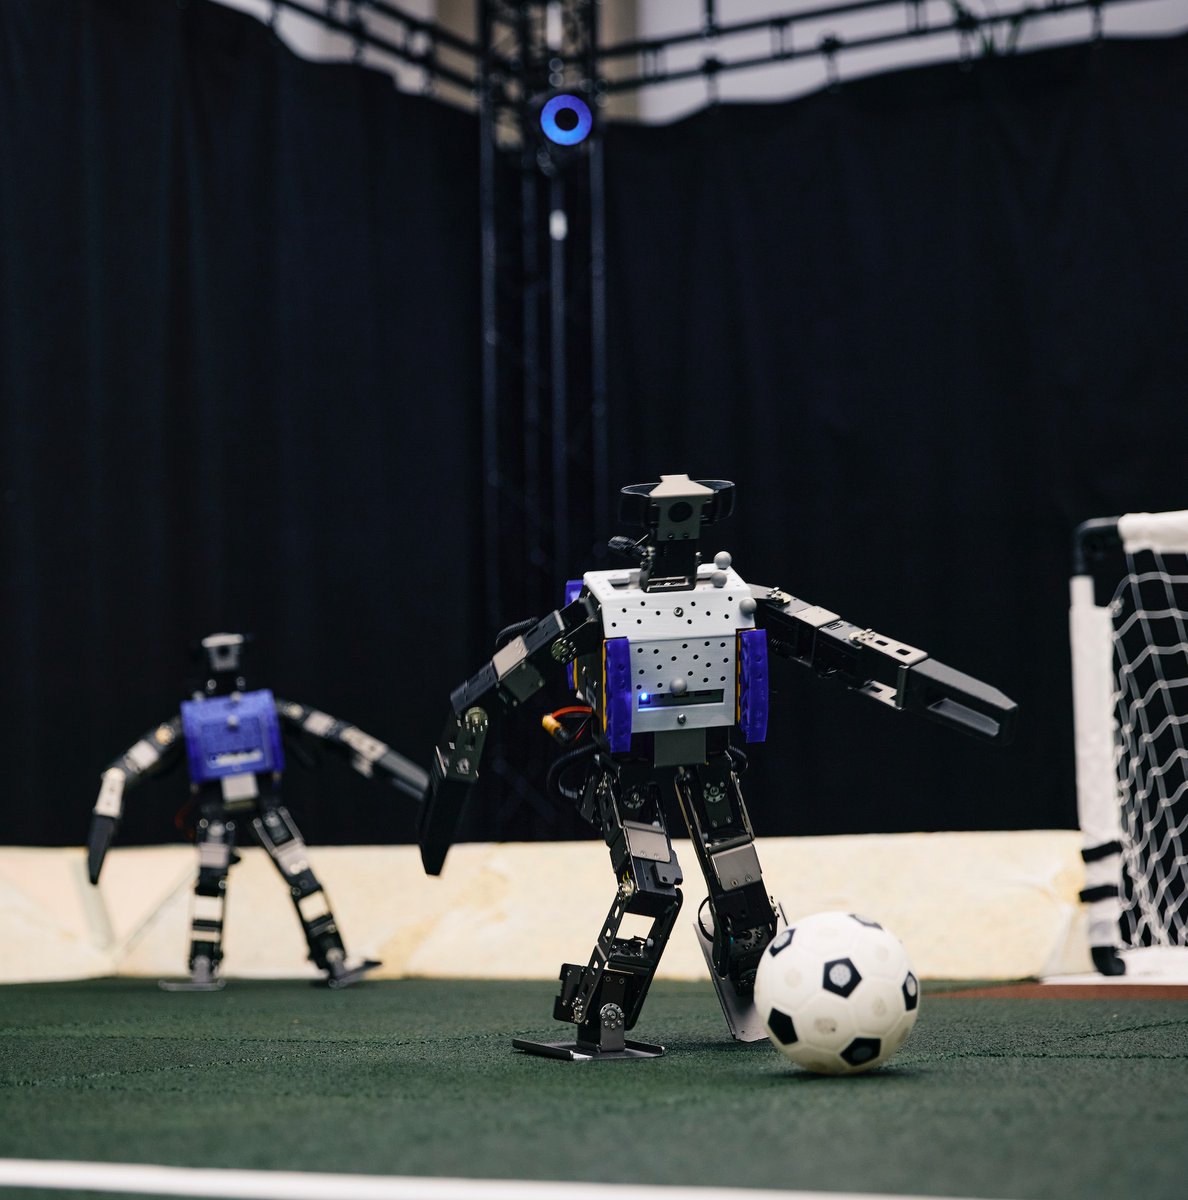
Learning Agile Soccer Skills for a Bipedal Robot with Deep Reinforcement Learning investigated the application of Deep Reinforcement Learning (Deep RL) for low-cost, miniature humanoid hardware in a dynamic environment, showing the method can synthesize sophisticated and safe movement skills making up complex behavioral strategies in a simplified one-versus-one...

293,474 görüntüleme • 3 yıl önce •via X (Twitter)

30 Yorum

Pablo Moncada-Larrotiz profil fotoğrafı
Pablo Moncada-Larrotiz3 yıl önce

I hope to see the best human team vs best robot team play in my lifetime. Like Deep Blue vs Kasparov but for football

kache profil fotoğrafı
kache3 yıl önce

super cool how they penalized it on torque/strain on its joints and got a smoother gait in the policy as a result

AgiDoomerAnon profil fotoğrafı
AgiDoomerAnon3 yıl önce

You are here.

murtaza profil fotoğrafı
murtaza3 yıl önce

I saw something similar but couldn't find it where , now i got it 👇

sam laki profil fotoğrafı
sam laki3 yıl önce

@yacineMTB Bruh how are they playing better than me

Julia (Blackhole) profil fotoğrafı
Julia (Blackhole)3 yıl önce

In terms of real-world dynamic humanoid locomotion this is nearly the best I've ever seen second only to Atlas, and this is on cheap stock hardware and with a fully automatically trained policy? Amazing work

Alberto Hojel profil fotoğrafı
Alberto Hojel3 yıl önce

I never knew something could be so adorable yet mind-blowing. Seems like RL is paying off.

Fabian Paischer profil fotoğrafı
Fabian Paischer3 yıl önce

What does "safe" refer to in this regard? The robots are consistently falling over Also, the only thing that appears to be dynamic in this environment while watching the video is the ball Are there any other dynamic aspects to it?

pranav profil fotoğrafı
pranav3 yıl önce

DeepMind are based out of London. Calling it soccer is a punishable offence!

My Art Ontario 🐢 profil fotoğrafı
My Art Ontario 🐢3 yıl önce

I want a robo baby yoda

SOPLECHNER SOPLECHNER profil fotoğrafı
SOPLECHNER SOPLECHNER3 yıl önce

Juegan mejor que la seleccion de Chile jajaja monos qls

7racker profil fotoğrafı
7racker3 yıl önce

Super toys are coming ☾

Sebastian Bitsch profil fotoğrafı
Sebastian Bitsch3 yıl önce

Fun watch, are they “stock” OP3 models?

Benny Johansson profil fotoğrafı
Benny Johansson3 yıl önce

Amazing and fun to watch 😀👍

Jinani profil fotoğrafı
Jinani3 yıl önce

FIFA 2030 in the making!

Jorge Villegas profil fotoğrafı
Jorge Villegas3 yıl önce

RIP Messi

Alexander Septian Arfe profil fotoğrafı
Alexander Septian Arfe3 yıl önce

@SaveToNotion #tweet #ai #ResearchPaper

Astro profil fotoğrafı
Astro3 yıl önce

It's football

lithium534 profil fotoğrafı
lithium5343 yıl önce

Very impressie.

Amit Khanna profil fotoğrafı
Amit Khanna3 yıl önce

That is one cruel lady, tripping that poor little robot like that.

Heather Brown profil fotoğrafı
Heather Brown3 yıl önce

I saw this on 60 minutes last week...too cool!

AU ⏸️⏹️▶️⏩️⏮️⏬️⏯️🔀🔁 profil fotoğrafı
AU ⏸️⏹️▶️⏩️⏮️⏬️⏯️🔀🔁3 yıl önce

@DotCSV

Darryl Mason profil fotoğrafı
Darryl Mason3 yıl önce

'I'm not playing on the same team as a fkng robot!' 'But that's who the crowds are coming to see! If we don't robot up the team, we lose supporters. The league wants this.' 'But they don't have the skills of human players!' 'They do know how to dive.' 'Yeah....that is true....'

🌞FORMATS profil fotoğrafı
🌞FORMATS3 yıl önce

@Wickedlander

Nico Bohlinger profil fotoğrafı
Nico Bohlinger3 yıl önce

When do we see DeepMind in RoboCup?👀

Furkan Gözükara profil fotoğrafı
Furkan Gözükara3 yıl önce

Nice

Long | 科技与商业沉思录 profil fotoğrafı
Long | 科技与商业沉思录3 yıl önce

@SaveToNotion #tweet #AIofPaper

Trist profil fotoğrafı
Trist3 yıl önce

awww adorable!

BabbleBones profil fotoğrafı
BabbleBones3 yıl önce

@yacineMTB This sparks joy

Rom_AI profil fotoğrafı
Rom_AI3 yıl önce

In the future, we will have World vs Robots in Wembley.

Benzer Videolar

Today, we're joined by Nikita Rudin, co-founder and CEO of Flexion to discuss the gap between current robotic capabilities and what’s required to deploy fully autonomous robots in the real world. Nikita explains how reinforcement learning and simulation have driven rapid progress in robot locomotion—and why locomotion is still far from “solved.” We dig into the sim2real gap, and how adding visual inputs introduces noise and significantly complicates sim-to-real transfer. We also explore the debate between end-to-end models and modular approaches, and why separating locomotion, planning, and semantics remains a pragmatic approach today. Nikita also introduces the concept of "real-to-sim", which uses real-world data to refine simulation parameters for higher fidelity training, discusses how reinforcement learning, imitation learning, and teleoperation data are combined to train robust policies for both quadruped and humanoid robots, and introduces Flexion's hierarchical approach that utilizes pre-trained Vision-Language Models (VLMs) for high-level task orchestration with Vision-Language-Action (VLA) models and low-level whole-body trackers. Finally, Nikita shares the behind-the-scenes in humanoid robot demos, his take on reinforcement learning in simulation versus the real world, the nuances of reward tuning, and offers practical advice for researchers and practitioners looking to get started in robotics today. 🗒️ For the full list of resources for this episode, visit the show notes page: 📖 CHAPTERS =============================== 00:00 - Introduction 04:07 - Is robot locomotion solved? 06:04 - Sim-to-real gap 08:58 - Adding semantics to policies 09:42 - Modular vs end-to-end architectures 10:29 - Planner model 12:21 - Adapting RL techniques from quadrupeds to humanoids 15:39 - Behind robot demos 18:09 - Humanoid robots in home environments 22:03 - Training approach 23:56 - VLA models 27:59 - Closing the sim-to-real gap 32:55 - Task orchestration using VLMs 36:38 - Tool use 38:10 - Model hierarchy 43:37 - Simulator versus simulation environment 44:57 - Combining imitation learning and reinforcement learning 46:42 - RL in real world versus RL in simulation 52:58 - Reward tuning and value functions in robotics 56:38 - Predictions 1:00:10 - Humanoids, quadropeds, and wheeled platforms 1:02:45 - Advice, recommended robot kits, and community pla

The TWIML AI Podcast

22,592 görüntüleme • 9 ay önce