正在加载视频...
视频加载失败
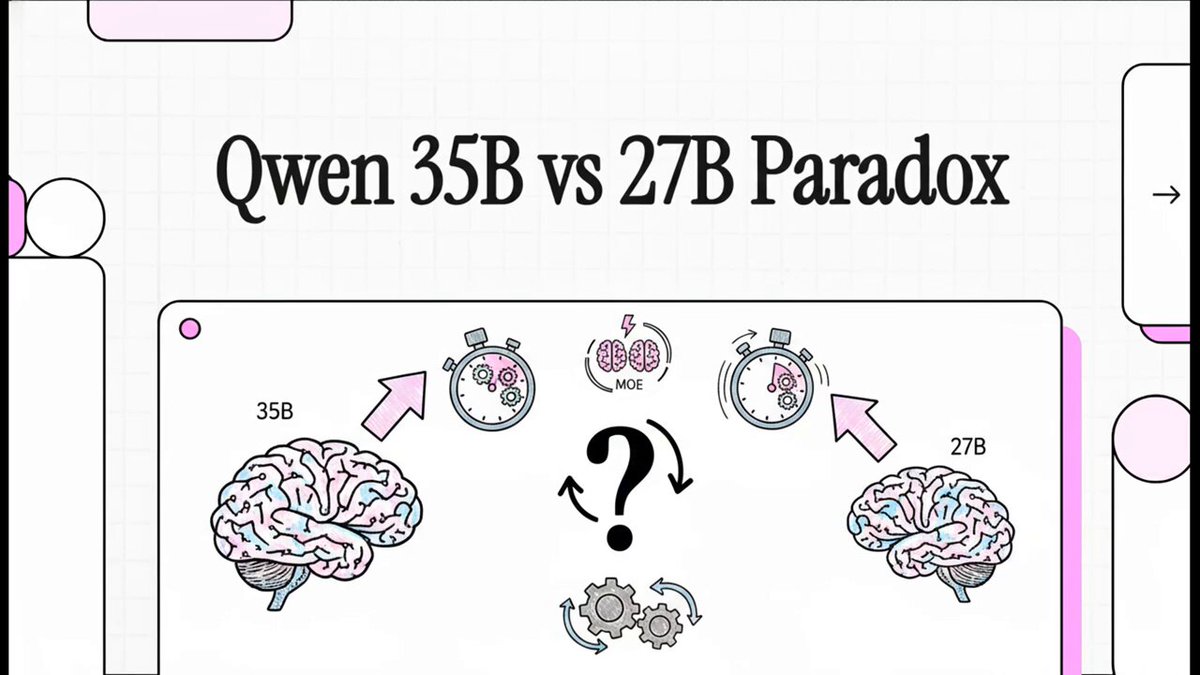
Need faster LLM inference without sacrificing accuracy? Speculative decoding can help. Choosing the right draft length and drafting method depends on your model, workload and hardware. We break down five practical guidelines for balancing throughput and latency.
0 条评论
暂无评论
原始帖子的评论将显示在这里