正在加载视频...
视频加载失败
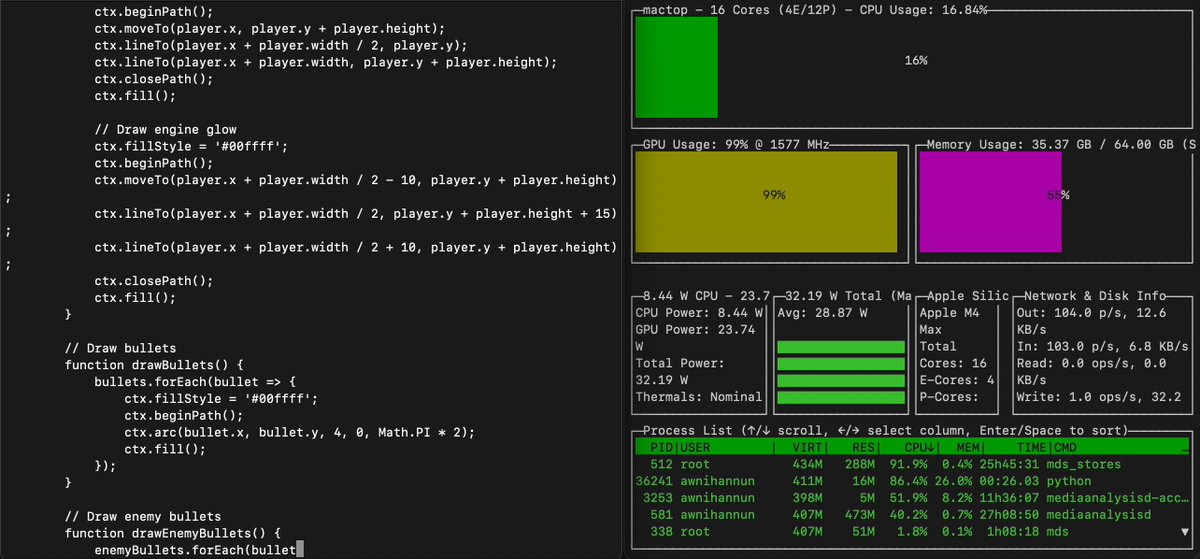
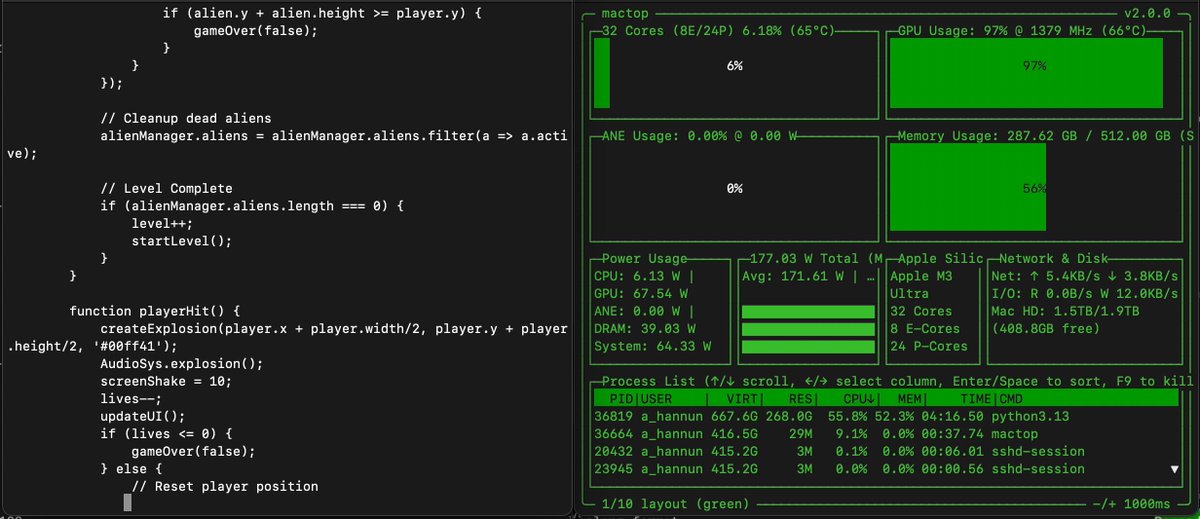
Running Ring 1T reasoning model on a single M3 Ultra with mlx-lm. It's quantized to 3.5 bits-per-weight. Uses 440GB and generated ~6k tokens at 18.2 toks/sec. Getting closer to GPT-5 at home.
18 条评论

Here's the space invaders game it generated:

I’m curious that for the same file size, does number of parameters always wins over high fidelity weights? For example, for is 500B 4bit model better than 250B 8bit model?
Subtle question which can depend a lot on the model so really the only way to answer is with evals. But from my experience most of the time 8-bit at a given file size is worse than a twice larger model at 4-bit in quality (which would have roughly the same size on disk). But the same is not true for 2-bit vs 4-bit.

Are you pleased with the quality at 3.5bits-per-weight?

Cool now show long context speeds 😉

Getting a 1T parameter model to run on a local machine is a huge milestone. The progress in quantization and frameworks like mlx-lm is making 'GPT-5 at home' feel closer than ever. Incredible work!

wow 18.2 tps is great. what's the typical TTFT?

Hey cool. Could I pair 2x 192gb and 3x 64gb Mac Studios & run it via mlx.distributed? Or is sharding still fixed equally per node?

Looking good! BTW, any reason MLX can't leverage the Neural Engine?

@PrinceSolotalk

Great Job! I can’t wait to try MLX Hi Awni, I’m Jingdong, collaborated with you at SVAIL. Ling/Ring/Ming are our team products

feel the agi

🤯🤯🤯

Nice! Whats the PP speed?

moar mobile models

Hm. This is what I’m getting 😁 Probably missing something important.
Yes it only works on main branch until the next release

what the