正在加载视频...
视频加载失败
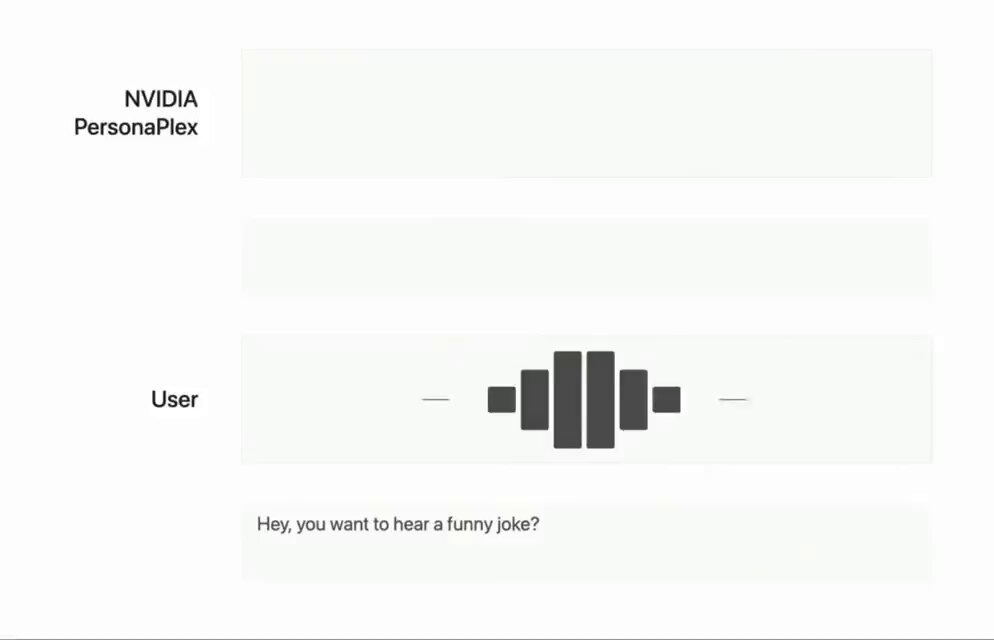
Smart Turn v2: open source, native audio turn detection in 14 languages. New checkpoint of the open source, open data, open training code, semantic VAD model on Hugging Face, fal, and Pipecat AI. - 3x faster inference (12ms on an L40) - 14 languages (13 more than v1, which... show more
46 条评论

This model is designed to be used together with a traditional VAD model for voice AI conversations. The voice AI pipeline typically looks like this: 1. A very short VAD timeout chunks the audio stream for the smart-turn model 2. Transcription runs in parallel 3. Transcription output is gated on turn detection before going to the rest of the pipeline The basic idea here is that you want turn detection to happen faster than transcription. It doesn't really matter how much faster, because you need "final" transcription fragments before you can run LLM inference. We're generally aiming for ~400ms end-to-end for turn detection. But other approaches are possible. For example, you can build pipelines that do greedy LLM inference on every transcription segment, and gate *that* output. This gets youe even lower latency, but cost is higher because you're throwing away all the LLM inference for every incomplete turn speech segment. Or, doubling down on the greedy inference approach, you can skip transcription entirely and feed every speech segment to a model capable of native audio inference. Again, throw away that output for speech segments that the smart turn model classifies as incomplete.
Blog post with code examples and docs pointers: - Repo with training code and development notes: - Weights: - Data sets: - Use the model for free in Pipecat Cloud + @FAL: - Here's a demo app hosted on @ vercel and Pipecat Cloud: - -

@huggingface @FAL @pipecat_ai So good!!

@huggingface @FAL @pipecat_ai Great release! Awesome job

@huggingface @FAL @pipecat_ai cool, definitely will try it

@huggingface @FAL @pipecat_ai very nice -- thanks for doing this work!

@huggingface @FAL @pipecat_ai Just tested the demo and wow, this is really good! Definitely great for use cases where people might take longer to respond but you wouldn’t want to preemptively respond!

@huggingface @FAL @pipecat_ai Wow, it's..perfect!

@huggingface @FAL @pipecat_ai Now that I’ve seen this, this has to be the new standard. Awesome 👏

@trydaily @huggingface @FAL @pipecat_ai beautiful, putting the new model in sage maker and testing now !
@trydaily @huggingface @FAL @pipecat_ai Can’t wait to hear any suggestions you have!

@huggingface @FAL @pipecat_ai 400ms ??!! 👀 good job dude
And there's still some low-hanging stuff in the FastAPI request path that could cut another ~100ms I think. Actual inference on an L40 is ~12ms. Marcus, who did the heavy lifting on this version but isn't on X, was focused on getting inference time down without sacrificing accuracy. I think the P50 could easily be under 300ms, including the 200ms VAD timeout, and the network request to do smart-turn inference.

@huggingface @FAL @pipecat_ai voice is better than gpt

@huggingface @FAL @pipecat_ai This is so good! Whats the TTS you are using? Sounds great too
@studiokensense @huggingface @FAL @pipecat_ai This is @cartesia !

@huggingface @FAL @pipecat_ai @bratrat we prototyped this last year haha

@huggingface @FAL @pipecat_ai We got to get you a hallway character :)
@huggingface @FAL @pipecat_ai > We got to get you a hallway character :) 100%. Let's do that!
@huggingface @FAL @pipecat_ai Ill dm you 🚀

This is awesome @kwindla. Do you have any tips for systematically getting an agent to consistently both respond AND do a tool call within a single turn? Example: I've noticed, especially with turns with MCP tool calls, an agent will say something like, "Yes I will do X. Please wait", and then end the turn before actually executing the tool call.

@huggingface @FAL @pipecat_ai What’s the animation?

@huggingface @FAL @pipecat_ai Impressive, but real-world comms data shows overlap ups accuracy... Context is key for robust solutions..
@huggingface @FAL @pipecat_ai > Impressive, but real-world comms data shows overlap ups accuracy... Context is key for robust solutions.. ?

@huggingface @FAL @pipecat_ai This is awesome 👏

@huggingface @FAL @pipecat_ai awesome results, will try out the script!

@ClementDelangue @huggingface @FAL @pipecat_ai Really impressive turn detection. I especially like pause handling. What about scenarios where the current speaker re-interrupts the other speaker? In this example the human interrupted the bot & it allowed it every time but in real life this isn’t always the case. Great Job 👍
Say more about what interruption cases you're thinking of? I've built a bunch of multi-participant + AI stuff and have done a fair amount of thinking about problems around when the AI should talk (or not) and how to handle various kinds of interruptions. Generally, I think there are some common "building blocks" but a lot of things are dependent on your specific use case. Having said that, 99% of people trying to build voice agents are doing "one human talking to one agent." That's what this model was primarily designed to facilitate. Does that make sense?
@ClementDelangue @huggingface @FAL @pipecat_ai It does, thank you for the details. I think I was thinking about when a speaker doesn’t feel like being talked over, should an agent have the capability to interrupt a human just like the human interrupted the agent? I’m not clear where this would actually b useful so may b moot
That's definitely something you can implement fairly easily with an inference step early in the Pipecat pipeline that's just a few-shot classifier (should the bot interrupt, based on what the user is saying now). That's the way I've done it, but there are other approaches too, of course.
@ClementDelangue @huggingface @FAL @pipecat_ai Interesting and straightforward. I honestly hadn’t thought about a simple solution like that. I guess the only trick is deciding why & when the agent can interrupt the human. Could be a fun thought exercise or project at some point.

@huggingface @FAL @pipecat_ai Any licensing restrictions for commercial use for the entire pipeline?
@huggingface @FAL @pipecat_ai Answered here just so it doesn't get lost in the threads:

@huggingface @FAL @pipecat_ai You’re too good 🚀🚀

@huggingface @FAL @pipecat_ai Cool! Why use Wav2Vec2 over Whisper?
Lots of prior art using the Wav2Vec2 family of models for classification tasks. This task feels more like a classification task than a generative task. Though you can definitely get to a good model for turn detection either way, I'm sure. We did a bunch of experiments with different architectures and base models. Wav2Vec2 had a good combination of useful pre-training to build on, flexible architecture that can accommodate a lot of different potential classification heads and other modifications, and the potential for very fast inference. I actually think an LSTM approach here makes a lot of sense, too. I could imagine going that direction if I had a *lot* more time to work on this!
@huggingface @FAL @pipecat_ai Makes sense - but whisper also supports classification right?
> whisper also supports classification right? I don't think so, in the general sense I'm talking about classification, here. You could use the output of the encoder layers only (ignoring the decoder layers entirely) plus a classification head. That would be an interesting thing to play around with! But that starts to look like you are re-inventing Wav2Vec2, maybe. Feel free to correct me if you know more about this than I do.
@huggingface @FAL @pipecat_ai I haven’t played around with it much but I do remember once training a model using WhisperForAudioClassification in the Transformers repo and I think it works exactly how you described it. IIRC it was much better than Wav2Vec2 for classification
Oh, cool. I can definitely imagine Whisper performing better as a base for some kinds of audio classification tasks. Maybe especially the larger model sizes. A primary requirement for this task is very fast inference time. I’m not super optimistic that it would be easy to get a classification-oriented Whisper variant down to 12ms inference on an L40, which is what this checkpoint of the smart-turn model clocks in at. But I could be wrong. My intuition after working on this problem for a bit is that I’d probably put effort into going smaller and continuing to improve the data sets. Rather than going bigger. I had fun hacking for a couple of days on the quick and dirty LSTM version that a contributor posted.

@huggingface @FAL @pipecat_ai This is great! One question - people usually break down their mobile number (& other known/fixed entities) into multiple parts. Can this model detect such turns? I'm guessing the current model does not use any such context
@huggingface @FAL @pipecat_ai this is huge, congrats team! btw have you ran this on a mac? whats the hardware requirement like?

@huggingface @FAL @pipecat_ai good job @kwindla , can the model know at which exact word it was interrupted and understand that the full sentence was not heard by the user?
> can the model know at which exact word it was interrupted and understand that the full sentence was not heard by the user? Yes! Word-level context fidelity for interruptions is the default in Pipecat if you are using a TTS that outputs word-level timing metadata. (Note that that's separate from the smart-turn logic. But having both working together in the same pipeline is great.)

@huggingface @FAL @pipecat_ai This is neat! We've used the following 2 metrics (beyond accuracy) to compare turn detection models: 1. Bot interrupting user rate (ideally 0) 2. Average time to respond when user is done speaking (ideally close to 0ms) Curious to see how this model will perform on our evals
@huggingface @FAL @pipecat_ai Let me know!