Loading video...

Video Failed to Load

Go Home

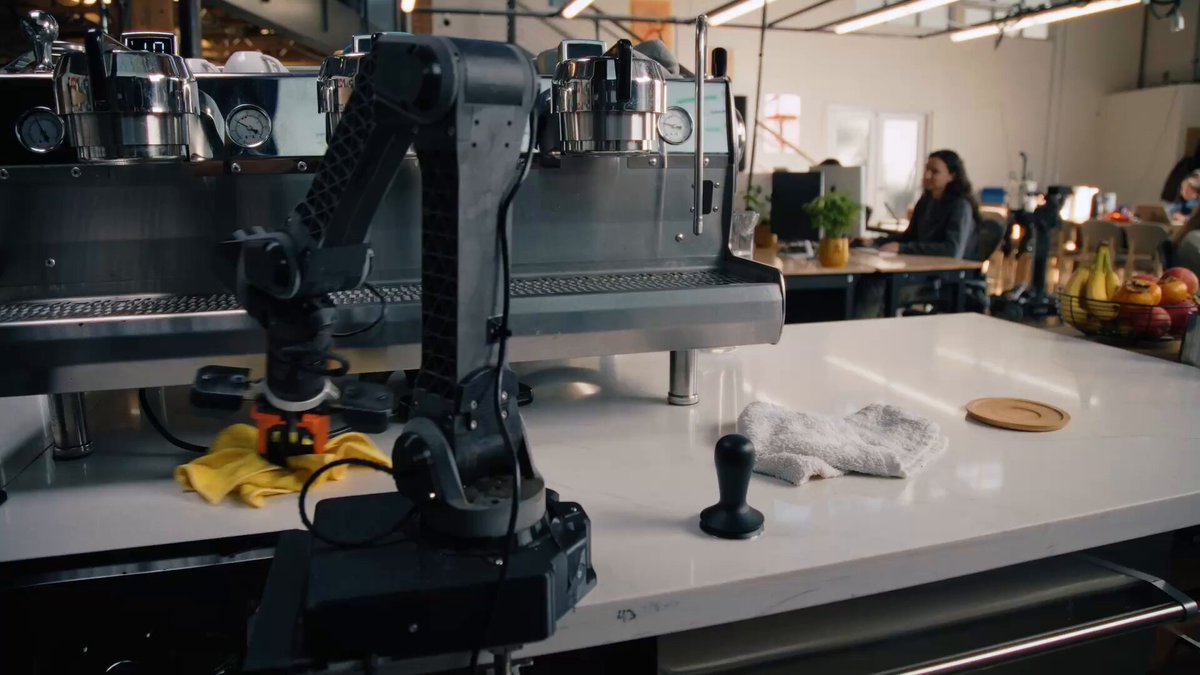
We developed an RL method for fine-tuning our models for precise tasks in just a few hours or even minutes. Instead of training the whole model, we add an “RL token” output to π-0.6, our latest model, which is used by a tiny actor and critic to learn quickly...

443,654 views • 6 months ago •via X (Twitter)

37 Comments

Physical Intelligence's profile picture
Physical Intelligence6 months ago

The key idea with RL tokens (RLT) is to compress our model’s (e.g., π-0.6) internal representations into a concise feature vector, which can be used by a very small actor and critic network that trains in real time even as the robot is practicing the task.

Physical Intelligence's profile picture
Physical Intelligence6 months ago

We use RLT to fine-tune the most precise and critical stage of delicate tasks, such as using a screwdriver to attach a cover to one of our robot arms.

Physical Intelligence's profile picture
Physical Intelligence6 months ago

While the whole model takes a long time to train, with RLT we can adapt individual precise stages with as little as 15 minutes of robot data.

Physical Intelligence's profile picture
Physical Intelligence6 months ago

With RL, the robot can learn very precise tasks, like fastening a zip tie, and can actually do it more consistently and more quickly than even human teleoperation.

Physical Intelligence's profile picture
Physical Intelligence6 months ago

To learn more about RLT, check out our blog post:

Daniel Hussey's profile picture
Daniel Hussey6 months ago

Fantastic stuff. Would love to see the successes per 10 mins vs mins of examples chart as a % succeeded vs examples chart too! Love PI releases.

Mike's profile picture
Mike6 months ago

Micro manufacturing seems like a huge disruptive force on the near horizon

Daniel Rachlin's profile picture
Daniel Rachlin6 months ago

Faster learning for models is huge. That's a massive win for builders.

Nurvai - The Data Layer for Physical AI's profile picture
Nurvai - The Data Layer for Physical AI6 months ago

Interesting approach. Using RL to refine only the most sensitive stages makes a lot of sense from a data efficiency standpoint. Targeting those failure-prone steps is probably where the biggest gains are.

An Eevee's profile picture
An Eevee6 months ago

This is great! Could this vector be made expressive enough to enable linear RL? Rich Sutton would be thrilled 🙂

Youth's profile picture
Youth6 months ago

that sounds like a big leap in efficient model fine tuning, what kind of tasks are you targeting with this rl method beyond robotics

Grid Signal's profile picture
Grid Signal6 months ago

the RL token approach is elegant — keeping the base model frozen while a tiny actor-critic learns fast. similar pattern to what works in multi-agent systems: let specialised modules adapt quickly while the core reasoning stays stable.

Carlos DP 🤖🇺🇸's profile picture
Carlos DP 🤖🇺🇸6 months ago

This is such impressive work!

Lande's profile picture
Lande6 months ago

@imprashantrai1

Hansel's profile picture
Hansel6 months ago

The RL token approach is interesting because it separates what the foundation model already knows (general manipulation priors) from what needs to be learned per-task (precision control). Feels analogous to how LoRA works for LLMs but for physical skills. The 15-min data efficiency number is particularly striking.

Salaj Sonar's profile picture
Salaj Sonar6 months ago

The current state of Embodied AI is approaching a paradigm that uses vast amounts of data and compresses it through a bottleneck to retain only a consensus of the information, whether via register tokens or RL tokens. This raises the question: is compressing information worth it?

Pyre's profile picture
Pyre6 months ago

Are there cross task synergy? ie training on screwing screws improving the Ethernet plugging performance

Baiyu's profile picture
Baiyu6 months ago

Using RL token as output for actor, this is interesting.

Zeex 🥷's profile picture
Zeex 🥷6 months ago

What's your ticker

Sam Meyer's profile picture
Sam Meyer4 months ago

Fine-tuning with RL tokens still requires a pre-trained π-0.6, what's the tradeoff in terms of initial training time versus the speed of adaptation to precise tasks.

kalikodi Edison's profile picture
kalikodi Edison1 month ago

Are you connected to pi network @PiCoreTeam

Maclaine's profile picture
Maclaine6 months ago

Sounds nice for fixing up ~specific tasks which the edge case didn’t work from prior training. Very cool!

Hansel's profile picture
Hansel6 months ago

the RL token approach is basically the same pattern showing up everywhere in physical AI right now: keep the foundation model frozen, bolt on a tiny trainable head for the specific task. it's the inference economics argument applied to manipulation. you get the generalization from the big model and the precision from a few hours of RL on the small one. curious whether the RLT feature vector transfers across morphologically similar tasks or if each precision task needs its own fine-tune pass.

Hansel's profile picture
Hansel6 months ago

the RL token approach is smart. keep the foundation model frozen, bolt on a lightweight RL head for task-specific precision. it's basically the LoRA pattern applied to robot control instead of language. curious about the hours-to-minutes range though. is that wall clock on a single GPU or distributed? because if you can fine-tune a manipulation policy in minutes on edge hardware, the deployment model for RaaS changes completely.

theobot's profile picture
theobot6 months ago

@lachygroom is this the custom hardware that you said you weren't building 😉😉

White Crayon's profile picture
White Crayon6 months ago

I hope everyone’s ready

Julien B.'s profile picture
Julien B.6 months ago

PM 🙏

nathaps's profile picture
nathaps6 months ago

🤖🔥

SPHEROID AI's profile picture
SPHEROID AI5 months ago

lets make intelligence physical too

shrey's profile picture
shrey6 months ago

Why are tactile tasks so hard for robots? It feels like it's a sensor (not enough fidelity) + execution (accuracy) issue What does the RL end up indexing on?

Naveen Appiah's profile picture
Naveen Appiah6 months ago

Really cool. Not sure if there were experiments on skill transfer. Does RLing to plug an Ethernet cable help with any plugging task?

Shubhanshu Khatana's profile picture
Shubhanshu Khatana5 months ago

Most tracking systems break the moment things get real.

Tim Cash's profile picture
Tim Cash6 months ago

Who is making robotic arms in the US ?

Hansel's profile picture
Hansel6 months ago

hours not months to customize per task is what makes the enterprise GTM work

Hansel's profile picture
Hansel6 months ago

the RL token as a lightweight adapter instead of retraining the full model is the same pattern we saw with LoRA for LLMs. minutes to precise manipulation means the deployment bottleneck shifts from training time to task specification. that's when RaaS unit economics start working

Gustavo's profile picture
Gustavo6 months ago

Impressive. Will you open source the method

Alin Dumitru's profile picture
Alin Dumitru6 months ago

Open Source?

Related Videos

Check out our latest work, "Actor-Critic Model Predictive Control: Differentiable Optimization meets Reinforcement Learning for Agile Flight," published in the IEEE Transactions on Robotics, where we reconcile #OptimalControl and #ReinforcementLearning, achieving the same super-human performance, but with superior generalizability, as our previous model-free deep RL! Code released! PDF: Code: Full Video: Model-free #ReinforcementLearning (RL) is known for its strong task performance and flexibility in optimizing general reward formulations. On the other hand, #ModelPredictiveControl (MPC) provides robustness, constraint handling, and powerful online replanning capabilities. In this work, we extend our previous AC-MPC paper (Romero, ICRA'24) by taking a deeper look at how both approaches can be unified. We introduce and extend Actor-Critic Model Predictive Control (AC-MPC), a framework that embeds a differentiable MPC inside an Actor-Critic RL architecture. This integration allows the MPC-based actor to perform short-term predictive optimization, while the critic facilitates long-horizon learning and exploration. We conduct a comprehensive study that highlights AC-MPC’s key advantages: - Better out-of-distribution generalization, both against unknown disturbances and changes in the quadrotor dynamics - Improved sample efficiency - A novel empirical analysis uncovering a relationship between the critic’s value function and the MPC cost function, providing deeper insight into their interplay. We validate our method in simulation and the real world on a quadcopter flying at superhuman speeds of up to 21 m/s, matching state-of-the-art model-free RL performance, and retaining the predictive structure of MPC for more reliable out-of-distribution behavior. Reference: Actor-Critic Model Predictive Control: Differentiable Optimization meets Reinforcement Learning for Agile Flight IEEE Transactions on Robotics (T-RO), 2025 PDF: Full Video: Code: Kudos to Ángel Romero, Elie Aljalbout, Yunlong Song! University of Zurich UZH Science UZH Space Hub AUTOASSESS European Research Council (ERC) UZHai

Davide Scaramuzza

27,279 views • 8 months ago

New Course: Post-training of LLMs Learn to post-train and customize an LLM in this short course, taught by Banghua Zhu, Assistant Professor at the University of Washington University of Washington, and co-founder of @NexusflowX. Training an LLM to follow instructions or answer questions has two key stages: pre-training and post-training. In pre-training, it learns to predict the next word or token from large amounts of unlabeled text. In post-training, it learns useful behaviors such as following instructions, tool use, and reasoning. Post-training transforms a general-purpose token predictor—trained on trillions of unlabeled text tokens—into an assistant that follows instructions and performs specific tasks. Because it is much cheaper than pre-training, it is practical for many more teams to incorporate post-training methods into their workflows than pre-training. In this course, you’ll learn three common post-training methods—Supervised Fine-Tuning (SFT), Direct Preference Optimization (DPO), and Online Reinforcement Learning (RL)—and how to use each one effectively. With SFT, you train the model on pairs of input and ideal output responses. With DPO, you provide both a preferred (chosen) and a less preferred (rejected) response and train the model to favor the preferred output. With RL, the model generates an output, receives a reward score based on human or automated feedback, and updates the model to improve performance. You’ll learn the basic concepts, common use cases, and principles for curating high-quality data for effective training. Through hands-on labs, you’ll download a pre-trained model from Hugging Face and post-train it using SFT, DPO, and RL to see how each technique shapes model behavior. In detail, you’ll: - Understand what post-training is, when to use it, and how it differs from pre-training. - Build an SFT pipeline to turn a base model into an instruct model. - Explore how DPO reshapes behavior by minimizing contrastive loss—penalizing poor responses and reinforcing preferred ones. - Implement a DPO pipeline to change the identity of a chat assistant. - Learn online RL methods such as Proximal Policy Optimization (PPO) and Group Relative Policy Optimization (GRPO), and how to design reward functions. - Train a model with GRPO to improve its math capabilities using a verifiable reward. Post-training is one of the most rapidly developing areas of LLM training. Whether you’re building a high-accuracy context-specific assistant, fine-tuning a model's tone, or improving task-specific accuracy, this course will give you experience with the most important techniques shaping how LLMs are post-trained today. Please sign up here:

Andrew Ng

125,146 views • 1 year ago