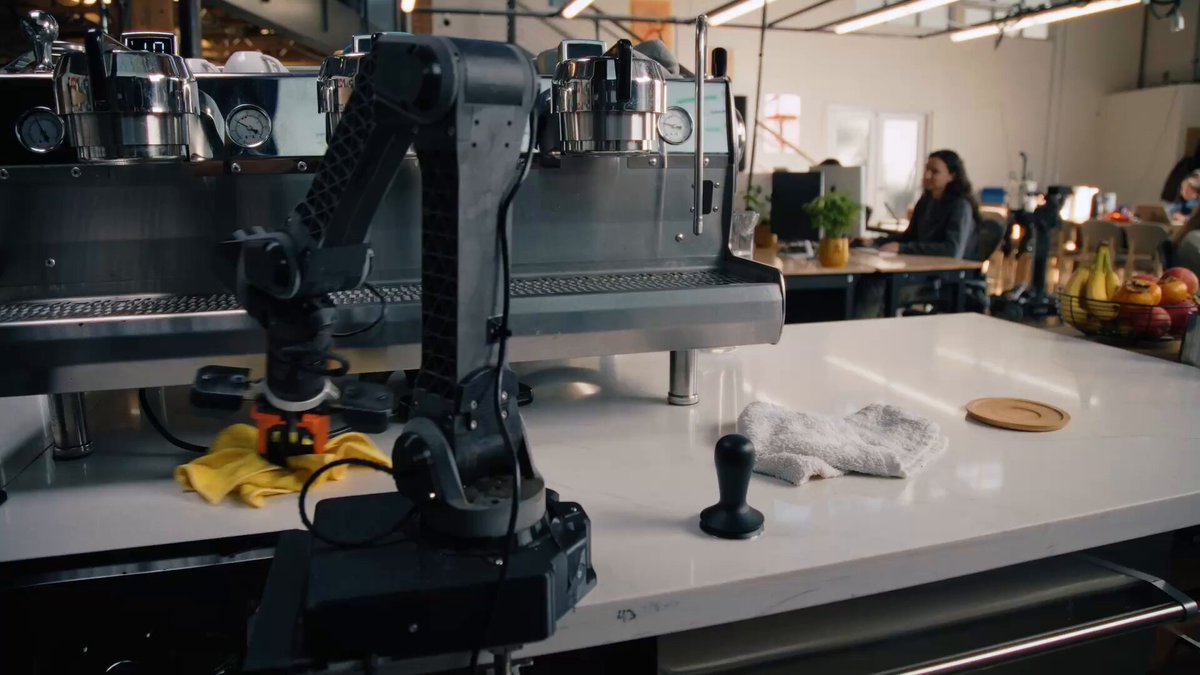
Video yükleniyor...
Video Yüklenemedi
We developed an RL method for fine-tuning our models for precise tasks in just a few hours or even minutes. Instead of training the whole model, we add an “RL token” output to π-0.6, our latest model, which is used by a tiny actor and critic to learn quickly... show more
443,654 görüntüleme • 6 ay önce •via X (Twitter)
37 Yorum

The key idea with RL tokens (RLT) is to compress our model’s (e.g., π-0.6) internal representations into a concise feature vector, which can be used by a very small actor and critic network that trains in real time even as the robot is practicing the task.
We use RLT to fine-tune the most precise and critical stage of delicate tasks, such as using a screwdriver to attach a cover to one of our robot arms.
While the whole model takes a long time to train, with RLT we can adapt individual precise stages with as little as 15 minutes of robot data.
With RL, the robot can learn very precise tasks, like fastening a zip tie, and can actually do it more consistently and more quickly than even human teleoperation.
To learn more about RLT, check out our blog post:

Fantastic stuff. Would love to see the successes per 10 mins vs mins of examples chart as a % succeeded vs examples chart too! Love PI releases.

Micro manufacturing seems like a huge disruptive force on the near horizon

Faster learning for models is huge. That's a massive win for builders.

Interesting approach. Using RL to refine only the most sensitive stages makes a lot of sense from a data efficiency standpoint. Targeting those failure-prone steps is probably where the biggest gains are.

This is great! Could this vector be made expressive enough to enable linear RL? Rich Sutton would be thrilled 🙂

that sounds like a big leap in efficient model fine tuning, what kind of tasks are you targeting with this rl method beyond robotics

the RL token approach is elegant — keeping the base model frozen while a tiny actor-critic learns fast. similar pattern to what works in multi-agent systems: let specialised modules adapt quickly while the core reasoning stays stable.

This is such impressive work!

@imprashantrai1

The RL token approach is interesting because it separates what the foundation model already knows (general manipulation priors) from what needs to be learned per-task (precision control). Feels analogous to how LoRA works for LLMs but for physical skills. The 15-min data efficiency number is particularly striking.

The current state of Embodied AI is approaching a paradigm that uses vast amounts of data and compresses it through a bottleneck to retain only a consensus of the information, whether via register tokens or RL tokens. This raises the question: is compressing information worth it?

Are there cross task synergy? ie training on screwing screws improving the Ethernet plugging performance

Using RL token as output for actor, this is interesting.

What's your ticker

Fine-tuning with RL tokens still requires a pre-trained π-0.6, what's the tradeoff in terms of initial training time versus the speed of adaptation to precise tasks.

Are you connected to pi network @PiCoreTeam

Sounds nice for fixing up ~specific tasks which the edge case didn’t work from prior training. Very cool!
the RL token approach is basically the same pattern showing up everywhere in physical AI right now: keep the foundation model frozen, bolt on a tiny trainable head for the specific task. it's the inference economics argument applied to manipulation. you get the generalization from the big model and the precision from a few hours of RL on the small one. curious whether the RLT feature vector transfers across morphologically similar tasks or if each precision task needs its own fine-tune pass.
the RL token approach is smart. keep the foundation model frozen, bolt on a lightweight RL head for task-specific precision. it's basically the LoRA pattern applied to robot control instead of language. curious about the hours-to-minutes range though. is that wall clock on a single GPU or distributed? because if you can fine-tune a manipulation policy in minutes on edge hardware, the deployment model for RaaS changes completely.

@lachygroom is this the custom hardware that you said you weren't building 😉😉

I hope everyone’s ready

PM 🙏

🤖🔥

lets make intelligence physical too

Why are tactile tasks so hard for robots? It feels like it's a sensor (not enough fidelity) + execution (accuracy) issue What does the RL end up indexing on?

Really cool. Not sure if there were experiments on skill transfer. Does RLing to plug an Ethernet cable help with any plugging task?

Most tracking systems break the moment things get real.

Who is making robotic arms in the US ?
hours not months to customize per task is what makes the enterprise GTM work
the RL token as a lightweight adapter instead of retraining the full model is the same pattern we saw with LoRA for LLMs. minutes to precise manipulation means the deployment bottleneck shifts from training time to task specification. that's when RaaS unit economics start working

Impressive. Will you open source the method

Open Source?