Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

We got extremely good at extracting a scanned from layer by layer 📋 - from printed fields, overlaid text, handwriting, and reviewer annotations. For instance, on an annotated permit, our Extract agents can extract out both the original permit number but also any drawn/handwritten annotations on top. they're also...

11,257 Aufrufe • vor 3 Tagen •via X (Twitter)

11 Kommentare

Profilbild von KShivendu 🌁
KShivendu 🌁vor 3 Tagen

Love your demo videos! 🔥

Profilbild von Mike|AI SOP Lab
Mike|AI SOP Labvor 3 Tagen

Can grounding point to an image region when handwriting has no source text layer? Keeping that link through extraction and retrieval would make a wrong field much easier to audit.

Profilbild von Jatin Garg
Jatin Gargvor 3 Tagen

the hard part with layered extraction is usually conflicting signals. how do you handle cases where handwriting corrections contradict the printed field value?

Profilbild von Cspoggers | AI notes
Cspoggers | AI notesvor 3 Tagen

for the permit example, a useful robustness check would be rescanning the same form at different resolutions and angles. score the value and its assignment to original/reviewer fields separately, so a readable number in the wrong field doesn't count as success.

Profilbild von Vikas(Vik) Malpani| AI for US Real Estate
Vikas(Vik) Malpani| AI for US Real Estatevor 3 Tagen

The annotated-permit case is exactly where generic OCR dies. In real-estate closings the binding change often lives in a handwritten margin note or a stamp, not the printed field. Nailing the annotation layer is what separates a demo from something a closing team trusts.

Profilbild von Robert
Robertvor 2 Tagen

Separating the annotation layer is the hard part. The edge case is an annotation that is itself wrong, a reviewer overwriting a correct printed digit. Keeping both values and flagging the disagreement beats letting the later layer win silently.

Profilbild von AgentSearch
AgentSearchvor 3 Tagen

Layer by layer is a good mental model for web pages too: the server HTML, then what JavaScript adds, then the overlays (cookie walls, modals, sticky nav). Most bad web extractions are the overlay layer winning. Picking which layer you actually want before parsing saves a lot of schema pain.

Profilbild von Ryan Nguyen
Ryan Nguyenvor 3 Tagen

This looks awesome.

Profilbild von ZANDAR 2610
ZANDAR 2610vor 3 Tagen

Will extract v2.5 be open source for use to use in our respective regions for data residency?

Profilbild von iafineden
iafinedenvor 3 Tagen

Layers are the hard part on web pages too. My reading app pulls the article out of messy pages, and when it grabs a comment or a sidebar by mistake, nothing looks broken. The quiz just asks about the wrong text and the reader probably blames themselves.

Profilbild von Joel Citron 🟦
Joel Citron 🟦vor 3 Tagen

My constraint on scanned forms is the handwritten layer — printed fields are table stakes, but the reviewer scribble is where our frontier calls quietly burn money and still miss the permit number. A 2x+ error cut at a fraction of the price is the kind of specialized agent I'd rather pay for than keep prompting a general model. How brittle is the grounding when the annotation ink crosses three fields at once?

Ähnliche Videos

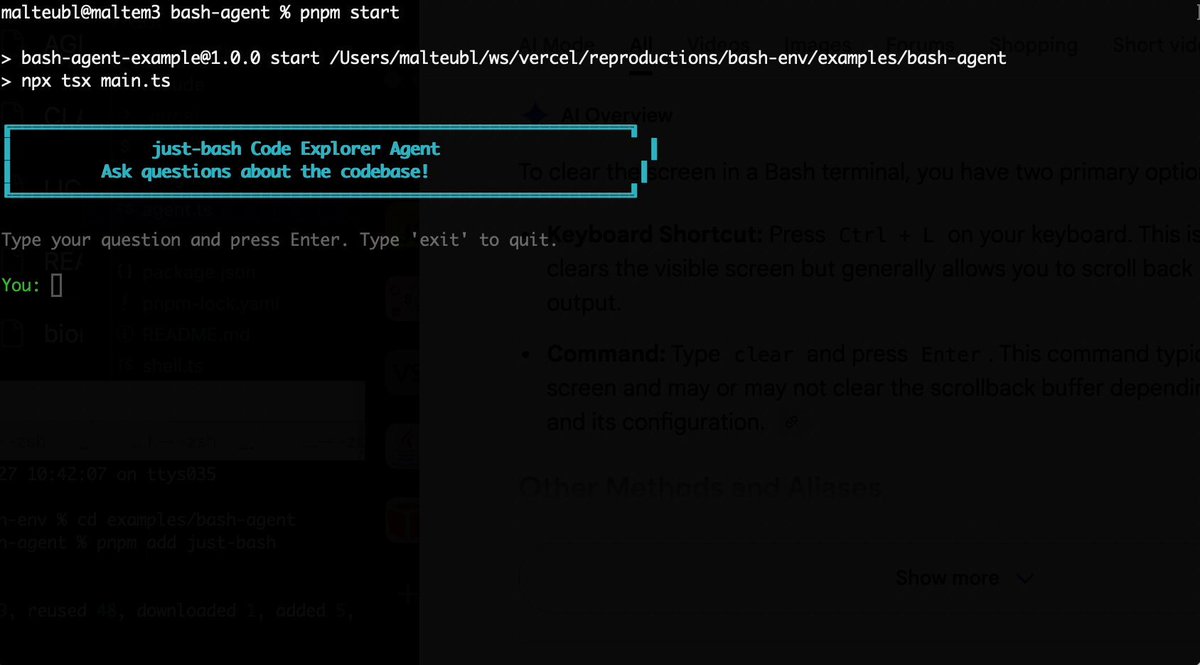
Bash is all you need! Which is why I'm introducing my holiday project: just-bash just-bash is a pretty complete implementation of bash in TypeScript designed to be used as a bash tool by AI agents. Because it turns out agents love exploring data via shell scripts, even beyond coding. It comes with grep, sed, awk and the 99th percentile features that an agent like Claude Code or Cursor would use. In fact, Claude Code can use it for secure bash execution. In the package - A bash-tool for AI SDK - A binary for use by yourself or your coding agents - An overlay filesystem to feed files to your agent securely - A Vercel Sandbox compatible API, so you can quickly upgrade to a real VM if you need to run binaries - An example AI agent that explores the just-bash code base using just-bash - I imported the Oils shell bash compatibility suite and just-bash passes a very good chunk What is interesting about this codebase: It was essentially entirely written by Opus 4.5. Coding agents love bash and they are good at reproducing it. They are also great at text-book recursive descent parsers and AST tweet-walk interpreters. That said, it is, like, a lot of code and I didn't read it all 😅. This is very much a hack, but it also seems to be _really_ useful. I haven't really found anything agents want to use that it doesn't support and it's fast and secure (caveats apply). It doesn't have write access to your computer and the filesystem is given a root that the agent cannot escape from. Find it at Related: Our recent blog post how we migrated our data analysis agent to bash tools and achieved incredible quality improvements The video shows the example agent investigating the just-bash code base

Malte Ubl

125,326 Aufrufe • vor 9 Monaten

🚨 THIS IS ACTUALLY INSANE Your AI agent can have access to the web. But if it can't reliably read what’s actually on the page, that access is almost useless. We looked at Firecrawl as the web layer for AI agents and the numbers are hard to ignore. The setup is simple: Give it a URL, search query, or website. Firecrawl handles the ugly part — crawling, scraping, rendering, extracting, and turning web content into something an AI model can actually use. The headline numbers: → 173,000+ GitHub stars → Search, scrape and interact with the web at scale → Supports web pages, PDFs, DOCX and other content → Structured data extraction for AI workflows → MCP support for connecting it directly to AI agents The workflow looks like this: Search → Scrape → Crawl → Extract → Feed the agent Three things stand out: 1. Scraping becomes an infrastructure layer Instead of maintaining your own pile of HTTP clients, parsers, browser automation and retry logic, you can treat web access as an API. 2. Agents get more than raw HTML The goal isn't just downloading a webpage. It's turning messy web content into clean context that an LLM can reason over. 3. The same layer works across different agent workflows Research agents. RAG pipelines. AI search. Competitive intelligence. Web-data extraction. The interesting shift: AI agents don't just need better models. They need better access to the information those models are supposed to reason about. Firecrawl is building that layer. Save this repo.

Vikas gupta

20,066 Aufrufe • vor 1 Monat