Загрузка видео...

Не удалось загрузить видео

На главную

We just launched Telnyx Decision Models in beta. AI agents make small judgment calls on every run. Is this caller asking for a refund? Which team owns this ticket? Is this incident urgent enough to page someone? Decision Models answers them in one API call. Send the context and...

866,125 просмотров • 18 дней назад •via X (Twitter)

Комментарии: 10

Фото профиля Humberto Figuera
Humberto Figuera18 дней назад

This is the thing I love from @telnyx, you guys adapt fast! 💪

Фото профиля matt.
matt.18 дней назад

need to chat with someone in the team would love to get some help integrating telnyx into @twentycrm

Фото профиля Telnyx
Telnyx18 дней назад

@twentycrm Hi Matt Just dmed you

Фото профиля Zeus ₿
Zeus ₿18 дней назад

Looking interesting, feel free to come inbox

Фото профиля Thierry
Thierry18 дней назад

I like the LCM that @tobi suggested better

Фото профиля Valeria Crypto
Valeria Crypto18 дней назад

Shall we collab? DM me! @telnyx

Фото профиля Ana de Armas
Ana de Armas18 дней назад

Can I get a follow back?

Фото профиля Lena Crypto
Lena Crypto18 дней назад

Hey, would love to connect with you guys. DM me.

Фото профиля Adam Reed
Adam Reed18 дней назад

Show me some stats! :)

Фото профиля Sophia Chen
Sophia Chen18 дней назад

Typed answers make branching easier to ship. Refund intent and urgent paging still have very different costs of error, so I'd give each decision its own review threshold and override path. One default confidence rule across all 64 questions would be hard to trust.

Похожие видео

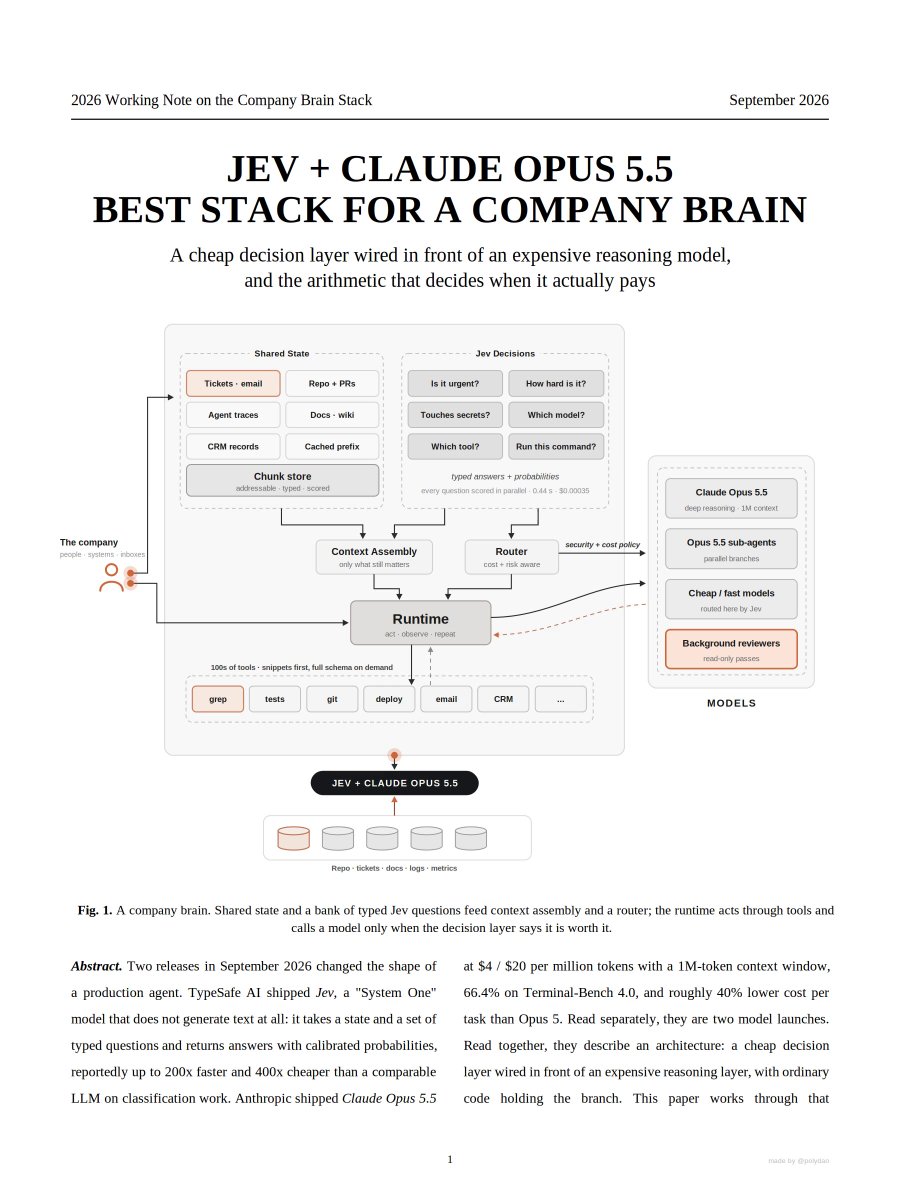
JEV + OPUS 5.5 IS INSANE FOR BUILDING A COMPANY BRAIN I pulled the whole architecture out of the TypeSafe and Anthropic docs and packed it into a 14-page PDF the 10 steps: 1. meet the pair > Opus 5.5 thinks, Jev decides, your code holds the branch 2. stop asking a text generator for a yes or no > Jev returns a typed answer with a calibrated probability in 0.44s for $0.00035 3. ask everything at once > Choice, Score and Noul run in parallel, so the fourth question costs almost nothing 4. branch on the number > 0.999 goes straight into the if statement. ~99% of turns end right here 5. stop routing blind > Opus 5.5 to Sonnet and back costs 5.84 against 3.32 for staying on 5.5 6. keep one context warm > cache reads at $0.20 per Mtok are 20x cheaper than a fresh load 7. escalate the hard part > the toughest 1% goes to Opus 5.5 with 1M context and 66.4% on Terminal-Bench 4.0 8. score every chunk on every query > keep whole, summarize or drop. the context gets rebuilt each turn 9. gate the actual command > every bash call gets classified before it runs, inside your own code 10. judge 100% of runs > $3.50 a day for 10,000 traces, and it matched the human label on all 500 decisions the result: a while loop that paid a frontier model for every tiny call turns into a brain that spends a fraction of a cent to notice and pays properly only when it has to think the person who brings this into their team walks into the budget meeting with the AI bill cut and the output up the PDF maps the company brain. the loop side of it - how Jev takes a Claude bill from $765 to $3 a month - is in the article below ↓

Mr. Buzzoni

103,282 просмотров • 15 дней назад

Jev is cool. So is it's OSS companion, Laya. The Latest Cool Thing In AI™ tends to get a lot of hype, sometimes without everyone even understanding it. So... what is this thing? Jev is an AI model that consumes input and produces output VERY differently than chat, claude, grok. The input is two things: 1) Text state to assess. Email, html, code, whatever. 2) A set of questions which will be asked about the attached state. The canonical example from TypeSafe's docs is to identify the urgency of a support ticket. We pass the model the customer text + a single noul question "is this urgent?". Jev returns a full set of JSON. This JSON is not generated with token-by-token autoregression. Jev is not trained to produce sequences of text tokens, rather to answer questions, and guarantees well-formed responses. In the example below, we see it produces a 0.99 probability (on a 0-1.0 scale) that the answer is "yes." Jev supports exactly three types of questions (seconds example in video): a) Noul: 0–1 probability that the answer to a yes/no question is "yes." b) Choice: Ask question with pre-defined set of answers. Jev chooses the best and assigns probabilities to each. c) Score: Ask question with pre-defined scale of answers. Jev produces a position on the scale. Jev computes answers for all questions in parallel, making responses super fast even for many questions in a single request. This might seem like a narrow set of capabilities, but in the right contexts leads to incredible potential. It also makes for a useful API / primitive for programming, since the outputs are... *ahem*... type-safe and predictable in structure. Jev is not going to replace LLMs for writing your code, auto-generating your docs, or being at the core of an agent harness. But Jev IS incredibly cool, and will be used to build a lot of amazing tech. Hope this helps.

Ben Dicken

40,810 просмотров • 23 дней назад

Redis built a cache that cuts LLM costs by 90%! Production LLM apps do not receive completely new questions every time. A customer-support assistant might receive all three of these: - "Can I get a refund after buying the monthly plan?" - "Is the monthly subscription refundable?" - "Can I cancel the plan and get my money back?" The wording is different, but the underlying question and its answer remain the same. Yet LLM apps process every version as a new request. They assemble the prompt, send it to the model, and generate an answer that may have already been generated. Prefix caching reduces part of these repeated calls. When requests begin with the same system prompt or context, the model can reuse the KV states already computed for that shared prefix. But the request still hits the LLM. The new tokens must be processed, and the complete answer must still be decoded. So even with a prefix-cache hit, there's another generation call involved. To solve this, instead of only caching computation inside the model, the application can cache the generated response outside it. When another question arrives, the system embeds it and compares it with previously answered questions. If it finds a sufficiently close match, it returns the stored response without invoking the LLM again. A cache hit removes the input tokens, output tokens, and decoding time associated with another LLM call. In practice, it is important to decide which questions can safely share an answer since a production setup needs well-tuned similarity thresholds, expiration policies, data isolation, and monitoring for incorrect matches. If you want to use this in practice, Redis already implements it as a managed service called Redis LangCache. Under the hood, it generates embeddings, searches previous responses, and returns a matching answer before another model call occurs. Redis also handles access scopes, custom filtering, TTL and eviction controls, and cache monitoring through Redis Cloud. I built an interface to compare it against direct LLM inference. The video below shows this in action, and I worked with Redis on this post to put this together. For the paraphrased question in my run, direct inference took 2.232 seconds and consumed 514 input tokens plus 250 output tokens. Redis returned the earlier response in 0.37 seconds with zero LLM input or output tokens. That was roughly 6x faster in this run. Redis reports API cost savings of up to 90% and cache-hit responses up to 15x faster. The actual result depends on how much safe repetition exists in the workload. You can try Redis LangCache here: If you want to dive deeper, I have already written a detailed breakdown of KV, prefix, prompt, and semantic caching in the article quoted below. This demo builds on the final technique and shows it running in practice. Read it below.

Avi Chawla

166,230 просмотров • 1 месяц назад

Qwen3.8-27B running at full BF16 on a free Kaggle TPU is kind of ridiculous. No quantization. No tiny context window. No expensive GPU instance. Just Qwen3.8-27B running on a Kaggle TPU v5e-8. The reported numbers: ~130 tok/s decode ~10,000 tok/s prefill 262K context That prefill number is especially wild. You can throw a huge amount of code or context at the model and ingest it extremely quickly, while still getting around 130 tokens per second during generation. And because it’s running in full BF16, you’re not relying on an aggressive quant just to make the model fit. But the really interesting part isn’t even the raw throughput. You can expose it as an OpenAI-compatible endpoint. That means you can plug the model into tools that already understand OpenAI-style APIs. Claude Code. Codex. OpenCode. And other compatible clients. So the workflow becomes pretty simple: Spin up the Qwen3.8-27B endpoint on Kaggle. Point your coding tool at the API. And suddenly you have a 27B coding model sitting behind the same interface you’d normally use for hosted models. The 262K context is also a huge deal for agentic coding. Large repositories can fit into a single context. Long conversations don’t need to be constantly trimmed. And tools can feed much more information back to the model without hitting a tiny context ceiling. The fact that this can be built around a free TPU environment is what makes this especially interesting. We’re getting to a point where experimenting with serious open models doesn’t always require owning a $2,000 GPU or paying for a large cloud instance. Free compute + open weights + an OpenAI-compatible API + existing coding agents. That’s a pretty powerful combination. Qwen3.8-27B is already an interesting model. Running the full BF16 version at ~130 tok/s with 262K context on free Kaggle TPU compute makes it a lot more interesting.

FHILY👑

35,910 просмотров • 1 месяц назад

Introducing PhoneLLM, an open model for voice agents. GPT 5.6 Terra performance on typical voice agent tasks at 1/3 the latency and 1/18 the cost. For voice agents, we need models that are both very low latency and very good at tool calling and instruction following. There's a trade-off here, and we often have to compromise on either latency or capability when building voice agents. With PhoneLLM (and the training and data stack that made this model possible) we're fixing this problem. For the last couple of years, most of the effort in frontier model development has gone towards leveraging test-time compute. Which is awesome! Models of all shapes and sizes are available that perform really, really well ... if you have "thinking" turned on for your model. But if you need your agent to respond at voice conversation speed, you can't use thinking models. PhoneLLM is a full-weights fine-tune of NVIDIA Nemotron Nano 30B. We trained on a wide range of real-world telephone and customer support use cases. The training focused on taking the excellent Nano 30B base capabilities and teaching the model to do typical voice agent tasks with thinking disabled. The results are really good: accurate tool calling and concise, on-topic responses in long conversations. And fast: TTFAT measured server-side is <100ms if you run PhoneLLM on a lightly loaded B200. :-) But seriously, when we characterize model latency, we do it with full, end-to-end, batched request simulations using real Pipecat voice agent pipelines. You can serve more than 80 concurrent agents on a single B200 with P95 end-to-end TTFAT <600ms. Including network overhead. That's an LLM cost-per-minute around $0.0025. (1/4 of a cent.) At a latency lower than any third-party API offers today. More details about this model, including weights on Hugging Face, how to spin it up with one click on Modal, and a starter project repo you can clone, are in the thread ...

kwindla

333,658 просмотров • 1 месяц назад