Video wird geladen...
Video konnte nicht geladen werden
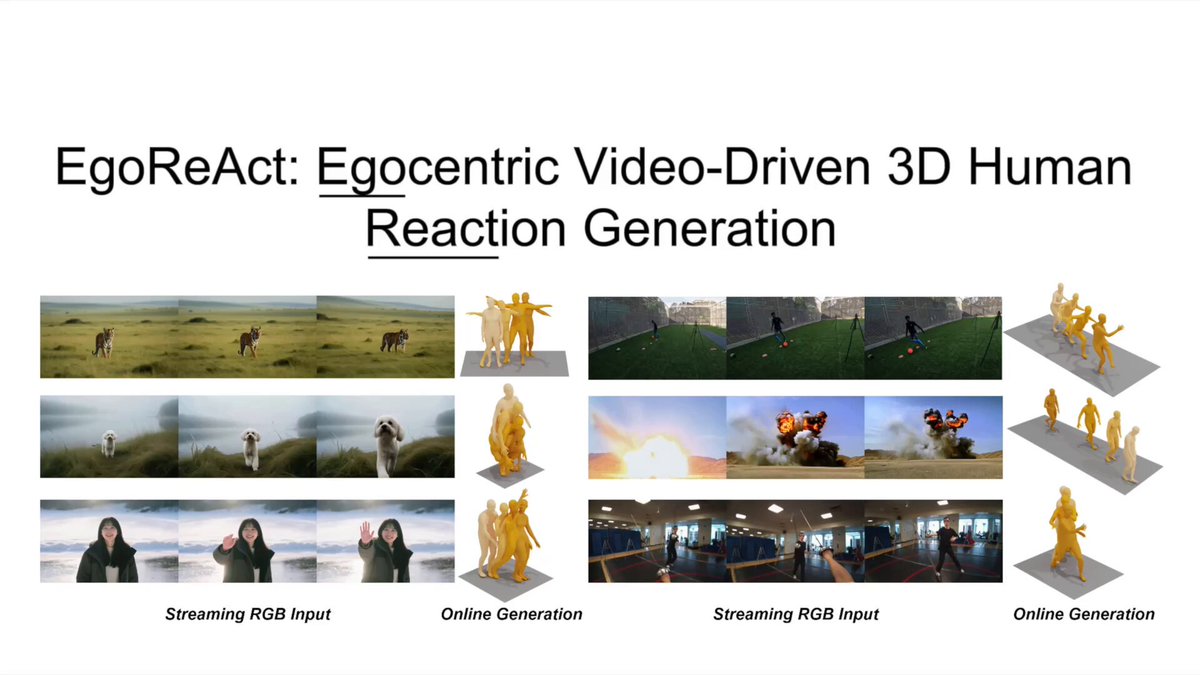
We will make a presentation of "Developing Vision-Language-Action Model from Egocentric Videos" at TuI1I.167, 9:00-10:30 6/2, #ICRA2026 We pretrain our robot policy from solely egocentric videos, and it works with ALOHA Stationary by lab-scale teleoperation-based finetuning!
10,492 Aufrufe • vor 4 Monaten •via X (Twitter)
1 Kommentare

Shuhei Kuritavor 4 Monaten
Project page: Paper: Code: