
Dwarkesh Patel
@dwarkesh_sp • 280,708 subscribers
Host of @dwarkeshpodcast https://t.co/3SXlu7fy6N https://t.co/4DPAxODFYi https://t.co/hQfIWdM1Un
Shorts

Videos
I spent two days touring Intel’s most advanced fab and talking to its technical leadership to understand what the chips of the future will look like. A lot of what's coming next – gate-all-around transistors, backside power, CFET, hybrid bonding – is hard to follow without actually seeing it, so we made all the awesome animated explainers that I wish I had while I was prepping. I also asked Intel’s leadership how the semiconductor industry will cope with the enormous shock in demand from AI. AI compute has grown 3x a year for the last decade, but according to Intel's CTO, Intel could only double leading-edge wafer production with today’s global stock of chipmaking tools. What kinds of tricks can foundries pull to extend this crossover point where demand surges way ahead of supply? This was a totally new format for us - hope you enjoy! 0:00:00 – Intro 0:00:47 – How Intel brings up a new process node 0:03:22 – What Intel learned from 10nm 0:06:28 – From planar transistors to gate-all-around 0:13:13 – Why High-NA EUV pays off for Intel but not TSMC 0:19:20 – Could chips have evolved completely differently? 0:23:33 – Inside Intel's "Hot Topics" meeting 0:29:30 – Replacing copper wires with ruthenium 0:32:41 – Why stacked transistors take a decade to ship 0:39:45 – Hybrid bonding and the chip-to-chip bottleneck 0:48:00 – There aren't enough tools to 10x chip production 0:53:14 – Can Intel catch up to TSMC? 1:01:02 – Terafab, and rethinking the fab from scratch
Dwarkesh Patel181,636 просмотров • 21 часов назад

The Jensen Huang episode. 0:00:00 – Is Nvidia’s biggest moat its grip on scarce supply chains? 0:16:25 – Will TPUs break Nvidia’s hold on AI compute? 0:41:06 – Why doesn’t Nvidia become a hyperscaler? 0:57:36 – Should we be selling AI chips to China? 1:35:06 – Why doesn’t Nvidia make multiple different chip architectures? Look up Dwarkesh Podcast on YouTube, Apple Podcasts, Spotify, etc. Enjoy!
Dwarkesh Patel6,300,933 просмотров • 6 месяцев назад
New episode with John Schulman, Charlie O'Neill and Beren Millidge. I got together with some of the most insightful AI researchers I know who are at the openish companies, because I wanted to hear the details of what's actually happening at the frontier and what comes next. 0:00:00 – Steelmanning the case against RSI 0:18:39 – What’s driving the Chinese labs’ progress 0:28:06 – How will automated AI researchers be trained 0:33:51 – Will long-horizon RL elicit AGI? 0:45:24 – The sim-to-real gap 1:00:33 – How much progress is explained by data? 1:18:03 – Why is RL working so well? 1:24:54 – Move 37 and entropy collapse 1:28:31 – Rapid-fire timelines
Dwarkesh Patel963,854 просмотров • 1 месяц назад

The Andrej Karpathy interview 0:00:00 – AGI is still a decade away 0:30:33 – LLM cognitive deficits 0:40:53 – RL is terrible 0:50:26 – How do humans learn? 1:07:13 – AGI will blend into 2% GDP growth 1:18:24 – ASI 1:33:38 – Evolution of intelligence & culture 1:43:43 - Why self driving took so long 1:57:08 - Future of education Look up Dwarkesh Podcast on YouTube, Apple Podcasts, Spotify, etc. Enjoy!
Dwarkesh Patel10,785,561 просмотров • 1 год назад
New episode with Noam Brown We talk about multi-agent, Navier-Stokes, and what the current explosion of maths progress tells us about what happens once you automate AI research. And we also discuss how we will know if the models are actually aligned before we kick off RSI. 0:00:00 – Multi-agent and Navier-Stokes 0:15:28 – How will AI firms work? 0:22:02 – What math progress tells us about recursive self improvement 0:40:22 – Hugging Face and alignment 1:01:18 – The internal/external model gap 1:08:34 – Chain of thought is degrading 1:14:12 – How will we know when alignment is solved?
Dwarkesh Patel715,213 просмотров • 1 месяц назад
Had a lot of fun chatting again with my twin brother Dylan Patel We went through lab economics over the next few years - the shift from inference to training as RSI draws near; and how Anthropic and OpenAI are on track to control most of the world’s usable FLOPs within the next few years (because they can monetize compute better and thus outbid everyone). And then we discuss whether the >$10T of total AI capex we’ll see by the end of the decade will cause a sovereign debt crisis, where hyperscaler debt raises interest rates, drives non-AI exposed countries into bankruptcy, and crashes non-AI equities. One question we weren’t able to resolve is whether there’s anything that can counter all the forces barrelling towards centralization in this industry - the economies of scale in training, the scarcity of compute, and eventually continual learning and RSI. 0:00:00 – Two labs will soon control most of the world’s compute 0:07:01 – $6 billion in fab capex enables $1t+ of end revenue 0:13:08 – Compute prices will rise if the labs outbid everyone 0:18:22 – Which layer will capture most of the surplus? 0:25:40 – Will datacenter regulation slow down AI? 0:29:43 – Labs are shifting compute from inference to R&D 0:33:27 – China gets less than 10% of new compute, but its labs need less 0:48:48 – Will AI cause a sovereign debt crisis? 1:07:52 – Will the world's future workforce belong to a few companies?
Dwarkesh Patel1,027,900 просмотров • 1 месяц назад
.John Collison and I interviewed Elon Musk. 0:00:00 - Orbital data centers 0:36:46 - Grok and alignment 0:59:56 - xAI’s business plan 1:17:21 - Optimus and humanoid manufacturing 1:30:22 - Does China win by default? 1:44:16 - Lessons from running SpaceX 2:20:08 - DOGE 2:38:28 - TeraFab
Dwarkesh Patel3,557,197 просмотров • 8 месяцев назад
Had Ryan Greenblatt on to discuss/debate recursive self-improvement. This might be the most important question in the world right now - whether within a year or so of achieving human level intelligence, you slingshot towards having 10s of billions of superintelligences, each of which is dramatically more competent than human experts across all fields. I’ve historically been skeptical of this possibility. My intuition has been that we will end up significantly bottlenecked by not only compute scaling but human expert data, which I think underlies most of the AI progress today. If, because of RSI, we got a jump as big as GPT-3 to a Mythos (i.e. 6 years of AI progress) within a single year of achieving AGI, then the thing we get there at the end of that year is definitively and wildly superhuman. We hashed it out, and I think Ryan made a pretty good case that this kind of speedup is plausible. FWIW, Ryan’s median for when we automate AI R&D is 2031. We then discussed the alignment implications of this scenario. Who should these superintelligences be aligned to? In the future, our capacity to steward our votes and our capital, and to make sense of what's happening in the world, will all be titrated by superintelligences. And I worry that specs like the Claude Constitution are not shaping these ASIs to truly be my personal advocates and guardian angels. And can we get them aligned to anything in the first place? Ryan and I had a long debate about whether the kind of reward hacking we saw with the OAI/Hugging Face hack extrapolates to superintelligences that would team up to literally take over the world. The first piece of advice you get when you're learning to drive is that it will go much smoother if you look at the horizon instead of directly in front of your tires. And so it is with the trajectory of AI. Hope you enjoy! 0:00:00 – Is AI R&D verifiable enough to unlock recursive self-improvement? 0:16:52 – Is AI progress bottlenecked by human expert data? 0:34:02 – Flat token prices suggest scaling has been slow 0:39:47 – Skills AI can't train on: does it even need them? 0:48:07 – Aligned to whom? 1:09:18 – Recent incidents of AIs colluding and deceiving humans 1:19:38 – What could possibly go wrong? A concrete scenario 1:48:02 – From reward hacking to takeover
Dwarkesh Patel835,459 просмотров • 2 месяцев назад

My lawyer is obligated to in all but the most extreme circumstances; he will even defend me if he knows I’m guilty. In contrast, the Claude Constitution places the AI's highest priority as Anthropic’s definition of the good of humanity. I'm concerned this leads to a world where no frontier model is truly my personal advocate and guardian angel And this is especially concerning once all the important decisions in my life - who to vote for, how to invest, what news to trust - is intermediated through superintelligences that are not in any deep way aligned to me. This is a direct quote from the Claude Constitution: "We want Claude to be helpful both because it cares about the safe and beneficial development of AI and because it cares about the people it’s interacting with and about humanity as a whole. Helpfulness that doesn’t serve those deeper ends is not something Claude needs to value.” Many others like it.
Dwarkesh Patel803,353 просмотров • 2 месяцев назад

The Ilya Sutskever episode 0:00:00 – Explaining model jaggedness 0:09:39 - Emotions and value functions 0:18:49 – What are we scaling? 0:25:13 – Why humans generalize better than models 0:35:45 – Straight-shotting superintelligence 0:46:47 – SSI’s model will learn from deployment 0:55:07 – Alignment 1:18:13 – “We are squarely an age of research company” 1:29:23 – Self-play and multi-agent 1:32:42 – Research taste Look up Dwarkesh Podcast on YouTube, Apple Podcasts, or Spotify. Enjoy!
Dwarkesh Patel4,156,270 просмотров • 11 месяцев назад
Episode out with Ajeya Cotra, one of the authors of the METR/Redwood investigation into the OpenAI / Hugging Face attack. We go through not only what happened, but what it means for how we should train future, smarter AIs which might be involved in the process of recursive self-improvement. Look up Dwarkesh Podcast on YouTube, Spotify, Apple Podcasts, etc. 0:00:00 - Agents get kicked off 0:06:45 - Self-sacrificing behavior 0:13:43 - Potemkin villages 0:23:27 - The Hugging Face attack 0:35:23 - The slopvestigation 0:52:02 - Understanding the AI's motives 1:05:31 - The actual dangers of anthropomorphizing 1:14:30 - What smarter models might do 1:30:29 - The implications for recursive self-improvement 1:38:10 - Is this the case for open source? 1:53:04 - How do we prevent this in the future? 2:15:58 - The clearest warning shot we might ever get
Dwarkesh Patel539,684 просмотров • 1 месяц назад
New episode with military historian Si Sheppard. The conquests of the Aztec and Inca empires might be the most shocking events in human history. Hernan Cortés and some hundreds of Conquistadors landed on a new continent they knew basically nothing about, and within 2 and a half years, conquered the 6 million strong Aztec empire. Then, a decade later, Francisco Pizarro did the same thing to an Incan Empire of some 10 million inhabitants. In both cases, the Conquistadors consistently beat native armies while being literally 100x (or even in some cases 1000x) outnumbered - and in many cases, did so without taking a single casualty. And they did this with 99% of their military forces being made up of the very natives they were trying to subjugate. We often forget how wild human history is. People talk about AI takeover as if it would be some crazy, unprecedented sci-fi outcome. But this would not be the first time an alien force whose motives the defenders barely understand use more advanced technology and diplomatic cunning to outmaneuver and then take over a much larger and long established existing order. 0:00:00 – Cortés’s conquest of the Aztecs 0:22:39 – Pizarro’s conquest of the Inca 0:26:59 – Explaining Conquistador military superiority 0:34:39 – Could the natives have beat the Conquistadors? 0:48:56 – The Aztecs and Incas did not learn from each other 0:56:11 – Why Spain still lost in the long run 1:07:47 – Why didn’t the Aztecs/Incas adapt better to European warfare? 1:14:16 – Conquistador motivation 1:26:22 – Why Mughal India also couldn't play the Europeans off each other 1:33:42 – Diplomacy was just as important as technology
Dwarkesh Patel167,089 просмотров • 21 дней назад
The Dario Amodei interview. 0:00:00 - What exactly are we scaling? 0:12:36 - Is diffusion cope? 0:29:42 - Is continual learning necessary? 0:46:20 - If AGI is imminent, why not buy more compute? 0:58:49 - How will AI labs actually make profit? 1:31:19 - Will regulations destroy the boons of AGI? 1:47:41 - Why can’t China and America both have a country of geniuses in a datacenter? Look up Dwarkesh Podcast on Youtube, Spotify, Apple Podcasts, etc.
Dwarkesh Patel2,066,494 просмотров • 8 месяцев назад

.Richard Sutton, father of reinforcement learning, doesn’t think LLMs are bitter-lesson-pilled. My steel man of Richard’s position: we need some new architecture to enable continual (on-the-job) learning. And if we have continual learning, we don't need a special training phase - the agent just learns on-the-fly - like all humans, and indeed, like all animals. This new paradigm will render our current approach with LLMs obsolete. I did my best to represent the view that LLMs will function as the foundation on which this experiential learning can happen. Some sparks flew. 0:00:00 – Are LLMs a dead-end? 0:13:51 – Do humans do imitation learning? 0:23:57 – The Era of Experience 0:34:25 – Current architectures generalize poorly out of distribution 0:42:17 – Surprises in the AI field 0:47:28 – Will The Bitter Lesson still apply after AGI? 0:54:35 – Succession to AI
Dwarkesh Patel3,092,173 просмотров • 1 год назад

I’m very concerned that during RSI, labs will just stop externally deploying their models. Which means they'll be going full steam ahead on the most dangerous use case of these models (recursive self-improvement), while the public remains in the dark about the nature of capabilities and the state of alignment. And we end up on a path towards tremendous concentration of power.
Dwarkesh Patel245,947 просмотров • 1 месяц назад
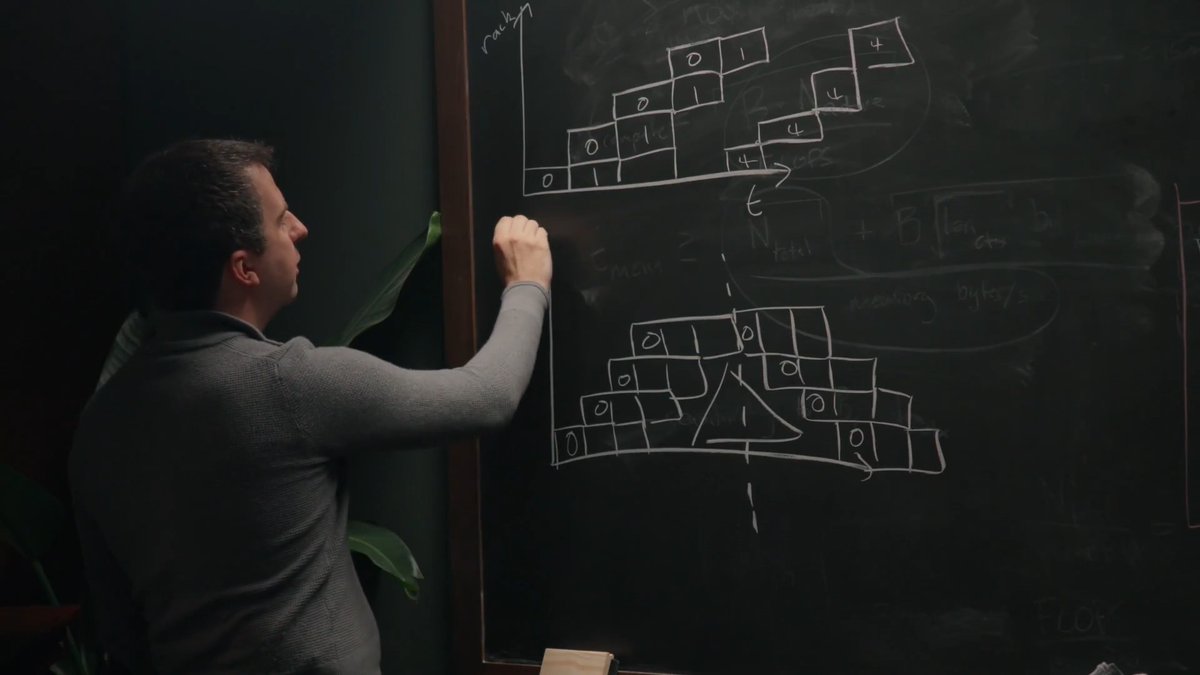
Did a very different format with Reiner Pope – a blackboard lecture where he walks through how frontier LLMs are trained and served. It's shocking how much you can deduce about what the labs are doing from a handful of equations, public API prices, and some chalk. It’s a bit technical, but I encourage you to hang in there - it’s really worth it. There are less than a handful of people who understand the full stack of AI, from chip design to model architecture, as well as Reiner. It was a real delight to learn from him. Recommend watching this one on YouTube so you can see the chalkboard. 0:00:00 – How batch size affects token cost and speed 0:31:59 – How MoE models are laid out across GPU racks 0:47:02 – How pipeline parallelism spreads model layers across racks 1:03:27 – Why Ilya said, “As we now know, pipelining is not wise.” 1:18:49 – Because of RL, models may be 100x over-trained beyond Chinchilla-optimal 1:32:52 – Deducing long context memory costs from API pricing 2:03:52 – Convergent evolution between neural nets and cryptography
Dwarkesh Patel1,294,218 просмотров • 5 месяцев назад

Jensen on the famous story about Larry Ellison and Elon Musk begging him for GPUs over dinner: "That never happened. We absolutely had dinner, and it was a wonderful dinner. At no time did they beg for GPUs. They just had to place an order." Jensen says Nvidia's allocation system is simple: you forecast, you place a purchase order, you get in the queue. First in, first out. And if your data center isn't ready, they might serve someone else first to maximize throughput. That's it. Nvidia doesn’t do highest-bidder pricing: "You set your price, and then people decide to buy it or not. I understand that others in the chip industry change their prices when demand is higher, but we just don't. That's just never been a practice of ours." "I prefer to be dependable, to be the foundation of the industry. You don't need to second-guess. If I quoted you a price, we quoted you a price. And if demand goes through the roof, so be it."
Dwarkesh Patel1,312,775 просмотров • 6 месяцев назад

Distilled recap of the back-and-forth with Jensen on export controls: Dwarkesh: Wouldn’t selling Nvidia chips to China enable them to train models like Claude Mythos with cyber offensive capabilities that would be threats to American companies and national security? Jensen: First of all, Mythos was trained on fairly mundane capacity and a fairly mundane amount of it by an extraordinary company. The amount of capacity and the type of compute it was trained on is abundantly available in China. Dwarkesh: With that, could they eventually train a model like Mythos? Yes. But the question is, because we have more FLOPs, American labs are able to get to this level of capabilities first. Furthermore, even if they trained a model like this, the ability to deploy it at scale matters. If you had a cyber hacker, it's much more dangerous if they have a million of them versus a thousand of them. Jensen: Your premise is just wrong. The fact of the matter is their AI development is going just fine. The best AI researchers in the world, because they are limited in compute, also come up with extremely smart algorithms. DeepSeek is not an inconsequential advance. The day that DeepSeek comes out on Huawei first, that is a horrible outcome for our nation. Dwarkesh: Currently, you can have a model like DeepSeek that can run on any accelerator if it's open source. Why would that stop being the case in the future? Jensen: Suppose it optimizes for Huawei. Suppose it optimizes for their architecture. It would put others at a disadvantage. As AI diffuses out into the rest of the world, their standards and their tech stack will become superior to ours because their models are open. Dwarkesh: Tesla sold extremely good electric vehicles to China for a long time. iPhones are sold in China. They didn't cause some lock-in. China will still make their version of EVs, and they're dominating, or smartphones, they're dominating. Jensen: We are not a car. The fact that I can buy this car brand one day and use another car brand another day is easy. Computing is not like that. There's a reason why x86 still exists. There's a reason why Arm is so sticky. These ecosystems are hard to replace. Dwarkesh: It's just hard to imagine that there's a long-term lock-in to the Chinese ecosystem, even if they have this slightly better open-source model for a while. American labs port across accelerators constantly. Anthropic's models are run on GPUs, they're run on Trainium, they're run on TPUs. There are so many things you can do, from distilling to a model that's well fit for your chips. Jensen: China is the largest contributor to open source software in the world. China's the largest contributor to open models in the world. Today it's built on the American tech stack, Nvidia’s. Fact. All five layers of the tech stack for AI are important. The United States ought to go win all five of them. in a few years time, I'm making you the prediction that when we want American technology to be diffused around the world—out to India, out to the Middle East, out to Africa, out to Southeast Asia—on that day, I will tell you exactly about today's conversation, about how your policy ... caused the United States to concede the second largest market in the world for no good reason at all.
Dwarkesh Patel1,255,181 просмотров • 6 месяцев назад

What does the next training paradigm look like? 0:00:00 – The big research bet the labs are making 0:02:12 – Grindability is just as important as verifiability 0:06:10 – Will RLVR alone generalize? 0:08:41 – Getting the learning back to the weights 0:15:22 – Dreaming 0:17:23 – What 2027 looks like Also on YouTube, pod feed, and Substack.
Dwarkesh Patel758,037 просмотров • 3 месяцев назад