elvis's banner
elvis's profile picture

elvis

@omarsar0 • 323,678 subscribers

Building the frontier @dair_ai • Prev: Meta AI | PaperswithCode | Elastic | PhD

Shorts

OMG!!! GPT-6 Astra built this using just one image reference. I am at a loss for words.

OMG!!! GPT-6 Astra built this using just one image reference. I am at a loss for words.

668,826 görüntüleme

Pay close attention to agentic search. LLM agents get much better at specialized tasks when you give them structured, expert knowledge. Xerj Corpus Hub lets you do this for any agent with no retraining. You connect a ready-made corpus of docs, guidelines, or real source code, and the agent searches it while it works. It's free, open source, and runs locally.

Pay close attention to agentic search. LLM agents get much better at specialized tasks when you give them structured, expert knowledge. Xerj Corpus Hub lets you do this for any agent with no retraining. You connect a ready-made corpus of docs, guidelines, or real source code, and the agent searches it while it works. It's free, open source, and runs locally.

13,594 görüntüleme

Own your personal agent, folks. Just built my own little personal agent with Pi's Pi Durable. I wanted to see how quickly I could build an OpenAI dots clone with open-source tools. I am amazed at how quickly I got this off the ground. It's proactive. It keeps working when you're not watching. It remembers you, runs jobs on a schedule, waits for your approval, and uses its own computer. Pi Durable makes that possible. Every step is checkpointed. I can kill the process mid-task, and My Pi picks up right where it left off. Memory lives in durable documents. What My Pi learns about me in one Space survives a crash and carries over to every other Space. Approvals are durable too. It also has its own computer. Each Space gets a full Linux desktop that My Pi controls with screenshots, mouse, and keyboard. The model runs through OpenRouter, so I can swap models without changing anything else. That's all configurable however you like it. If you've been wanting your own personal agent, now is a great time to build one. I am building this as an experimental ground where I can test new ideas and experiment deeply with proactive personal agents. But I plan to open-source it after testing it a bit and adding more interesting primitives. The goal is to make it customizable and easy to build on, so others can experiment with their own personal agent functionalities.

Own your personal agent, folks. Just built my own little personal agent with Pi's Pi Durable. I wanted to see how quickly I could build an OpenAI dots clone with open-source tools. I am amazed at how quickly I got this off the ground. It's proactive. It keeps working when you're not watching. It remembers you, runs jobs on a schedule, waits for your approval, and uses its own computer. Pi Durable makes that possible. Every step is checkpointed. I can kill the process mid-task, and My Pi picks up right where it left off. Memory lives in durable documents. What My Pi learns about me in one Space survives a crash and carries over to every other Space. Approvals are durable too. It also has its own computer. Each Space gets a full Linux desktop that My Pi controls with screenshots, mouse, and keyboard. The model runs through OpenRouter, so I can swap models without changing anything else. That's all configurable however you like it. If you've been wanting your own personal agent, now is a great time to build one. I am building this as an experimental ground where I can test new ideas and experiment deeply with proactive personal agents. But I plan to open-source it after testing it a bit and adding more interesting primitives. The goal is to make it customizable and easy to build on, so others can experiment with their own personal agent functionalities.

35,838 görüntüleme

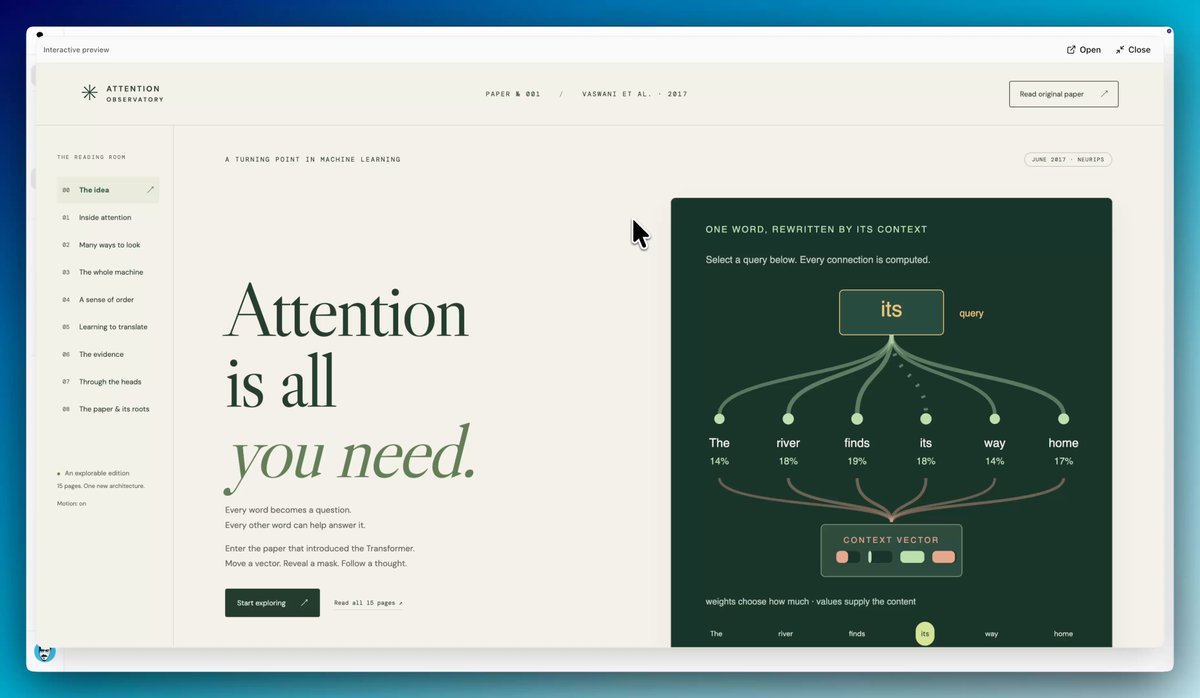
Building a personal knowledge base for my agents is increasingly where I spend my time these days. Like Andrej Karpathy, I also use Obsidian for my MD vaults. What's different in my approach is that I curate research papers on a daily basis and have actually tuned a Skill for months to find high-signal, relevant papers. I was reviewing and curating papers manually for some time, but now it's all automated as it has gotten so good at capturing what I consider the best of the best. There are so many papers these days, so this is a big deal. You all get to benefit from that with the papers I feature in my timeline and on DAIR.AI. The papers are indexed using tobi lutke qmd cli tool (all of it in markdown files along with useful metadata). So good for semantic search and surfacing insights, unlike anything out there. I am a visual person, so I then started to experiment with how to leverage this personal knowledge base of research papers inside my new interactive artifact generator (mcp tools inside my agent orchestrator system). The result is what you see in the clip. 100s of papers with all sorts of insights visualized. I keep track of research papers daily, so believe me when I tell you that this system is absolutely insane at surfacing insights. This is the result of months of tinkering on how to index research and leverage agent automations for wikification and robust documentation. But this is just the beginning. The visual artifact (which is interactive too) can be changed dynamically as I please. I can prompt my agent to throw any data at it. I can add different views to the data. Different interactions. I feel like this is the most personalized research system I have ever built and used, and it's not even close. The knowledge that the agents are able to surface from this basic setup is already extremely useful as I experiment with new agentic engineering concepts. I feel like this knowledge layer and the higher-level ones I am working on will allow me to maximize other automation tools like autoresearch. The research is only as good as the research questions. And the research questions are only as good as the insights the agents have access to. Where I am spending time now is on how to make this more actionable. I am obsessed about the search problem here. The automations, autoresearch, ralph research loop (I built one months ago) are easier to build but are only as good as what you feed them. Work in progress. More updates soon. Back to building.

Building a personal knowledge base for my agents is increasingly where I spend my time these days. Like Andrej Karpathy, I also use Obsidian for my MD vaults. What's different in my approach is that I curate research papers on a daily basis and have actually tuned a Skill for months to find high-signal, relevant papers. I was reviewing and curating papers manually for some time, but now it's all automated as it has gotten so good at capturing what I consider the best of the best. There are so many papers these days, so this is a big deal. You all get to benefit from that with the papers I feature in my timeline and on DAIR.AI. The papers are indexed using tobi lutke qmd cli tool (all of it in markdown files along with useful metadata). So good for semantic search and surfacing insights, unlike anything out there. I am a visual person, so I then started to experiment with how to leverage this personal knowledge base of research papers inside my new interactive artifact generator (mcp tools inside my agent orchestrator system). The result is what you see in the clip. 100s of papers with all sorts of insights visualized. I keep track of research papers daily, so believe me when I tell you that this system is absolutely insane at surfacing insights. This is the result of months of tinkering on how to index research and leverage agent automations for wikification and robust documentation. But this is just the beginning. The visual artifact (which is interactive too) can be changed dynamically as I please. I can prompt my agent to throw any data at it. I can add different views to the data. Different interactions. I feel like this is the most personalized research system I have ever built and used, and it's not even close. The knowledge that the agents are able to surface from this basic setup is already extremely useful as I experiment with new agentic engineering concepts. I feel like this knowledge layer and the higher-level ones I am working on will allow me to maximize other automation tools like autoresearch. The research is only as good as the research questions. And the research questions are only as good as the insights the agents have access to. Where I am spending time now is on how to make this more actionable. I am obsessed about the search problem here. The automations, autoresearch, ralph research loop (I built one months ago) are easier to build but are only as good as what you feed them. Work in progress. More updates soon. Back to building.

468,076 görüntüleme

One of the craziest use cases I’ve found for Jev: verifiers. I am so excited about this that I at least wanted to share the high-level idea. I used Jev to build a custom verifier for the /goal feature in my agent harness. It checks whether the goal is actually complete after every turn, making continuous verification cheap enough to scale. This means I can run more of these verifiers (previously handled by another expensive reasoning model) more frequently to keep the agents on track. System One models are perfect for verification. I think of this as scaling harnesses further by cleverly combining System One and System Two models. I have a feeling this will enable a new wave of scalable test-time compute methods. Watch this space closely. I've just started to experiment with this and am already seeing really good results. I need to explore and figure out a way to benchmark it. I will share more once I have more results. This is an insane unlock for long-horizon agents. You heard it here first. And you can expect to see more harnesses embracing this new pattern. Full guide dropping in the next couple of days.

One of the craziest use cases I’ve found for Jev: verifiers. I am so excited about this that I at least wanted to share the high-level idea. I used Jev to build a custom verifier for the /goal feature in my agent harness. It checks whether the goal is actually complete after every turn, making continuous verification cheap enough to scale. This means I can run more of these verifiers (previously handled by another expensive reasoning model) more frequently to keep the agents on track. System One models are perfect for verification. I think of this as scaling harnesses further by cleverly combining System One and System Two models. I have a feeling this will enable a new wave of scalable test-time compute methods. Watch this space closely. I've just started to experiment with this and am already seeing really good results. I need to explore and figure out a way to benchmark it. I will share more once I have more results. This is an insane unlock for long-horizon agents. You heard it here first. And you can expect to see more harnesses embracing this new pattern. Full guide dropping in the next couple of days.

60,318 görüntüleme

Recommended agent skill. /eli5 works great for visualizing deep technical concepts! I find it speeds up my thought process and helps me collaborate better with agents. Try /eli5 with Pi and Ox Alpha in our harness playground:

Recommended agent skill. /eli5 works great for visualizing deep technical concepts! I find it speeds up my thought process and helps me collaborate better with agents. Try /eli5 with Pi and Ox Alpha in our harness playground:

51,557 görüntüleme

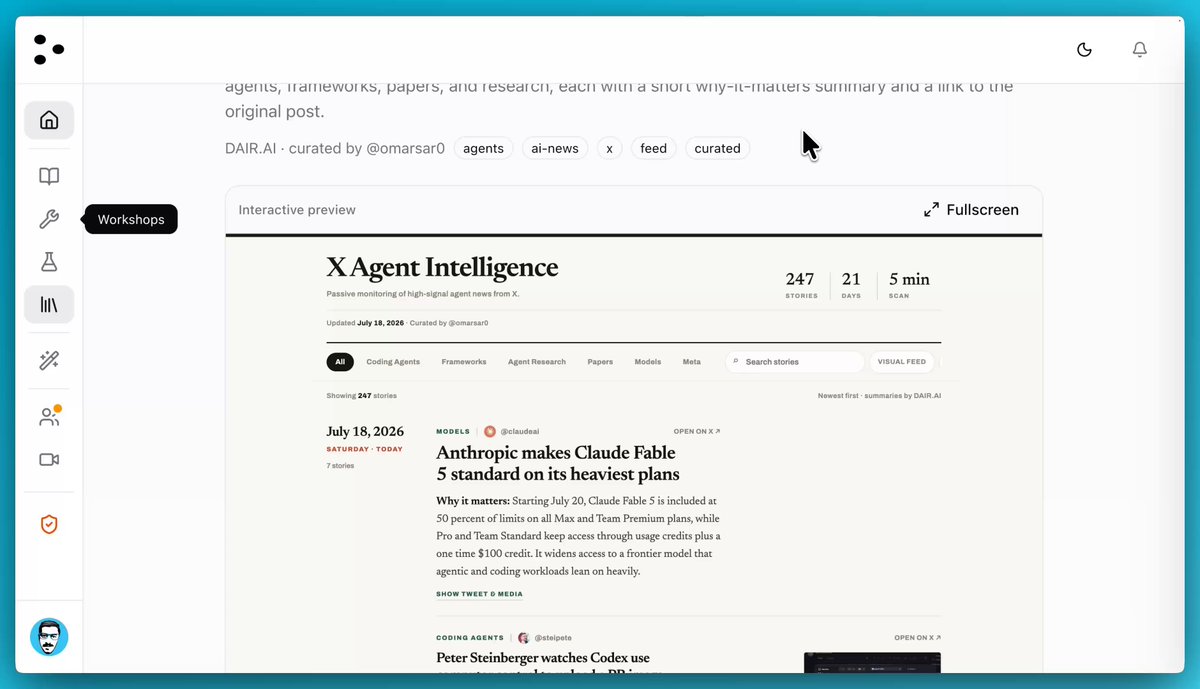
Sharing my new skill! It keeps track of high-signal X accounts for top AI news, papers, projects, etc. Total gamechanger for me. Built with X MCP tools. Give your agent the skill and tell it to generate the artifact with top stories. Works for Codex, Claude, Hermes, OpenClaw, or whatever you use. 3 steps: 1. Set up X MCP - X API: 2. Install skill here: 3. Run prompt: "Use the x-agent-intelligence skill to build a self-contained local feed from my X MCP connection; ask for my source handles if needed, save feed.html, and validate it." It should generate a nice, beautiful HTML artifact like the one shown in the clip. You can tune it however you want. You can then set a schedule/automation to do this daily or whatever cadence you prefer. I have it every 4 hours. You will need to curate the X accounts yourself, but I have shared a few good ones under the assets. You can ask your agent to tune it to however you like. I have also shared my personal feed with our community here: I understand if it gets tricky to set up. Please reach out to me in the community forum. I plan to do a little tutorial or live session soon to help others reproduce the process. You can also store the feed as a wiki, as I have in my own implementation, but that's optional. If you encounter any issues or have ideas on how to improve it, please open a PR.

Sharing my new skill! It keeps track of high-signal X accounts for top AI news, papers, projects, etc. Total gamechanger for me. Built with X MCP tools. Give your agent the skill and tell it to generate the artifact with top stories. Works for Codex, Claude, Hermes, OpenClaw, or whatever you use. 3 steps: 1. Set up X MCP - X API: 2. Install skill here: 3. Run prompt: "Use the x-agent-intelligence skill to build a self-contained local feed from my X MCP connection; ask for my source handles if needed, save feed.html, and validate it." It should generate a nice, beautiful HTML artifact like the one shown in the clip. You can tune it however you want. You can then set a schedule/automation to do this daily or whatever cadence you prefer. I have it every 4 hours. You will need to curate the X accounts yourself, but I have shared a few good ones under the assets. You can ask your agent to tune it to however you like. I have also shared my personal feed with our community here: I understand if it gets tricky to set up. Please reach out to me in the community forum. I plan to do a little tutorial or live session soon to help others reproduce the process. You can also store the feed as a wiki, as I have in my own implementation, but that's optional. If you encounter any issues or have ideas on how to improve it, please open a PR.

72,234 görüntüleme

As an ML Engineer, this is one of the most useful applications of GPT-4 I've seen. Chat Explore is a powerful AI-powered data exploration tool. Here’s why I am so impressed:

As an ML Engineer, this is one of the most useful applications of GPT-4 I've seen. Chat Explore is a powerful AI-powered data exploration tool. Here’s why I am so impressed:

716,742 görüntüleme

Been exploring a new way to explore AI research papers to discover deeper insights. Agents are at the center of it. So far, I've built this little interactive artifact generator in my orchestrator to visualize things. This allows me to change views and insights (on-demand) from 100s of papers. Just scratching the surface here. More to share soon.

Been exploring a new way to explore AI research papers to discover deeper insights. Agents are at the center of it. So far, I've built this little interactive artifact generator in my orchestrator to visualize things. This allows me to change views and insights (on-demand) from 100s of papers. Just scratching the surface here. More to share soon.

143,127 görüntüleme

This blew up more than I expected. To minimize the negative impact of these changes, my orchestrator can now smoothly switch/handoff between any provider/model (e.g., fable 5 -> gpt-5-sol) Just one of the benefits of owning the harness & orchestrator.

This blew up more than I expected. To minimize the negative impact of these changes, my orchestrator can now smoothly switch/handoff between any provider/model (e.g., fable 5 -> gpt-5-sol) Just one of the benefits of owning the harness & orchestrator.

62,278 görüntüleme

This is insane! 🤯 Just built a new skill in Claude Code using Opus 4.5. The skill uses Gemini 3 Pro (via API) for designing web pages. Look at what it generated from one simple prompt.

This is insane! 🤯 Just built a new skill in Claude Code using Opus 4.5. The skill uses Gemini 3 Pro (via API) for designing web pages. Look at what it generated from one simple prompt.

152,981 görüntüleme

NEW favorite artifact. I read this every morning to catch up on AI news from high-signal X accounts. It's an HTML artifact that curates X posts using the X MCP tools. Composed by my research agents. I have a daily automation that goes through curated X accounts and captures AI papers, projects, and more. I feel like this is closer to the "For You" feed that we all want. Happy to share the artifact and automation instructions if anyone thinks it would be useful for them.

NEW favorite artifact. I read this every morning to catch up on AI news from high-signal X accounts. It's an HTML artifact that curates X posts using the X MCP tools. Composed by my research agents. I have a daily automation that goes through curated X accounts and captures AI papers, projects, and more. I feel like this is closer to the "For You" feed that we all want. Happy to share the artifact and automation instructions if anyone thinks it would be useful for them.

49,980 görüntüleme

I am in disbelief right now. GPT-6 Astra is a truly incredible model. It took about 2 hrs to generate this 3D model of Xunantunich, a Maya archaeological site in western Belize.

I am in disbelief right now. GPT-6 Astra is a truly incredible model. It took about 2 hrs to generate this 3D model of Xunantunich, a Maya archaeological site in western Belize.

23,472 görüntüleme

Found a great production use case for Jev. I used Jev to organize ~2.3K AI research papers. The total cost was $0.14, and it took about 83 seconds. The process: The papers already had old tags, which I ran through a previous open model (DeepSeek V4 Flash). However, I wasn't confident in the classifications, and I didn't want to spend more on tokens unless I spent time tuning it into a good LLM classifier via few-shot (more expensive). Too tedious, too costly, and unsustainable. Luckily for us, we now have Jev to help us with organizing papers better. So Jev first went through all the papers and retagged them. It agreed with 75% of the previous tags. Jev found about 579 high-confidence topic changes. I evaluated reliability by manually labeling 30 disagreements and accepted all of them. I was astonished by Jev's classification capabilities. We applied and verified all changes in production. I'm much more satisfied with the classifications, but I think there is still room for improvement. Check out the papers here: I will experiment with Jev more. The takeaway is that pipelines can be significantly improved by carefully combining System One and System Two models. Jev clearly unlocks more interesting ways to organize papers and offer a more useful discovery layer for research papers. More updates on that soon.

Found a great production use case for Jev. I used Jev to organize ~2.3K AI research papers. The total cost was $0.14, and it took about 83 seconds. The process: The papers already had old tags, which I ran through a previous open model (DeepSeek V4 Flash). However, I wasn't confident in the classifications, and I didn't want to spend more on tokens unless I spent time tuning it into a good LLM classifier via few-shot (more expensive). Too tedious, too costly, and unsustainable. Luckily for us, we now have Jev to help us with organizing papers better. So Jev first went through all the papers and retagged them. It agreed with 75% of the previous tags. Jev found about 579 high-confidence topic changes. I evaluated reliability by manually labeling 30 disagreements and accepted all of them. I was astonished by Jev's classification capabilities. We applied and verified all changes in production. I'm much more satisfied with the classifications, but I think there is still room for improvement. Check out the papers here: I will experiment with Jev more. The takeaway is that pipelines can be significantly improved by carefully combining System One and System Two models. Jev clearly unlocks more interesting ways to organize papers and offer a more useful discovery layer for research papers. More updates on that soon.

15,427 görüntüleme

After a few more hours, I think I've figured out Opus 5. Opus 5 is trained to be more agentic than anything I've used. All Claude 5 models are like that. So what changes? The way to interact with Opus 5 or contextualize it won't work the same way as with other models. It loves exploring, so it doesn't need much guidance for it. Unique preferences, artifacts, and references compliment it well and enable cleaner and more effective exploration and execution. Now that it can explore more effectively on its own and understand intent better, the best thing to do is to get out of its way (e.g., it doesn't need examples of your preferences; a clear high-level description of it works best). It's truly agentic in that sense. A good first step to provide better context for Opus 5 is to distinguish between what's situational and what needs persistence. Regardless, persistent system prompts and CLAUDE.MD needs to stay lightweight. Remove memories and tool descriptions from these. CLAUDE.MD is also a great place to tap into progressive disclosure by linking command/skills to it. On the situational side, agent skills and auto-memory can leverage progressive disclosure and the improved ability of the model to use its external context/knowledge. Conflicting and unnecessary instructions, which are common at this layer (mainly to ensure reliability), are going to throw off this model easily. That's the biggest change I had to make. Simple, clean, and clear prompts and skills work best. I had to clean a lot of my skills and system prompts. The way I prompt remains the same (usually clear and well-scoped). MCP tool descriptions are also more descriptive and have been deduped from the system prompt. Anthropic released a guide on the new rules for context engineering, which was helpful here. I started to test the recommendations and created a little artifact with the things that worked along the way. This might feel like a lot of work. Believe me, it has been frustrating. But I think we can expect future frontier models to become more agentic and smarter at figuring out the right context/gaps. The best thing to do is to prepare for that now. Boris Cherny mentioned that Opus 5 is their least prompt-injectable model yet. I am not sure if that was something they intentionally trained for or if it emerged based on how it was trained, which is to be extremely agentic in nature and more direct in execution.

After a few more hours, I think I've figured out Opus 5. Opus 5 is trained to be more agentic than anything I've used. All Claude 5 models are like that. So what changes? The way to interact with Opus 5 or contextualize it won't work the same way as with other models. It loves exploring, so it doesn't need much guidance for it. Unique preferences, artifacts, and references compliment it well and enable cleaner and more effective exploration and execution. Now that it can explore more effectively on its own and understand intent better, the best thing to do is to get out of its way (e.g., it doesn't need examples of your preferences; a clear high-level description of it works best). It's truly agentic in that sense. A good first step to provide better context for Opus 5 is to distinguish between what's situational and what needs persistence. Regardless, persistent system prompts and CLAUDE.MD needs to stay lightweight. Remove memories and tool descriptions from these. CLAUDE.MD is also a great place to tap into progressive disclosure by linking command/skills to it. On the situational side, agent skills and auto-memory can leverage progressive disclosure and the improved ability of the model to use its external context/knowledge. Conflicting and unnecessary instructions, which are common at this layer (mainly to ensure reliability), are going to throw off this model easily. That's the biggest change I had to make. Simple, clean, and clear prompts and skills work best. I had to clean a lot of my skills and system prompts. The way I prompt remains the same (usually clear and well-scoped). MCP tool descriptions are also more descriptive and have been deduped from the system prompt. Anthropic released a guide on the new rules for context engineering, which was helpful here. I started to test the recommendations and created a little artifact with the things that worked along the way. This might feel like a lot of work. Believe me, it has been frustrating. But I think we can expect future frontier models to become more agentic and smarter at figuring out the right context/gaps. The best thing to do is to prepare for that now. Boris Cherny mentioned that Opus 5 is their least prompt-injectable model yet. I am not sure if that was something they intentionally trained for or if it emerged based on how it was trained, which is to be extremely agentic in nature and more direct in execution.

37,824 görüntüleme

I just built my own wiki generator plugin for my agents. My agents can now generate wikis for anything I ask. One of my favorite wikis is called PaperWiki. This is a great example of what Andrej Karpathy describes. It uses obsidian vaults to organize papers, retrieve LLM-generated summaries, diagrams, and other advanced views for paper exploration. When Obsidian UI is not enough, I use my own artifact generator inside my agent orchestrator (see clip for example). This allows my agents to build any kind of view or exploration feature that I need. The papers are all curated with automations and several rules/patterns I have manually built over the years. On the surface, this looks basic. But behind the scenes, there are advanced search capabilities, connections, metadata, derived data, and other interesting bits of information that are extremely useful for my research agents. This is mostly built for agents. The artifact preview is just a high-level way to validate and quickly assess the quality of the wiki, suggest improvements, and it's also great for research. I use tobi lutke's qmd for all search capabilities. Everything is markdown. The summaries and even the diagrams. The wiki updates on its own based on several automations I have optimized over the past couple of weeks. The wiki grows and self-improves based on several requirements important for my research use cases. This is as personalized as it gets. There is nothing like it out there. And I use my research expertise to continue improving it over time. This is a vanilla wiki. There are so many things I want to build on top of this. Different aggregations, views, artifacts, etc. All to help automate more of my research work and accelerate productivity. I think the biggest leverage here is how powerful this could be for discovery and experimentation. One of my goals is to use it to find deeper connections and insights that would otherwise elude the top human researchers and use those to generate interesting new hypotheses and research experiments. That way, my agents can use autoresearch to explore research ideas at the frontier. Stay tuned for more.

I just built my own wiki generator plugin for my agents. My agents can now generate wikis for anything I ask. One of my favorite wikis is called PaperWiki. This is a great example of what Andrej Karpathy describes. It uses obsidian vaults to organize papers, retrieve LLM-generated summaries, diagrams, and other advanced views for paper exploration. When Obsidian UI is not enough, I use my own artifact generator inside my agent orchestrator (see clip for example). This allows my agents to build any kind of view or exploration feature that I need. The papers are all curated with automations and several rules/patterns I have manually built over the years. On the surface, this looks basic. But behind the scenes, there are advanced search capabilities, connections, metadata, derived data, and other interesting bits of information that are extremely useful for my research agents. This is mostly built for agents. The artifact preview is just a high-level way to validate and quickly assess the quality of the wiki, suggest improvements, and it's also great for research. I use tobi lutke's qmd for all search capabilities. Everything is markdown. The summaries and even the diagrams. The wiki updates on its own based on several automations I have optimized over the past couple of weeks. The wiki grows and self-improves based on several requirements important for my research use cases. This is as personalized as it gets. There is nothing like it out there. And I use my research expertise to continue improving it over time. This is a vanilla wiki. There are so many things I want to build on top of this. Different aggregations, views, artifacts, etc. All to help automate more of my research work and accelerate productivity. I think the biggest leverage here is how powerful this could be for discovery and experimentation. One of my goals is to use it to find deeper connections and insights that would otherwise elude the top human researchers and use those to generate interesting new hypotheses and research experiments. That way, my agents can use autoresearch to explore research ideas at the frontier. Stay tuned for more.

67,308 görüntüleme

Dynamic workflows are a generalization of harnesses, automations, loops, routing, and graphs. It's the most powerful feature I have built into my agent orchestrator. Supports all kinds of patterns that leverage different agent backends (claude, codex, pi, hermes,...). It's a meta-harness approach that unlocks new forms of test-time compute. Example of use cases it supports: > LLM councils to get different perspectives from LLMs or plan more intensively > Dynamically routing tasks to different agents based on needs (e.g., cost efficiency and optimal intelligence) > Advisor/Judge + executor workflows and pretty much any complex graph-based pattern required by the task. I find it especially useful for long-running work and code reviewing. > Agent teams that talk to each other if needed for the task. I like to use this for AI editing, artifact creation, and other creative tasks. And I am sure it supports so many things that I haven't discovered yet. I got inspired by the dynamic workflow feature released by the Claude Code team. I had actually built it earlier this year but wanted to generalize it across different agent backends. I think this is going to become more popular in the coming days. I will share more of my findings soon.

Dynamic workflows are a generalization of harnesses, automations, loops, routing, and graphs. It's the most powerful feature I have built into my agent orchestrator. Supports all kinds of patterns that leverage different agent backends (claude, codex, pi, hermes,...). It's a meta-harness approach that unlocks new forms of test-time compute. Example of use cases it supports: > LLM councils to get different perspectives from LLMs or plan more intensively > Dynamically routing tasks to different agents based on needs (e.g., cost efficiency and optimal intelligence) > Advisor/Judge + executor workflows and pretty much any complex graph-based pattern required by the task. I find it especially useful for long-running work and code reviewing. > Agent teams that talk to each other if needed for the task. I like to use this for AI editing, artifact creation, and other creative tasks. And I am sure it supports so many things that I haven't discovered yet. I got inspired by the dynamic workflow feature released by the Claude Code team. I had actually built it earlier this year but wanted to generalize it across different agent backends. I think this is going to become more popular in the coming days. I will share more of my findings soon.

32,897 görüntüleme

Just built an insane new agent skill. It can perfectly extract slides from YT videos, then write notes, images, transcripts, and slides into Obsidian vaults. An HTML artifact allows me to navigate and add more notes as I listen. Should I release the skill?

Just built an insane new agent skill. It can perfectly extract slides from YT videos, then write notes, images, transcripts, and slides into Obsidian vaults. An HTML artifact allows me to navigate and add more notes as I listen. Should I release the skill?

46,685 görüntüleme

This is one of the fastest ways to build a custom ChatGPT-like system on top of your data. It's called ChatLLM (by Abacus.AI). Here is a demo of how to build a simple custom chat LLM:

This is one of the fastest ways to build a custom ChatGPT-like system on top of your data. It's called ChatLLM (by Abacus.AI). Here is a demo of how to build a simple custom chat LLM:

227,183 görüntüleme

We are entering an extremely exciting era for open-weight models. Kimi K2.6 now feels like a top agentic model. I took it for a spin via Fireworks AI fast inference APIs. Kimi K2.6 has impressive agentic capabilities, design skills, and the ability to synthesize large amounts of information. I built a little Skill that produces survey papers on any AI research topic you want. (see example in the clip) You can use the skill to tell your agent to generate a survey on whatever topic and watch it go to work. The artifact was fully generated by Kimi.ai's Kimi K2.6. It's cheap and fast. Next step for me is to explore ways to continue integrating the capabilities of these models on use cases like automating my LLM knowledge bases and augmenting my agent memory capabilities. Stay tuned for more.

We are entering an extremely exciting era for open-weight models. Kimi K2.6 now feels like a top agentic model. I took it for a spin via Fireworks AI fast inference APIs. Kimi K2.6 has impressive agentic capabilities, design skills, and the ability to synthesize large amounts of information. I built a little Skill that produces survey papers on any AI research topic you want. (see example in the clip) You can use the skill to tell your agent to generate a survey on whatever topic and watch it go to work. The artifact was fully generated by Kimi.ai's Kimi K2.6. It's cheap and fast. Next step for me is to explore ways to continue integrating the capabilities of these models on use cases like automating my LLM knowledge bases and augmenting my agent memory capabilities. Stay tuned for more.

47,678 görüntüleme

Videos

omarsar0's profile picture

LLM Wikis are being slept on. I argue that creating knowledge bases with LLMs or coding agents is one of the most valuable applications of AI today. It's about being intentional in building and scaling your intelligence stack. To showcase this, I wanted to share an LLM Wiki I have built over the last couple of months. It's called PaperWiki, and I use it across all my research workflows, along with my research agents. In fact, I also use it to curate papers I share with my communities, newsletter, and on X. The PaperWiki is updated regularly with automations, so I basically have agents on a loop maintaining it. All the entries are ingested from different sources and stored in a vault (Obsidian) and further indexed using qmd. And then further presented via an HTML artifact. So all of it is easily accessible to all my agents and easily searchable through full-text search and rich semantic search. The structure of the wiki has proven significantly useful to start interesting and exciting cutting-edge research projects with my research agents (from building tiny and more efficient gpt/difussion llms to building out SoTA harnesses and memory systems). It turns out that agents love markdown files and can more easily navigate the papers given the rich metadata structure of the wiki. I am just getting started on this, but it's clear to me that we should all be experimenting with LLM Wikis. Here's why: Building LLM knowledge bases gets you into the habit of leveraging AI outputs in all kinds of creative ways. It's the good kind of tokenmaxxing we should all be pushing for. LLM Wikis can be maintained automatically in a loop. I use an automation that updates the wiki every day based on papers I curate. The curation is another automation I run in a loop (with a bit of human in the loop), so I get to build on all my previous knowledge and expertise, and all of it compounds the deeper the integration/layers. One interesting result of this process is that I feel like I can better spot high-quality papers and remove noise more easily. Social media could never solve that. And most paper aggregators use metrics I simply don't trust. I like that agents can help with the noise vs. signal problem. This is important for research. Lots of people consider agents to produce mostly slop. But it doesn't have to be that way. Careful curations, prompts, automations, verifiers, and human-in-the-loop can produce some astonishing results. And you really don't need frontier models for this. I use a combination of frontier models (opus-4.8) and open-weight models (deepseek-v4-flash) to maintain this. An exciting future work (we are working on this DAIR.AI) is to tune specialized models on top of this to allow LLMs to quickly understand cutting-edge research ideas and can better conceptualize research strategies that further accelerate scientific research agents. I plan to open-source a bunch of this work, including the artifact, but this is currently work in progress, and I was excited to share some thoughts as I continue working on it. Sharing more as I go. Stay tuned!

elvis

56,161 görüntüleme • 3 ay önce