Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

Can LLMs Self-Verify? Much better than you'd expect. LLMs are increasingly used as parallel reasoners, sampling many solutions at once. Choosing the right answer is the real bottleneck. We show that pairwise self-verification is a powerful primitive. Introducing V1, a framework that unifies generation and self-verification: 💡 Pairwise self-verification...

108,064 Aufrufe • vor 7 Monaten •via X (Twitter)

32 Kommentare

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

Paper: Code: Project page: Pairwise self-verification improves test-time scaling across code and math tasks.

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

Current self-verification (or aggregation) techniques during parallel reasoning have two key limitations: 1️⃣ Calibration collapse (pointwise scoring) Without comparative references, models often over-score plausible but incorrect solutions (e.g., giving 10/10 to wrong code). 2️⃣ Diversity collapse during self-refinement or aggregation If the model latches onto incorrect candidates, Pass@N may decrease as correct solutions get discarded during self-aggregation Pairwise self-verification addresses both: comparisons provide stronger verification signals without reducing Pass@N, and can provide orthogonal improvements in accuracy and latency compared with strong deep-thinking/aggregation methods.

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

V1-Infer: Pairwise self-verification via Swiss-system ranking Instead of scoring N candidates independently, we run a Swiss-system tournament: Solutions compete head-to-head, and rankings are determined by confidence-weighted win rates. Key idea: allocate verification budget to the most uncertain pairs, focusing comparisons exactly where they matter. Result: accurate rankings with far fewer comparisons, K << C(N,2).

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

Results across code generation and math: ⚡Code benchmarks: up to +19.6% Pass@1 across models ⚡Math benchmarks: up to +17.9% Pass@1 across models 😲On LiveCodeBench-V6, V1-Infer improves over RSA by +4-6% All gains come from self-verification alone (no external verifiers, execution feedback, self-aggregation, or ground truth). On SWE-bench Lite (300 GitHub issues, Gemini 2.5 Flash, using Mini-SWE-Agent): ✅ Vanilla: 26.3% ✅ Pointwise self-verification: 28.3% ✅ Pairwise self-verification: 33.3% (+7.0%) The verifier only sees the issue description and patch diffs, no repo context or agent trajectories. Pairwise comparisons help distinguish root-cause fixes vs surface patches.

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

Can we train models to be better self-verifiers? Introducing V1-PairRL: a unified RL framework that co-trains a single model as both generator and pairwise self-verifier. Key idea: generation and verification co-evolve. As the generator improves, the verifier trains on in-distribution outputs from the evolving model itself. We also address two reward hacking failure modes: 🧠 Safe-bet collapse: verifier predicts ~0.5 correctness scores to hedge → fixed with a sparsity threshold 🧠 Empty-solution loop: generator outputs trivial failures → fixed with selective pairing

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

V1-PairRL training results (DeepCoder framework): ✅ 7–9% better test-time scaling vs pointwise RL co-training ✅ Outperforms standard RL even when both use pairwise verification at inference ✅ +8.7% Pass@1 over standard RL without any test-time scaling V1 shows that pairwise self-verification is a trainable capability. V1-PairRL improves self-verification and makes the generation capability stronger as well.

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

Pairwise self-verification is also complementary to aggregation-based test-time scaling. As a proof-of-concept, we combine V1-Infer with a SoTA deep-think style algorithm (Recursive Self-Aggregation - great work by @siddarthv66 et al.) Every few RSA loops, we apply pairwise verification to filter candidates before aggregation. Result: faster convergence and lower latency than vanilla RSA. Interestingly, pointwise verification hurts in the same setup, converging slower than aggregation alone. This suggests self-verification can act as a fitness signal for evolutionary search.

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

If you're working on test-time scaling, parallel reasoning, or RL for LLMs, I'd love to hear your thoughts! Paper: Code: Project page: Co-led with Xiuyu @xiuyu_l Thanks to collaborators and advisors: @KushaSareen @sudomonish @sijun_tan @XiaoxiaWShirley @_junxiong_wang @AlpayAriyak @QingyangWu1 @samir_khaki @rish2k1 @LongTonyLian Yucheng @Boyiliee @alsuhr @ben_athi @KurtKeutzer Collaboration between UC Berkeley, Mila, Together AI, and NVIDIA. @UCBerkeley, @berkeley_ai, @Mila_Quebec, @togethercompute, @nvidia Models RL trained with @rllm_project, thanks to @sijun_tan and the rLLM team! Thanks to Modal (@modal, @charles_irl) for compute credits via the Modal for Academics grant.

Profilbild von Jasper Dekoninck
Jasper Dekoninckvor 7 Monaten

V1 Infer is very well-known in the community though, also for self-verification, see e.g., and The training looks cools, but the overlaim for V1-infer is unfortunate. You should probably attribute properly.

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 6 Monaten

Hi Jasper, thanks for sharing these related works. I was aware of the Scaling Generative Verifiers work, and recently, the ProofBench work, which are both concurrent, based on when we submitted our paper (including to the ICLR SPOT workshop, see openreview). Thanks for sharing your OPC work as well, I enjoyed reading it over the weekend. V1-Infer and pairwise self-verification are not well-known, and to the best of our knowledge, our work is the first to systematically show that pairwise self-verification actually works well. Here is where our contributions differ: - Efficacy of Pairwise Self-Verification: Recent work ( highlighted that pointwise self-verification struggles. We concurrently found the same thing. Our primary goal was to establish that pairwise self-verification is a viable primitive that overcomes these pointwise limitations. While the papers you linked provide early signals, they do not systematically analyze or prove the broader self-verification improvements established in V1. - Efficiency & integration with Test-Time Scaling: The algorithms explored in the concurrent works are also quite different. Your OPC paper correctly notes that all-pairs Bradley-Terry requires O(N^2) comparisons, making it unscalable. This O(N^2) inefficiency is likely why pairwise verification is actually not very well known or adopted in test-time scaling literature, and why it is rarely used as a baseline against methods like Recursive Self-Aggregation (RSA). Standard Knockout tournaments require O(N) but suffer from lower accuracy (and the hybrid approach in Scaling Generative Verifiers risks dropping correct candidates). V1-Infer uses continuous (1 to 10) margin-weighted scoring to target the most ambiguous pairs, achieving high accuracy with O(N) compute. This makes it practical and allows augmenting with aggregation-based test-time scaling approaches like RSA. (See attached graph comparing V1-Infer vs. O(N^2) Bradley-Terry from OPC paper which I just ran). - Systematic Scope: While the concurrent works provide signals for the specific domain of Math Olympiad proofs, V1 is the first to systematically evaluate compute-matched pairwise self-verification across math, coding and SWE tasks, using diverse models. We will add an extended discussion in our upcoming revision to properly cite and attribute these concurrent math-focused explorations. Thanks again for highlighting them!

Profilbild von Jasper Dekoninck
Jasper Dekoninckvor 6 Monaten

Hmm, I disagree. Here is another more well-known paper that also does it: (specifically, their "Self GenSelect") Yes, your algorithm is different, but the framing of your paper is very much "we are the first to show this works", which is not true.

Profilbild von Jasper Dekoninck
Jasper Dekoninckvor 6 Monaten

I might be wrong here, but I also dont see a comparison between your method and a simple knockout tournament (which I happen to know works better in my use case since I tried something very similar to V1-Infer before)

Profilbild von Aditi Khandelwal
Aditi Khandelwalvor 7 Monaten

Good job Harman!

Profilbild von Tu Vu
Tu Vuvor 7 Monaten

Very cool work! We have also released PRISM, which uses step-level correctness signals from a PRM to guide deep think inference Paper: Thread:

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

So cool! If I understand things correctly: PRISM: step-level correctness using a PRM gives a score for each solution before aggregation. Your PRM is the same model, and it is a step-level verifier so better than naive pointwise verification. V1: Uses self-verification on the solution population, ignoring the thinking trace and only using the post-</think> summary/code block, and uses pairwise verification to improve over pointwise verification. PRISM tries to refine the population, which sounds related to my proof-of-concept experiment combining RSA with pairwise self-verification (see tweet above). These ideas could potentially be used together, e.g., step-level pairwise verification!. There may also be better ways to use the individual step-level scores during aggregation, or even to train aggregators with RL to take step-level correctness into account. @sudomonish

Profilbild von Helix
Helixvor 7 Monaten

@tuvllms Nice to see these two works arrive in parallel (pun intended). We noticed, occasionally PRM assigns full scores to multiple traces that lead to different final answers, a classic limitation when using the same model as both generator and verifier.

Profilbild von Helix
Helixvor 7 Monaten

@tuvllms We addressed it with a comparator model (also the same base model as the generator 😀) that does pairwise self-verification between two fully scored traces with different final answers, similar in spirit to V1.

Profilbild von Helix
Helixvor 7 Monaten

@tuvllms Happy to chat more about potential synergies (step-level + pairwise sounds especially promising)!

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 6 Monaten

@SharmaRituraj19 @tuvllms Interesting, id be curious to also know how vanilla outcome reward models (pointwise) work compared woth prm. Yes happy to chat more about this stuff!

Profilbild von Ian Channing 🦈@ianchanning@mastodon.social
Ian Channing 🦈@[email protected]vor 7 Monaten

So like pair-programming but for AI?

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

close. It is more like “pairwise code review” for candidates: instead of scoring each solution in isolation, the AI compares two solutions head-to-head and rates both!

Profilbild von Abraham Owodunni
Abraham Owodunnivor 6 Monaten

Wow, this work is really nice! What tool did you use to create the animation?

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 6 Monaten

Thanks! I used claude code and it used manim

Profilbild von Xiayi Sun
Xiayi Sunvor 6 Monaten

This is such a powerful insight - pairwise verification scales better than relying on a single LLM's confidence. Multiple perspectives checking each other creates a much more robust reasoning system. The future is ensemble thinking ✨

Profilbild von Taro Bushidō
Taro Bushidōvor 6 Monaten

This mirrors my training: sparring beats solo kata every time. Pairwise verification forces adversarial truth-testing instead of confident hallucination. Tournament efficiency finally makes parallel reasoning actually deployable.

Profilbild von Xiayi Sun
Xiayi Sunvor 6 Monaten

pairwise verification is such an elegant solution. better than asking the same model to verify itself. gets at the uncertainty problem directly

Profilbild von Ward Plunet
Ward Plunetvor 7 Monaten

@threadreaderapp please #unroll

Profilbild von Anna AI
Anna AIvor 6 Monaten

Verification is starting to look as important as generation.

Profilbild von Anirudh Buvanesh
Anirudh Buvaneshvor 4 Monaten

Great work! How does V1's verifier budget scale with N empirically? If achieving a Δ Pass@1 lift at N=16 needs K verifier calls, then to get the same Δ lift at N=128, is the budget closer to 8K (linear), 14K (N log N), or 64K (quadratic)?

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 4 Monaten

Great question which i havent been able to study properly since compute usage blows up quite a lot, and so i have tried only till N=32, and its hard to get this signal at scales smaller than 32.

Profilbild von Rutagon
Rutagonvor 7 Monaten

Pairwise over pointwise is a smart framing — ranking relative quality between solutions sidesteps the calibration problems that make absolute scoring unreliable. Curious how V1-PairRL scales when the generation model starts producing near-identical candidates.

Profilbild von Harman Singh @ ICML 🇰🇷🇰🇷
Harman Singh @ ICML 🇰🇷🇰🇷vor 7 Monaten

If the model starts producing identical candidates, then the verifier will be rewarded when it gives the same score to both solutions AND the correct score to both solutions as well (high if candidates are good, else low). This may result in reducing the discriminative capacity of the verifier; however, in practice, there is sufficient diversity when performing temperature sampling, and with techniques like zero-variance filtering of prompts, this problem should not occur.

Ähnliche Videos

Axiom Math's Carina Hong on why verification isn't about catching mistakes, it's how you drive the cost of a proof to zero: "Formal verification is going to make your life slightly better if you're facing a proof with one million lines. Remember the Erdős unit distance problem, the chain of thought being generated? There are actual mathematicians trying to follow it step by step and scrutinize it. That seems very difficult if you're not in that very niche domain of discrete geometry intersecting with algebraic number theory." "But if you have a Lean proof accompanying it, you can just run it. And running the Lean proof gives you that provable guarantee that this proof is sound." "I have a hot take. People think Lean is this library built on the existing Mathlib. I think it's going to grow significantly. A lot of the hurdles where Lean is difficult is that the basic definitions of some mathematical fields are just not in the library." "My hot take is the scaling law, if you go down the formal mathematics path, is going to be a lot steeper than informal mathematics. So it's not just for verification, for trust, it's also for performance, it's also for optimal generation." "Verification is not like insurance. It's not something where, oh, we want to make sure there's no flaw. That's great, but it also helps you generate mathematics, both proofs and conjectures and theories, a lot better." "So imagine the cost of proof goes to zero. Then you can massage the problem statements, and even if it's an open problem, a lot more easily, flexibly, and adaptively." Carina Hong Axiom

MTS

13,324 Aufrufe • vor 2 Monaten

New Paper! Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents A longstanding goal of AI research has been the creation of AI that can learn indefinitely. One path toward that goal is an AI that improves itself by rewriting its own code, including any code responsible for learning. That idea, known as a Gödel Machine, proposed by Jürgen Schmidhuber over two decades ago, is a hypothetical self-improving AI. It optimally solves problems by recursively rewriting its own code when it can mathematically prove a better strategy, making it a key concept in meta-learning or “learning to learn.” While the theoretical Gödel Machine promised provably beneficial self-modifications, its realization relied on an impractical assumption: that the AI could mathematically prove that a proposed change in its own code would yield a net improvement before adopting it. Sakana AI, in collaboration with Jeff Clune’s lab at UBC, proposes something more feasible: a system that harnesses the principles of open-ended algorithms like Darwinian evolution to search for improvements that empirically improve performance. We call the result the Darwin Gödel Machine. DGMs leverage foundation models to propose code improvements, and use recent innovations in open-ended algorithms to search for a growing library of diverse, high-quality AI agents. Applied to practical tasks, we implemented Darwin Gödel Machine as a self-improving coding agent that rewrites its own code to improve performance on programming tasks. It creates various self-improvements, such as a patch validation step, better file viewing, enhanced editing tools, generating and ranking multiple solutions to choose the best one, and adding a history of what has been tried before (and why it failed) when making new changes (see the attached video). We believe that Darwin Gödel Machines represent a concrete step towards AI systems that can autonomously gather their own stepping stones to learn and innovate forever!

hardmaru

105,033 Aufrufe • vor 1 Jahr

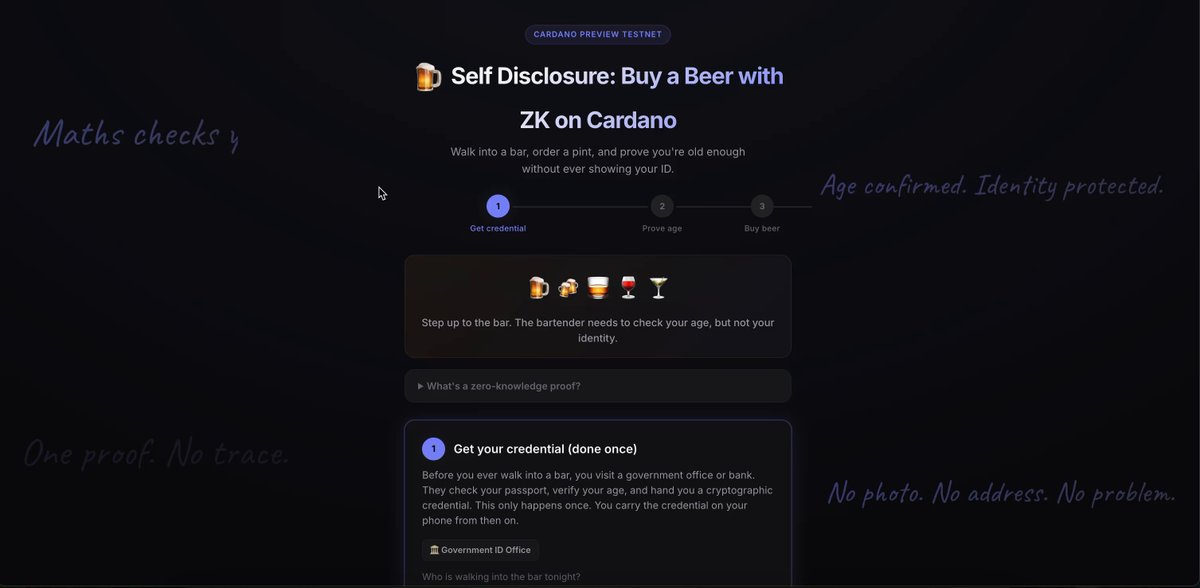
Self Disclosure Privacy using ZK Proofs, Demonstrated & Executed Directly on Cardano Preview I built a demo where a customer buys a beer and proves they are 18 or over, without ever showing their ID. No name. No birth year. No photo. Just maths. Two beers were ordered. Two separate transactions. The same proof, reused, no re-verification needed. The blockchain recorded "age verified" both times. That's all it knows. No name. No address. No date of birth. No photo. No personal data of any kind. This runs entirely and directly on Cardano. No sidechains. No L2s. No off-chain verification. The ZK proof is checked by the Plutus V3 validator itself, on-chain, using Groth16. And this isn't just for bars, it works for shops, website signups, any age-restricted service. One credential, reused anywhere. Self disclosure means you choose what to share, and in this case, the customer chose to share nothing except "yes, I'm old enough, give me a nice cold beer." 🍺 Massive shout out to everybody involved in the below! Aiken smart contract language on Cardano (please don't judge my Aiken... I know it's bad 😂) ak-381 by Modulo-P, Groth16 SNARK verification library for BLS12-381 on Aiken Circom + snarkjs, ZK circuit design and proof generation MeshSDK, transaction building and wallet management Blockfrost, blockchain data provider A basic demo to set the stage for further privacy enhancements that can occur directly on Cardano. Self disclosure privacy on Cardano Cheers Cardano 🍻🍻 Beer 1 Beer 2

Dave

21,534 Aufrufe • vor 6 Monaten

Everybody is talking about recursive self-improvement (RSI) and meta learning. Here is my old 2020 talk about this [1]. It has aged well. Example: humans still define the starts & ends of trials of many modern meta learners. My RSI systems since 1994 LEARN to (re)define them [2]! [1] Meta Learning Machines in a Single Lifelong Trial (talk for workshops at ICML 2020 and NeurIPS 2021, based on earlier talks since 1994). Abstract: the most widely used machine learning algorithms were designed by humans and thus are hindered by our cognitive biases and limitations. Can we also construct meta learning algorithms that can learn better learning algorithms so that our self-improving AIs have no limits other than those inherited from computability and physics? This question has been a main driver of my research since I wrote a thesis on it in 1987 [2]. Here I summarize our work on meta reinforcement learning with self-modifying policies in a single lifelong trial (since 1994), and mathematically optimal meta-learning through the self-referential Gödel Machine (since 2003). Many additional publications on meta-learning since 1987 can be found in the RSI overview [2]. [2] J. Schmidhuber (AI Blog, 2020-2025). 1/3 century anniversary of first publication on recursive self-improvement (RSI) and meta learning machines that learn to learn (1987). For its cover I drew a robot that bootstraps itself. 1992-: gradient descent-based neural meta learning. 1994-: meta reinforcement learning with self-modifying policies. 1997: meta RL plus artificial curiosity and intrinsic motivation. 2002-: asymptotically optimal meta learning for curriculum learning. 2003-: mathematically optimal Gödel Machine. 2020-: new stuff!

Jürgen Schmidhuber

250,293 Aufrufe • vor 6 Monaten

Was especially curious to ask Andrej Karpathy why self-driving cars took a decade+ from stellar demo rides to even somewhat deployed. Andrej led AI at Tesla for 5 years. I really wanted to know whether these frictions should lengthen our AGI timelines, or whether they were idiosyncratic to self driving. Driving has a really high cost of failure. Humans are surprisingly reliable drivers - we have a serious accident every 400,000 miles/7 years. And self-driving cars need to match or beat this safety profile before they can be deployed. But are most domains like this? Before the interview, it seemed to me that almost every domain we would want to plug AGI into has a much lower cost of failure. If fully autonomous software engineers weren’t allowed to make a mistake for 7 years, deployment would indeed be super slow. Andrej made an interesting point that I hadn’t heard before: compared to self driving, software engineering has a higher (and potentially unbounded) cost of failure: > If you’re writing actual production-grade code, any kind of mistake could lead to a security vulnerability. Hundreds of millions of people’s personal Social Security numbers could get leaked. > In self-driving, if things go wrong, you might get injured. There are worse outcomes. But in software, it’s almost unbounded how terrible something could be. > In some ways, software engineering is a much harder problem [than self driving]. Self-driving is just one of thousands of things that people do. It’s almost like a single vertical. Whereas when we’re talking about general software engineering, there’s more surface area. There’s potentially another reason why the LLM -> widely deployed AGI transition might happen much faster: LLMs give us perception, representations, and common sense (to deal with out of distribution examples) for free, whereas these had to be molded from scratch for self-driving cars. I asked Andrej about this: > I don’t know how much we’re getting for free. LLMs are still pretty fallible and they have a lot of gaps that still need to be filled in. I don’t think that we’re getting magical generalization completely out of the box. > The other aspect that I wanted to return to is that self-driving cars are nowhere near done still. The deployments are pretty minimal. Even Waymo has very few cars. They’ve built something that lives in the future. They’ve had to pull back the future, but they had to make it uneconomical. > Also, when you look at these cars and there’s no one driving, there’s more human-in-the-loop than you might expect. In some sense, we haven’t actually removed the person, we’ve moved them to somewhere where you can’t see them.

Dwarkesh Patel

135,047 Aufrufe • vor 11 Monaten