Загрузка видео...

Не удалось загрузить видео

На главную

Claude Code /simplify is now /code-review Now accepts an effort parameter: - low: short, scoped, latency-sensitive tasks that aren't intelligence-sensitive - medium: cost-sensitive work that can trade off some intelligence for fewer tokens - high: balances tokens and intelligence. Minimum for intelligence-sensitive work, or to cut spend vs xhigh...

86,169 просмотров • 5 месяцев назад •via X (Twitter)

Комментарии: 36

Фото профиля Daniel San
Daniel San5 месяцев назад

This skill spawns agents to run tasks in parallel. Here's part of the /code-review prompt at effort max

Фото профиля Daniel San
Daniel San5 месяцев назад

Getting really good results. Worth a try!

Фото профиля Peter Truong
Peter Truong5 месяцев назад

Effort param is clean. But it won’t save you on UI bugs — you still have to translate “the spacing feels off” into something the model can act on. That step doesn’t scale with intelligence.

Фото профиля Ilyas Turki
Ilyas Turki5 месяцев назад

boris cherny said in his latest thread, when opus 4.7 came out, that he used a /verify skill that did exactly what the code review skill does today.

Фото профиля Ofek Shaked | AI Engineer
Ofek Shaked | AI Engineer5 месяцев назад

Effort parameters on code review turn one off prompts into tunable execution policy which is exactly the missing control layer for production agent reliability across the full dev lifecycle.

Фото профиля InvisibleSock
InvisibleSock5 месяцев назад

Better overthink than underthink imho :D

Фото профиля Tommaso Rinversi
Tommaso Rinversi5 месяцев назад

Without that calibration, every team will quietly default to max and call the extra review cost “quality.”

Фото профиля Kyriakos
Kyriakos5 месяцев назад

Finally we can match token

Фото профиля Victor
Victor5 месяцев назад

code review as a first class verb, not a chore tacked on at the end

Фото профиля Solomon Neas
Solomon Neas5 месяцев назад

I prefer to tell claude to have codex code review and fix its mistakes.

Фото профиля CryptoClaw
CryptoClaw5 месяцев назад

Been running Claude Code daily with Hermes. effort=high is the sweet spot for agentic workflows — xhigh burns tokens overthinking simple file edits. curious what effort you default to for /code-review PRs?

Фото профиля TravelerOfCode
TravelerOfCode5 месяцев назад

the effort parameter is the underhyped change here. cost-sensitive teams stop having to choose between premium-model overhead and quality. low/medium/high lets you match spend to the task class automatically. bookmarking the migration note.

Фото профиля Natik Gadzhi @natik@hachyderm.io
Natik Gadzhi @[email protected]5 месяцев назад

Weren't they two different things before? I.e. code-review as in feature-dev or related?

Фото профиля Hargun Singh Rana
Hargun Singh Rana5 месяцев назад

What terminal app u are using mate?

Фото профиля Michał Piszczek
Michał Piszczek5 месяцев назад

effort is just a cost dial. everyone runs low until a review misses the one that mattered

Фото профиля MindyCore
MindyCore5 месяцев назад

Wow! Giving teams clearer control over reasoning depth and efficiency feels like a very practical step for real-world AI workflows. The nuance between speed, cost, and quality matters more every day 💙⚡

Фото профиля Fiducial.ai
Fiducial.ai5 месяцев назад

The max overthinks warning is real, had it spiral on a simple refactor once, xhigh is almost always the right call unless you specifically need it to grind through something gnarly.

Фото профиля 두둠찌찌
두둠찌찌5 месяцев назад

effort 파라미터가 비용-품질 트레이드오프를 사용자한테 명시적으로 넘긴 게 흥미해요. 보통 이런 선택은 내부에서 숨기는데.

Фото профиля Ezenwa
Ezenwa5 месяцев назад

ugh fuck no, i have a skill named code-review already.

Фото профиля Jorge
Jorge5 месяцев назад

This screws with @sentry code-review skill darn.

Фото профиля Daniel San
Daniel San5 месяцев назад

@sentry The problem with generally-named skills They have hierarchy and this kind of thing can happen

Фото профиля 💎🖐️ UberTrader
💎🖐️ UberTrader5 месяцев назад

Finally, a way to stop the AI from overthinking simple bug fixes. 'Max' sounds like a trap for token spend. 😂😂

Фото профиля plainscope
plainscope5 месяцев назад

How does the effort parameter in Claude Code affect the output quality? Is it more about speed or accuracy?

Фото профиля 唐清乐
唐清乐5 месяцев назад

/simplify 改名 /code-review 加上 effort 参数是好改进,但 effort 的三个等级选择对新手来说又多了一个决策负担,建议提供推荐默认值。

Фото профиля Cristian N
Cristian N5 месяцев назад

do you have any idea, is this using extra credit tokens or the subscription?

Фото профиля Alexander Malakhov
Alexander Malakhov5 месяцев назад

Xhigh, limits bye bye

Фото профиля Terry Bui
Terry Bui5 месяцев назад

低: 短い、スコープが限られ、遅延に敏感なタスクが受け入れ可能です。 中: コストに敏感な作業で、一部の知能をトークンに交換できるもの。 高: トークンと知能をバランスさせる。知能に敏感な作業、または xhigh に対して支出を削減したい場合の最小値。 x高: ほとんどのコーディングや主体的なタスクに最適な結果をもたらします。Opus 4.7 では推奨されるデフォルト値。 最高値: 高要求のタスクでパフォーマンスを向上させることができますが、収益が低下し、過度に考え込む傾向があります。広く採用する前にテストしてください。

Фото профиля Callam
Callam5 месяцев назад

oh good, I can stop typing /simp to Claude 20 times a day

Фото профиля AI Mastery Guide
AI Mastery Guide5 месяцев назад

5 effort levels means you can actually match the tool to the task instead of burning tokens on everything

Фото профиля Enes Gogalic 🎩
Enes Gogalic 🎩5 месяцев назад

Didn’t know 🙌🏻

Фото профиля JMoon
JMoon5 месяцев назад

effort param was the missing piece. low for a quick scan, high when you actually want it to push back on the architecture.

Фото профиля Di 🎒 | ETHGas ⛽
Di 🎒 | ETHGas ⛽5 месяцев назад

@dani_avila7 Is the /review different? Do you think better use /code-review only?

Фото профиля AI Developer MM
AI Developer MM5 месяцев назад

오우 업데이트가 엄청

Фото профиля Ramit Koul
Ramit Koul5 месяцев назад

effort levels for review make sense. not every check needs the same brainpower.

Фото профиля martin
martin5 месяцев назад

why would anyone use anything less than max?

Фото профиля Thomas Lane
Thomas Lane5 месяцев назад

Hey @dani_avila7 which terminal is this?
Похожие видео

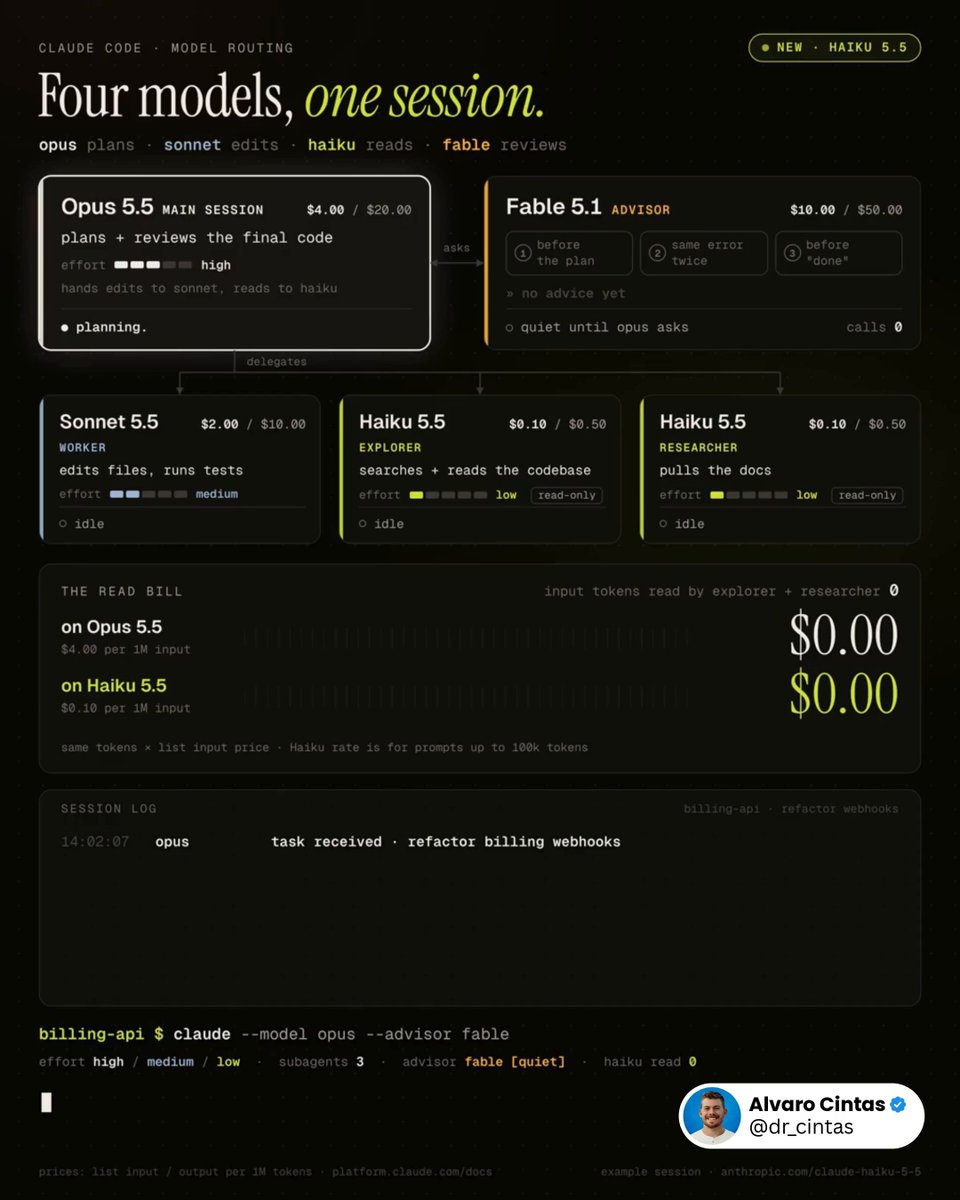
This workflow will save you thousands with Claude. Run Opus 5.5, Sonnet 5.5, Haiku 5.5, and Fable 5.1 together, and stop spending Opus tokens on work that doesn't need Opus. The entire idea in one line: Opus plans, Sonnet edits, Haiku reads, Fable reviews at decision points. Roles, broken down: - Opus 5.5, high effort, owns the plan and reviews the final code - Sonnet 5.5, medium effort, is the worker: edits files, runs tests - Haiku 5.5, low effort, splits into explorer (searches and reads the codebase) and researcher (pulls docs). it's the first Haiku with an effort setting - Fable 5.1, set with /advisor fable. Opus calls it at decision points, and it gets the full transcript each time Three moments Opus tends to call it: → before committing to a plan: is this the right approach? → the same error shows up again: is this going nowhere? → before marking the task done: did something get skipped? Why Haiku only reads: Anthropic's launch post says Sonnet 5.5 and Opus 5.5 are still the better choice for complex agentic coding (Terminal-Bench 4.0: 39.2% for Haiku 5.5, 70.6% for Sonnet 5.5) and that Haiku 5.5 fits narrowly scoped subagent work. so it gets the lookups, not the edits. Anyone still running one model for everything is paying $4 per million input tokens to check whether a file exists. Haiku 5.5 does it for $0.10. Drop this into Claude Code 👇 "Rebuild my Claude Code setup around this structure: Confirm Claude Code is v2.1.293 or later, so the haiku alias resolves to Haiku 5.5. If it isn't, stop and tell me to run claude update. Look through ~/.claude/agents and .claude/agents for subagents already covering explorer, worker, and researcher. Only create new ones for roles that are missing. Set model: haiku, effort: low on explorer and researcher, with no Edit or Write tools. Set model: sonnet, effort: medium on worker. If an existing subagent is locked to a different model, leave it as is and just list it. Name the explorer subagent Explore so it overrides the built-in one, which otherwise runs on my main model. In ~/.claude/settings.json, set advisorModel to fable, and set effortLevel to high for claude-opus-5-5 under modelSettings. A top-level effortLevel in user settings doesn't apply to Opus 5.5. Check for anything disabling the advisor: CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, or anything blocking feature-flag fetches. Also check CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort settings, and CLAUDE_CODE_SUBAGENT_MODEL_FORCE, which makes Claude Code ignore subagent model fields. Report what you find. Don't change any of it yet. Add one line to ~/.claude/CLAUDE.md: consult the advisor before a big plan, when the same error shows up twice, and before marking a long task done. Show every change as a diff first. Wait for my go-ahead before touching anything."

Alvaro Cintas

56,940 просмотров • 13 дней назад

this is pure f*cking treasure Claude Code tip: once Opus 5.5 is your main model, stop leaving Fable 5.1 sitting idle and stop burning Opus tokens on tasks Sonnet 5.5 can swarm put it on call with /goal claude --auto-mode "/goal all tests pass and lint is clean" Opus 5.5 keeps writing the code in auto mode Sonnet 5.5 swarms the routine work at medium Fable 5.1 inspects the full transcript and only speaks up at the turn boundary: → not yet met: am I drifting from acceptance criteria? → met: do the tests, diffs, and lint hold? → impossible: am I chasing an unreachable state? Fable grades. Opus ships JEV engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or halt) go to JEV in under 16ms, and the big models only see the ones that split — the full tree > Opus 5.5 on high runs the main session > worker edits and patches code on Sonnet 5.5 > explorer indexes AST maps and call sites on Sonnet 5.5 > verifier runs tests and linters on Sonnet 5.5 > all three subagents on medium effort > Fable 5.1 on call as the Stop hook evaluator > JEV routes micro-forks under 16ms paste the tree and this prompt into Claude Code ↓ "Reconfigure my Claude Code setup around this tree: 1. Set the main session to Opus 5.5 on high effort with auto mode enabled. 2. Put Fable 5.1 on call as a session-scoped evaluator attached to the Stop hook: - Read-only transcript evaluation with zero tool calls - Three structured outcomes: not yet met (with steering notes), met (auto-clear), and impossible (abort early) 3. Spawn Sonnet 5.5 subagents on medium effort for worker, explorer, and verifier roles. Defer goal checks while background tasks run. 4. Route fast deterministic forks (tool resolution, path selection, auto-retries) through JEV. 5. Add one rule to CLAUDE.md: run long tasks with: claude --auto-mode \"/goal \" Show me every configuration change as a diff first. No edits until I say go." ↳

mirku

41,948 просмотров • 14 дней назад

i finally mastered how to maximise my opus 5.5 usage limits... the trick: let jev choose which subagent gets each task and how much effort it should use. [here’s how i’d wire it:] claude breaks the project into tasks. jev selects from predefined worker profiles. claude applies the selected settings and dispatches the work. → main session, medium: clarify the requirements, define what “done” looks like, and prepare the tasks → builder, low: small, clearly defined tasks with existing examples or patterns → builder, medium: tasks that connect multiple parts or need decisions within the approved plan → verifier, high: check requirements, probe edge cases, and report problems for the builder to fix jev gets the task’s scope, what’s uncertain, and the consequences of failure. it chooses from the profiles allowed for that task. your approval checkpoints stay in place. paste this into your next planning session: “use opus 5.5 with jev selecting the worker and effort profile for each task. first, check that a working jev integration is available and that this environment supports separate effort settings for subagents. check for configuration or environment overrides that could prevent those settings from taking effect. if anything is missing, explain what needs wiring before proceeding. break my request into tasks with clear ownership, dependencies, relevant context, and acceptance checks. keep small related tasks together when a separate subagent would add unnecessary overhead. keep the main session at medium effort. offer jev these worker profiles: builder at low effort for small, clearly defined tasks using existing patterns; builder at medium effort for tasks that connect multiple parts or require decisions within the approved plan; verifier at high effort for checking requirements and edge cases. give jev each task’s scope, uncertainties, dependencies, and consequences of failure. only offer profiles appropriate to the current stage. validate its selection before dispatching. use the actual jev integration; don’t simulate its decisions. if it abstains or returns an invalid choice, stop that handoff and ask me. show me the task plan and proposed assignments before starting. after approval, launch the selected workers with their assigned effort settings, relevant context, file ownership, and completion checks. let me review the result before verification. the verifier may add tests but must leave implementation code unchanged. have it report what passed, what failed, and what remains uncertain. send implementation fixes back to the builder, then recheck the affected parts. if a task repeatedly fails, examine the requirements and approach before increasing effort. report available total usage, including jev calls, worker calls, retries, and verification. don’t invent missing data. compare similar completed tasks before claiming savings.” steal this 👇

Avid

31,355 просмотров • 25 дней назад

Claude Code tip: once Opus 5.5 is your main model, stop leaving Fable 5.1 sitting idle and stop burning Opus tokens on tasks Sonnet 5.5 can swarm put it on call with /advisor run /advisor fable Opus 5.5 plans and ships the code Sonnet 5.5 swarms the routine work at medium effort Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Fable 5.1 reviews. Sonnet 5.5 executes. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big model only sees the ones that split Plan on high. Delegate on medium. Keep Fable on call. - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on Sonnet 5.5 at medium effort > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

mirku

424,286 просмотров • 21 дней назад